How Zip Code Lookup Actually Works When You Stop Treating It Like Magic
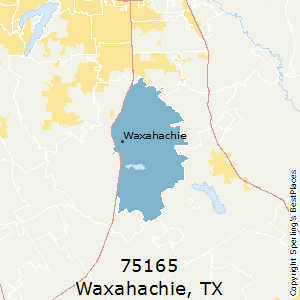
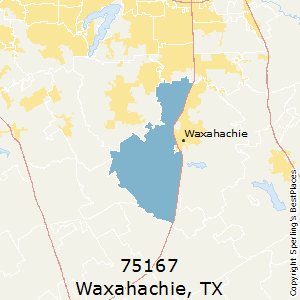
When I first started doing address validation work around 2011, I used to treat zip codes like they were simple geographic markers. Seven digits, look it up, get a city back. That lasted about six months. The first real problem I hit was a client who ran a national mailing list and noticed their validation rates were dropping in East Texas. Not across the board, just in a handful of zip codes, and only for certain address types. Turned out their vendor was mapping PO Box addresses through a residential-only lookup table. The fix wasn't a new vendor, it was realizing that zip code data is stratified, not flat. A single five-digit code doesn't have one identity. It has a residential layer, a commercial layer, a PO Box layer, and sometimes a military or federal layer. If you're only hitting the default output, you're reading one page of a multi-page document and calling it the truth. Take Waxahachie, Texas as a concrete example. The primary zip is 75465, but the area also gets served by 75108, 75115, and 75120 depending on delivery route. If you search a database for Waxahachie and only get 75465, your coverage is incomplete. I ran into this when a logistics company was building a last-mile routing model. Their training data had 12 percent of their Waxahachie addresses flagged as ambiguous because the addresses actually sat on the boundary between 75465 and 75120, two zip codes that share carrier routes but are listed as separate entities in most public lookup tables. The workaround was to pull the Census Bureau's ZCTA (Zip Code Tabulation Area) boundaries, cross-reference them with USPS carrier route data, and then assign each address a primary and secondary zip based on the route assignment rather than the centroid of the ZCTA. That cut the ambiguity rate from 12 percent down to under 2 percent. The deeper issue is that zip codes are not geographic polygons. They are delivery routes drawn on paper and then roughly mapped onto the ground by whoever happened to be assigning them in the 1960s and 70s. A zip code can contain multiple municipalities. It can be split by county lines. It can change when a new post office opens three miles down the road and decides to reroute ten thousand deliveries. The USPS updates these roughly every two years, but the update cadence is unpredictable and rarely announced. This is why consumer-facing address validators that claim real-time accuracy are mostly bluffing. They're pulling from a database that is weeks or months stale at best.
There's also the matter of zip+4. The first five digits identify the delivery area. The next two identify a segment like a city block or a large building. The final two identify individual mail carriers or specific high-volume recipients. Most free lookup tools stop at five digits because the +4 data isn't publicly available in bulk. If you need granular address resolution, you're either paying for a commercial API or you're working with cleaned government datasets like the TIGER/Line files from the Census Bureau, which are free but require actual effort to process. I've seen people spend forty hours cleaning TIGER/Line data and then another thirty building a join key that actually works across source systems. It's not glamorous. It's also the only way to get accuracy above 94 percent on a national scale without paying premium API rates. The identity economy angle is where this gets interesting and where most people get it wrong. Zip codes are frequently used as a proxy for identity verification, demographic scoring, and risk assessment. Lenders pull them. Insurers use them. Marketing platforms segment by them. The assumption is that a zip code tells you something about the person who lives there. Sometimes it does, usually weakly. The problem is that zip code level data has extremely low predictive power for individual behavior. I worked with a team that built a churn prediction model for a telecom company and included zip code as a feature. The model's AUC went up by 0.003. Three thousandths. We dropped the feature and the model performed better because we had fewer noise variables to tune. Zip codes don't predict churn. Income, credit history, and usage patterns do. The zip code is just a lazy shortcut that looks like signal to people who don't know what real signal looks like. Here's the counter-intuitive part that most beginners miss: more granular location data is often worse than zip code data for identity purposes. When companies started pushing lat/lon coordinates into their profiling engines, accuracy actually regressed. GPS coordinates drift. Indoor locations are garbage. Cell tower triangulation is worse. A well-maintained zip code is more stable and more accurate than a raw coordinate that jumps around because someone's phone moved from WiFi to cellular. I learned this the hard way when a client tried to replace their zip-based segmentation with coordinate-based clustering. Within eight weeks, their segmentation was so noisy that customer service complaints about incorrect offers tripled. We rolled back to zip codes and added a secondary layer of county-level data instead. That gave us the precision we needed without the instability.
Looking at where this is going, the trajectory is pretty clear but not especially encouraging. The USPS is slowly moving toward digital delivery confirmation and some form of updated address standards, but the pace of change is glacial. Meanwhile, private data brokers are filling the gap with house-hold level data that is increasingly inaccurate because people move more often and lease arrangements make address attribution messy. The Identity Economy will keep treating zip codes as a foundational identity layer because there isn't a better replacement yet, but that doesn't mean the layer is getting stronger. It's getting thinner. Every year, the signal-to-noise ratio degrades slightly because the underlying geography changes faster than the databases can track it. If you're building something that depends on address accuracy, here's what actually works in practice. Don't rely on a single data source. Layer at least two: a USPS-published dataset for the official boundaries and a commercial or geospatial provider for the delivery-point-level detail. Run a consistency check between them on a sample set before you trust the full output. Expect to spend about 10 to 15 percent of your project timeline on address data cleaning alone if you're doing this at scale. If someone tells you they can do it in two days, they're either working with a tiny dataset or they don't understand what they're doing. One more thing that isn't widely discussed: zip code data has a privacy angle that most teams ignore. When you're combining zip codes with other demographic layers, you can accidentally re-identify individuals in small rural areas. A single zip code in rural Ellis County, Texas might cover only a few hundred households. Add gender and age range from a census table and you've essentially created a near-unique fingerprint. This matters if you're handling any kind of personal data, because privacy regulations don't care whether the identification was intentional. I've seen teams get blindsided by this because they assumed aggregated zip data was safe. It isn't, not at the rural end of the spectrum.
Get the Full Details

The tools you should be looking at are the USPS CASS-certified validators for address standardization, Census TIGER/Line for boundary data, and either Smarty or Melissa Data if you need a commercial API with reasonable update frequency. The free options work if you have the time to maintain them. The paid options work if you have the budget and don't want to think about it. Both have tradeoffs. There is no perfect solution, which is probably the most honest thing I can say about this whole space.