Starting With What Actually Happens Under The Hood
Most people describe this topic as a hierarchy, like deep learning sits on top of machine learning like a fancy second floor. That's not wrong, but it's not useful either. The real distinction shows up when you're actually building something and the model refuses to train the way you expected. I spent three years working on tabular data classification before I ever touched a neural network for production work. The transition wasn't smooth. I kept trying to make XGBoost behave like a ResNet and wondering why neither was giving me what I needed. Here's what I figured out after burning through a few failed deployments.
Uncovering The Hidden Patterns Whats The Real Difference Between Machine Learning And Deep Learning
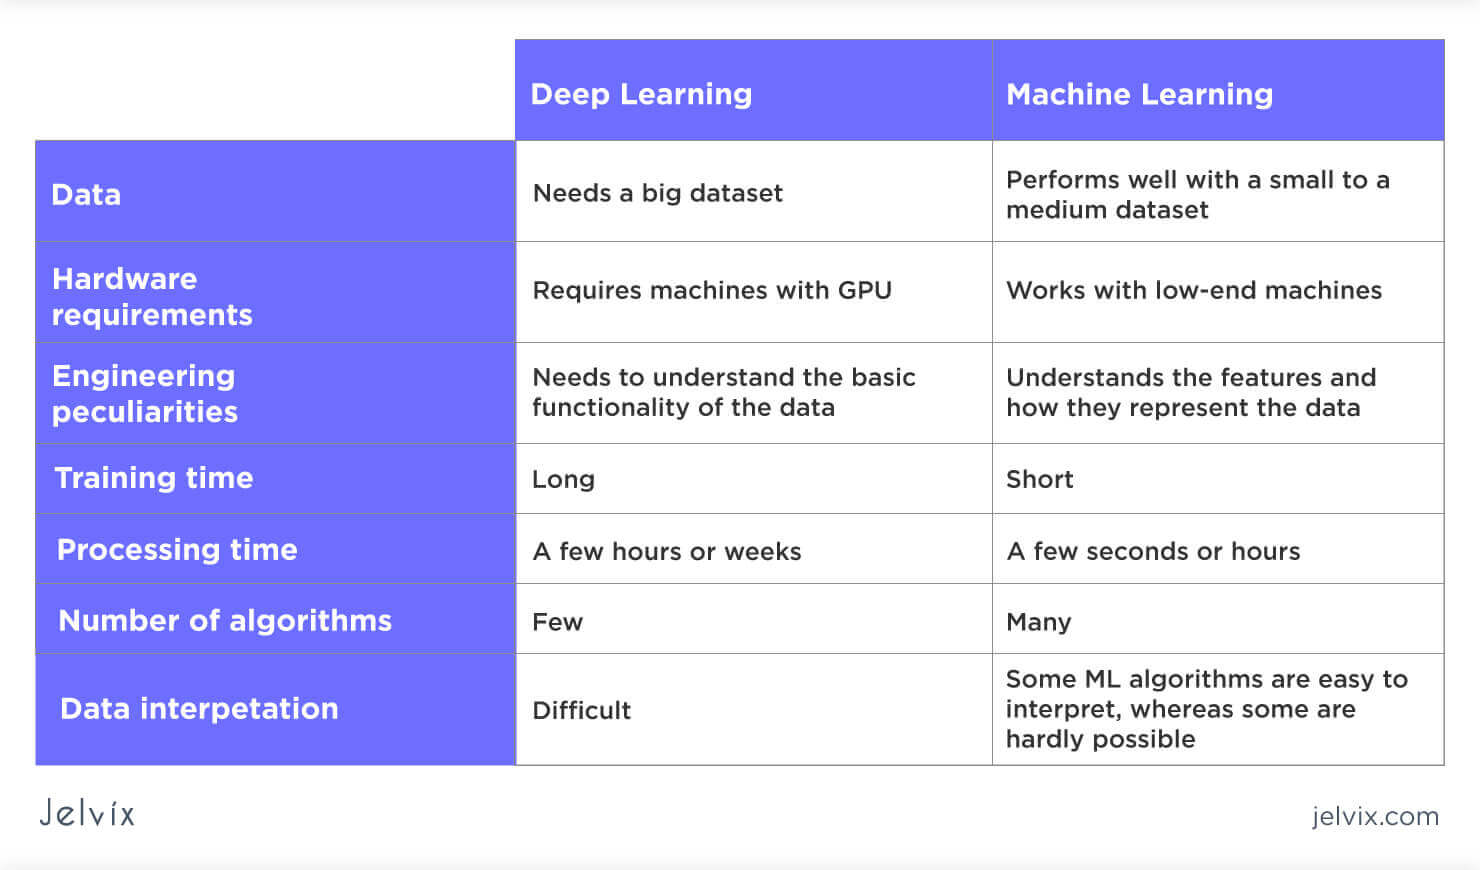
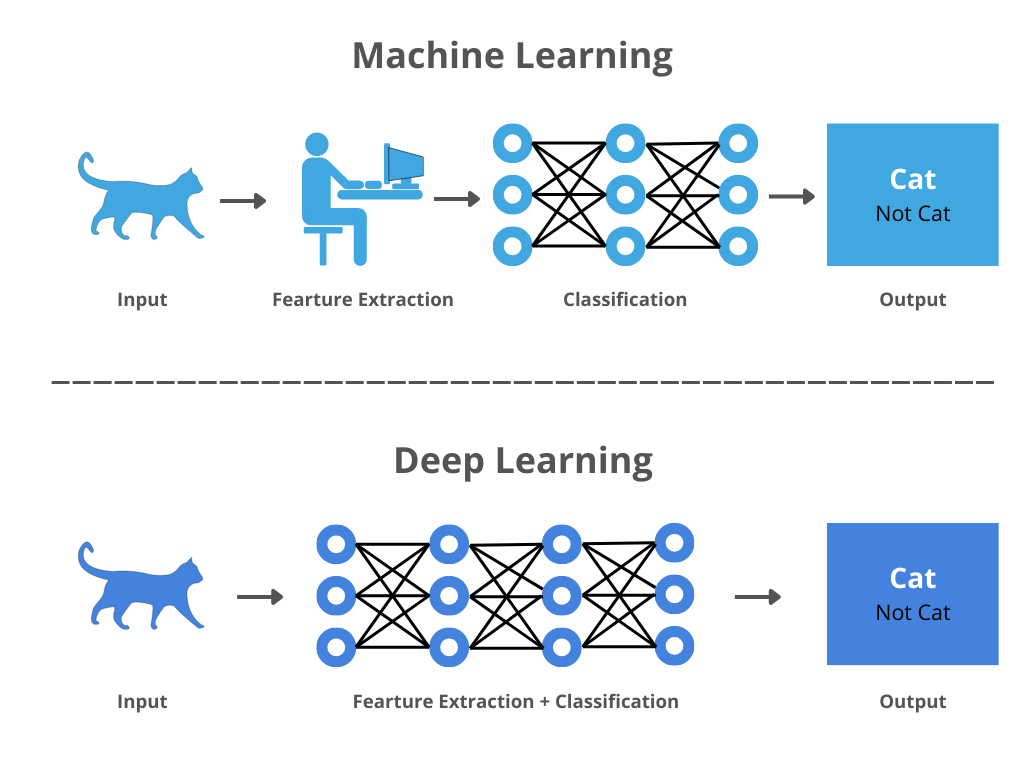
Machine learning, in the practical sense, means you design features manually and feed them into algorithms like gradient boosting, random forests, support vector machines, or logistic regression. You look at your data, you decide which columns matter, you engineer interactions, handle missing values yourself, and the model learns the mapping between those engineered inputs and your target variable. The feature engineering is where the work lives. Deep learning removes that step by using layered neural networks that learn representations directly from raw inputs. A convolutional network takes pixel values. A transformer takes token IDs. The model figures out which features matter by adjusting weights across multiple hidden layers during training. You still do preprocessing, but the model does the feature extraction internally. The reason this distinction matters in practice comes down to data type and volume. Tabular data with clean columns? Traditional machine learning usually wins. Images, audio waveforms, raw text, time series with complex temporal dependencies? Deep learning becomes competitive or superior, but only when you have enough data and compute to train it properly.
I encountered a specific edge case that exposed the gap clearly. We had a dataset of manufacturing sensor readings - about 400 features per timestamp, irregular sampling intervals, and we needed to predict equipment failure within a rolling 48-hour window. I tried a gradient boosting model first because that's what I knew. It got us to about 74% recall on failures, which wasn't acceptable. Then I built a 1D convolutional network with attention layers that ingested the raw sensor sequences directly. It jumped to 89% recall, but required GPU training and roughly 10x more labeled data than the tree-based model would have needed. The tradeoff was real. Better performance, significantly higher infrastructure cost and longer training time.
Get the Full Details

Where The Common Understanding Breaks Down
Beginners often assume deep learning is always better because the architecture sounds more advanced. That's incorrect and it causes problems in production. I've seen teams ship LSTM models for problems that a simple logistic regression solved in minutes with equal accuracy. The deep learning model took eight hours to train on a single GPU and required a dedicated inference service just to handle the latency. Another misconception is that deep learning eliminates the need for domain knowledge. It doesn't. The domain expertise just shifts upstream. Instead of engineering features, you need to understand architecture choices, regularization strategies, data augmentation approaches, and how to structure your training pipeline. You're still applying domain knowledge, just at a different level of abstraction. The training dynamics are fundamentally different too. Tree-based models converge quickly and their performance is relatively stable across random seed variations. Neural networks are sensitive to initialization, learning rate scheduling, batch size selection, and architecture depth. A poorly tuned network can underperform a simple model by a wide margin, and diagnosing whether the issue is data quality, architecture mismatch, or hyperparameter selection takes experience.
What Each Approach Actually Requires
Traditional machine learning workflows typically involve data cleaning, feature engineering, model selection from a relatively small set of well-understood algorithms, cross-validation, and deployment. The interpretability is straightforward. You can look at feature importance scores and explain to a stakeholder exactly which variables drove a prediction. SHAP values and permutation importance give you decent approximations even for complex ensemble methods. Deep learning workflows add several layers of complexity. You need to define an architecture, choose an optimizer, manage learning rate schedules, handle overfitting through dropout or weight decay, possibly implement custom loss functions, and deal with the computational overhead. Interpretability becomes harder. You can use techniques like attention visualization, integrated gradients, or layer-wise relevance propagation, but these are approximations, not direct explanations. A feature importance plot from a random forest tells you something concrete. An attention heatmap from a transformer tells you something suggestive. The data requirements diverge sharply here. Tree models can produce decent results with a few thousand labeled examples if your features are well-constructed. Neural networks generally need orders of magnitude more data to generalize properly, unless you're using transfer learning from a pretrained model. Fine-tuning a BERT model on your domain text with maybe 10,000 examples works fine. Training a similar architecture from scratch would likely fail on that same dataset.
When To Choose What
If your data is structured or semi-structured with a clear schema, start with gradient boosting. LightGBM and XGBoost will give you strong baselines quickly. If you get to a point where the model plateaus and you suspect there are nonlinear interactions your features aren't capturing, then consider whether a neural network might extract those patterns automatically. Don't skip the baseline. I've lost track of how many times I've seen someone build a complex deep learning pipeline only to find a simple model had already solved most of the problem. If your data is unstructured - images, audio, raw text, video - deep learning is usually the right starting point because traditional methods struggle to create meaningful features from that kind of input. Even then, pretrained models and transfer learning often let you bypass the massive data requirements that originally made deep learning attractive. The intersection area is where most real projects live. Financial data with some text components. Medical records that combine lab results with clinical notes. E-commerce data mixing user behavior logs with product descriptions. In those cases, hybrid approaches work well. You can run a traditional model on the structured features, a neural network on the unstructured features, and combine the predictions. It's more engineering work, but it often extracts more signal than either approach alone.

The difference between these two approaches isn't about one being superior to the other. It's about matching the tool to the data structure and the constraints you're working under. Getting that wrong doesn't just waste compute hours. It produces models that look good in validation but fail in production because the assumptions baked into the architecture don't match the actual data distribution.