Setting Up Intelligent Automation Without Losing Your Mind
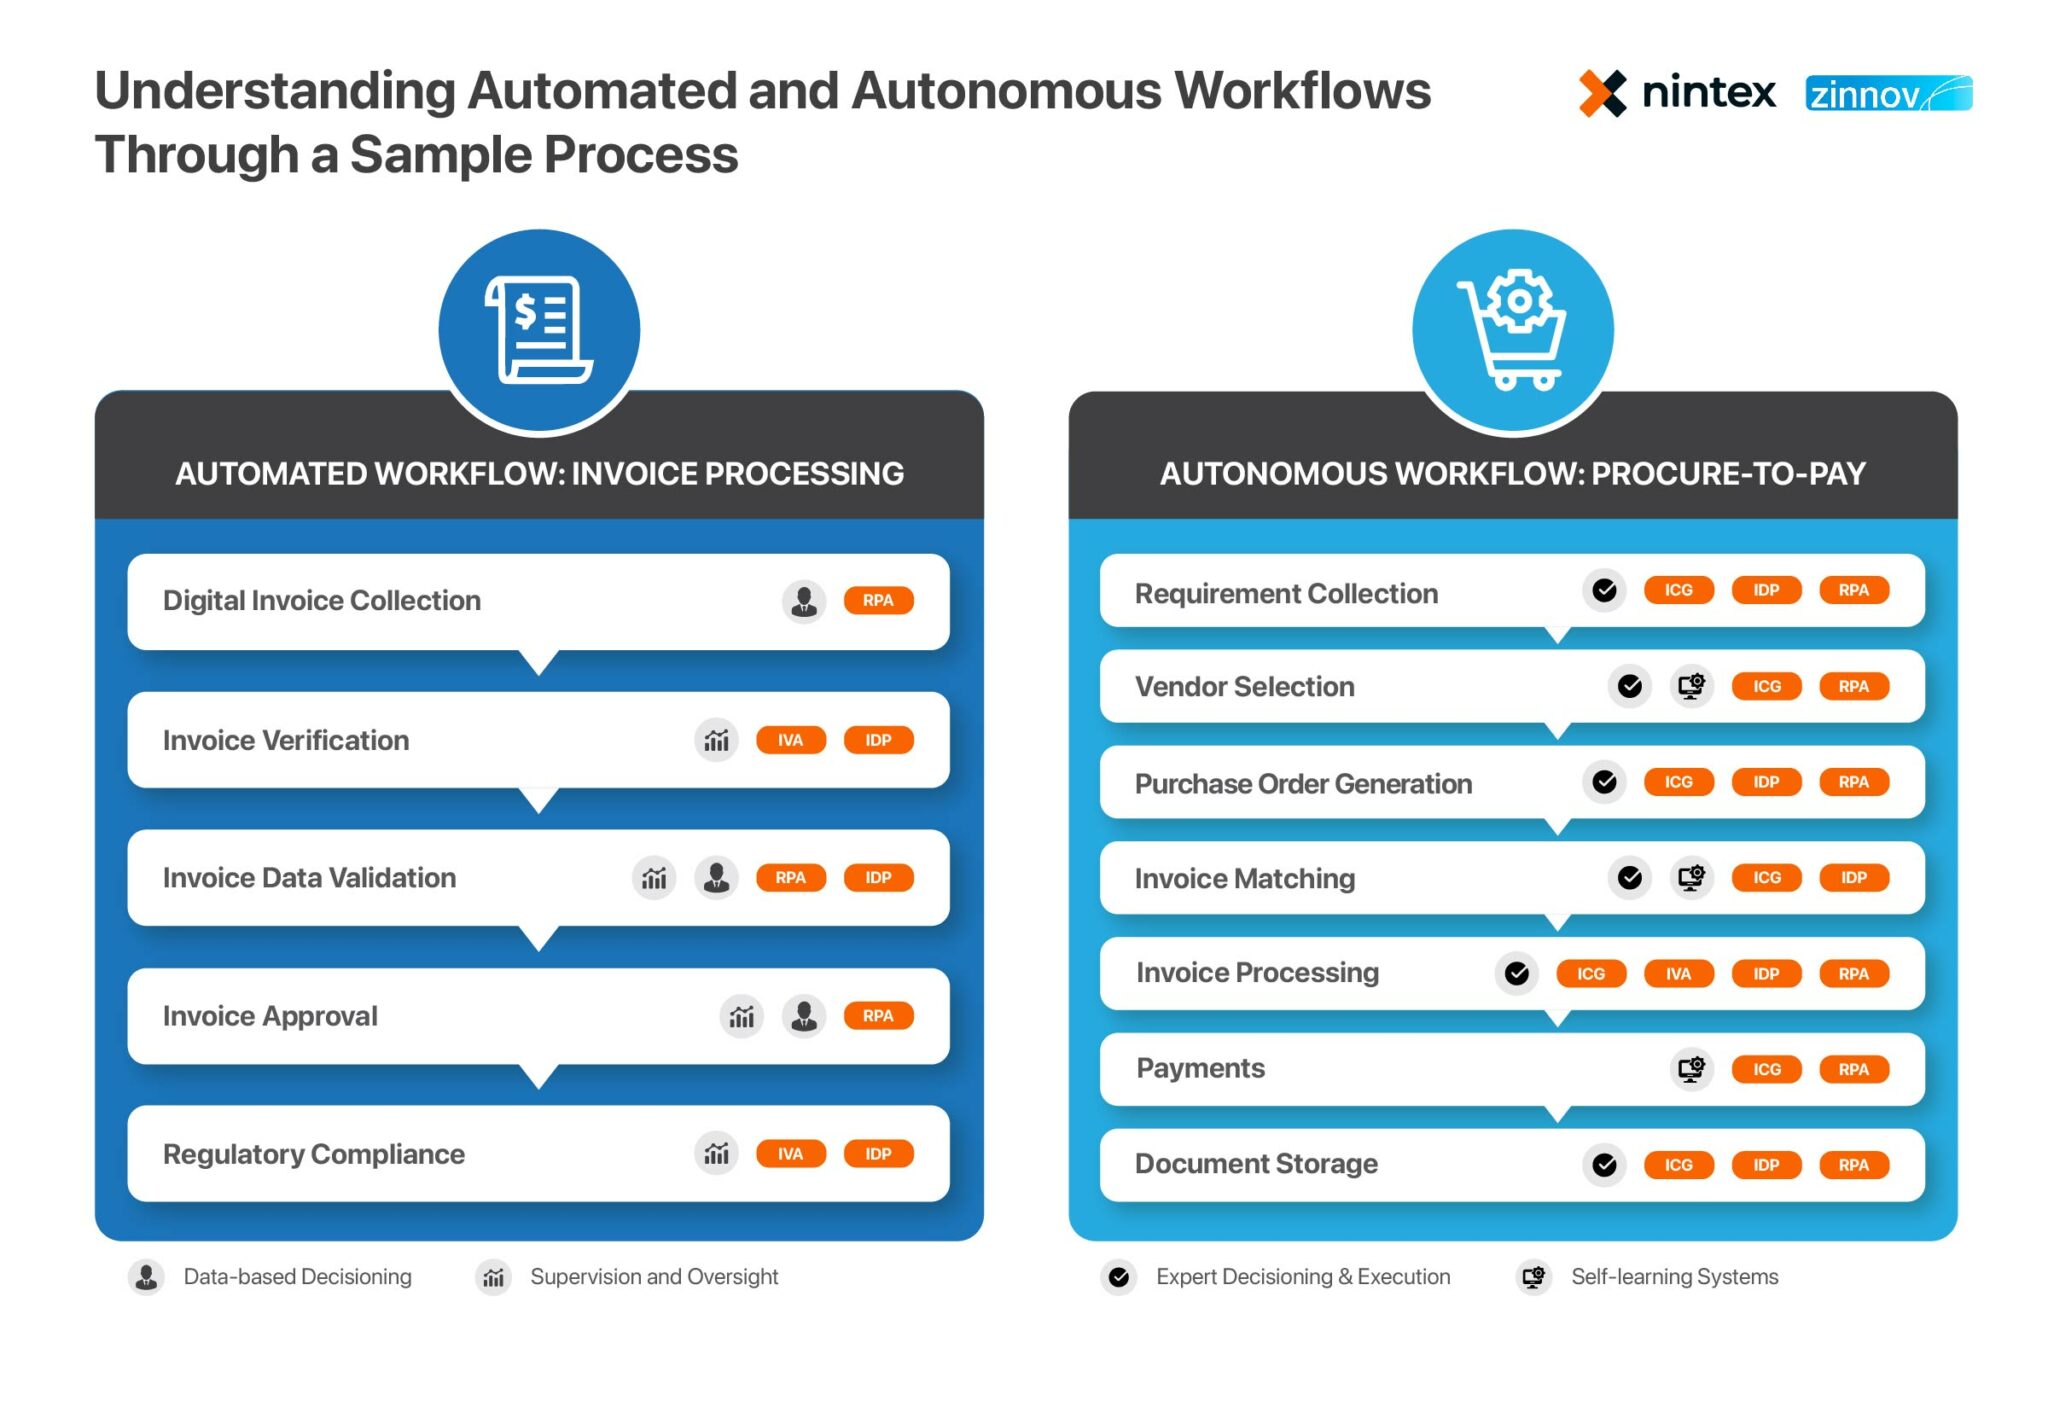
I spent three years trying to get our internal document processing pipeline to work reliably before anything actually stuck. The first two attempts used rule-based scripts that broke the moment a single field format changed. The third used a basic RPA tool and survived about six weeks before a UI update from the vendor took it down. What finally worked was closer to what people now call Uwmpaws Revolutionizing Digital Workflows Through Intelligent Automation, though at the time we just called it "the thing that doesn't break." The core idea is straightforward enough, but the execution has a few traps that everyone hits on the first pass. You start by identifying which parts of your workflow are deterministic and which are messy. Rule-based automation works fine for the deterministic half. The messy half is where you need a model that can handle variations in input — things like inconsistent form layouts, scanned receipts with different fonts, or emails that don't follow a template.
Uwmpaws Revolutionizing Digital Workflows Through Intelligent Automation
What separates a setup that actually works from one that looks good in a demo is how you handle the handoff between the deterministic layer and the intelligent layer. Most people wire these together poorly and wonder why their accuracy drops to 60 percent once they push to production. Here is how I structured it: First, build an ingestion pipeline that sanitizes and normalizes raw input before anything else touches it. This means standardizing file formats, extracting text from PDFs with OCR confidence scores attached, and logging every rejection reason. If a document fails OCR with a confidence below 0.7, route it to a manual review queue immediately. Do not let it fall through to the model layer pretending it is valid data. I learned this the hard way after an entire week of "model predictions" turned out to be garbage text from unreadable scans, and nobody noticed because the pipeline never flagged it.
Second, separate classification from extraction. A common mistake is feeding raw documents directly into an extraction model and expecting it to also figure out what type of document it is. Use a lightweight classifier first — even a simple logistic regression on extracted features can do this — and then route to the appropriate extraction pipeline. Our classification accuracy went from about 55 percent to 94 percent just by adding this step, and extraction accuracy followed because each model was now seeing only the document types it was trained for. Third, and this is the part nobody mentions in the marketing material, you need a feedback loop that feeds human corrections back into retraining. I set up a system where any field that a reviewer changed was tagged with the original model prediction, the corrected value, the document type, and a timestamp. Once a week we batch-retrained the affected models using the new labeled examples. Within two months, our error rate on recurring document types dropped by roughly 40 percent. The system was not static. It adapted, which is the actual value proposition here. There are real limitations though, and you should know about them before committing to this approach. The biggest one is latency. Intelligent automation adds processing time. A simple rule-based script can process a document in under a second. A pipeline with OCR, classification, extraction, and validation might take 8 to 15 seconds per document depending on your infrastructure. If you are processing thousands of documents per hour, that adds up fast. We solved this with async queues and parallel processing, but that requires a more sophisticated deployment than most teams have ready.
Get the Full Details
Another limitation is the cold start problem. If you are automating a workflow for a document type you have never seen before, you start at zero accuracy. There is no workaround other than getting a small labeled dataset through manual annotation first, or running the system in shadow mode where it processes documents without acting on the output until you have enough training data. I recommend shadow mode for at least two weeks before any automation goes live. It is painful to watch the system make mistakes in real time, but it prevents you from accidentally automating bad decisions. The cost structure is also worth considering upfront. Cloud-based OCR and model inference add up. For a mid-volume operation processing a few thousand documents per day, expect roughly $200 to $600 per month in API and compute costs depending on the providers you use. Hosting models yourself cuts those costs but requires ML engineering resources you may not have. It is rarely worth building custom models from scratch unless you have over 50,000 documents per month and very specific requirements that off-the-shelf solutions cannot handle. For implementation, I started with Python and a stack of open source tools: Tesseract or EasyOCR for OCR, a transformer-based classifier for document type detection, and a lightweight NER model for extraction. We wrapped everything in FastAPI, deployed on Kubernetes with a Celery worker queue, and used PostgreSQL for the feedback loop storage. The total setup time for a basic version was about three weeks for a small team. A polished, production-ready version took another two months of iteration.
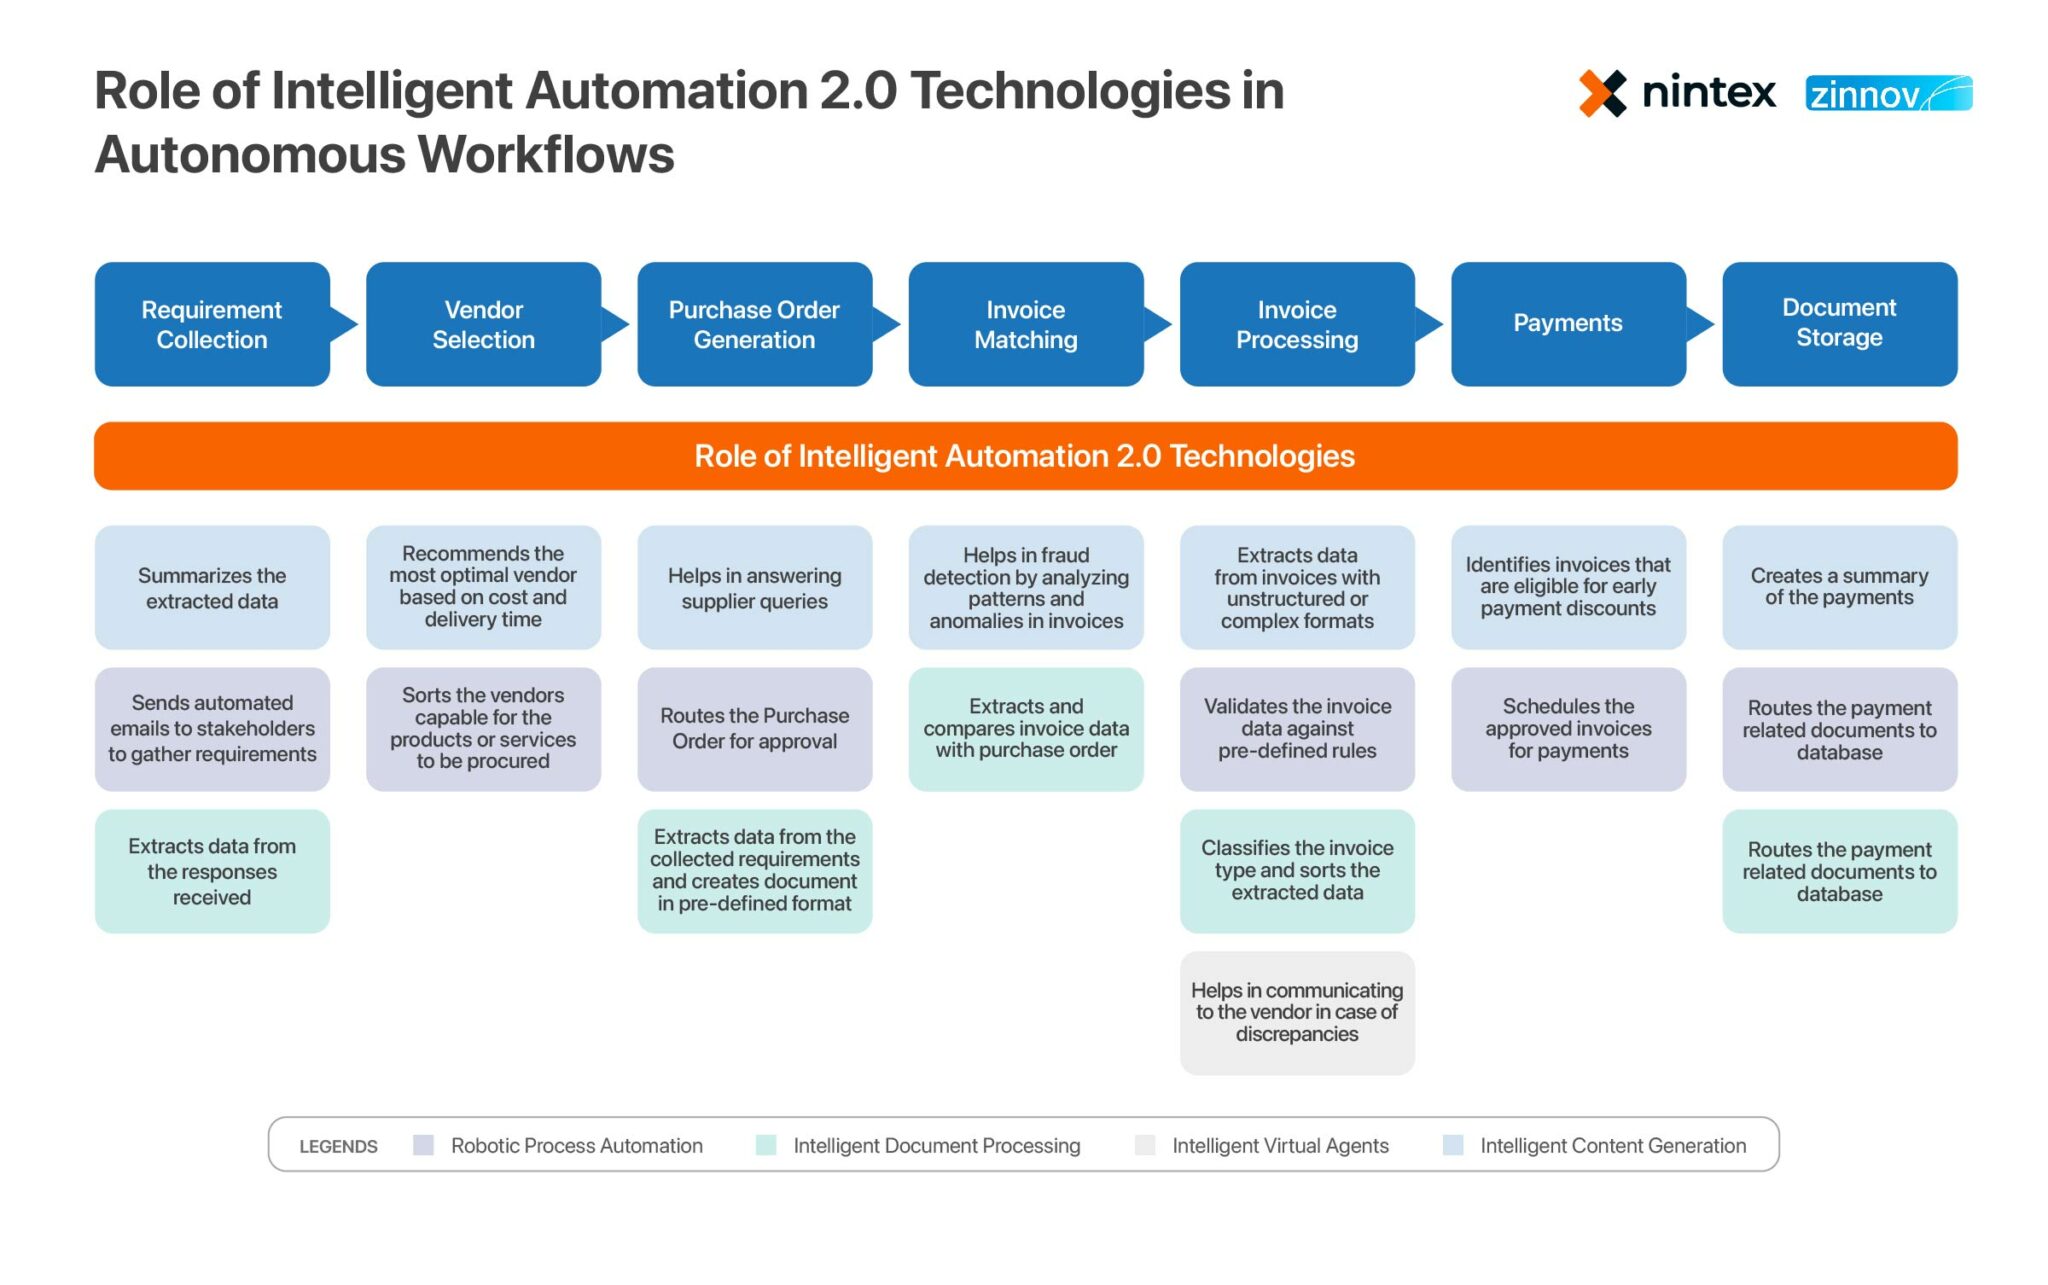
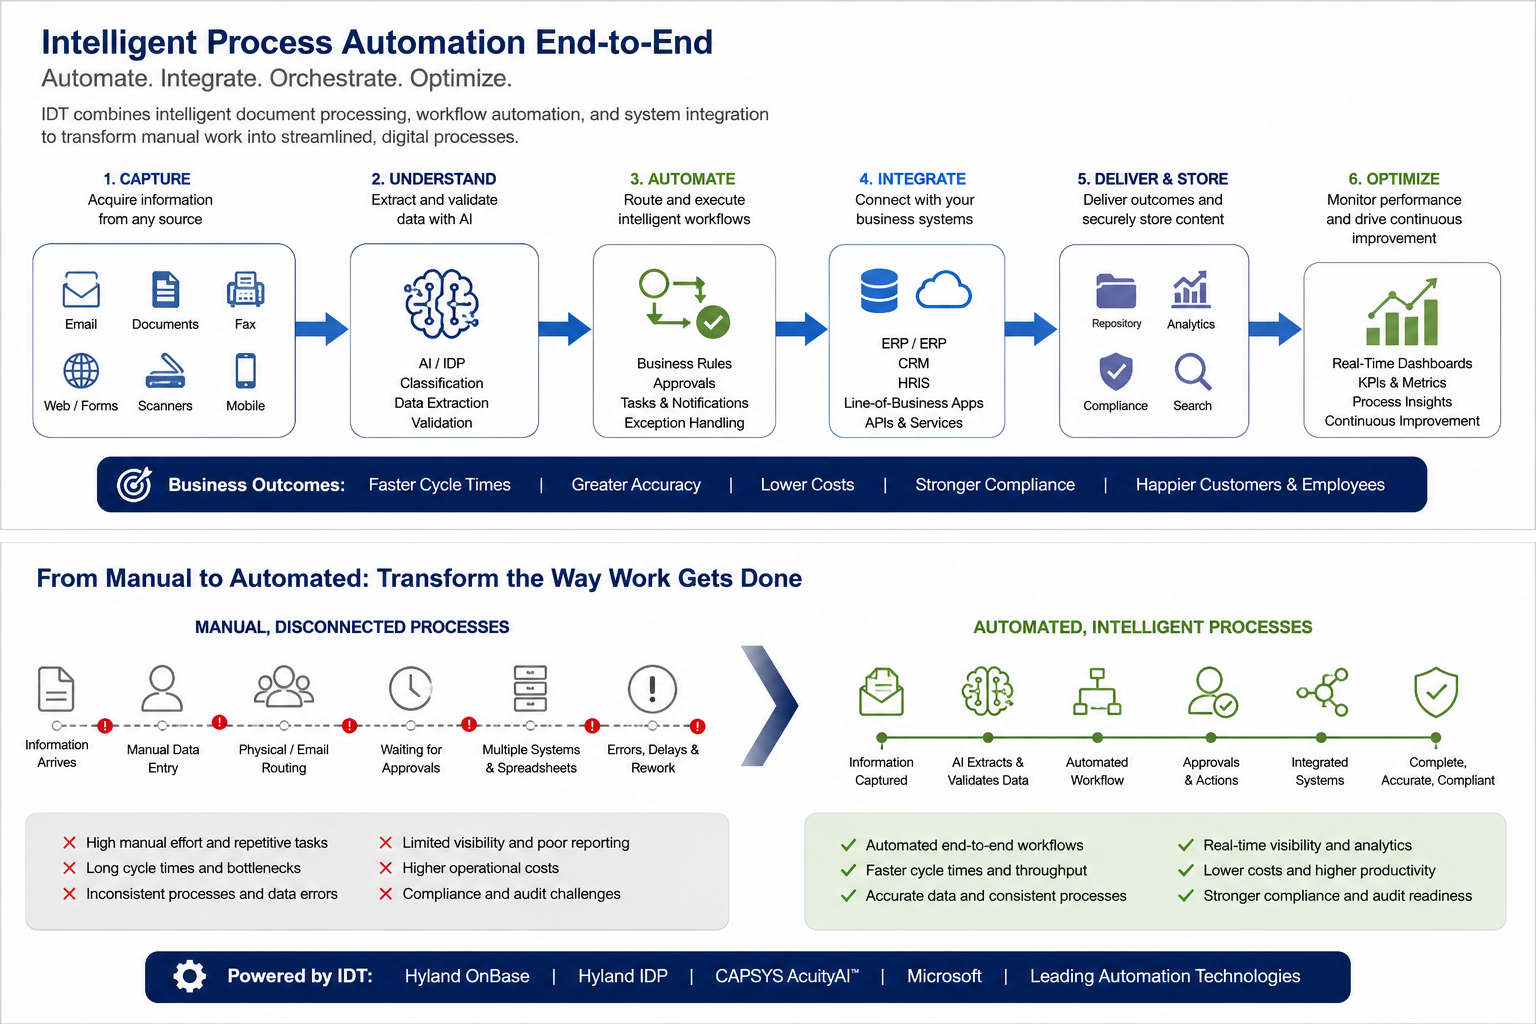
If you want a faster starting point, there are commercial platforms like UiPath, Automation Anywhere, and Microsoft Power Automate that have added AI capabilities on top of their existing automation frameworks. They are more expensive per seat but reduce the engineering overhead significantly. The tradeoff is that you are locked into their ecosystems and their model limitations. The open source path gives you control but demands more maintenance. The practical workflow looks like this. Documents land in an S3 bucket or equivalent storage. A Lambda function triggers the pipeline, runs OCR, classifies the document, routes to the appropriate extraction model, validates the output against business rules, and writes results to the database. Failed validations go to a review dashboard. Corrected fields feed back into the retraining pipeline. The whole thing runs with about 85 to 92 percent automation coverage depending on document quality, with the remaining 8 to 15 percent requiring human review. What I find interesting is that the hardest part was never the technology. It was getting stakeholders to accept that the system would not be 100 percent accurate and designing workflows around that reality. Once we stopped treating it as a replacement for humans and started treating it as a tool that handles the boring predictable work while flagging the exceptions, everything clicked into place.