URLs are just strings that control everything you see on the internet
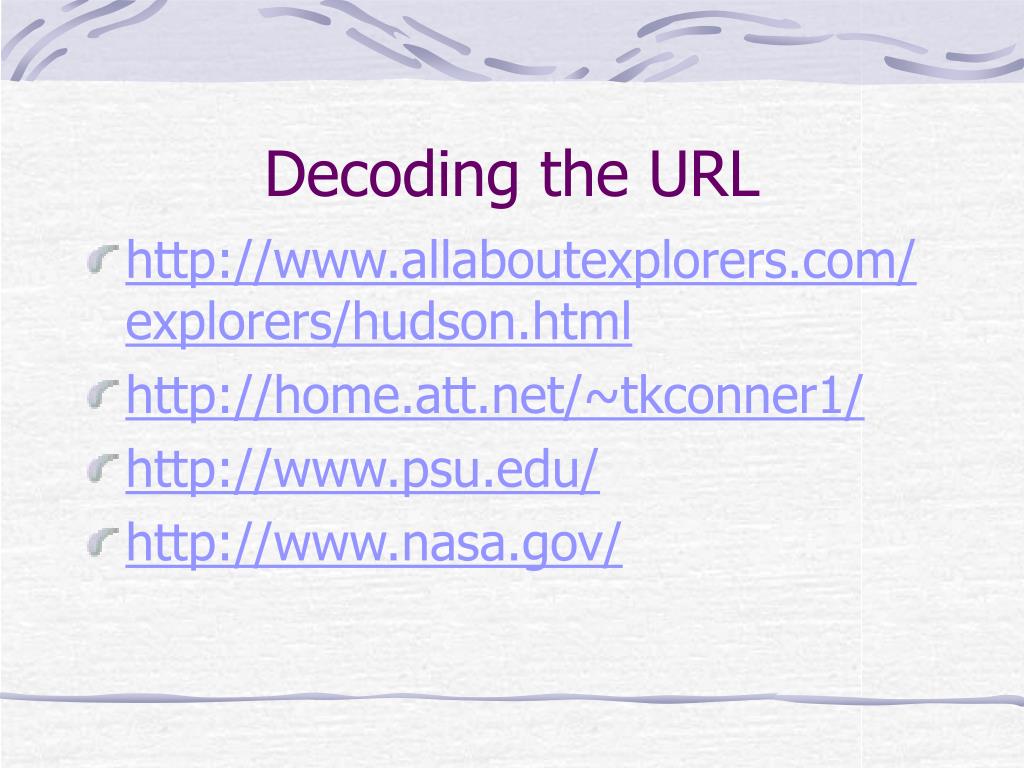
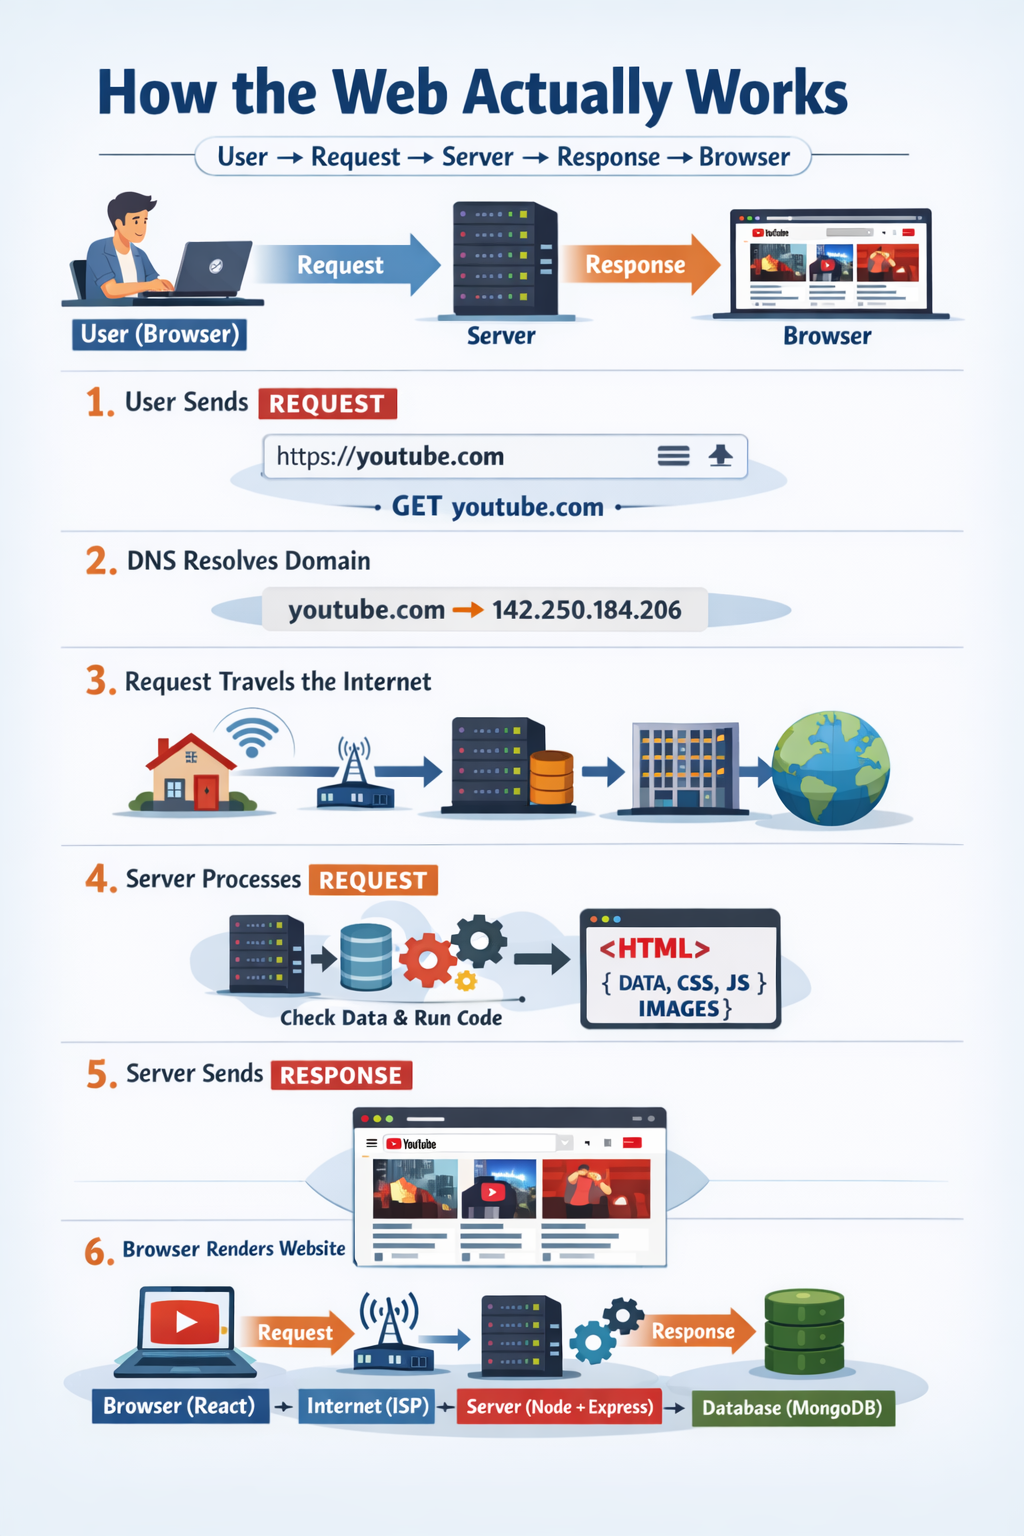
Most people treat a URL like a web address, something you type and then forget about. It is not an address. It is a precise instruction set that tells your browser where to go, what protocol to use, whether to expect encryption, which server to talk to, and exactly which resource to pull back. When you type something like https://example.com/path?foo=bar, you are sending a structured command that goes through DNS resolution, TLS handshake, HTTP request routing, server-side parsing, and response delivery before anything renders on your screen. The structure matters more than most browsers make it obvious. Take the protocol part first. http gets you plain text. https adds TLS encryption, which changed the entire shape of the web by 2018 when Google started ranking encrypted sites higher and browsers began flagging non-https as insecure. That single change forced millions of small businesses to get SSL certificates or watch their traffic drop. Not because the technology was better, but because the browser chrome started punishing you visually for not having it. Then there is the hostname. This is where DNS kicks in. Your browser takes that string, asks a recursive resolver what the IP is, and the resolver walks through root servers, TLD servers, and authoritative nameservers before giving you an actual number like 93.184.216.34. Sometimes it gives you multiple IPs for load balancing. Sometimes it returns different IPs based on your geographic location, which is how CDNs work. This is why a site might load fine from one country and timeout from another, even though the URL is identical.
The path part determines what resource you are asking for. /products/shoes/1234 is completely different from /products/shoes, and servers handle those as separate requests. Single Page Applications made this confusing because they started using hash-based routing like /#/dashboard instead of proper paths. That meant the server saw the same request regardless of what came after the hash, pushing all routing logic to the client side. It worked until you tried to share a link and everyone landed on the homepage. Query strings are the least structured part. They are just key-value pairs separated by ampersands, and they do whatever the server decides to do with them. /search?q=shoes&page=2 is conventional, but there is nothing enforcing that. Some sites put state in the path, some put it in cookies, some use session tokens in the query string, which is a security problem if those URLs end up in server logs or browser history. I spent two days troubleshooting a redirect loop last year involving a URL that looked perfectly normal. The problem was a trailing slash mismatch combined with a misconfigured .htaccess rule on an Apache server. One version of the URL had a slash at the end, the other did not, and the rewrite rules were sending each to the other in an infinite cycle. The fix was adding a single RedirectMatch directive that told Apache to canonicalize trailing slashes once and stop second-guessing itself. That kind of thing does not show up in any tutorial.
Encoding is another area where people regularly shoot themselves in the foot. Spaces become %20 or + depending on whether they are in the path or query string. Special characters need percent-encoding, and browsers do not always handle this consistently. I had a case where a user pasted a URL containing a German umlaut, the browser sent it as-is without encoding, and the server rejected it with a 400 Bad Request because it expected UTF-8 percent-encoded bytes. The workaround was implementing a client-side encoding step before the request went out, using encodeURIComponent on the pathname and search portions separately. Port numbers are rarely visible because browsers default to 80 for http and 443 for https, but specifying a different port changes everything about where the request goes. localhost:8080 is a completely different destination from localhost:443, even though the hostname is identical. Development environments abuse this constantly, and it causes confusion when people copy URLs between environments without adjusting the port. Fragment identifiers, the part after a hash symbol, never reach the server. Your browser sends everything up to the #, and the remainder stays client-side. This is why page anchor links work, but also why putting sensitive data in a fragment is useless for security purposes. The server never sees it, but it lives in your browser history and gets sent to any JavaScript running on the page.
Get the Full Details

Relative URLs are deceptively powerful. /about is resolved against the current domain, ./about against the current directory, and ../about against the parent directory. This is standard behavior across every browser, but it breaks predictably when people assume a relative URL will resolve the way they expect after a redirect. If you link to /about from /blog/ and then the server redirects /blog/ to /blog, your relative link might end up pointing to /blog/about instead of /about, depending on how the browser resolves it. The biggest practical issue I see is people treating URLs as permanent identifiers for content. They are not. A URL can change, a page can move, a domain can expire, and the web has no built-in guarantee that a URL you save today will work tomorrow. The workaround is using canonical URLs and implementing proper 301 redirects, but most small sites skip both because they do not want to maintain redirect rules. The result is broken links everywhere, and search engines eventually stop trusting the site. Another thing nobody talks about is URL length limits. The old RFC standard said 2048 characters, but modern browsers support much longer URLs. The real constraint is the server, and some web frameworks have hard limits around 8192 characters for the request line. Go past that and you get a 413 Payload Too Large error, which most people interpret as a server configuration problem when it is actually just a URL that is too long. Query strings with encoded data can blow past this quickly if you are passing large tokens or embedded content.
Security-wise, URLs expose more than most users realize. They leak into server logs, browser history, proxy caches, and Referer headers. If your URL contains a session token or personal identifier, anyone who sees the Referer header from a page on your site linking to a third party now has access to that information. The common mitigation is moving sensitive data out of the URL entirely, into POST bodies or secure cookies, but legacy systems often keep it in query parameters because that is how they were originally built. URLs also shape what people trust. A domain like example-store.com with an HTTPS certificate and a clean path structure looks more legitimate than a URL full of random characters and subdirectories. Phishing sites exploit this by using lookalike domains and shortening services to mask the true destination. URL shorteners specifically remove any visible signal about where you are actually going, which is why they are heavily associated with spam campaigns. There is no universal tool for auditing URLs at scale, but a combination of cURL for manual inspection and Burp Suite for deeper analysis covers most practical needs. I use cURL with the -I flag to check response headers and redirect chains without downloading the full page, and Burp when I need to see exactly what the browser is sending at the packet level. For bulk validation, a simple Python script using the requests library with follow_redirects disabled can check hundreds of URLs against expected status codes and response times in under ten minutes.
Understanding how URLs work does not make you immune to problems, but it does help you diagnose them faster. A 404 is not always a missing page. It can be a case-sensitivity issue on a Linux server, a missing rewrite rule, or a URL that was cached by a CDN with the wrong variant. A 301 redirect might be sending traffic to the wrong protocol if your server configuration is inconsistent. Most URL issues are configuration issues in disguise. The web would function adequately without most of the nuances I described, but it would be significantly less predictable. URLs are the backbone of every interaction that happens online, and the way they are structured determines not just where you end up, but how fast you get there, whether your data stays private, and whether the link you saved last year still works today.