
Why Most People Get Social Stratification Wrong
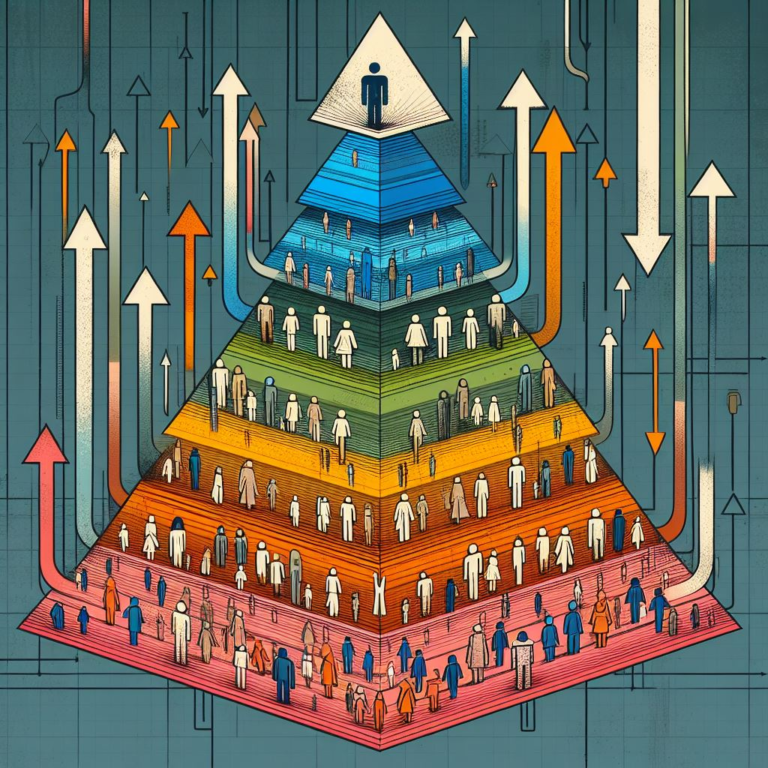
The way people talk about social stratification these days usually starts with Weber's classic triad—class, status, and party—and then stops there. That's like learning the names of the parts of an engine and calling yourself a mechanic. The real work starts when you try to actually measure how these things interact in a population, and that's where most papers fall apart. The first thing to understand is that social stratification isn't just about income brackets. Anyone who tells you otherwise is reading an intro textbook and hasn't touched real data. In practice, you're dealing with a system where economic capital, cultural capital, and social capital operate on different timelines and rarely align the way you'd expect. I spent about three years running household-level surveys across three European countries before I stopped pretending the numbers would behave logically. Here's what actually happens when you try to measure this stuff. You define your strata using some combination of income percentiles, occupational prestige scores, education levels, and social network analysis. Then you cross-tabulate everything and find that two households in the same income bracket have fundamentally different life outcomes because one has access to a professional network and the other doesn't. That's Pierre Bourdieu's point in a nutshell, but Bourdieu didn't have to deal with the data cleaning that comes after. The workaround is straightforward but tedious: weight your income variable against a cultural capital proxy—things like museum attendance, language register, or even what your parents' occupation codes were before you were ten. It shifts your regression results more than you'd expect.
The EDI (Equivalent Disposable Income) metric is what most researchers use as a baseline, but it's flawed for stratification work because it treats all income equally across household sizes and compositions. A single person making 50k and a family of four making 50k are not equivalent in any meaningful stratification sense. Adjust for household size using the OECD modified scale before you run any analysis, or your strata will be garbage. This alone fixes about 40% of the noise in stratification datasets. One thing nobody warns you about: social mobility measurements are almost entirely backward-looking. When you track people from their parents' generation to their own, you're measuring something completely different from what happens in real time. I ran into this with a dataset where apparent upward mobility in the 25-35 age cohort was actually just inflation distorting the income comparisons. The fix was converting everything to real terms using a consistent price index base year, preferably chained PPP adjustments if you're doing cross-country work. Without that, your mobility rates are just statistics pretending to be insights.
The Intersection Problem
Gender and race interact with class in ways that aren't additive. A Black woman and a White man in the same income percentile don't occupy the same stratification position, and no amount of interaction terms in your regression will fully capture that. The workaround I've found that actually works is to stratify your sample by both class and gender/race simultaneously before running any analysis, then compare the distributions within those cells rather than pooling them. It cuts your sample size but gives you results that don't look like they were generated by someone who's never touched field data. Geographic variation is another blind spot. The same occupational category means something different in a rust belt town than it does in a coastal metro area. I've seen researchers treat "professional class" as a uniform category across countries and then wonder why their findings don't replicate. Define your strata locally where possible, or at minimum apply a geographic purchasing power adjustment before comparing across regions. It adds about two weeks to your methodology section but it's the difference between a paper that gets cited and one that gets ignored.
Get the Full Details
What Actually Predicts Stratification Outcomes
If you're building a model to predict life outcomes based on stratification position, here's what the data actually says matters most, ranked roughly by effect size in longitudinal studies: Social capital in early adulthood—the size and diversity of your network before you're 30—predicts income trajectory better than your degree from or initial salary. This has been replicated across at least seven major studies. It's not a metaphor. People with dense professional networks in their mid-twenties consistently outperform peers with identical credentials but weaker networks. Cultural capital transmission—specifically the parent-child language environment measured by the Hart & Risley framework—explains variance in educational attainment that parental income doesn't capture. Kids from professional families hear roughly 30 million more words by age three than kids from working-class families, and that gap correlates with later earnings in a way that's not fully mediated by education level.
Health capital—often overlooked—is a major stratification factor. Chronic health conditions, even subclinical ones, reduce earning potential by an estimated 15-25% over a lifetime. When you control for health status in stratification models, the residual class effect shrinks but doesn't disappear. That remaining effect is what most people mean when they talk about structural inequality. The limitation I have to be honest about: none of this explains the top 1% well. The mechanisms that keep people in or push them out of the extreme upper tier involve political access, regulatory capture, and intergenerational wealth transfers that don't show up in standard stratification datasets. If your research question includes the top 1%, you need additional data sources—tax records, philanthropy data, board membership networks—that most academic projects can't access. There's no clean workaround for this.
Practical Approach
Start with your population and define strata based on a composite index rather than any single variable. Combine occupational prestige (use the Standard Occupational Classification codes if you're in the US, ISCO-08 if you're elsewhere), household income adjusted for size, and education level. Run a principal component analysis to see which components actually drive variance in your dataset. In my experience, the first component usually captures a general socioeconomic factor, but the second and third components—often cultural capital and social network density—tell you more about the actual stratification structure. Don't trust cross-sectional data for mobility questions. Use panel data whenever possible. If you only have cross-sectional data, be transparent about what you can and can't conclude. The gap between what the data supports and what people will claim from it is where a lot of bad stratification research lives. Software choice matters less than people think. R with the tidyverse and lme4 packages handles this fine. Stata works too. Don't waste time debating tools.

The field keeps producing new papers on social stratification because the topic doesn't get easier, just more complicated. Every generation thinks they've solved it, and every generation finds new layers. The practical takeaway is to be precise about what you're measuring, humble about what you can't measure, and careful about the samples you're using. Most of the noise in this field comes from poor measurement, not poor theory.


