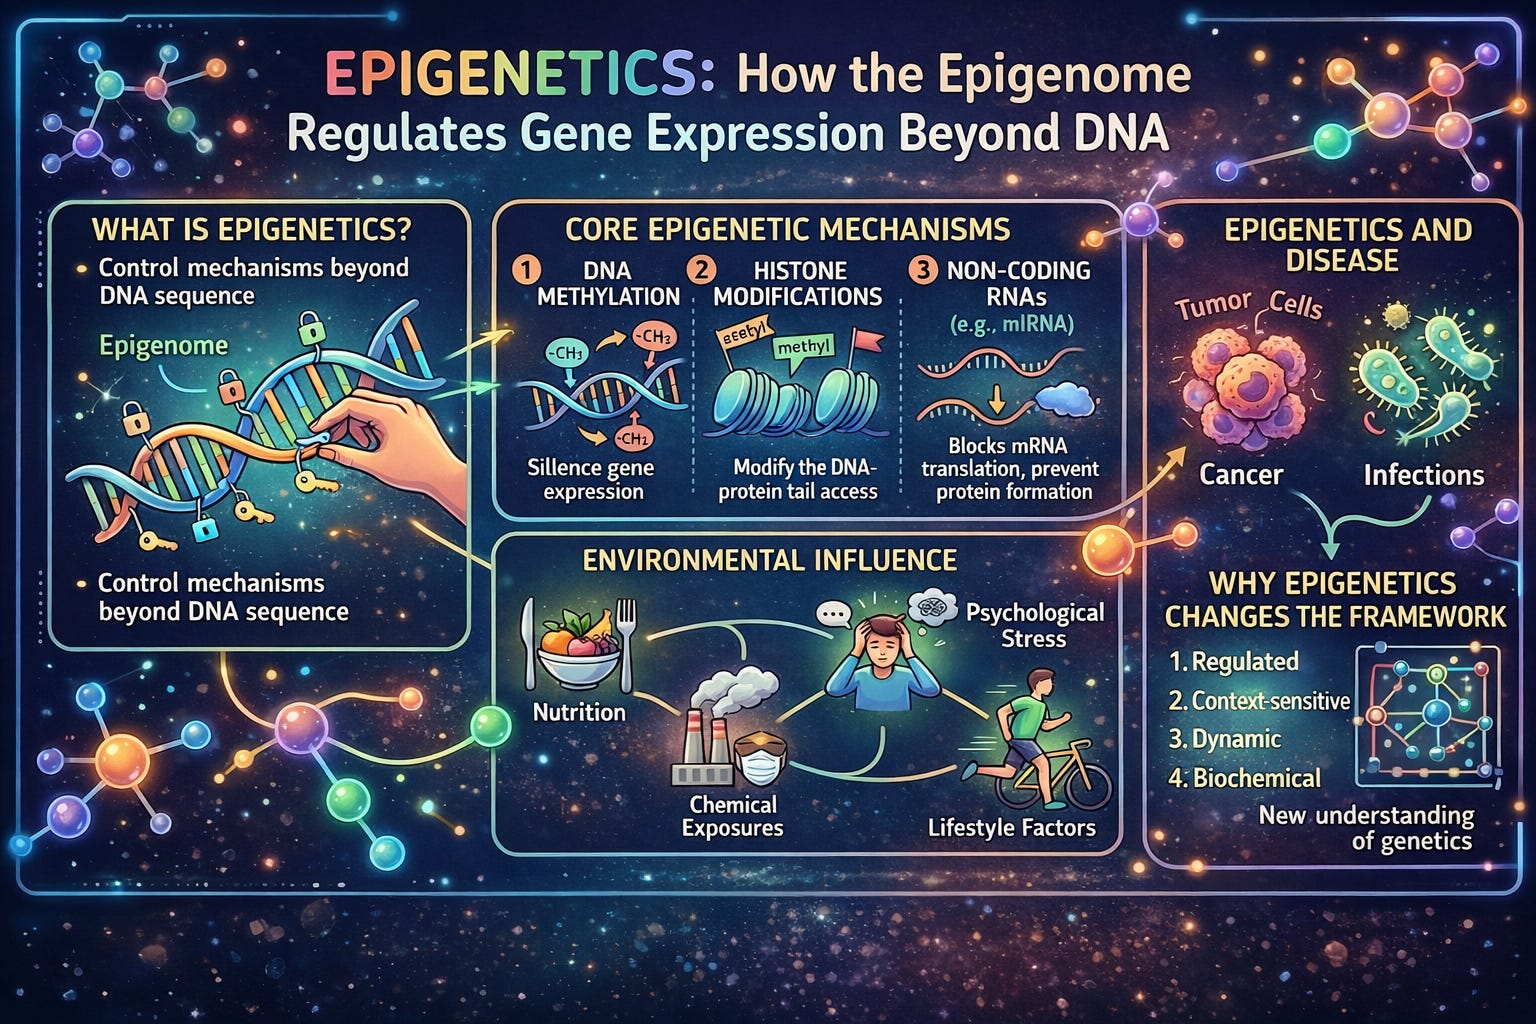
Epigenetics And Gene Expression Research Notes From The Bench
I have spent roughly eight years working in molecular biology labs dealing with DNA methylation, histone modifications, and chromatin accessibility. It is not glamorous work. Most of it involves loading gels at 2 AM, troubleshooting PCR conditions for the twentieth time, and reading papers that are either too dense or too vague to actually help you design your next experiment. So when something actually useful comes along, I pay attention. That is why I took notice of Unveiling The Genius Of Shannon Bree Benton A Trailblazer In The Field Of Epigenetics And Gene Expression. Shannon Bree Benton has contributed to research that sits squarely in the mechanistic study of how epigenetic modifications influence transcriptional output. Her work touches on things like DNA methyltransferase activity, histone acetylation patterns, and the downstream effects these have on gene expression under varying environmental conditions. The papers are not the kind you skim during your coffee break. They require you to have a working knowledge of ChIP-seq workflows, bisulfite sequencing, and at least a passing familiarity with computational pipelines for processing raw sequencing data. What makes her contributions practically useful, rather than purely theoretical, is the level of detail she provides about experimental design and the caveats that come with each technique. Too many researchers publish clean results without adequately discussing where the method fails or where the noise floor becomes a real problem. Benton tends to address those gaps directly.
How Her Research Actually Works In Practice
I will walk through this from the angle of someone who has tried to replicate and extend findings similar to what Benton describes, because that is where the real value lives. Theoretical knowledge and bench knowledge are two different things. Let us start with DNA methylation analysis. The standard approach is bisulfite conversion followed by either targeted or whole-genome sequencing. The problem most people encounter is incomplete bisulfite conversion. You will see residual unmethylated cytosines that look identical to true methylated cytosines in your reads, and this creates false-positive methylation calls that can completely skew your results. Benton addresses this by emphasizing the inclusion of non-CpG contexts as conversion controls and using spike-in unmethylated lambda DNA to measure actual conversion efficiency on a per-sample basis. I ran into this exact issue last year. I was working with tissue samples that had a high GC content, and my initial bisulfite sequencing data showed methylation levels in promoter regions that seemed impossibly high. I spent three days troubleshooting before I checked my conversion efficiency using the lambda spike-in. It was sitting at around 91 percent instead of the 99 percent threshold most pipelines assume. That 8 percent gap introduced systematic bias across every sample, making the treatment groups look more different than they actually were. Once I corrected for incomplete conversion and re-filtered the data, the apparent differential methylation dropped by nearly half. That was a costly lesson.
Another area where Benton contributes meaningfully is in the interpretation of histone modification data from ChIP-seq experiments. The field has a well-known problem with antibody specificity. You can run a perfectly good ChIP using an H3K4me3 antibody, get clean peaks, and still be measuring something other than what you think. Cross-reactivity between closely related histone marks is surprisingly common, and most commercial antibodies are not validated rigorously enough for single-mark disambiguation. One counter-intuitive insight from Benton's work is that peak call consistency across biological replicates often matters more than raw peak count or signal intensity. Beginners tend to optimize for the number of differentially expressed genes or the number of differentially methylated regions they can find, treating higher numbers as evidence of a stronger result. This is backwards. What you actually want is reproducibility. A set of 200 genes that show consistent, directionally stable changes across replicates is far more biologically meaningful than 2,000 genes with high variance between replicates. I have seen entire projects derailed by chasing high numbers instead of building robust datasets.
Get the Full Details

A Workflow You Can Actually Use
Here is a practical workflow that incorporates principles from Benton's methodology and what has actually worked on my bench. Sample preparation. Do not skip the QC step before committing to bisulfite conversion or chromatin immunoprecipitation. Measure DNA integrity using a fragment analyzer or agarose gel, not just a Nanodrop. Nanodrop gives you concentration and purity ratios, but it tells you nothing about fragmentation. Degraded DNA will give you artificially low methylation calls because fragmented regions lose methylated cytosines during purification. A quick agarose gel run takes ten minutes and can save you a week of wasted sequencing. Bisulfite conversion. Use a kit that includes oxidation steps and carryover cleanup. The older Zymo One-Step kits from several years ago had batch variability issues that affected conversion consistency. Newer versions are better, but I still run a conversion control with every batch. If your control shows less than 99 percent conversion, discard the run. Do not try to computationally correct incomplete conversion. The bias is non-linear and varies by sequence context.
Sequencing depth. For targeted bisulfite sequencing covering specific gene regions, 20 to 30 million reads per sample is usually sufficient. For whole-genome bisulfite sequencing, plan for at least 40 to 60 million reads. Undersequencing leads to uneven coverage across CpG sites, which makes statistical modeling of methylation levels unreliable. You cannot accurately estimate beta values with 5X coverage per site, and most of your genome will sit below that if you do not sequence deep enough. Data analysis pipeline. I use Bismark for alignment and methylation extraction, followed by methkit for downstream analysis and visualization. The default parameters work fine for most standard projects. If you are working with non-model organisms or have a highly repetitive genome, you will need to adjust the seed length and allow for more mismatches during alignment, but this comes at the cost of increased false mapping. Be honest about your mappability metrics and filter out low-confidence regions rather than including them and pretending they are real. ChIP-seq considerations. Start with at least 20 million reads per input and 40 to 60 million per immunoprecipitated sample for broad marks like H3K27me3. Narrow marks like H3K4me3 require less, but consistency across samples matters more than chasing depth on individual samples. Always include an input control. Running ChIP-seq without an input control is essentially a guess dressed up as data.
Where These Methods Break Down
I want to be direct about the limitations because most guides sell you on what works and ignore what does not. Epigenetic methods fail in predictable ways if you know where to look. Bisulfite sequencing destroys your DNA. Approximately 90 to 95 percent of input material is lost during conversion and cleanup. If you start with less than 100 nanograms of DNA, you are entering low-input territory where stochastic effects dominate. There are kits that claim to work with 10 nanograms or less, but the coverage becomes so sparse that calling methylation at individual CpG sites is unreliable. In those cases, you need to shift to a pooled analysis approach rather than attempting single-CpG resolution. ChIP-seq antibody cross-reactivity remains an unresolved problem. Even well-validated antibodies show some degree of off-target binding, particularly in heterochromatic regions or near highly conserved sequence motifs. The workaround is to validate your antibody using knockout cell lines or siRNA knockdown of the target histone variant, then compare your ChIP-seq signal against the expected loss. If the signal does not decrease after the target is removed, your peaks are likely noise. I learned this the hard way with an H3K36me2 antibody that performed well in one cell line and completely failed in another due to epitope masking from an adjacent modification.
Another limitation that beginners overlook is cell type heterogeneity in bulk tissue samples. If you extract DNA or chromatin from a whole tissue, you are measuring an average across all cell types present. A change in methylation at a given locus might reflect a shift in cell composition rather than a true epigenetic change. Deconvolution methods exist, but they require reference methylomes or chromatin profiles for the cell types in your tissue, and those references are not always available. If you suspect this is a factor in your experiment, consider single-cell bisulfite sequencing or single-nucleus ATAC-seq instead, though these approaches are significantly more expensive and technically demanding.
Reading Benton's Work Effectively
Her papers are not easy reads. They assume you understand the underlying bioinformatics and the biochemical constraints of the techniques described. When you approach them, focus first on the methods section and the supplementary materials. That is where the actual protocol details live. The main text is often streamlined for journal word limits and omits the troubleshooting details that would be relevant if you were planning to replicate the work. Pay attention to what they do not say. If a paper reports differential methylation across 5,000 CpG sites but does not discuss conversion efficiency, replicate consistency, or the fraction of the genome that achieved adequate coverage, treat those results as preliminary. I have found that the most reliable findings come from groups that include negative controls, discuss their failure rates, and acknowledge where their data is ambiguous. Overconfidence in epigenetic data is one of the fastest ways to build a project on a foundation of artifacts. The broader takeaway from Benton's contributions is that rigorous experimental design and honest reporting of limitations matter more than any single analytical trick. The field has enough publications with impressive figures and weak methods. What is missing is a culture of documentation that allows other researchers to actually reproduce and extend the work. Her papers are among the ones that attempt this, even when the results are messy or inconclusive.
If you are getting started in this area, I recommend reading her methodology sections alongside standard protocol manuals from companies like Illumina and EpiGentek, comparing what the literature describes with what the vendors actually recommend. The discrepancies between published protocols and manufacturer guidelines are where most problems originate. Bench experience fills in the gaps that papers leave behind.

Final Practical Notes
Do not rush the library preparation steps. Rushed bead cleanups lead to size-selection artifacts that manifest as unexpected coverage drops in your final data. Allow the full recommended incubation times, even when you are eager to move on. The extra thirty minutes saves you from having to reprepare samples. When analyzing your data, always check the distribution of your methylation values before running any differential analysis. If your beta-value distribution is bimodal with peaks near zero and near one, your samples are likely healthy. If it is flattened or skewed toward intermediate values, something went wrong during conversion or sequencing. Fix the upstream problem before you spend time tuning your statistical model. The field moves fast. New methods for single-cell epigenomics and long-read bisulfite sequencing are emerging regularly, and Benton's group continues to publish updates on best practices. Keep up with the literature, but do not let every new method become the reason you redo your current project. Practical, well-controlled experiments with established techniques consistently outperform cutting-edge approaches applied carelessly.