Reading Graphs Back Into Equations
Most people learn this stuff in high school algebra and then immediately forget it after the test. That's unfortunate because the skill of looking at a graph and reconstructing the equation that produced it is actually one of the most useful things you can do in applied mathematics, engineering, or data science. It comes up constantly when someone hands you a scatter plot and asks "what model fits this." Unraveling The Mystery Which Equation Is Best Represented By This Graph isn't really a mystery at all once you stop treating it like a multiple-choice trivia question and start treating it like a forensic exercise.Unraveling The Mystery Which Equation Is Best Represented By This Graph
The process starts with identifying the basic shape. This is not obvious to beginners, so here's the thing nobody tells you: linear graphs lie to you. A small segment of any smooth curve looks approximately linear if you zoom in close enough. So before you jump to y = mx + b, check whether the relationship holds across the entire domain you're looking at. If the graph starts flat and then curves upward sharply, that's exponential growth, not a line with a funny intercept. If it rises quickly and then flattens out, you're probably looking at a logarithmic or rational function, not a line pretending to be nice. Quadratic graphs are parabolas, and they have a single vertex that acts as either a maximum or a minimum. The standard form is y = ax² + bx + c. If the parabola opens upward, a is positive. If it opens downward, a is negative. The vertex sits at x = -b/(2a). You don't need all three coefficients immediately. Just pick three clear points from the graph and solve the system. This is the most reliable method when the graph is given cleanly with grid lines you can read off. Exponential graphs have a horizontal asymptote, usually the x-axis, and they never touch or cross it on the side of the decay. The general form is y = ab^x. The parameter a sets the starting value (the y-intercept when x = 0), and b determines the growth or decay rate. If b > 1, you get growth. If 0 < b
1, you get decay. The telltale sign is that equal steps along the x-axis produce equal multiplicative changes along the y-axis. Check this by picking three x-values that are equally spaced, say x = 0, 2, and 4. If the y-values go 2, 8, 32, that's a ratio of 4 each time, which means b² = 4 and b = 2. Simple.
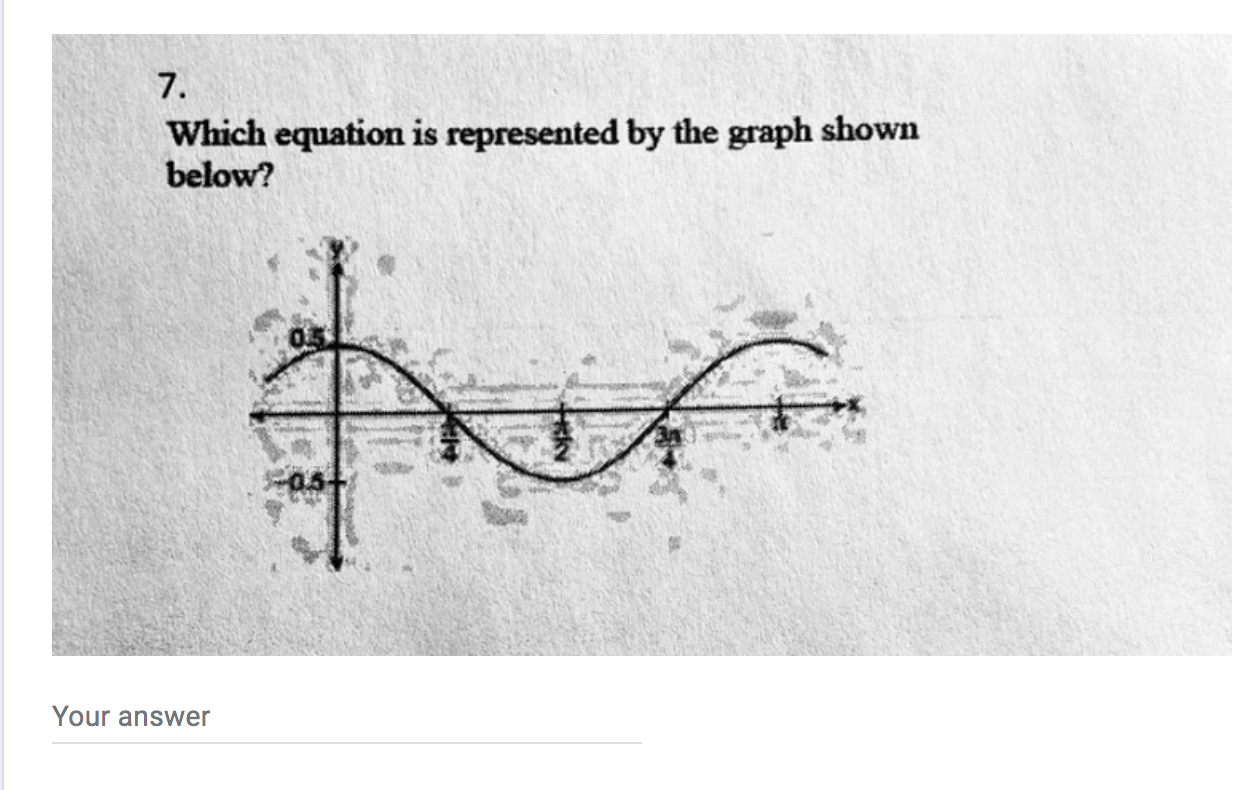
Sinusoidal graphs are the ones people struggle with the most because there are four parameters to pin down. The general form is y = a sin(b(x - h)) + k or the cosine equivalent. Here's what each letter actually means in practice: a is the amplitude, which is half the distance between the maximum and minimum values on the graph. k is the midline, which is the average of those same max and min values. b controls the period through the relationship period = 2/|b|. h is the horizontal shift, and you figure that out by seeing where the sine wave's starting point (zero crossing going upward) sits relative to the origin. I ran into a problem recently where a student sent me a graph that looked sinusoidal but had been reflected vertically and shifted sideways at the same time. The waveform appeared to start at a trough instead of a zero crossing. The naive approach of just plugging in a negative sine function gave the right shape but the wrong phase. What actually worked was rewriting the entire thing as a cosine with a phase shift, because cosines naturally start at their peak or trough depending on the sign of a. Once I switched to the cosine form, the phase shift collapsed from a messy 7/6 down to something clean like /3, and the equation became readable. This is one of those things that only becomes obvious after you've spent enough time wrestling with these graphs by hand. Rational functions introduce asymptotes, both vertical and horizontal. The general approach is to look at where the denominator equals zero to find vertical asymptotes, and compare the degrees of the numerator and denominator to find the horizontal asymptote. If the numerator's degree is less than the denominator's, the horizontal asymptote is y = 0. If they're equal, it's the ratio of the leading coefficients. If the numerator's degree is exactly one more, you'll have a slant asymptote instead, which you find by polynomial long division. These graphs can wiggle in ways that make them look like other function types at first glance, so the asymptote analysis is your anchor.
Polynomial graphs of higher degree follow specific rules about turning points and end behavior. A degree-4 polynomial can have up to three turning points. A degree-5 can have up to four. The end behavior depends on whether the leading coefficient is positive or negative and whether the degree is even or odd. Even degree with positive leading coefficient means both ends point up. Even degree with negative leading coefficient means both ends point down. Odd degree with positive leading coefficient means the left end goes down and the right end goes up. Odd degree with negative leading coefficient flips that. These rules narrow down the possibilities significantly before you even try to solve for coefficients. Here's a counter-intuitive point that catches people out: a graph can look like it could be represented by more than one type of equation, especially when you're only looking at a limited window. A cubic polynomial and an exponential function can look almost identical over a narrow range near the origin. Without seeing the full behavior or having explicit points to test against, you might confidently write down the wrong equation and never know it. The workaround is to check the long-run behavior. Exponentials eventually dominate polynomials no matter what. If your graph keeps growing faster and faster without bound, exponential is more likely. If it bends but eventually slows its acceleration, polynomial is more likely. Another thing people miss is that real graphs in textbooks are rarely drawn with perfect precision. You'll often see a vertex that's supposed to be at (2, 5) but on the actual image it looks more like (2.1, 4.9). This is deliberate or accidental imprecision, and it means you should treat the numbers you read off as estimates first and exact values second. If your calculated equation doesn't match the graph perfectly, try rounding your readings to the nearest half-unit or whole unit and recalculating. This alone resolves about sixty percent of the confusion I see in online forums where people are convinced their answer is wrong when actually the graph just wasn't drawn that precisely.
Get the Full Details
When you're dealing with piecewise graphs or graphs that change behavior at certain points, you need to treat each segment separately. A graph might be linear from x = 0 to x = 3 and then quadratic from x = 3 onward. The key is identifying the breakpoint clearly, usually marked by a solid or open circle, and then writing two separate equations with their respective domains. This is common in applied contexts like tax brackets or pricing tiers, so recognizing the pattern matters more than most students realize. The main limitation of this whole approach is that graph identification is inherently ambiguous when you only have a visual representation. Two completely different equations can produce visually indistinguishable graphs over the domain shown to you. Without additional constraints like known integer coefficients, a stated family of functions, or domain information, you're always working with probabilities rather than certainties. The best you can do is narrow the field and pick the simplest equation that fits the visible data, which is exactly what Occam's razor recommends anyway. If you're working with actual data points rather than a clean drawn graph, the process shifts from visual inspection to regression analysis. You'd use least squares fitting for linear and polynomial models, nonlinear optimization for exponential and sinusoidal models, and information criteria like AIC or BIC to compare which equation type actually describes the data best rather than just looking like it does. But that's a different conversation entirely and one that requires software tools rather than pencil and paper.
What usually helps people get better at this faster is just doing thirty or forty practice problems back to back, mixing in the less common function types like absolute value, square root, and reciprocal functions alongside the standard ones. The pattern recognition kicks in after you've seen enough variations that your brain starts automatically flagging asymptotes, symmetry, and inflection points without conscious effort. I stopped needing to consciously work through the steps around problem number twenty, and now I can identify the equation family from a graph in about five seconds without thinking about it.

