Understanding Dallas Crime Data Maps
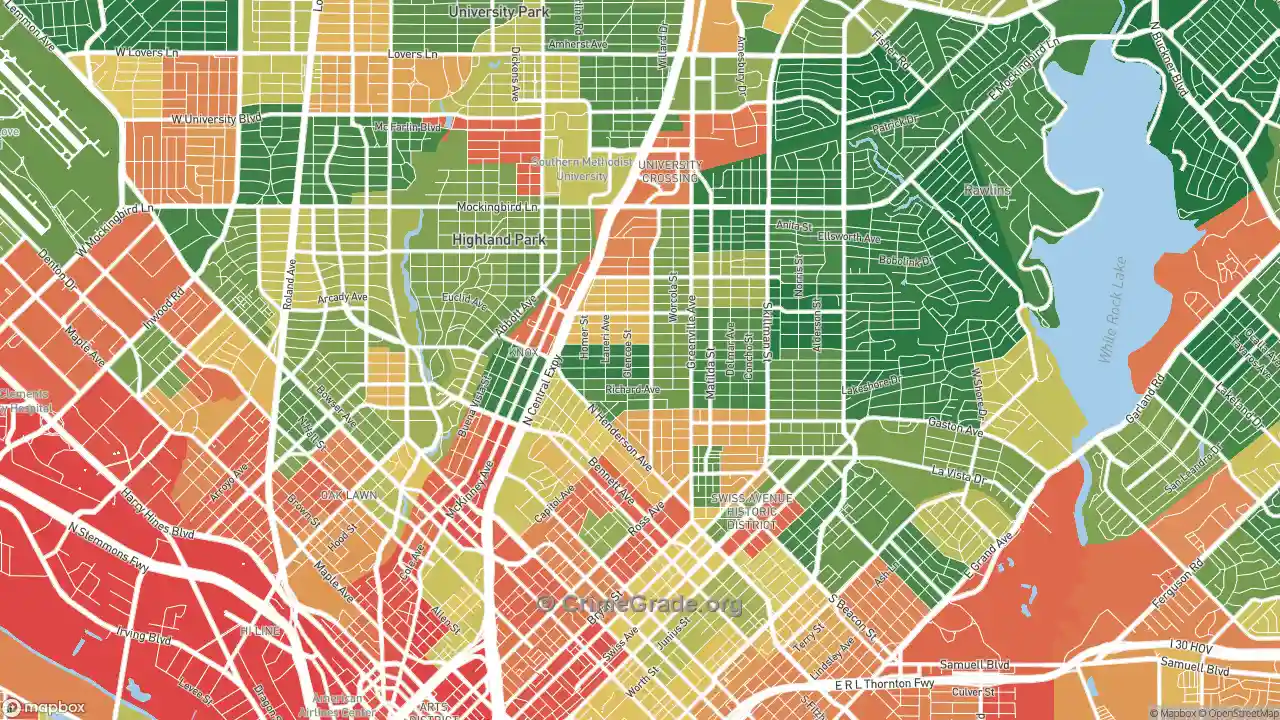
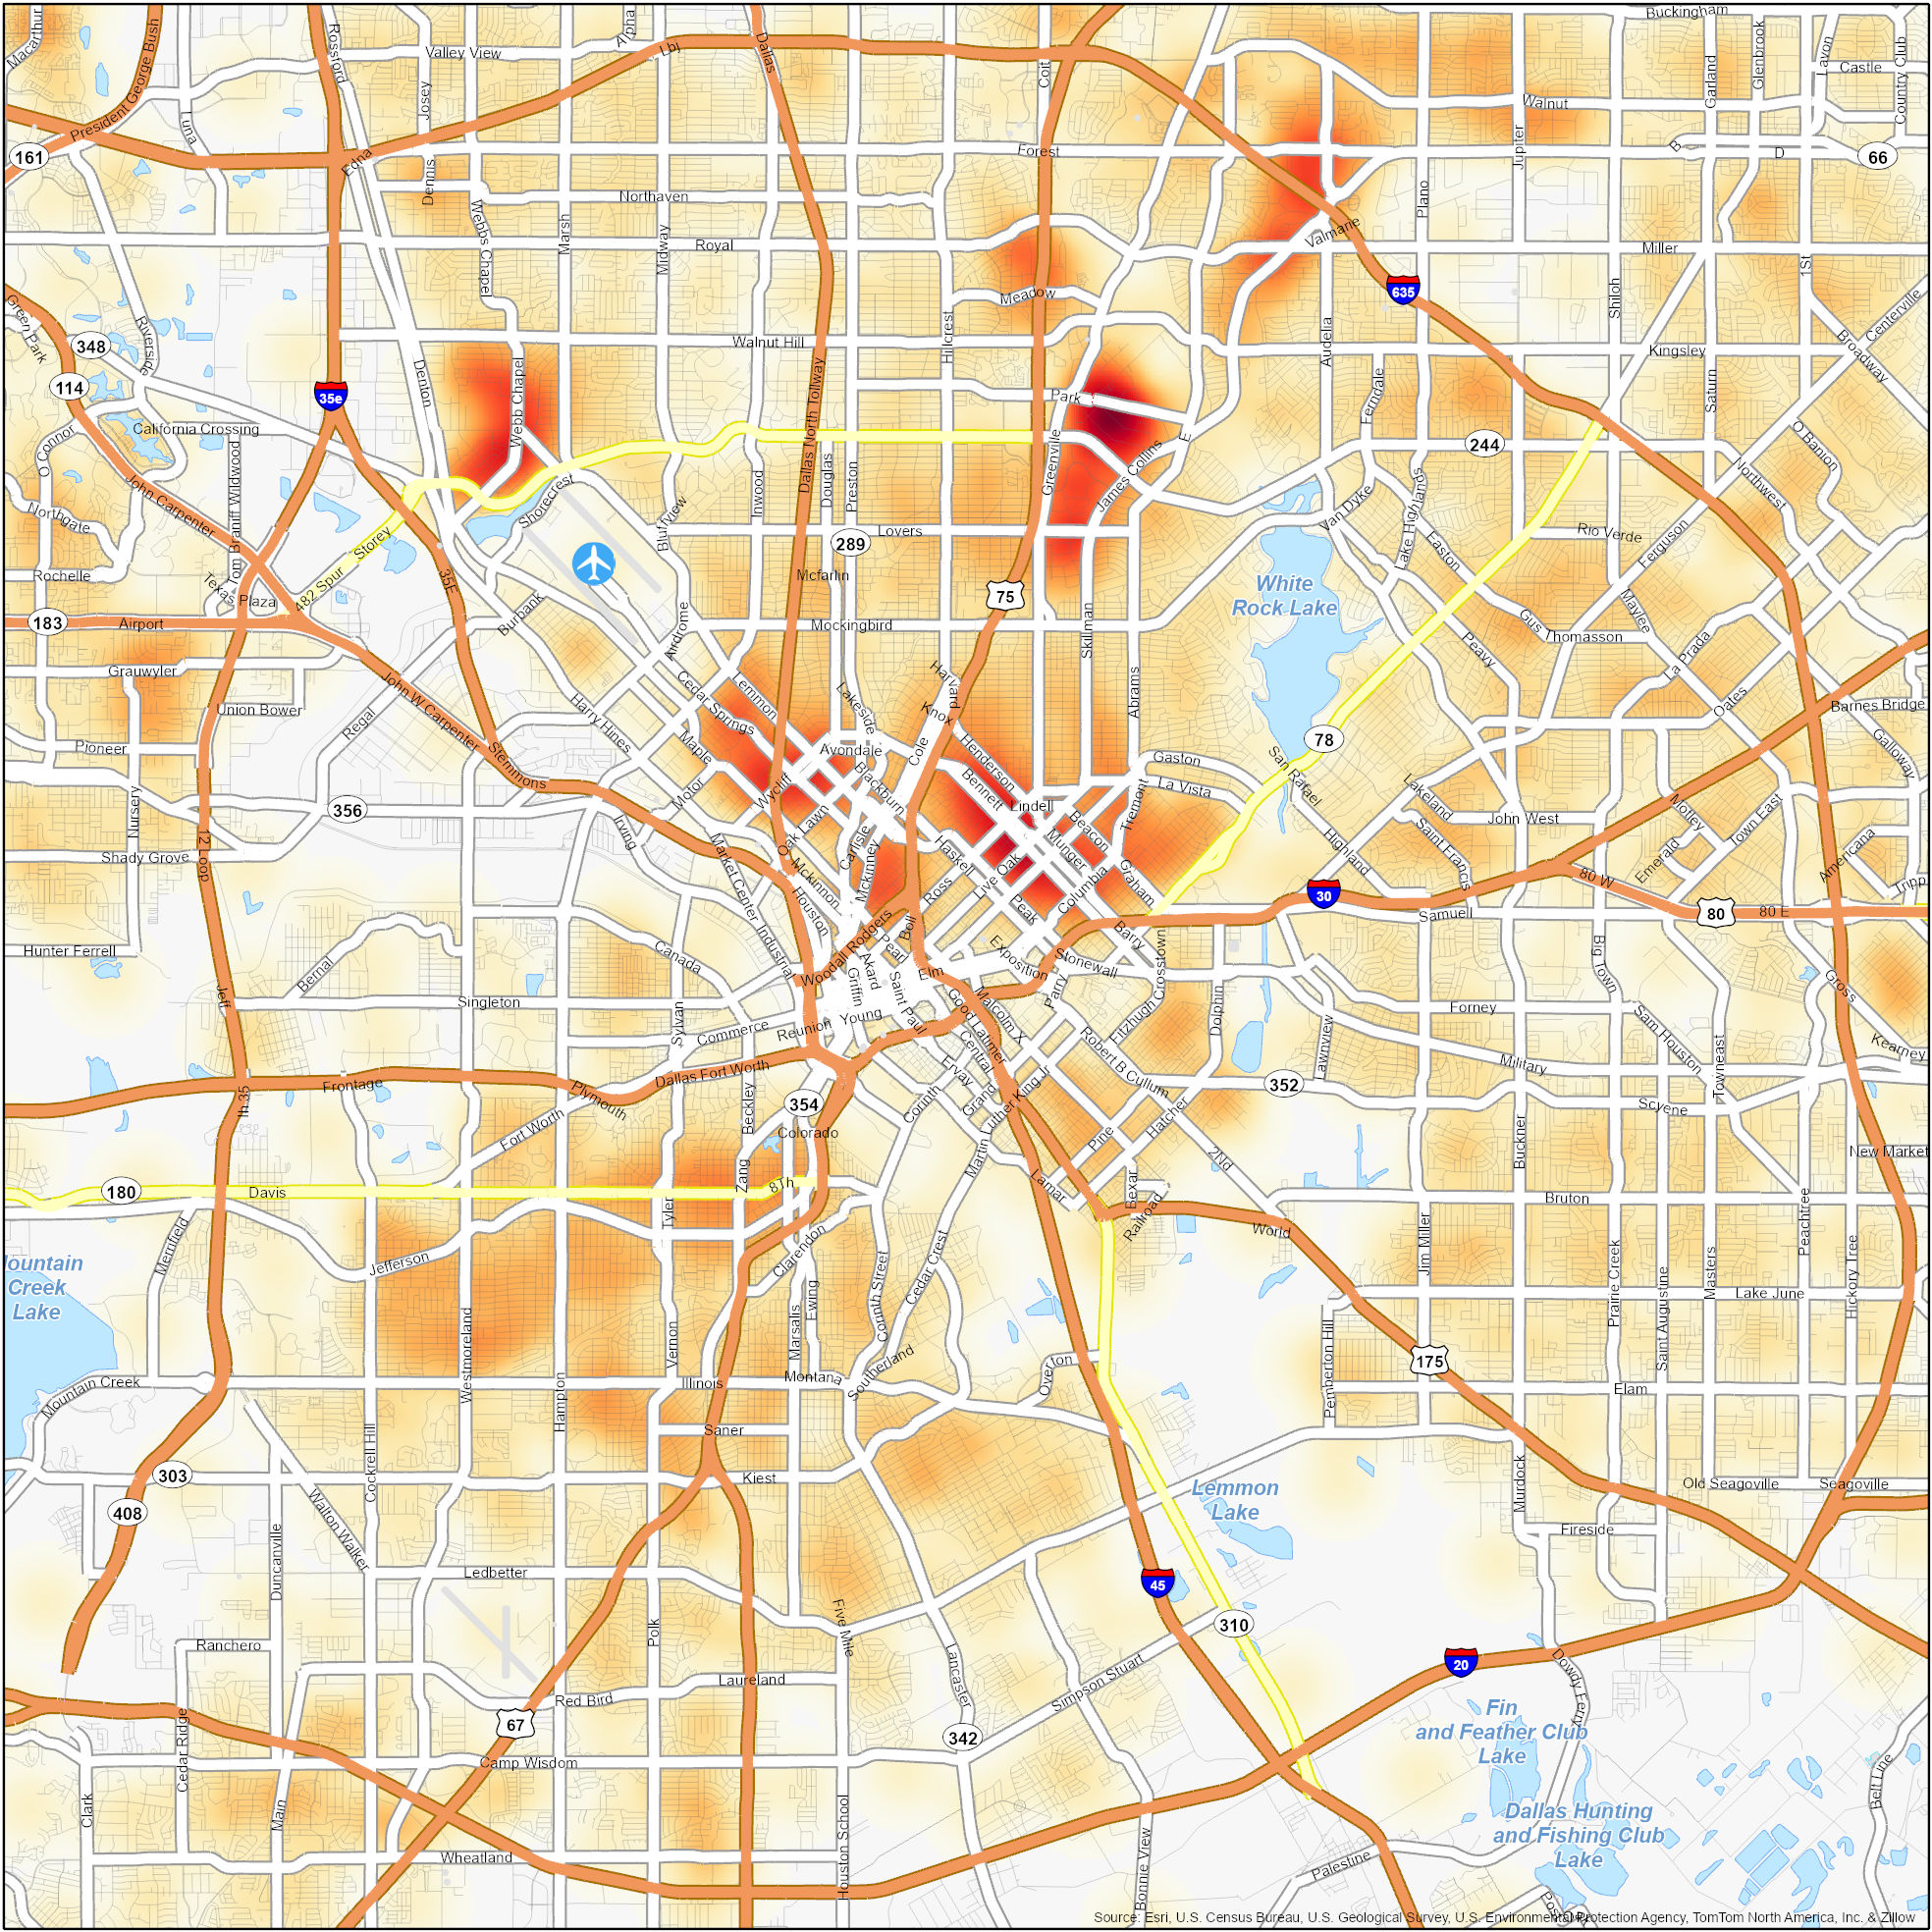
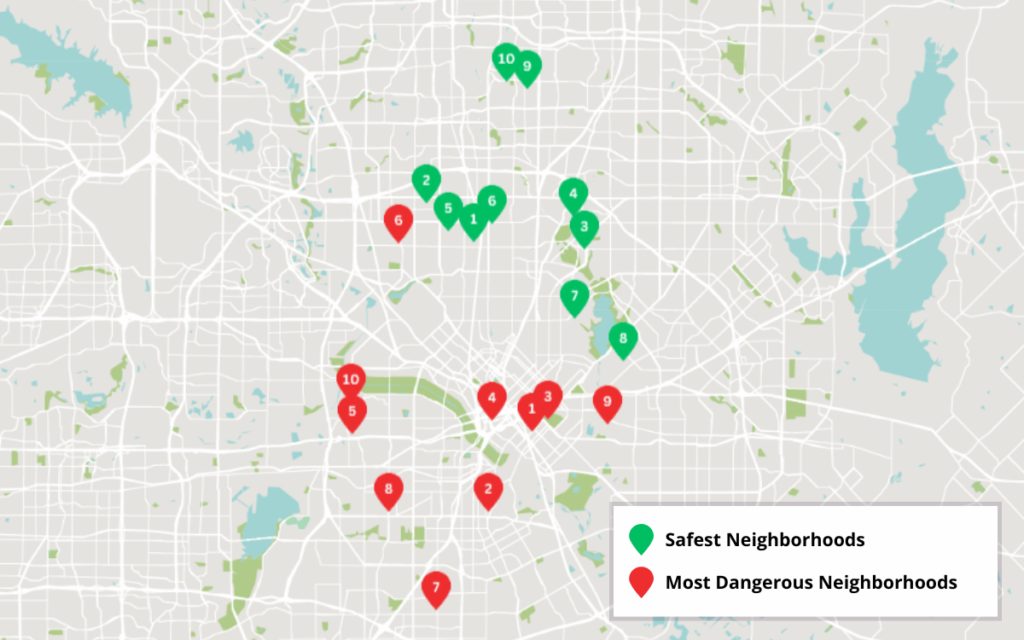
Crime mapping in Dallas has evolved past simple dot plots on a street grid. The current generation of tools lets you layer incident types, time windows, demographic correlates, and patrol zone boundaries into something actually useful for analysis. I spent most of last year auditing what these dashboards can and can’t do before recommending any to people in my network. The raw data comes from Dallas Police Department public releases, typically CSV exports or API endpoints tied to case timestamps, GPS coordinates, and offense classifications. The trick is cleaning that data so it doesn't mislead you. I've seen plenty of people import raw feeds and immediately draw conclusions about neighborhood safety based on unfiltered point counts, which is a mistake almost as old as the platforms themselves.
Unlocking The Truth A Deep Dive Into Dallas Crime Maps Insights
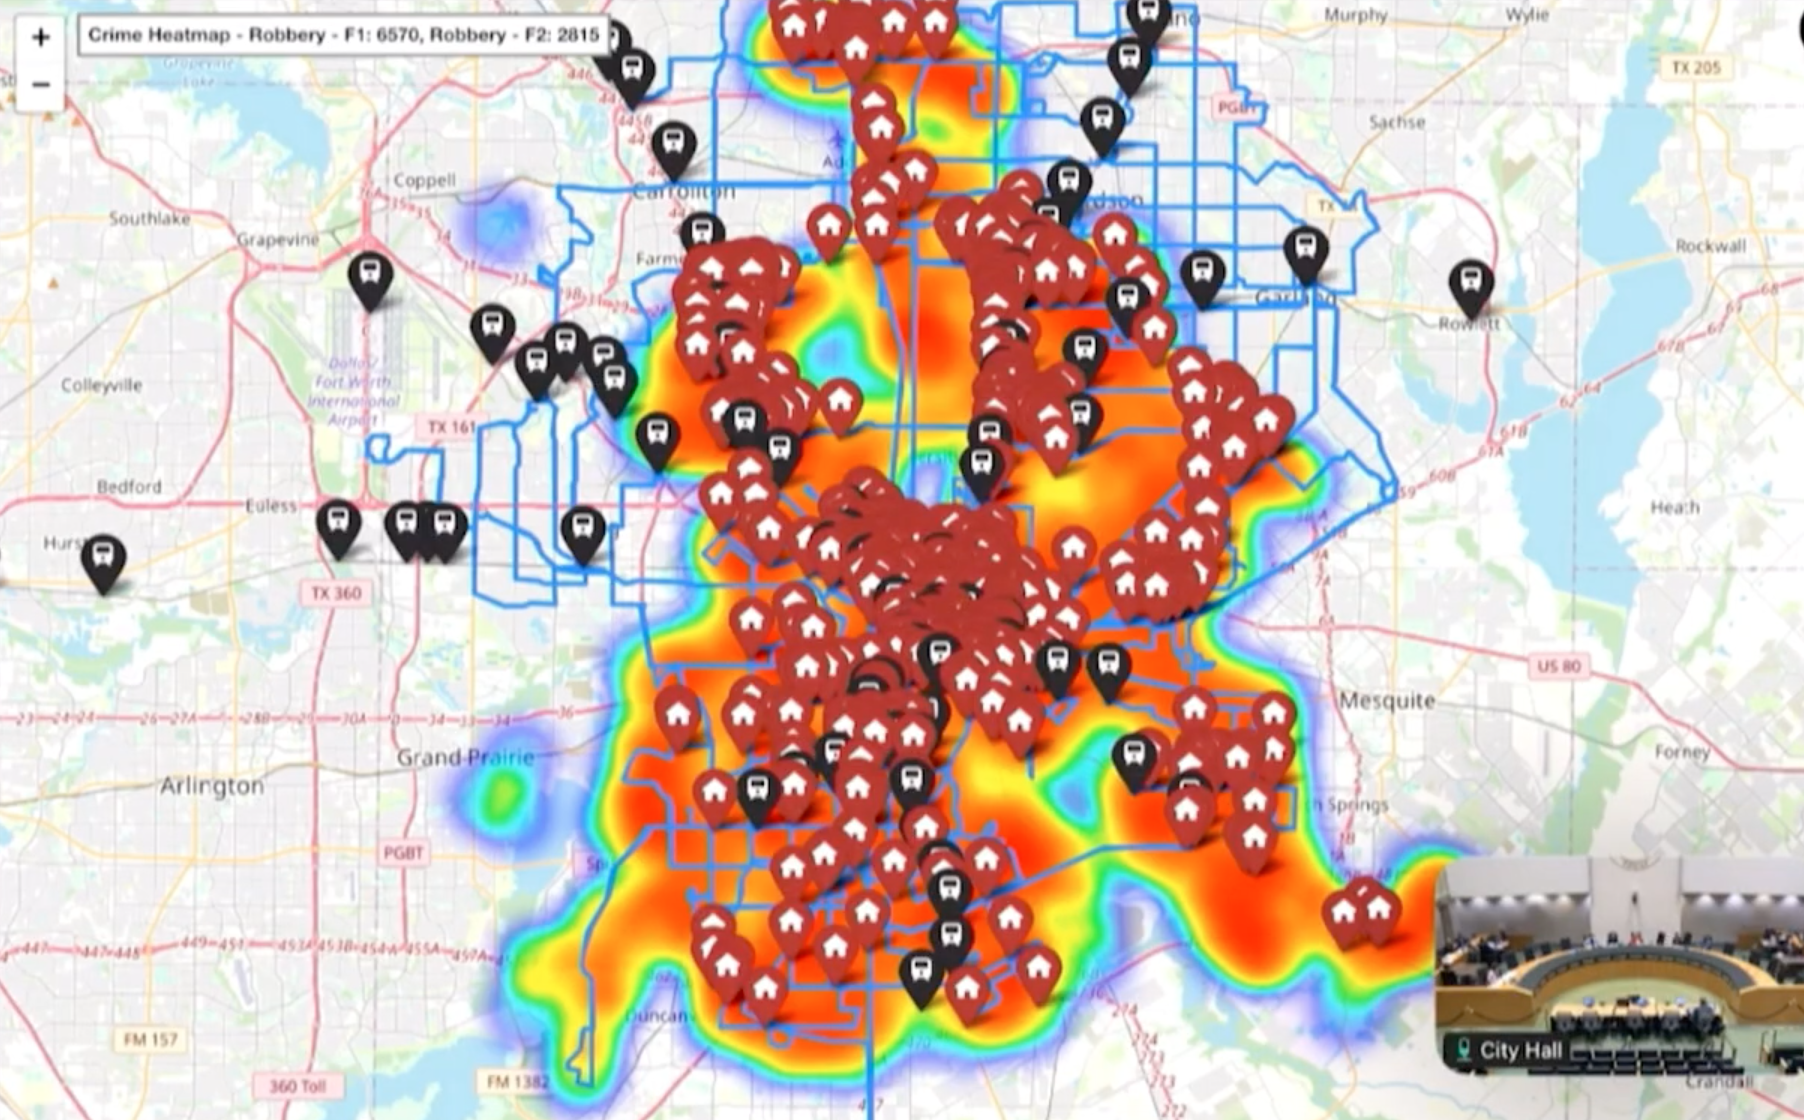
When people talk about "unlocking the truth" with crime maps, what they usually mean is figuring out how to read these tools without falling for common visual distortion techniques. Heat maps compress data in ways that make sparse areas look dense. Bubble charts do the same in reverse. The real insight comes from understanding the underlying methodology, not just looking at the pretty colors. Here is what happens from incident report to interactive map. Dallas PD logs an incident. An officer enters the location as GPS coordinates, usually accurate to within a few meters for street-level events. The record gets tagged with an offense code, a date stamp, and sometimes a time range. That data flows into a central repository, gets geocoded if coordinates are missing, and then becomes available through published endpoints or scheduled downloads. Most public-facing dashboards pull from the secondhand version of this pipeline. They are cleaned, deduplicated, and sometimes redacted. If you want the raw feed, you request it through the city's open data portal. Processing a full year of data through a standard geocoding pipeline takes roughly forty-five minutes on a modest local machine. The visualization step afterward depends entirely on what tool you are using.
What Most People Miss About Crime Mapping
The biggest blind spot I keep seeing is reporting bias built into the data itself. Not every crime gets reported. Not every report gets coded the same way across different precincts. A burglary in one area might get logged as a different offense type in another if the responding officers interpret the scene differently. This means point density alone is never a clean measure of actual crime volume. Another thing nobody warns beginners about is the ecological fallacy. Looking at a map and saying a whole neighborhood is dangerous because half the dots cluster there is statistically unsound. Those dots represent individual incidents, not residents. Many of them happen in commercial corridors, transit hubs, or public spaces where large numbers of people pass through. The residential impact is a completely different question that requires additional data layers to answer properly.
Get the Full Details

My Experience With A Specific Edge Case
Last fall I was helping someone analyze a six-month window in the Oak Cliff area. The dashboard showed a sudden spike in property crimes that looked alarming at first glance. When I dug into the raw CSV, I found that the spike correlated exactly with a policy change where officers started coding certain theft-by-forgery incidents as fraud instead of larceny. The total incident count barely moved. The visual pattern changed dramatically because the classification shifted. The workaround was straightforward. I stopped using offense-type filters for headline analysis and switched to a broader category view that grouped related codes together. I also pulled the original incident notes for a random sample of fifty records and cross-referenced them against the code assignments. This took about three hours but saved the entire analysis from being completely wrong. If you are working with Dallas crime data seriously, budget time for validation before you trust the visual output.
Recommended Tools And Where To Access The Data
The official Dallas Open Data portal at dallasopendata.com hosts the crime dataset with download options. The API supports date-range queries and field filtering. For visualization, I have used QGIS for static mapping work and Keen.io for interactive dashboards, though the platform landscape changes frequently. Commercial options like ArcGIS Online handle larger datasets more cleanly but cost money. If you just want to explore quickly without building anything custom, several third-party aggregators pull the Dallas feed and add their own styling. These are fine for casual use but you should always verify critical findings against the source data. The original dataset has fields like incident ID, offense code, location type, and timestamp that aggregated versions sometimes strip out for simplicity.
Common Pitfalls To Avoid
Timezone mismatches are surprisingly common. Some systems store timestamps in UTC and others in Central time. If you are comparing Dallas data against national datasets, you will get shifted patterns unless you normalize everything to the same offset. I lost an afternoon to this once when I thought I was seeing a weekday versus weekend crime pattern difference that was entirely artificial. Another frequent error is assuming spatial precision matches reporting precision. GPS coordinates from police reports are usually accurate, but when incidents occur near boundaries or in large complexes, the coordinate might snap to the nearest addressable point. This creates artificial clustering along major roads that does not reflect actual incident distribution. Running a small buffer analysis, say two hundred meters around high-density zones, usually reveals whether the pattern is real or an artifact.

Practical Workflow For Serious Analysis
Start by downloading the raw data for your target period. Clean it locally using Python or a spreadsheet tool. Validate a sample of records against the source if possible. Build your initial visualization with broad category groupings rather than specific offense codes. Test alternative classifications to see if your conclusions hold. Add demographic or land-use layers only after you are comfortable with the core incident data. This sequence usually takes one to two days for a focused regional analysis, depending on your familiarity with the tools. The process is tedious but necessary. Crime maps are persuasive by design. They look authoritative because they combine geography with numbers in a format people intuitively understand. That persuasiveness is exactly why you need to understand the plumbing behind them before sharing any findings with others or using them to make decisions.
When Crime Maps Fall Flat
There are scenarios where these tools simply cannot give you useful answers. Predictive policing claims, for example, often rely on historical crime data projected forward. The underlying assumption is that past patterns reliably predict future hot spots. That assumption breaks down whenever there is a structural shift in policing strategy, economic conditions, or population movement. I have watched well-meaning analysts present six-month forecasts based on one year of data and get burned when the model failed to account for a new patrol deployment or a closing of a major employer. Crime mapping also struggles with victimless crimes and low-reporting offenses. Drug-related incidents, domestic violence, and harassment are systematically underrepresented in public datasets compared to violent property crimes. If your analysis focuses only on what the map shows, you will paint an incomplete picture of actual community safety dynamics.
Where To Go From Here
Start with the official Dallas dataset. Spend time just reading the field descriptions and codebooks before you build anything. Pick a small geographic area and a short time window and walk through the entire pipeline manually. You will catch misunderstandings faster this way than by jumping into automated workflows. The effort pays off every time you need to explain your methodology to someone else or defend your conclusions against a skeptical reader. The tools keep improving. Better geocoding, faster rendering, more transparent methodologies. The fundamentals have not changed much. Data quality determines everything. Understanding what you are looking at matters more than any fancy visualization feature. Take the time to learn the gaps in the system. You will produce better work and avoid looking foolish when someone points out the obvious blind spot you missed.