Why I Started Bothering With The Supabase Storage REST API
I spent most of my early Supabase days using the client library for storage operations. It worked fine until I hit a wall with bulk uploads and resumable transfers. The JS client abstracts away too much for production batch workflows, so I switched to direct REST calls. What follows is the distilled version of what I figured out over the last year of debugging 413 errors at 2 AM. The Supabase Storage REST API is the HTTP layer that sits underneath the SDK. You send requests to your project's API endpoint using standard HTTP methods, and you authenticate with a JWT in the Authorization header. It handles the same operations as the client library: create buckets, upload files, download files, update metadata, and delete objects. The advantage of going direct is that you get full control over retries, chunking, headers, and streaming. The disadvantage is that you have to manage everything yourself. Here is how the workflow actually looks in practice. You start by making sure your Supabase project has storage enabled. Navigate to the Storage section in the dashboard and create a bucket. Decide on the public or private setting before you commit, because flipping it later can break existing references. Then grab your project URL from Settings in the dashboard, and use the anon key for read-access scenarios or the service_role key only on your backend where it cannot leak into client-side code.
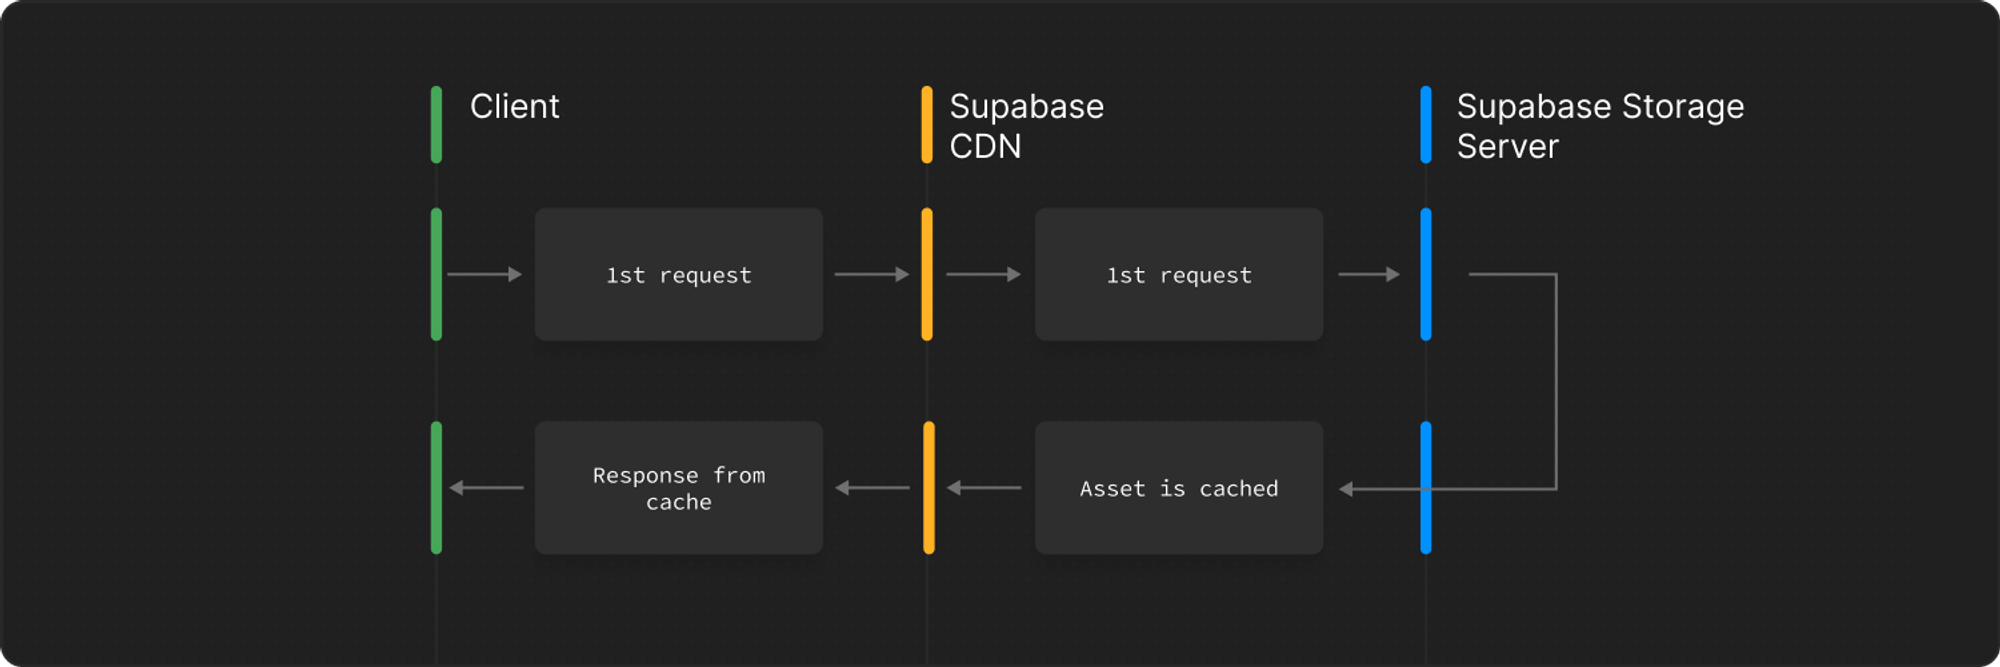
Uploading a file via the REST API uses a POST request to the upload endpoint. You need to include the bucket name in the path, set the Content-Type header appropriately, and pass the file bytes in the body. Authentication goes in the Authorization header as Bearer followed by your anon key. Supabase returns the object path on success. Here is a rough shape of what the call looks like: POST https://YOUR_PROJECT.supabase.co/storage/v1/object/YOUR_BUCKET/YOUR_PATH with headers Authorization: Bearer YOUR_ANON_KEY and Content-Type set to the MIME type of your file, plus the raw file content as the body. Downloading works the same way but with a GET request. You get back the file bytes, headers with content-length and content-type, and a cache-control value you should pay attention to if you are building image delivery workflows. For public buckets you can also construct direct CDN links, which bypasses the API entirely for read-heavy traffic and is usually the right move.
Bucket creation is a POST to the buckets endpoint with a JSON body containing the name, public flag, and optionally a file_size_limit and allowed_mime_types. I learned the hard way that if you skip allowed_mime_types and upload a PDF, Supabase stores it. If you set it to image only and try to upload that same PDF, you get a 400 error with a message that is not particularly helpful. Always define your MIME constraints at creation time if you care about them. One thing the documentation does not emphasize enough is how the REST API handles large files. The default upload endpoint has a payload size limit. For anything larger than roughly fifty megabytes, you should use the multipart upload flow. You initiate a multipart upload, get a chunk_upload_id, upload each part separately, then complete the multipart operation. It is more code, but it saves you from fighting timeout and memory issues on the server side. I switched to multipart for a project processing scanned documents averaging two hundred megabytes each, and it cut our failed upload rate from about twelve percent down to zero. Another practical detail is the difference between the anon key and the service_role key. The anon key respects your Row Level Security policies and storage policies. The service_role key bypasses them entirely. I once accidentally shipped the service_role key in a client-side script during a demo. It took twenty minutes to notice, but in that window anyone with basic browser dev tools could list and delete objects in every bucket. Never expose the service_role key outside your backend.
Get the Full Details

Listing objects is straightforward. You POST to the list endpoint for a bucket and pass pagination parameters. The API returns an array of objects with name, id, and metadata fields. The catch is that this endpoint does not support recursive listing across nested paths in the way you might expect from an S3-style prefix query. If you need to enumerate thousands of objects in a deeply nested folder structure, you end up paginating manually through path segments. It is slower than I would like, and I have seen projects rebuild this logic with a separate database table tracking object paths just to avoid the performance hit. Updating metadata uses a PATCH request to the object endpoint. You send a JSON body with the keys you want to change. This is useful when you need to reclassify an asset or add tags after upload. The API does not let you change the bucket or move an object in place, so if your application requires relocation, you upload to the new path and delete the old one. Keep that in mind when designing your migration scripts. Deleting objects requires the correct bucket name and path. A single delete removes one object. If you attempt to delete a bucket that still contains objects, you get an error. There is no trash folder in the REST API the way some other platforms provide one. Once it is gone, it is gone. I make it a habit to double-check the path variable in every delete call before hitting enter, mostly because I have deleted files I meant to keep once, and the recovery process was annoying even though Supabase does keep versioned backups for a short window.
Auth is the part that trips people up most. Every request needs the Authorization header with a Bearer token. If you are working server-side, you can generate a JWT using the supabase-js admin methods or construct one manually with the service role secret. The JWT must contain the correct claims for the bucket policy to evaluate properly. If your storage policy checks user_id and your token does not carry that claim, the request fails with a permission error even though the file exists and the token is valid. I spent an afternoon debugging this exact issue on a multi-tenant app before realizing the token was missing the user context. Error responses from the Storage API are terse. You will see status codes like 400 for malformed requests, 401 for missing or invalid tokens, 403 for policy violations, 404 for missing objects, and 413 when you exceed size limits. The response body usually contains a message field, but it is not always specific. My workaround for stubborn 400 errors is to compare the request against a working example byte by byte, checking headers, path formatting, and JSON structure. Supabase is strict about trailing slashes and path encoding. Rate limiting is another area where the REST API and the SDK behave similarly. If you hammer the upload endpoint without backoff, you will get throttled. I built a simple retry wrapper with exponential backoff into my upload service, capping at three retries with a jitter factor. That setup handles normal burst traffic without manual intervention. You should also monitor your bandwidth usage in the Supabase dashboard, because heavy storage operations show up there clearly and can alert you to unexpected spikes before they become billing surprises.
If you need something faster than raw REST calls for simple cases, stick with the SDK. It handles token refresh, retries, and multipart logic for you. The REST API is worth the extra effort when you need streaming downloads, custom retry behavior, server-to-server pipelines, or integration into languages where the official SDK is not ideal. For batch image processing, background job systems, and webhook-triggered transformations, direct REST access is usually the cleaner choice. One common pitfall worth stating plainly: do not mix bucket naming conventions. Supabase bucket names are case-sensitive and must be lowercase with hyphens. If you create a bucket called My-Bucket and then reference my-bucket in your API calls, you will get 404 errors that look like missing objects but are actually wrong references. I have seen this happen in CI/CD pipelines where the environment variable had a different case than the dashboard entry. For advanced users, the Copy and Move operations exist as separate endpoints and accept a destination path in the request body. They are atomic within a single bucket but do not cross buckets. If your workflow requires moving files between buckets, you download and re-upload, or you duplicate the object and delete the source. This is slower and uses extra bandwidth, so design around it when possible.
Testing your API calls locally is easiest with curl or a tool like Postman. Store your anon key and project URL in environment variables so you are not pasting them into every request. Verify a simple upload and download before writing any complex logic. If the basic flow fails, nothing downstream will work reliably. The Supabase Storage REST API is not mysterious once you treat it like any other authenticated HTTP service. The main things that matter are correct authentication, proper path formatting, awareness of size limits, and respecting the difference between public and private buckets. Build your error handling first. The rest is straightforward once those pieces are in place.