The Real Structure Behind Canada's Postal System
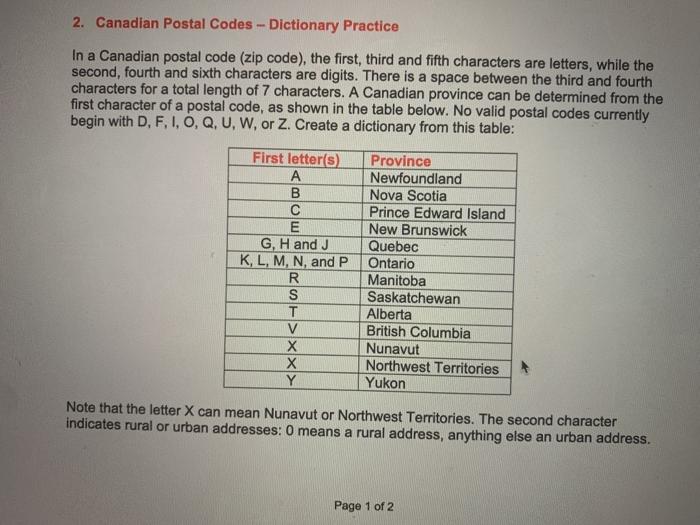
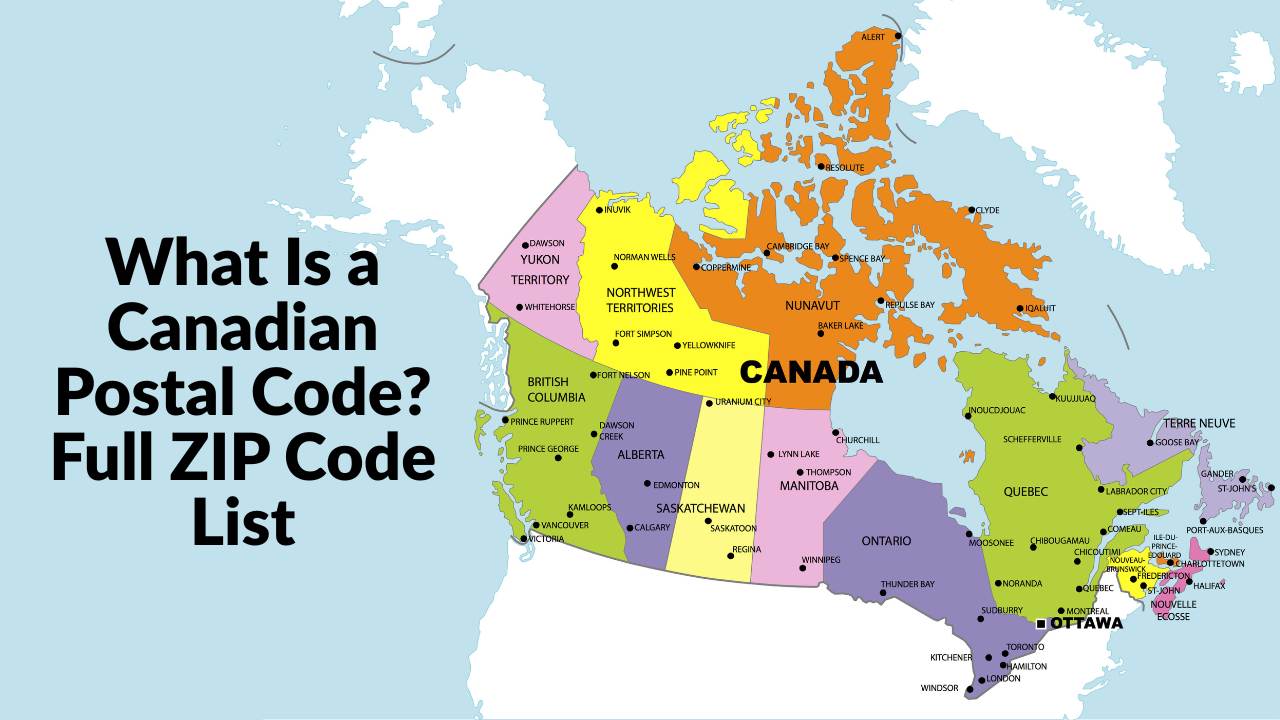
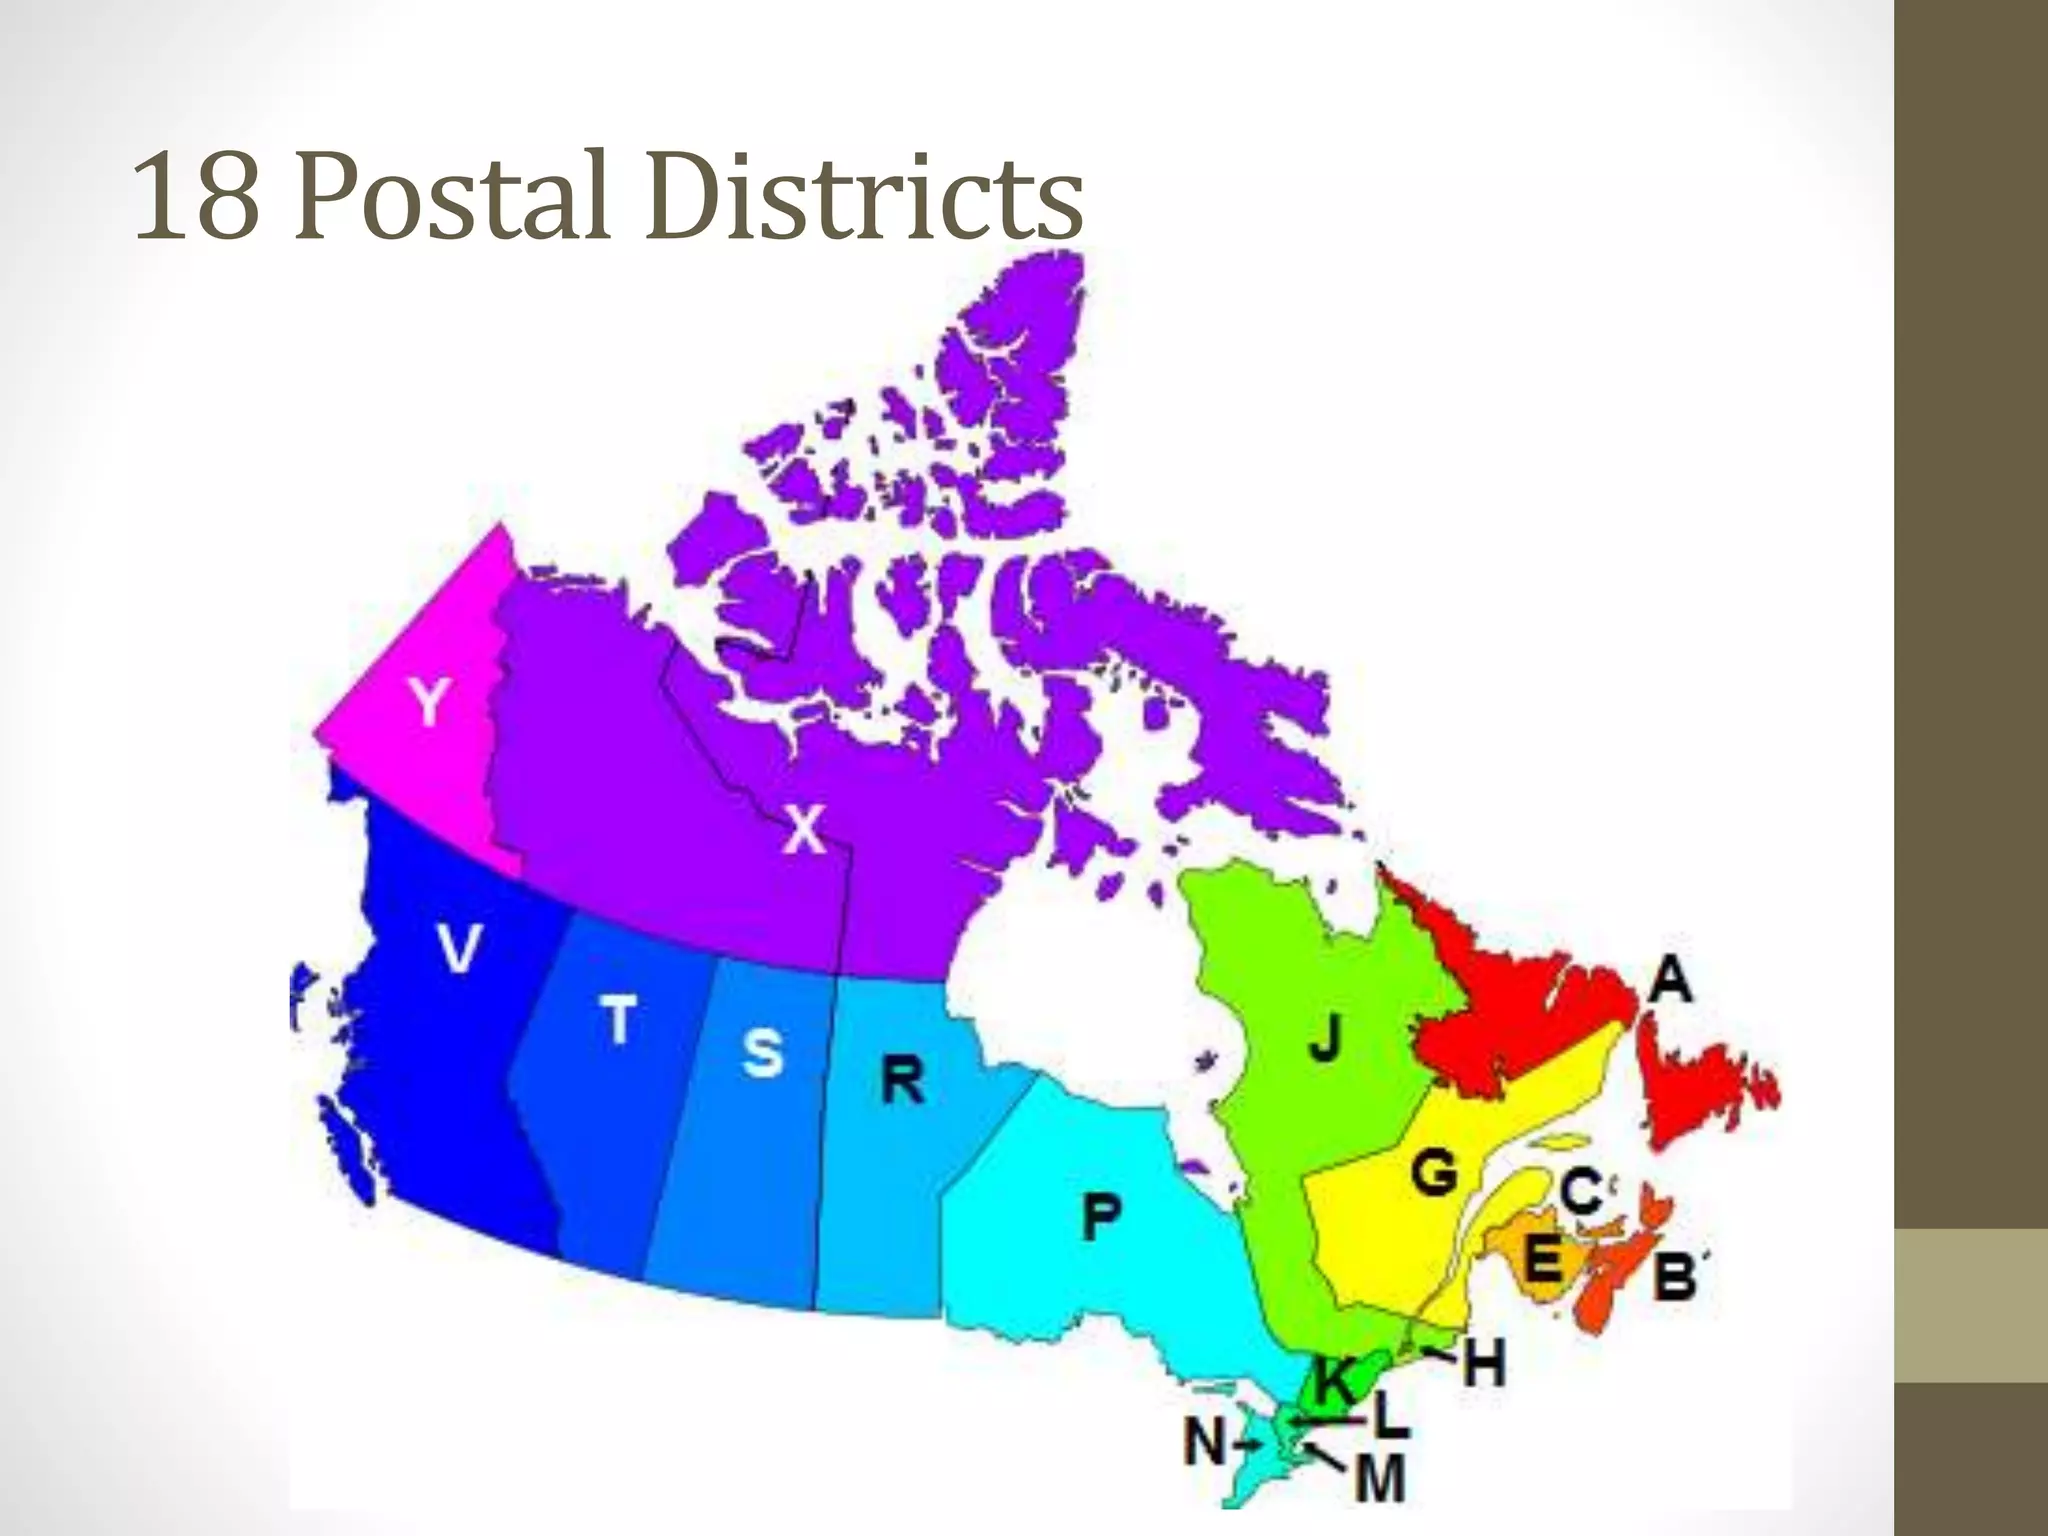
Canadian postal codes look like they follow a random pattern if you just stare at them. They're not random. Each one is built on a geographic logic that most people never notice until they need to sort mail, segment customers, or debug a shipping address. A standard format is a single space separating two parts: a forward sortation area on the left and a local delivery unit on the right. The first character is always a letter, as is the third character. The second position is always a number, and the fourth is a letter again. The final two are numbers. That fixed structure is what makes the system predictable enough for automation, and exactly why it trips people up when they try to use it without understanding the geography behind it. The first letter maps to a specific province or territory. K through S cover Ontario. A and B are Newfoundland and Labrador plus Nova Scotia. C is Cape Breton. E runs through New Brunswick. H is Montreal and surrounding areas. J through L cover Quebec. G is the rest of Quebec. M is Toronto. X covers the Northwest Territories and Yukon. Y is Yukon alone. V starts in British Columbia. R is Manitoba and Saskatchewan. T covers Alberta. A0A through A0B in remote areas are special cases that some systems choke on because they look like typos but are perfectly valid. The second character, the digit, splits that large region into smaller sectors. Some letters have a 0 in that position only for rural or high-volume downtown cores. Most urban areas distribute digits across the full range. The third character is where things get interesting. It usually represents a district within the city or a specific group of rural routes. After that, the last three characters define the actual delivery segment. That means two addresses on the same street might share the first three characters but diverge at the end. Conversely, two adjacent buildings could have different forward sortation areas if a highway or railway divides them.
I spent several years managing logistics databases where address validation was mandatory, and the first time I hit a block was with a client whose customer service team treated postal codes as optional fields. When we turned on strict validation, about eighteen percent of their submissions failed. Half of those were legitimate codes entered with a missing space or transposed letters. The other half were real codes that pointed to PO Boxes or military addresses outside the standard geographic mapping. Parsing postal codes alone does not solve delivery routing. You need a lookup table that accounts for the difference between a street address and a post office box route.
How Forward Sortation Areas Shape Delivery Zones
A forward sortation area is not a city. It is a mail processing zone. People assume K1A is all of Ottawa or that M5B covers downtown Toronto. Neither is true. K1A is the Parliament Hill area and a narrow slice of central Ottawa. K2P runs through another part of the city. M5B is the Entertainment District and a few blocks around it. The same letter prefix can contain dozens of non-overlapping FSA clusters scattered across a metropolitan area, and then there are rural FSAs that span hundreds of square kilometres but serve very few addresses. This matters because anyone building a geocoding pipeline or running market segmentation by postal code needs to accept that the geographic granularity is uneven. An FSA in suburban Mississauga might cover roughly two thousand residences. An FSA in northern Nunavut might cover fewer than fifty but an area larger than some Canadian provinces. If you aggregate data at the FSA level, you get useful patterns in dense urban corridors and almost nothing in the north. That is a feature of the system, not a bug, but it breaks assumptions if you expect uniform coverage. The original design intention was simple. The Canada Post sorting network reads the first three characters to route mail to the correct facility, then uses the last three for local delivery walking sequences. The system was engineered before digital maps existed, which is why it feels more like a postal routing scheme than a modern geographic information system. It works well for mail. It works less well for spatial analysis unless you layer it with actual boundary data from official sources.
Get the Full Details
Common Mistakes That Break Address Validation
The most frequent error I see is treating the space in a postal code as optional. It is not optional for parsing. Code that strips spaces before validation will misread H3C 1N4 as H3C1N4, pass the regex check, and then fail when the system tries to split it into FSA and LDA components. Always validate the format first, preserve the space, and only normalize after you have confirmed the structure. Another common mistake is accepting lower case without converting it. The system allows both, but downstream APIs often expect upper case. Normalize to upper case immediately after validation so your pipeline stays consistent. A third issue is assuming every valid postal code points to a deliverable street address. Many codes, especially those ending in 0, are assigned to high-volume receivers, government buildings, or specialized routes. When you use postal codes for demographic profiling or credit scoring, those outliers can skew your results because they represent a single point of delivery rather than a residential population. Filtering by the last three characters or checking against a database of known PO Box routes removes most of that noise. I once worked on a project where a vendor's validation library rejected K0A codes entirely. The library had a hardcoded exception list that only allowed certain rural prefixes. K0A is a legitimate FSA in eastern Ontario and southwestern Quebec. The rejection rate looked like a data quality problem until I traced it to the library's invalid whitelist. We switched to a validator that accepted the full alphanumeric range and then applied business rules separately. That cut our false rejection rate from about four percent to near zero in a single change.
Tools and Lookup Methods That Actually Work
If you need reliable postal code data, the Canada Post Commercial Customer Information API is the official source. It provides lookup, validation, and geographic conversion for a fee based on request volume. It is accurate, regularly updated, and covers the full range including the special Alaska and military routes that confuse domestic-only tools. Alternatives include open datasets from StatCan that map postal codes to census tracts, which are free but lag behind real-time changes. For small projects, a maintained CSV dump of all active codes paired with a local regex validator is often faster than calling an external service. When I built an internal address verifier, I started with the StatCan boundary file, added a regex that enforces the A1A 1A1 pattern, and then cross-referenced every submitted code against a cached copy of the official list downloaded weekly. The regex catches format errors instantly. The list catches fabricated codes that look valid but never exist. The StatCan file gives you geographic context for any code that passes both checks. That three-layer approach is more work upfront than a single API call, but it eliminates the surprise failures that happen when a provider updates its data without warning.
What Postal Codes Can and Cannot Tell You
Postal codes are excellent for mail routing and rough regional segmentation. They are poor proxies for neighbourhood identity, school districts, or municipal boundaries. A single postal code can span multiple wards, cross city limits, or sit entirely within an annexed area that changed jurisdiction decades ago. People often treat the first three characters as a city label. That assumption breaks immediately in cities like Toronto, Vancouver, and Montreal where a single FSA can cover a few blocks and multiple adjacent FSAs share the same urban name. The system also cannot handle informal addressing. Rural routes without street numbers, seasonal properties, and unincorporated communities sometimes use postal codes that do not align with any municipal map. If your application requires municipality data, do not derive it from the postal code alone. Use a separate lookup or accept that some addresses will remain unclassified until you add civic address records to the mix. This limitation is not a flaw in the postal system. It is a consequence of conflating mailing infrastructure with administrative geography. The practical takeaway is straightforward. Validate the format first, preserve the space, normalize to upper case, check against an official list, and only then decide whether you need geographic enrichment. If you skip any of those steps, your pipeline will produce results that look correct until they fail in production. The Canada Post APIs, StatCan files, and careful regex validation are not optional extras. They are the minimum foundation for any system that relies on postal codes beyond surface-level formatting.