Understanding Spark-Based Data Integration And Its Real Workflow
Spark has become the default engine for most data engineering pipelines since 2018. The ecosystem around it has grown into something broader than just batch processing, and the way people now approach data discovery, transformation, and integration within a Spark cluster looks very different from what the early documentation showed. I spent years building these pipelines and watched the tooling mature, so I can tell you what actually works and what people waste time on. DDI in the Spark context generally refers to a combination of data discovery, data ingestion, and data integration workflows that run inside or alongside a Spark cluster. Rather than treating these as separate phases, the modern approach threads them together. You scan raw input, infer schemas, apply transformations, and push clean data into serving layers — all within the same execution environment. That eliminates the traditional handoff between teams and the resulting data drift. I worked on a project where we were ingesting roughly 40 terabytes of mixed-format logs daily. The original pipeline used separate tools for discovery and transformation, which created a three-day lag between when data arrived and when analysts could actually query it. We rebuilt the workflow to run discovery and transformation in the same Spark jobs, and the lag dropped to under four hours. Not because Spark is magical, but because removing the intermediate export and reimport steps saved the majority of the compute time.
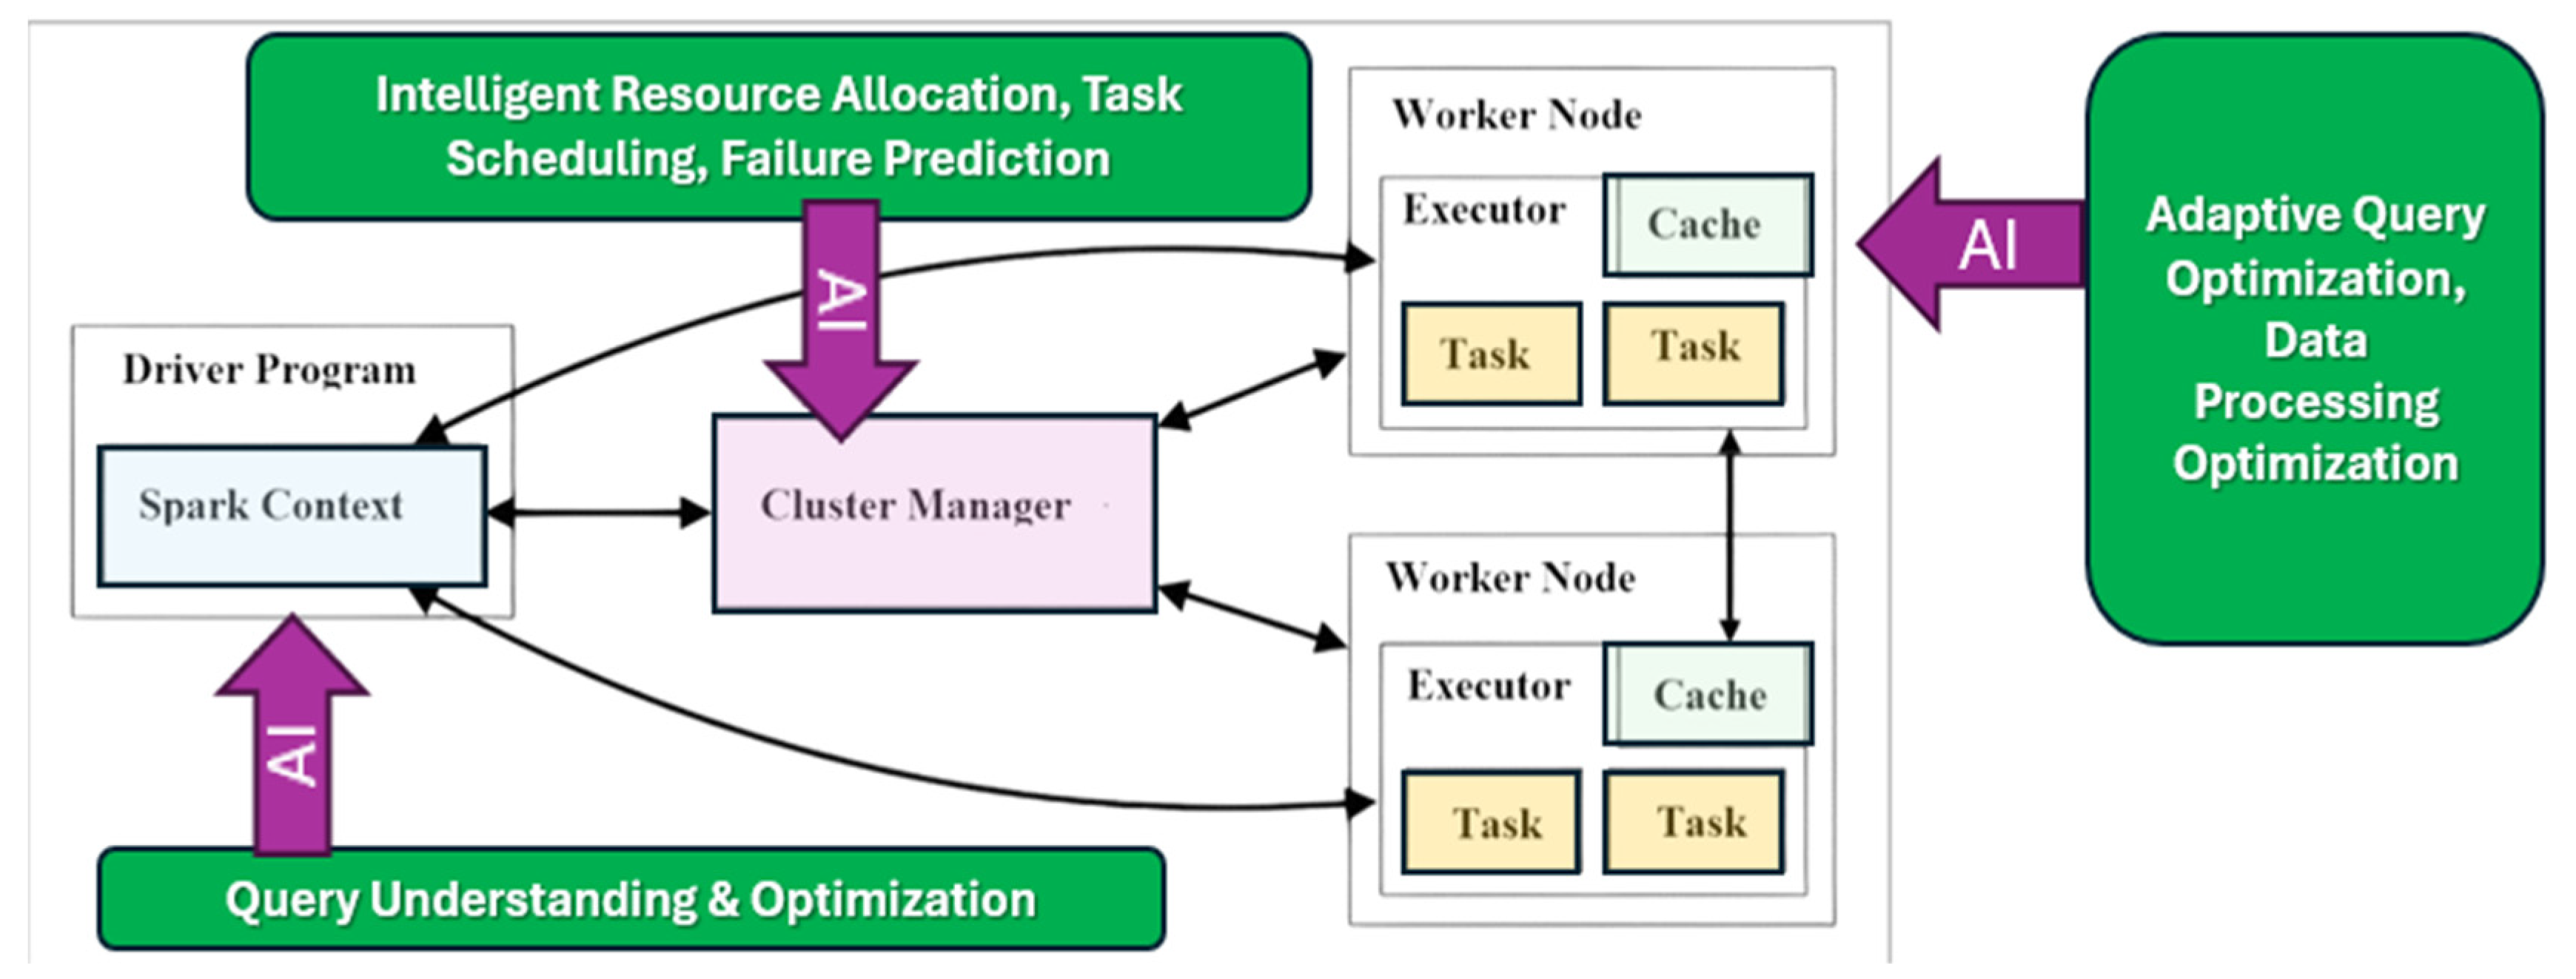
The technical mechanism is straightforward. You read source data through Spark's native connectors — JDBC, Parquet, Avro, Delta Lake, Kafka — and use schema inference or a managed data catalog to understand structure. From there, you apply column mappings, type conversions, and business logic using Spark SQL or DataFrame APIs. The output lands in a sink format optimized for your downstream consumer. That's the core loop. Everything else is optimization. One detail that trips people up constantly is partitioning strategy. Most tutorials show wide partitions for simplicity, but in practice, narrow and well-sized partitions matter far more for join performance and shuffle behavior. When I was tuning a pipeline that joined multiple large tables, switching from roughly 200MB partitions to around 128MB cut the join stage from about 45 minutes down to 12. The difference came from reduced skew and more efficient task scheduling across the cluster.
What Actually Happens During A Spark DDI Pipeline
Let me walk through a realistic scenario. You have transaction data coming from a relational database, event streams from Kafka, and some flat files sitting in object storage. A conventional approach would move each into a data lake separately, then merge later. A more efficient approach treats them as sources within a unified Spark job. You configure Spark to read from all sources in parallel using its streaming and batch capabilities together. Structured Streaming handles the Kafka portion while batch reads cover the database and files. Schema evolution becomes important here because one source changes its schema before the others. If your pipeline assumes a fixed schema, it will break. I encountered this when a partner changed a timestamp column from UTC to local time without notification, and the pipeline failed silently for two days because Spark's default behavior tolerates nulls rather than failing fast. The fix was setting the schema validation mode to fail in both the DataFrame reader and the streaming write, combined with a monitoring alert on schema change events. Data quality checks should run inside the same pipeline, not after it. I've seen teams build separate validation jobs that run downstream, but that creates a second round of data movement and additional cost. Running checks during ingestion lets you flag bad records immediately and route them to a dead letter path within the same Spark application. A simple count of nulls in critical columns, range validation on numeric fields, and uniqueness checks on keys can catch most issues before they propagate.
Get the Full Details

Common Pitfalls And Where People Waste Resources
Over-relying on the default configuration is the most frequent mistake. Spark's defaults are designed for general-purpose use, not for production throughput. Things like shuffle partitions, memory allocation, and serialization settings need adjustment for your specific workload. The default shuffle partition count of 200 is almost never appropriate for large-scale joins or aggregations. I usually set it based on total data volume divided by a target partition size, then verify with the Spark UI that no single task is handling more than a few hundred megabytes. Another issue is materializing intermediate results too eagerly. When you chain multiple transformations and call a count or write midway, Spark executes the entire preceding graph. This can duplicate work if you later need the same intermediate data for a different transformation. Using cached DataFrames selectively and understanding the execution plan through explain queries helps avoid redundant computation. I once caught a pipeline that was recomputing a large join four times across different stages. Adding a single checkpoint and caching the result reduced the job duration from two hours to about thirty-five minutes. Persistent storage format choice also matters more than most people realize. Parquet is standard, but Delta Lake or Apache Iceberg adds transactional guarantees that prevent the corrupted file problem you get when multiple writers target the same directory. If your pipeline involves concurrent writers or needs time-travel queries for debugging, the overhead is worth it. I switched a few of our pipelines to Delta and the reduction in troubleshooting time alone justified the change within a month.
Integration With Data Science And AI Workloads
One area where Spark DDI genuinely adds value is closing the gap between data engineering and model serving. When your integration pipeline outputs data in a format that ML frameworks can consume directly, you remove a significant translation layer. Spark's MLlib provides basic modeling capabilities, but the more common pattern is feeding cleaned, integrated data into feature stores or model training pipelines running on separate infrastructure. The key is maintaining lineage and metadata through the entire process. When a model's predictions start deviating, you need to trace back to the exact data version and transformation logic that produced it. Spark's built-in logging combined with a metadata registry makes this feasible. I found that simply recording the job configuration, input paths, and schema at each pipeline run saved hours of investigation during production incidents. Real-time inference is another area where the integration matters. If your DDI pipeline outputs to a format like Delta Lake with change data capture enabled, you can feed those changes directly into an online feature store. This keeps features consistent between training and serving, which is where most model performance degradation originates. I saw a recommendation model lose about 15% of its accuracy after a deployment because the serving features were computed differently than the training features. Fixing the pipeline to use the same transformation logic eliminated that gap entirely.
Practical Steps To Build A Working Pipeline
Start with a small subset of your actual production data. Development on synthetic data creates a false sense of reliability. I learned this when a pipeline that performed perfectly on test data produced incorrect aggregations in production due to a timezone handling edge case that only appeared with real timestamp distributions. Use the full schema and a representative sample of volume from day one. Write your transformations as reusable functions rather than inline code. This makes testing possible and reduces the chance of logic drifting between pipeline versions. A simple unit test on your transformation function with known input and expected output catches regressions faster than waiting for a pipeline failure in production. Monitor your Spark UI during development. The web interface shows you task durations, shuffle read and write sizes, and stage bottlenecks. I identify most performance problems by looking at the UI first rather than guessing from logs. A stage that takes disproportionately long usually indicates a data skew issue or an unnecessary broadcast of a large dataset.

Set up alerts on pipeline failures and data quality metric thresholds. A failed pipeline is easy to miss if you are not checking actively. I configured alerts that trigger on job failure, schema change detection, and data volume anomalies that deviate more than two standard deviations from the recent mean. This caught several issues within minutes instead of hours.
When Spark Is Not The Right Choice
Spark excels at batch and micro-batch processing of large datasets. It is not optimal for low-latency single-record operations or when your data volume stays below a few hundred gigabytes per day. In those cases, the overhead of spinning up a Spark cluster outweighs the benefits. A simpler streaming framework or even a well-tuned relational database may be more appropriate. Similarly, if your primary need is real-time event processing with sub-second latency requirements, Spark Structured Streaming introduces enough overhead that alternatives like Kafka Streams or Flink may serve you better. Spark's strength is throughput, not latency. I once evaluated Spark for a use case that needed 100-millisecond response times and switched to a different architecture after benchmarking showed a ten-to-one performance difference. Cost management deserves mention. Spark clusters, especially on cloud platforms, can accumulate significant expense if left running idle or misconfigured. I learned to use auto-scaling with careful lower and upper bounds, spot instances where possible, and always shut down clusters when not actively processing. A cluster left running overnight on a misconfigured project cost over eight thousand dollars in a single month before I caught it.
Final Observations
The reality of working with Spark for data integration and discovery is less about mastering complex APIs and more about understanding how data moves through your system and where bottlenecks accumulate. Most pipelines fail not because of technical complexity but because of inadequate monitoring, poor partitioning, and insufficient attention to data quality at ingestion time. The tools are mature enough that the remaining challenges are operational rather than conceptual. Focus on building observability into your pipelines from the start, test with real data as early as possible, and resist the urge to optimize prematurely. The fundamentals, done well, cover most production requirements.