The Actual Structure Behind PDF Layers
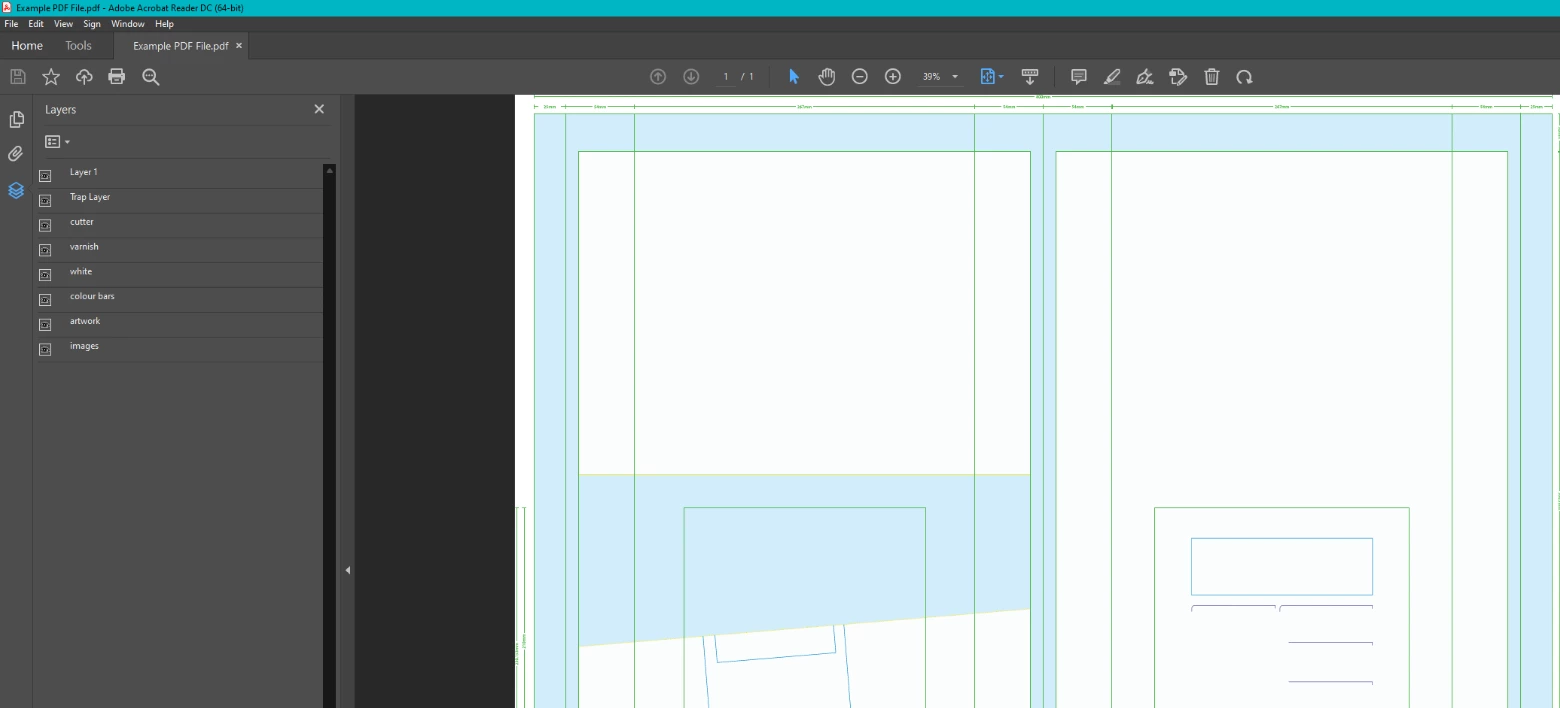
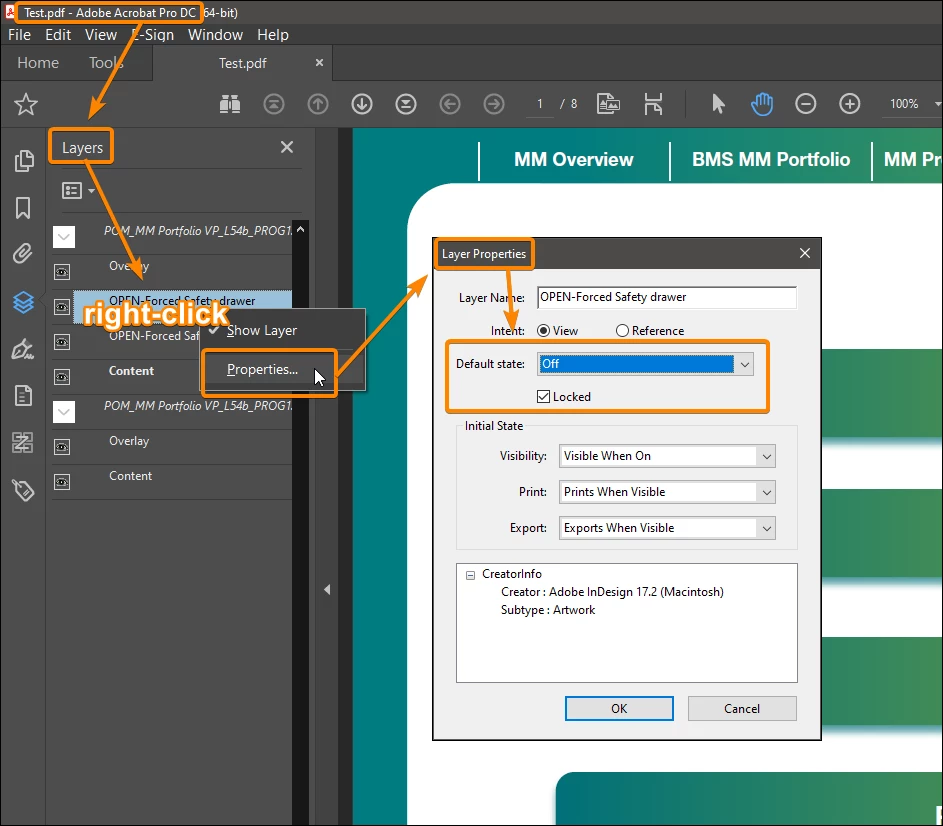
PDF layers aren't a proprietary trick. They're called optional content groups, or OCGs, and they've been part of the PDF specification since version 1.5. When a document has layers, the PDF contains a dictionary of OCG objects in its resource list. Each OCG defines a group of page content that can be shown or hidden independently of everything else. Multiple OCGs can be combined into an OptionalContentConfiguration dictionary, which is what Acrobat actually reads when you click checkboxes in the Layers panel. Here's what most people miss: a single layer in the UI doesn't always correspond to one OCG object in the file. Acrobat groups them visually based on a hierarchy, but the underlying structure can have parent OCGs that don't have content of their own. They exist purely to organize child OCGs. Flattening such a document without understanding that hierarchy means you'll either leave orphan content or accidentally merge unrelated groups together.
Unlocking The Layers Of PDF Inside Out And Back Again
The phrase gets thrown around a lot in forums, usually referring to the act of opening a layered PDF, toggling visibility, and saving it back. The technical version of that is manipulating the OCG configuration. Here's how it actually works when you're doing it yourself instead of clicking through a GUI. Open the PDF in a tool that exposes the structure. Adobe Acrobat Pro will show you the Layers panel, which is the easy path. For anything programmatic, PyMuPDF, iText 7, or PDFBox are your options. PyMuPDF (the Python wrapper around the MuPDF engine) is the fastest for reading and inspecting layer structures. It will tell you how many OCGs exist, whether they're nested, and their current visibility state in seconds. PDFBox is slower but more capable for structural modifications. iText is fine if you're already in that ecosystem, but be aware of its licensing changes in recent versions. When you read a layered PDF with PyMuPDF, the layers dictionary is accessible through the document object. A basic inspection loop looks like this: iterate over the doc's layer properties, check each group's state, and write that to a config file. The state is either ON, OFF, or NEVER, where NEVER means the layer was never visible in any saved configuration. That NEVER state is important because it tells you something was intentionally hidden at creation time, not just unchecked by the user.
To modify and save back, you construct a new OptionalContentConfiguration dictionary. This means building an array of OCG references paired with their desired states, wrapping that in a config object, and setting it as the document's /OCProperties entry. Acrobat will honor this on next open. PDFBox's PDOptionalContentProperties class handles most of the construction for you. With iText, you're working closer to the raw PDF syntax, which gives more control but requires more manual dictionary management. I worked on a project last year where the source PDF had roughly 40 optional content groups distributed across three levels of nesting. The requirement was to extract only the top two layers, flatten them into a single visible page, and preserve the rest as hidden but intact. The straightforward approach failed because one of the child OCGs under a parent group was referenced from two different pages. Acrobat's export-to-flatten function duplicated that content on both pages instead of preserving the single reference. I ended up writing a script that traced each OCG reference across all pages, built a deduplicated mapping, and reconstructed the page content streams with explicit layer assignments before flattening. It took about six hours to get right. The core issue was that flattening isn't a simple visibility toggle. It's a content stream modification that has to respect how each page references its OCGs individually. Here's another thing that isn't obvious. Layer visibility in a PDF is persistent per-document, not per-viewer session. If you open a layered PDF, hide layer 3, and close it without saving, the next person who opens that same file will see layer 3. The visibility state you set in Acrobat's UI is only temporary unless you explicitly save the document. Many people complain about layers "not staying hidden" because they assume the viewer remembers their preferences. It doesn't. You have to write the configuration back to the file.
Get the Full Details
The Hidden Complexity in "Simple" Layer Documents
Not every PDF that looks like it has layers actually uses optional content groups. Some documents achieve the same visual effect by using transparency groups, clipping paths, or simply stacking content on top of each other with opacity settings. These aren't layers in the PDF spec sense. Acrobat won't show them in the Layers panel, but a user could reasonably describe the document as having "layers" in a visual sense. The workaround for extracting content from these is completely different. You'd be working with the page content stream directly, parsing drawing operators, and filtering by transparency group membership rather than OCG state. That's significantly more work and requires a proper PDF parser, not a utility that just reads the layer metadata. Then there's the issue of form fields and layers interacting in unexpected ways. An AcroForm field can be placed inside an OCG, meaning its visibility is controlled by the layer state. But when you flatten a document, form fields become static content. If you flatten while a layer containing form fields is hidden, those fields disappear entirely. If it's visible, they get flattened into the page content and become uneditable. There's no middle ground. I ran into this with a permit application PDF where the signature block was on a separate OCG. The user wanted to hide the signature layer and flatten the rest. The result was a document where the signature field was gone, not just hidden. The workaround was to flatten first, then reposition the signature field content as static text using a low-level content stream edit. That's roughly a two-hour process per document and not something you want to automate without careful testing. Another edge case that costs people hours: linked OCGs. A single OCG can be referenced from multiple pages. When you change its state, it changes everywhere. This is by design, but it causes problems when you want different pages to show different layer configurations. The solution is to create page-specific OCG configurations instead of relying on the document-level default. You assign a custom OptionalContentConfiguration to each page's resources dictionary. This is supported by the spec but not well-documented in any of the official Adobe guides. PyMuPDF makes this relatively straightforward. You clone the document's default OCG config, modify the cloned config, and attach it to the individual page. The tradeoff is file size increase, because each page now carries its own config dictionary.
Common Pitfalls When Removing or Extracting Layers
The biggest mistake people make is assuming that hiding all layers and saving produces a blank page. It doesn't. A PDF with all optional content groups turned off will still render. The content that isn't covered by any OCG—the default content stream—remains visible. Layer groups only control the content inside them. If the base page content was never assigned to an OCG, it shows through regardless of what you do with the layers. I spent an afternoon debugging a document where the user expected complete removal of content by hiding all layers. The underlying text and images were outside the OCG structure entirely. They were just regular page content that the author forgot to assign to a group. There's no clean way to recover that except editing the page content stream directly, which is tedious and error-prone. XFA forms are a separate headache. PDFs built with XML Forms Architecture (XFA) handle their own internal layer-like structures that are completely independent of OCGs. Attempting to manipulate OCGs on an XFA form PDF usually has no visible effect because the rendering pipeline prioritizes the XFA content model. The only reliable approach is to convert the XFA form to a standard PDF first, preferably using Adobe's own conversion tools, and then work with the OCGs on the converted output. Third-party converters sometimes strip layer information during XFA-to-PDF conversion, so you lose what you're trying to manage. Vector-based PDFs from CAD programs are notorious for having extremely deep OCG nesting. I once opened a Revit export that had 127 nested optional content groups. The parent OCGs had no content of their own. The actual geometry was at the leaf level. Flatten tool in Acrobat would freeze for several minutes on a document of that complexity. The workaround was to export the layer list to JSON, filter out the groups I didn't need, and apply the filter through a script that rebuilt the OCG tree at a reasonable depth before flattening. Processing time dropped from unmeasurable to under three minutes on a standard machine.
When This Approach Doesn't Work
Layer manipulation in PDFs has hard limits. If a PDF is scanned image-based with no text or vector content, optional content groups may still exist, but they'd contain image fragments rather than meaningful semantic content. Hiding or showing them won't help you extract readable text. You'd need OCR on the visible fragments, which is a completely separate workflow. Encrypted PDFs present another blocker. If the document has owner password protection that restricts content extraction, you cannot read or modify the OCG structure regardless of what tool you use. The encryption covers the entire PDF object graph, including the /OCProperties dictionary. You'd need the owner password to unlock the document before any layer work is possible. This isn't a limitation of the layer tooling. It's a fundamental restriction of the PDF security model. Some PDF producers create layers using deprecated or non-standard approaches. Older versions of certain plotting software generated layer-like behavior through custom dictionaries that Acrobat doesn't recognize as OCGs. These documents will appear to have layers in some viewers but not in others. There's no reliable way to normalize them because the structure isn't standardized. The best you can do is identify the producer's naming convention and map it manually, which is effectively reverse engineering the file structure.

Practical Steps That Actually Save Time
If you're doing this repeatedly, the inspection phase is where you should invest effort. Export the full layer tree with nesting information and OCG states to a JSON file before making any changes. A single command with PyMuPDF takes about 15 seconds on most documents and gives you a complete picture of what you're working with. Without that, you're guessing, which leads to wasted iterations. When flattening, always work on a copy. The flattening process modifies content streams irreversibly. If your OCG mapping is wrong, you'll have lost the original structure and there's no undo. I keep a backup of the unmodified file alongside every working copy. The extra disk space is negligible compared to the time spent recovering from a bad flatten. For batch operations across many files, avoid GUI-based tools. Acrobat's batch processing is functional but slow and resource-heavy. A Python script using PyMuPDF or PDFBox can process 50 layered PDFs in the time it takes to manually handle five. The initial script development takes a few hours, but the return is immediate and scales linearly with document count.
File size impact is worth monitoring. Flattening a heavily layered PDF can either reduce or increase the final size depending on how the content streams are merged. If many layers share common resources like fonts and images, flattening consolidates them and may shrink the file. If each layer has unique content with overlapping resource declarations, the merge can produce redundant data and inflate the output. I've seen a 40MB layered PDF become 28MB after flattening and another 40MB file grow to 61MB. Both were valid outcomes. There's no way to predict which direction it will go without testing.