How We Actually Deployed Document Processing at Scale
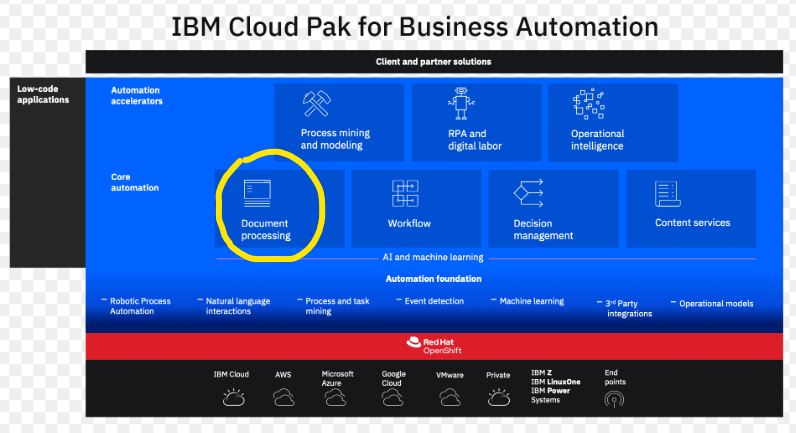
I spent about six months configuring IBM Recognition Center for a client who was drowning in paper invoices and vendor forms. Their old process involved three people sitting at a scanner, pulling documents, and manually entering data into an SAP backend. It took roughly four hours per batch of 500 documents. After we got Recognition Center working, that same batch ran in about 20 minutes with about 87 percent accuracy on the first pass. The rest got routed to a human queue for review. That's not a magic number — it depended heavily on how messy their source documents were. Recognition Center is IBM's enterprise-grade optical character recognition and form recognition platform. It sits in the document processing pipeline and handles the heavy lifting of reading structured and semi-structured documents. It works alongside other IBM tools like Datacap and FileNet, but it can also operate independently depending on your infrastructure. The core idea is straightforward: you train it on templates, it learns to find fields and extract text, and then it processes new documents against those templates at scale. The thing most people get wrong when they start is the template setup. You don't just point it at a PDF and expect it to figure out where the invoice number lives. You define capture zones, field types, validation rules, and confidence thresholds. I remember working with a set of European procurement forms that had checkboxes, handwritten initials, and tabular line items all mixed together. The default template engine would confidently read the checkbox locations but completely miss the handwritten portion because the training set only had typed examples. The workaround was to run a separate handwriting-specific model on those particular regions and then merge the results post-capture. Not ideal, but functional. That's one of those details you only learn after burning two weeks on it.
Unlocking Enterprise Efficiency How Ibm Recognition Center Revolutionizes Document Processing
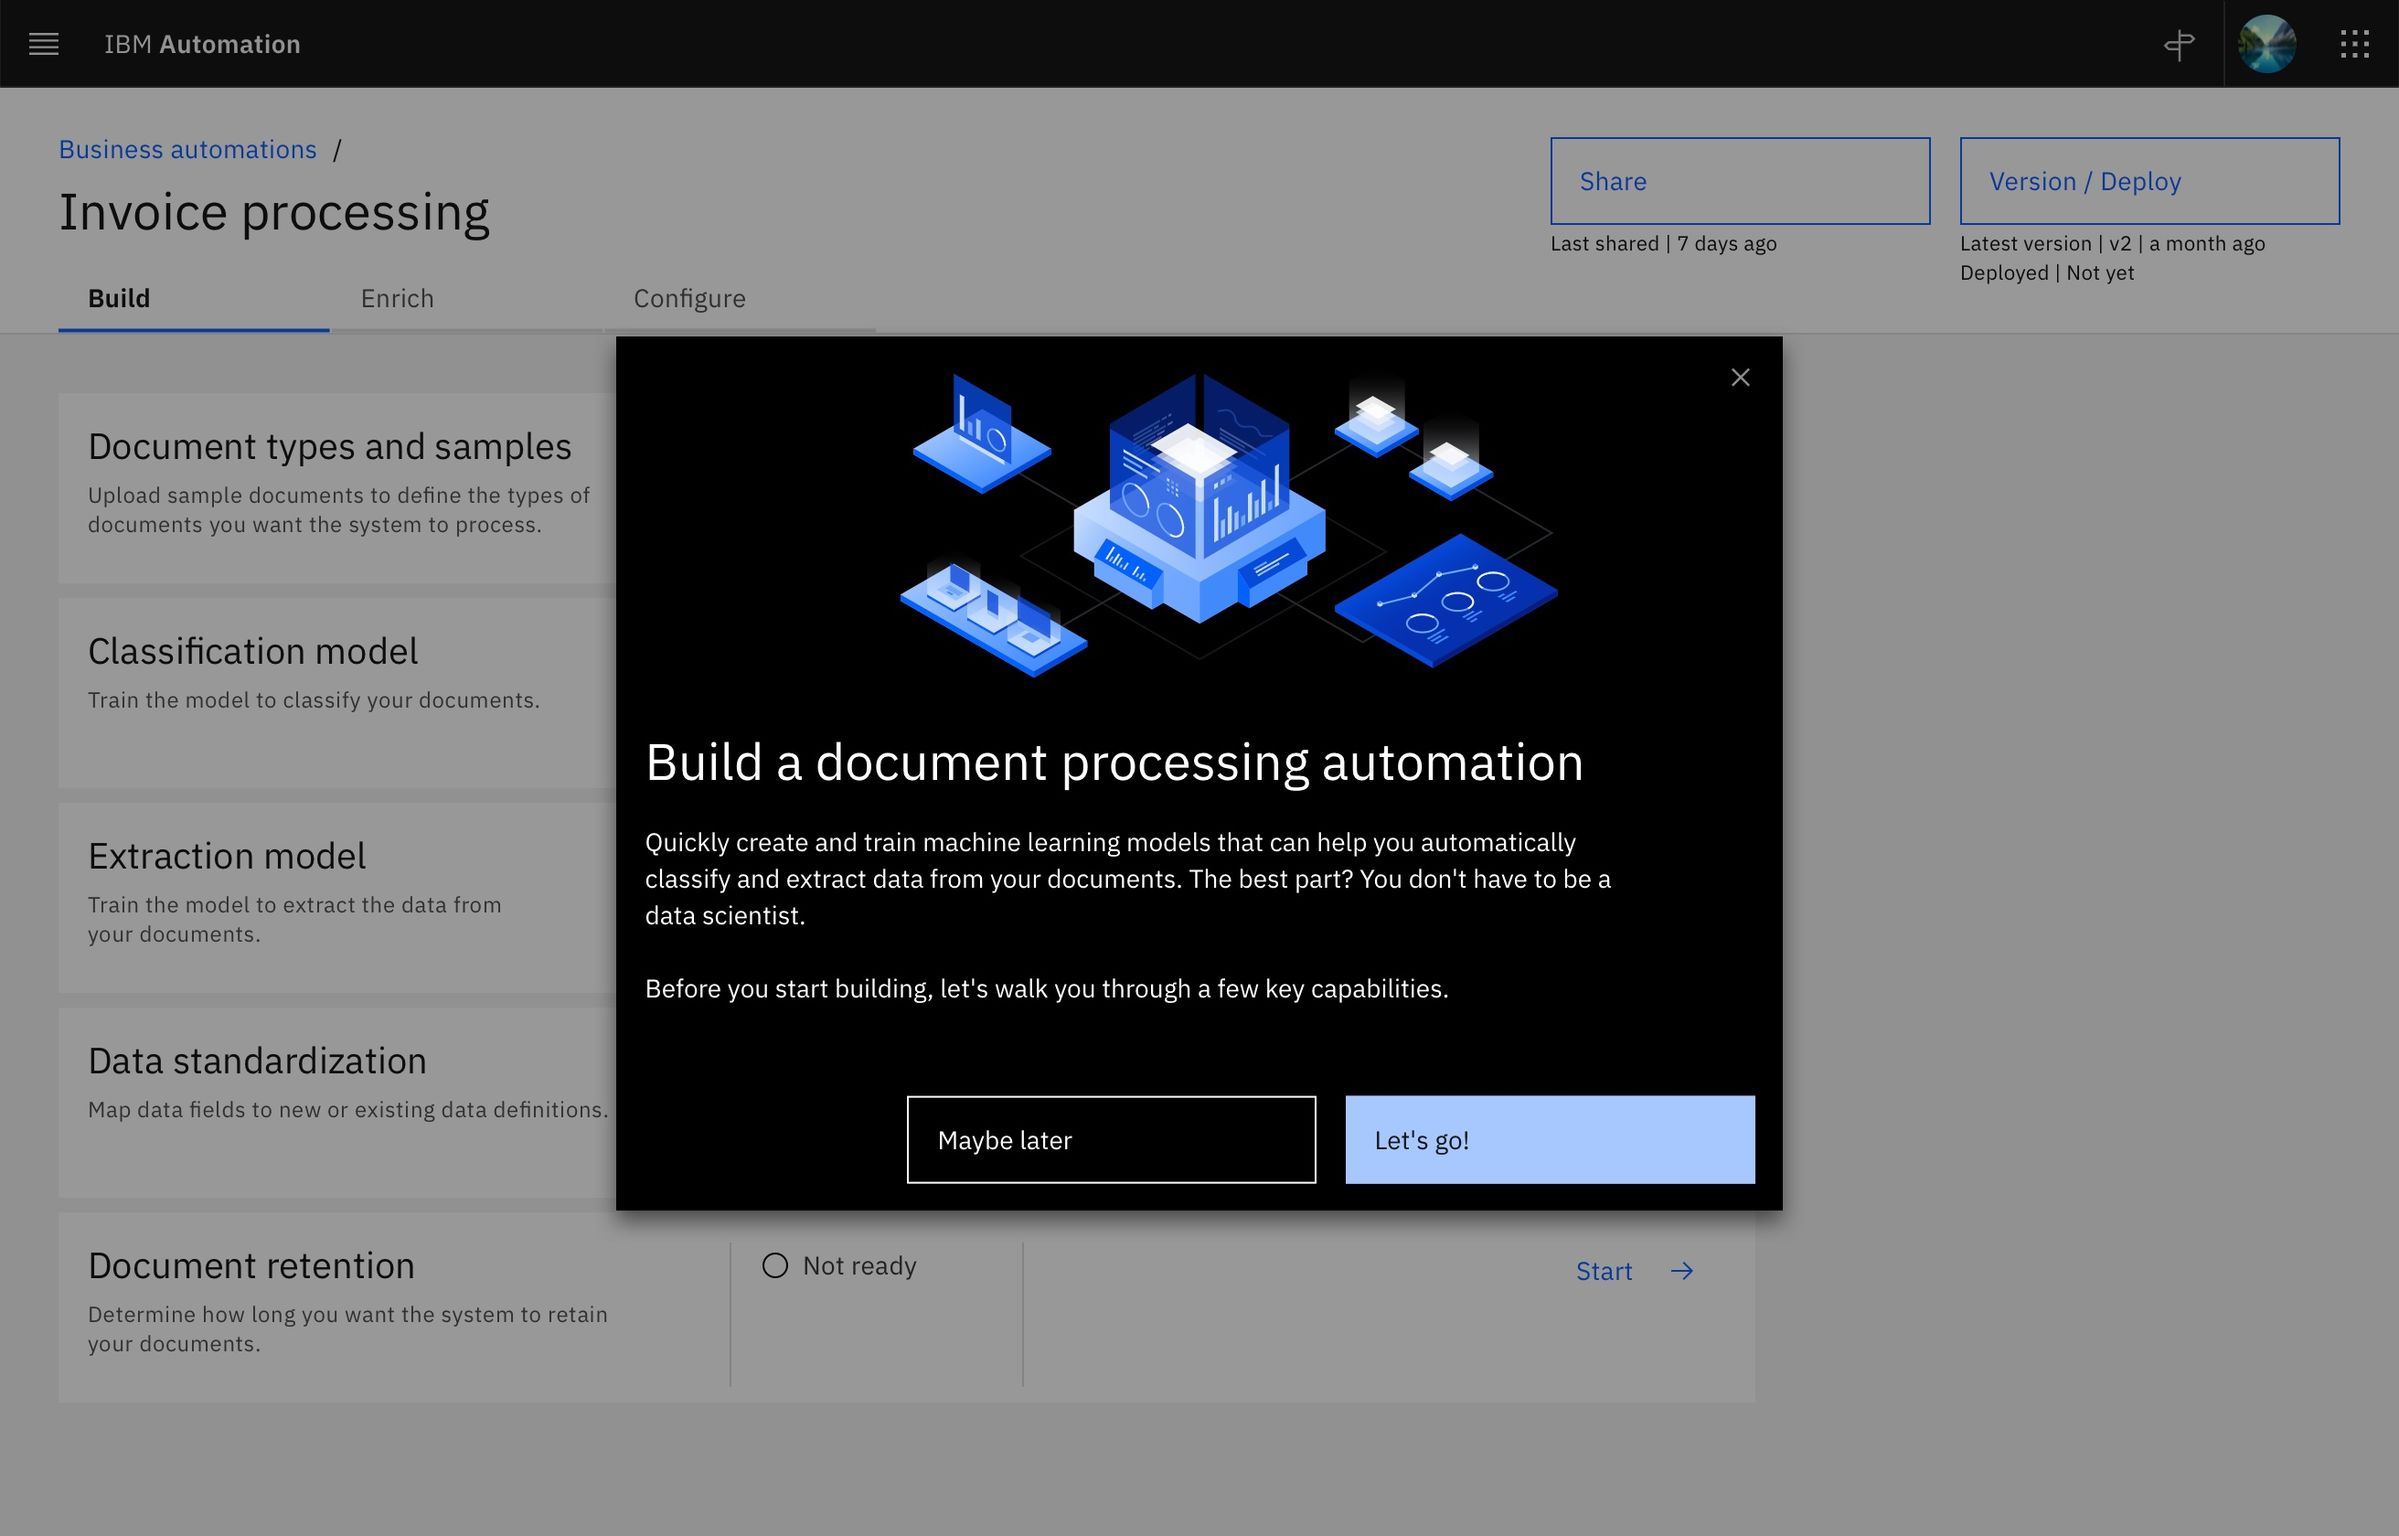
Getting Recognition Center up and running involves a few concrete steps. First, you install it on your chosen infrastructure — it supports containerized deployments on Kubernetes, which is standard now. Then you connect it to your document sources, whether that's email attachments, scanned images, or a file drop folder. After that comes the template creation phase, which is where most projects stall out. You'll need a representative sample of your actual documents. Not cleaned-up test PDFs. Real ones. The ones with coffee stains, misaligned scans, varying fonts, and partial page cuts. I once saw a team build templates using perfectly scanned demo documents and then watch the production accuracy crater to 34 percent because their live documents came through a lower-quality multi-function printer. Always validate against your worst case, not your best case. The configuration itself happens through the Recognition Center interface, where you create templates, define fields, set up validation patterns, and configure routing rules. Validation patterns are particularly important. Without them, the system will happily extract text from the wrong location and call it accurate. Setting regex patterns for invoice numbers, dates, and total amounts forces the system to reject garbage extractions before they reach your downstream systems.
After templates are built, you run a pilot batch. This is non-negotiable. Run at least 200 real documents through and compare the extraction results against ground truth. Measure confidence scores, track which fields consistently fail, and adjust your templates accordingly. I typically see three to five template iterations before accuracy stabilizes above 85 percent for a given document type. One nuance that isn't widely discussed is how Recognition Center handles table recognition. Standard field extraction works well for labeled forms, but line-item tables — things like purchase order line items or shipping manifests — require a different approach. You need to configure table zones separately and specify row and column structures. The system can recognize repeated patterns across rows, but if your tables vary significantly in structure, you'll get partial matches or dropped rows. In one project, we had purchase orders where some vendors listed quantities in separate columns and others merged them with descriptions. We solved it by creating two complementary table templates and letting the confidence scores determine which one to apply. Integration with downstream systems is usually done through APIs or via IBM's connector framework. Most enterprises feed the extracted data into ERP systems, document management platforms, or custom databases. Make sure your integration layer handles failures gracefully. Documents that fall below confidence thresholds should route to a manual review queue, not silently enter your system with incorrect data. I've seen two companies do this wrong and lose days debugging why their financial reports contained phantom line items.
Get the Full Details
There are real limitations to keep in mind. Recognition Center is expensive to set up and maintain. The licensing model is based on document volume and complexity, so a high-volume operation can see significant costs. Template creation requires skilled personnel — it's not something you hand off to a junior developer and walk away from. And the handwriting recognition, while improving, still struggles with poor quality or non-standard scripts. If your document pipeline is dominated by handwritten forms or heavily degraded scans, you may need supplementary tools or a different approach entirely. Another practical consideration is ongoing maintenance. Templates drift. Document formats change. Vendors update their invoice layouts. New regulations introduce different required fields. You need a scheduled review process — quarterly at minimum — to validate that your templates are still performing as expected. I set up automated confidence score dashboards for my clients so we could spot degradation before it became a business problem. A sudden drop in average confidence is usually a signal that a document format has changed somewhere in the supply chain. If you're evaluating whether Recognition Center is the right fit, it really depends on your volume and complexity. For small operations processing under a thousand documents per month, lighterweight OCR solutions or even managed services might be more cost-effective. Recognition Center shines when you're handling thousands of documents daily across multiple types and channels, and you need enterprise-grade accuracy, audit trails, and integration capabilities. The initial investment is substantial, but the automation gains become clear fairly quickly once everything is tuned.
The deployment timeline typically runs three to six months depending on document variety and infrastructure readiness. Start with your highest-volume document type, prove the workflow end-to-end, and then expand to additional types. Trying to boil the ocean upfront is the fastest way to derail the project. Get one process working reliably, then replicate the pattern. That's how we ended up processing over twelve thousand documents a day across seventeen template types without major incidents.