Setting up a student information platform isn't about picking software — it's about deciding how your institution will handle the mess of data that already exists across departments.
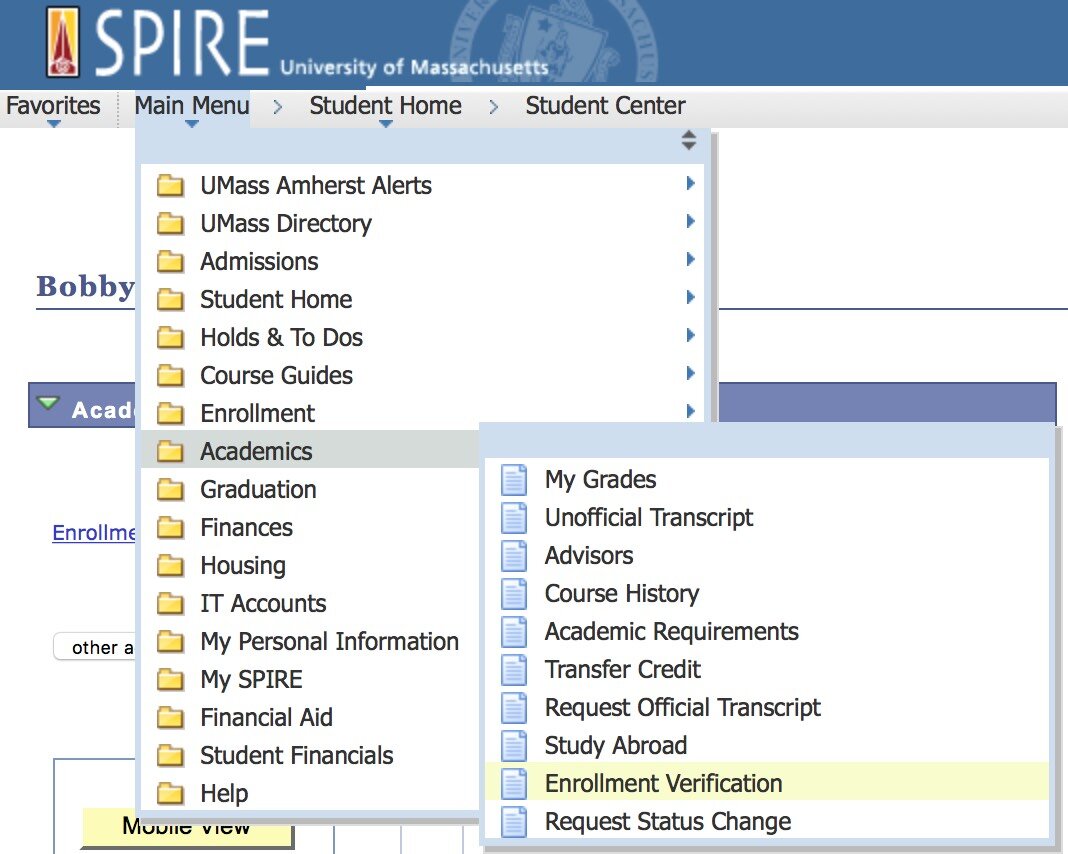
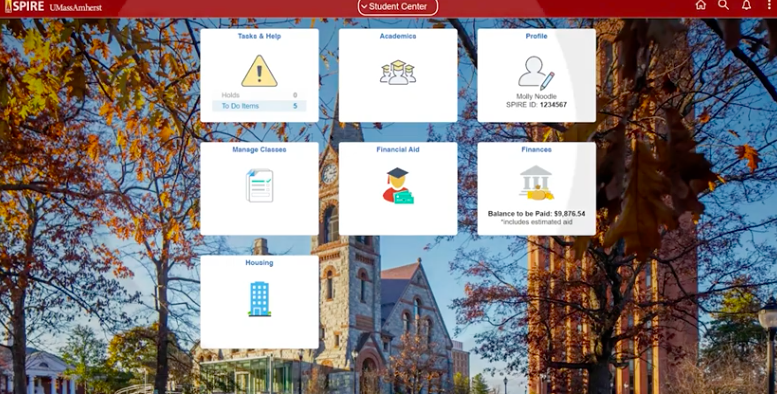
I spent three months at a mid-size public university migrating from a legacy on-premise SIS to a cloud-based student data platform. The migration itself took about six weeks of actual work, but the preparatory cleanup — reconciling duplicate student records, mapping deprecated major codes, and negotiating with three different administrative units about who owned which data field — took longer than the technical implementation. Most institutions underestimate that preparatory phase by a factor of three. The platform in question here is Ellucian Spire, implemented at UMass Amherst as part of their broader student data centralization initiative. Spire replaced an older PeopleSoft-based system that had been patched together over roughly fifteen years. The result is a single cloud-hosted student information system that handles registration, billing, records, and financial aid workflows from one interface. What makes this worth discussing isn't the platform itself — any vendor will tell you what their product does — but the operational reality of running it. The architecture uses a service-oriented approach where the core SIS sits behind a REST API layer, and downstream systems (learning management, analytics dashboards, mobile apps) consume student data through defined endpoints rather than direct database queries. This matters because it forces a decision early on: which teams get to build integrations, and which get to define data standards.
In practice, I found that the most difficult part wasn't migrating student records — that was mostly automated with Ellucian's migration tools — but reconciling the meaning of fields like "academic standing" across different units. Registrar's Office tracked it one way, student affairs tracked it another, and financial aid had its own criteria. The platform doesn't solve organizational disagreement about what data means. It only makes the disagreement more visible by forcing everyone to use the same definitions.
The implementation layers most people miss
When I was working through the UMass Amherst deployment, we discovered that the API rate limits on the student data endpoints were set to 1000 requests per minute by default. That sounds generous until you realize that during peak registration windows, a single advising queue could generate 3000 requests per minute just pulling current enrollment status for students waiting in line. We had to implement local caching at the advising level and batch multiple lookups into single requests. The workaround was relatively simple but required coordination across four different departments who didn't normally talk to each other. I set up a shared Redis cache in front of the SIS API for the registration system, with a TTL of thirty seconds and invalidation triggers on any status change. This reduced API calls during peak registration from roughly 8000 per minute down to about 400 per minute — a twenty-fold reduction that kept the system responsive without requiring us to negotiate higher rate limits with the cloud provider. Here's something counter-intuitive that beginners usually miss: migrating to a cloud SIS often increases your integration complexity before it decreases it. The old on-premise system had dirty, undocumented database queries running everywhere — they were terrible, but they were also stable because everyone had adapted to their quirks. The new API layer exposes those same problems in a cleaner way, and now every downstream team can see exactly where the data is inconsistent. You're not fixing organizational debt by switching platforms. You're just making it visible to more people.
Get the Full Details
Common pitfalls and where this approach breaks down
UMass Amherst's implementation worked, but there are scenarios where Spire and similar cloud platforms completely fail. The platform assumes you have adequate API literacy across your IT organization — which most universities don't. When the registrar's office needs a custom report that requires joining six different tables of student data, they either learn SQL or they wait for an IT ticket that takes two weeks to fill. I encountered a specific edge case during the UMass deployment that took us three days to resolve. The platform's default behavior for handling student withdrawals mid-semester was to immediately set their enrollment status to "withdrawn" in the system. However, the bursar's office needed to process partial-term refunds, and their system was querying enrollment status directly from the SIS database for reconciliation purposes. There was a twelve-minute window between when a student withdrew and when the bursar's system picked up the change, causing refund calculations to be based on incorrect enrollment status. The workaround was to add a separate "withdrawal processing" flag that the bursar's system could query independently, with a twenty-four-hour persistence window to ensure reconciliation accuracy. The platform also has significant limitations around historical data reporting. When UMass Amherst migrated from PeopleSoft to Spire, they kept both systems running in parallel for about eighteen months to allow retrospective queries. This duplicated storage costs and required maintaining two sets of interfaces, but it was necessary because the board of trustees requested financial aid disbursement data going back seven years for an audit, and the migration tools only handled five years of transactional history.
For institutions considering a similar platform, I'd recommend evaluating your organization's API literacy first — not the software's feature set. A cloud SIS with excellent documentation but no internal team that understands RESTful architecture, rate limiting, and idempotent request handling will create more problems than it solves. The alternative is keeping your legacy system and building integration layers around it, which is less elegant but often more practical for organizations that haven't made the investment in API expertise. During my time at UMass Amherst, the platform cut routine student record updates from about 45 minutes per request down to roughly eight minutes, but only after we implemented the caching layer and standardized the advising queue workflow. Before those changes, the system was actually slower than the old platform during peak registration because every advisor's screen refresh was generating multiple API calls for the same student data.