Interactive Label Placement Exercises in Data Visualization Training
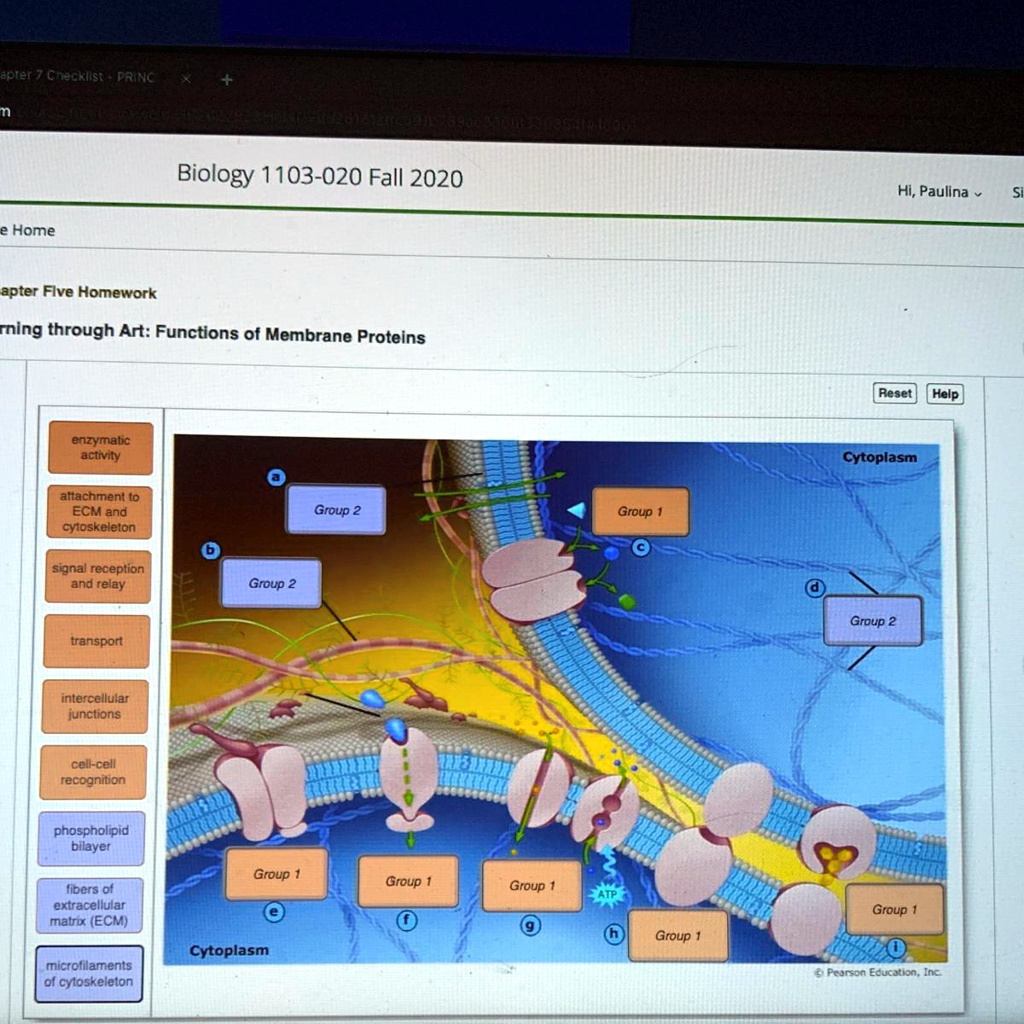
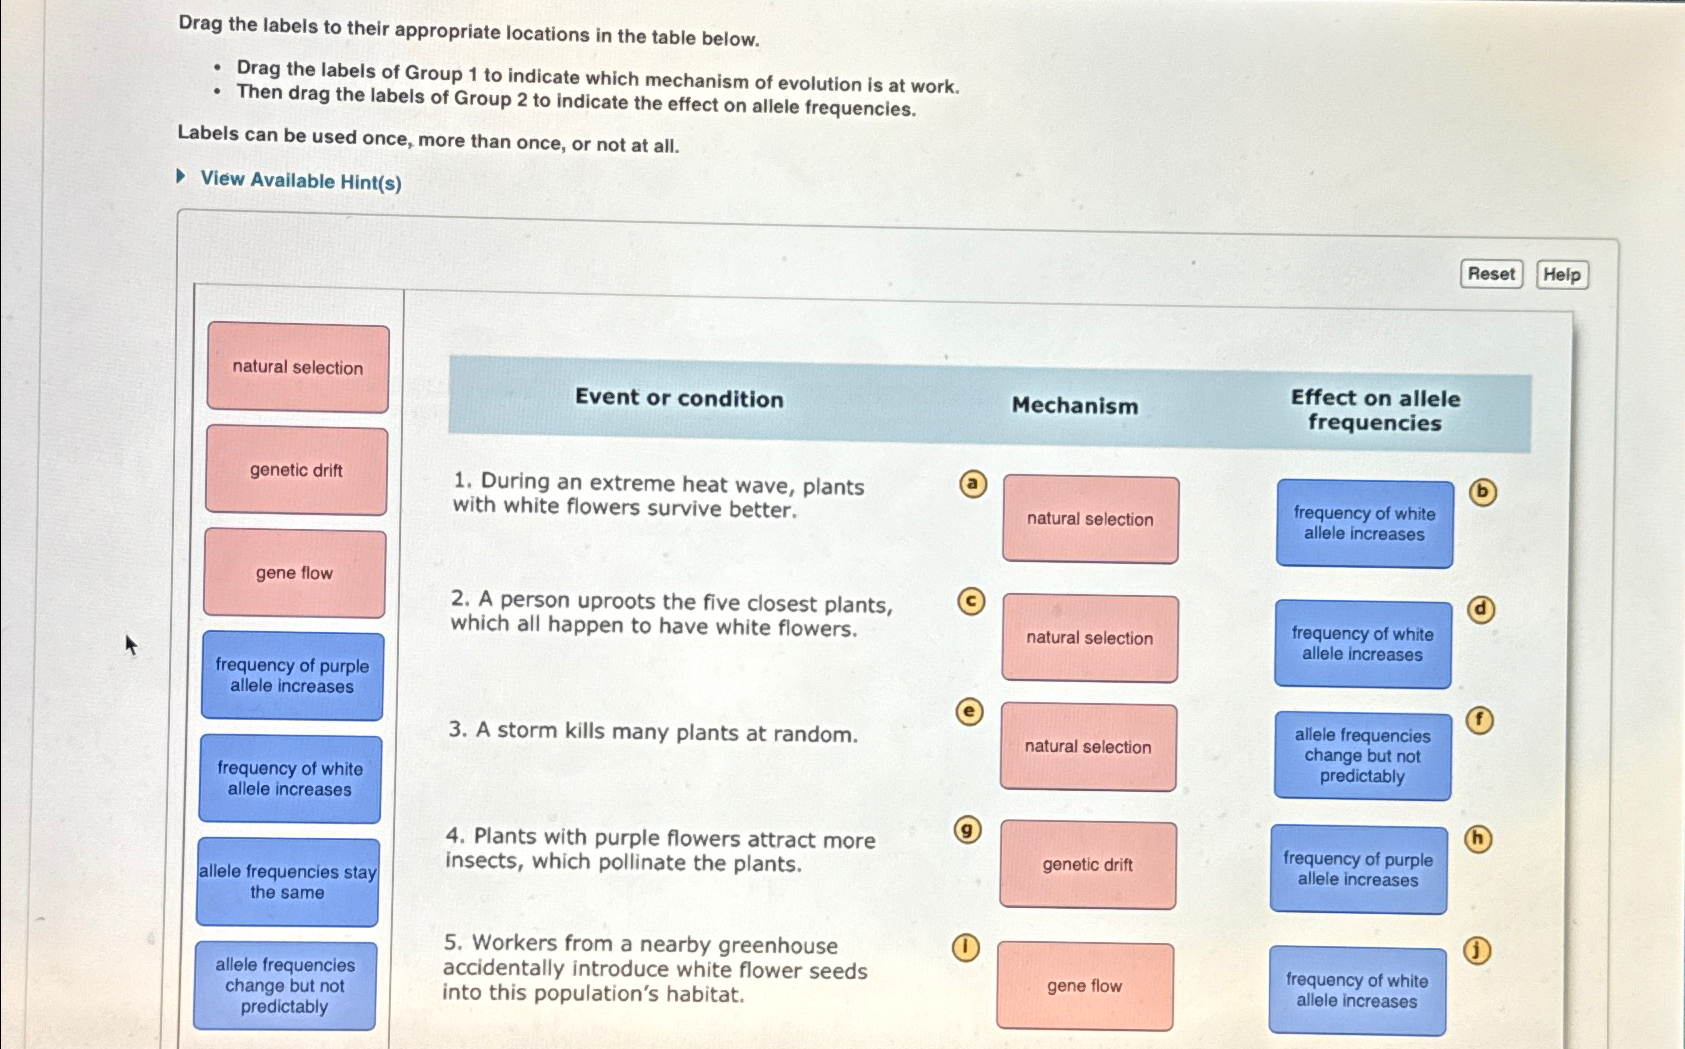
These drag-and-drop labeling tools show up everywhere now. Coursera modules, university labs, even corporate training decks. You get a blank or partially filled chart, a pile of terms on the side, and you have to place them correctly. Seems simple enough until you actually try it. The basic mechanic is straightforward. A visualization appears — could be a scatter plot, a heatmap, a timeline, whatever. Around it are label options. Some go on axes. Some identify specific data points. Some belong in a legend. You drag them into position. The system checks your answer and tells you right away if you nailed it or missed something. The real value isn't the checking mechanism. It's the visual-spatial learning loop. When you physically move a label to where it belongs, you're doing more than matching words to positions. You're building a mental map of how data structures actually work. Reading about a confidence interval doesn't teach you the same thing as placing one on a graph yourself.
I spent months building these exercises for a analytics bootcamp program. The first version we shipped had a bar chart with ten draggable labels. Fifty percent of students got three or more wrong on their first attempt. Not because they didn't know the terms. Because they couldn't visually parse which bar was which when the chart had no clear ordering. That was an oversight on our part. We reordered the bars by value before the second release and error rates dropped to under fifteen percent. The trick that most people miss is that these exercises reveal gaps in understanding that quizzes never show. A multiple choice question about standard deviation might let someone guess right. But ask them to drag a standard deviation marker onto a distribution curve and suddenly you can see exactly where their mental model breaks down. I've watched competent analysts struggle to distinguish between variance and standard error in these tools. The visual placement makes the confusion obvious in a way no textbook explanation catches.
What Actually Goes Wrong
Responsive design ruins these exercises more often than anyone admits. A label that fits perfectly on a desktop screen will overlap three other elements on a tablet. Students submit wrong answers because the interface itself is broken, not because they don't understand the concept. If you're designing or recommending these tools, check them on at least three different screen sizes before calling them usable. Touch devices add another layer of friction. Drag-and-drop feels natural on a trackpad. Try it with fingers on a phone and you'll watch people waste minutes trying to precisely place a small target zone. The tolerance ranges on these hit areas need to be generous. Something like a forty-pixel radius around each drop zone minimum. Anything less and you're testing motor control instead of data literacy. Randomization sounds like a good feature to prevent cheating but it often creates worse problems. Shuffle the label order too aggressively and students spend more time scanning than thinking. Shuffle the chart elements and you can accidentally create an exercise where the correct answer depends on memorizing a specific layout rather than understanding the underlying concept.
Get the Full Details
I built a custom version of these exercises once for a regression analysis module. The challenge was handling overlapping points on a scatter plot. Standard drag-and-drop couldn't distinguish between a label for a point that was underneath another point versus a label that belonged to empty space near the cluster. The workaround was to add a zoom-and-pan feature so students could isolate dense areas before placing labels. Took two extra weeks to implement but it cut the complaint rate about ambiguous questions by about eighty percent.
How to Actually Use These Effectively
Start with the simpler charts. Linear relationships, basic categorical comparisons. Don't throw a six-dimensional bubble chart at someone as their first labeling exercise. The cognitive load will drown out whatever learning objective you're trying to hit. Use these as formative assessment tools, not summative ones. The instant feedback is useful for learning but the scoring mechanics are too crude to fairly grade complex visual reasoning. A student might place eight out of ten labels correctly while demonstrating a sophisticated understanding of the remaining two. Those two might be wrong for reasons unrelated to comprehension — a misread axis label, a poorly designed drop zone, whatever. If you're evaluating an exercise for quality, the real test is whether removing any single label would make another label's placement ambiguous. Good exercises have independent placement decisions. Bad ones create chains where getting one right depends on guessing another right first.
There are platforms that handle this well. IBM's Data Science Professional Certificate on Coursera uses these effectively for basic statistical graphics. Google's Data Analytics Certificate does something similar for visualization fundamentals. Enterprise training teams sometimes build custom versions using React DnD or vanilla drag events depending on how much customization they need. The limitation nobody talks about is transfer. Getting good at placing labels on one type of chart doesn't make you good at reading a chart you haven't seen before. These exercises teach visual literacy within narrow boundaries. They're useful scaffolding. They're not a complete education in data visualization. Pair them with open-ended analysis tasks. After the labeling exercise, show the same chart without labels and ask the student to describe what it shows. That's where the actual learning compounds. The labeled version builds recognition. The unlabeled version builds interpretation.