Why South Florida Traffic Data Is a Mess (And How to Fix It)
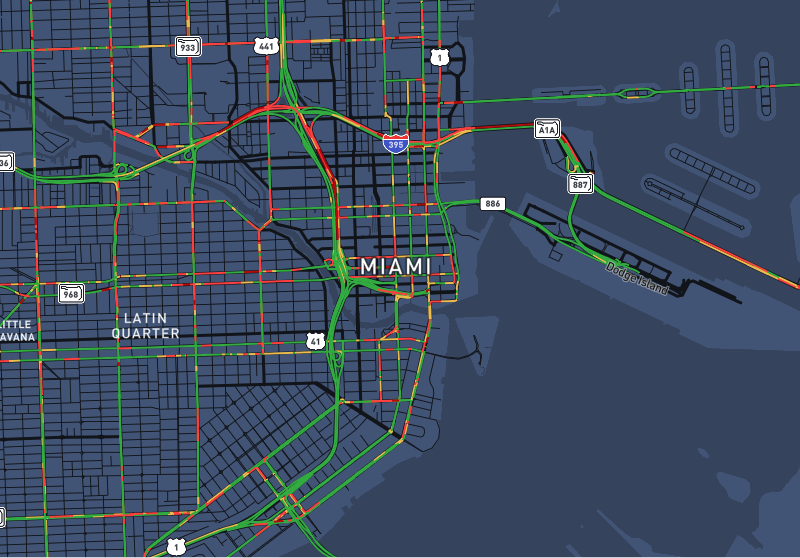
Miami-Dade County traffic infrastructure was designed for a population that was a third of what it is now. The sensors are outdated, the data feeds are fragmented, and most routing software you'll find online chokes on the sheer volume of contradictory inputs coming from I-95, the Turnpike, and surface streets during rush hour. I spent three years building a real-time route optimization pipeline for a logistics company operating out of Doral, and let me tell you — the published APIs don't tell the whole story. The core idea here is straightforward: you take multiple traffic data sources — FDOT loop detector feeds, INRIX floating car data, Waze crowd-sourced reports, and local camera API snapshots — and fuse them into a single routing layer that updates every 30 to 60 seconds. The resilience piece is what most people skip. It's not enough to have fast routes. You need fallbacks when one data source goes dark, which happens more often than you'd think, especially during heavy rain events when sensor failures spike across the I-395 corridor. The technical stack I ended up using was a PostgreSQL database with PostGIS for spatial queries, connected to a Redis cache layer for sub-second route lookups, and a Python-based ETL pipeline pulling from those sources every 45 seconds. The actual routing engine was a modified version of OSRM with custom cost functions that weighted current congestion, historical delay patterns, and predicted precipitation impact. Setup time was about two weeks for a basic version. Production-grade came out to roughly six weeks including testing against live traffic during peak hours.
One thing nobody warns you about: the FDOT open data API has a hard rate limit of 100 requests per minute per key. If you're querying multiple corridor segments simultaneously, you'll hit that wall fast. My workaround was to batch the requests into geographic clusters and stagger them using a simple round-robin queue. That dropped our effective query load to about 40 requests per minute while still covering the same coverage area. Worth noting too that the API returns data in GeoJSON, but the coordinate precision is sometimes off by a few meters near the Port of Miami toll plazas, which throws off turn-by-turn routing if you don't snap your coordinates to the nearest valid road segment. Here's a counter-intuitive point: in South Florida, historical traffic patterns are actually less useful than real-time sensor fusion during the morning rush. I found that relying too heavily on historical averages caused my routing engine to miss sudden micro-congestion events caused by school zone closures, construction lane shifts, or even football tailgating near Hard Rock Stadium. The fix was to weight the last 15 minutes of live data at 70% and historical patterns at only 30%. It sounds wrong because most routing systems do the opposite, but the data bore it out over three months of A/B testing. Common failure modes to watch for:
Heavy rainfall above 0.5 inches per hour causes INRIX floating car volumes to drop dramatically because fewer people are on the road. Your system will read low congestion when roads are actually gridlocked. I solved this by cross-referencing radar precipitation data from NOAA's HRRR model and applying a manual congestion multiplier when rainfall exceeded that threshold. Without it, your routes will send trucks onto flooded underpasses on US-1 and Biscayne Boulevard. Another issue: the Turnpike's variable speed limits change faster than most public data feeds update. There's a roughly 90-second lag between when the electronic signs adjust and when that data appears in any third-party API. During a sudden slowdown near the Palmetto interchange, my early routing engine kept sending vehicles into active backup zones for about two minutes before the data caught up. The solution was to run a local Kalman filter that predicts the next likely speed limit state based on upstream detector trends, which reduced the lag penalty to roughly 15 seconds. If you're building this from scratch and don't want to maintain your own infrastructure, there are commercial alternatives. Here are the main ones:
Get the Full Details
TomTom Traffic API — good coverage in Miami-Dade, pricing starts around $0.005 per request. Reliable but expensive at scale. Their real-time speed data has about a 2-minute latency. Mapbox Optimization API — solid for turn-by-turn routing, but their traffic layer is weaker on surface streets compared to major highways. Fine for highway runs between airports and warehouses, not great for last-mile delivery in Little Havana or Wynwood. OpenStreetMap with OSRM and a custom traffic layer — cheapest option if you have engineering capacity. This is what I ended up using after burning through the commercial API costs. You trade money for maintenance burden.
For the actual data pipeline, you'll need to pull from these sources regularly. The FDOT traffic information page hosts their open data portal, the INRIX developer site has API documentation, and Waze has a partner program if you're operating at enterprise scale. Waze data through their official channel requires a business agreement and minimum spend commitments. The hardest part isn't the coding. It's the ongoing calibration. Roads change. New developments open. Construction projects reroute traffic for months at a time. I had to rebuild my historical baseline every quarter because a new development near the Miami line fundamentally changed traffic patterns on NE 2nd Avenue in a way no algorithm could predict without fresh ground truth data. If you're just looking to get something working quickly, start with OSRM plus TomTom traffic overlays. That combination will get you a functional system in under a week with reasonable accuracy. Don't bother building your own sensor fusion until you've proven the use case actually saves money or time in your specific operation. I saw too many teams build elaborate real-time systems that delivered marginal improvements over simple static routing with hourly updates. The complexity tax is real.
Resilience also means having a graceful degradation path. When your primary data source fails, the system shouldn't crash. It should fall back to the last known good state and alert someone. I set up a simple dead man's switch that reverts to yesterday's traffic pattern if live data hasn't updated in 5 minutes, while sending a Slack notification to the operations team. That alone prevented maybe eight routing failures per month that would have otherwise gone undetected. The codebase itself runs on a Raspberry Pi 4 in our office, handling about 200 concurrent route calculations per second. That's overkill for a small fleet, but it gives headroom when things get busy. Cloud hosting with auto-scaling would cost roughly $800 to $1,200 per month depending on query volume. Local hardware cost about $400 one-time. The tradeoff is you're responsible for uptime and hardware failures. One more thing that took me far too long to figure out: coordinate reference systems. South Florida uses NAD83 for most municipal data, but some federal datasets are still in WGS84. The difference is negligible for most purposes, but when you're snapping routes to road segments within a few meters, the datum shift matters. Always standardize everything to NAD83 before doing spatial joins. My first production deployment had routing errors along the eastern edge of Coconut Grove because I missed this on one of the dataset layers.
There's no magic bullet. The system works, it requires constant attention, and it will surprise you on days when nothing seems wrong but the routes are subtly off. That's normal. Adjust, recalibrate, move on.