Sorting ArrayLists in Java
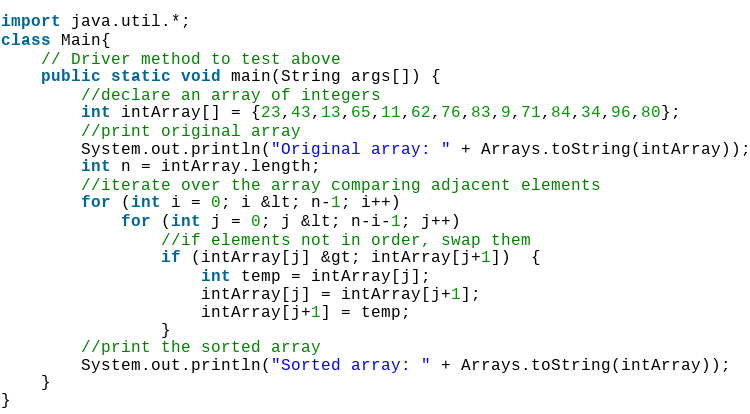
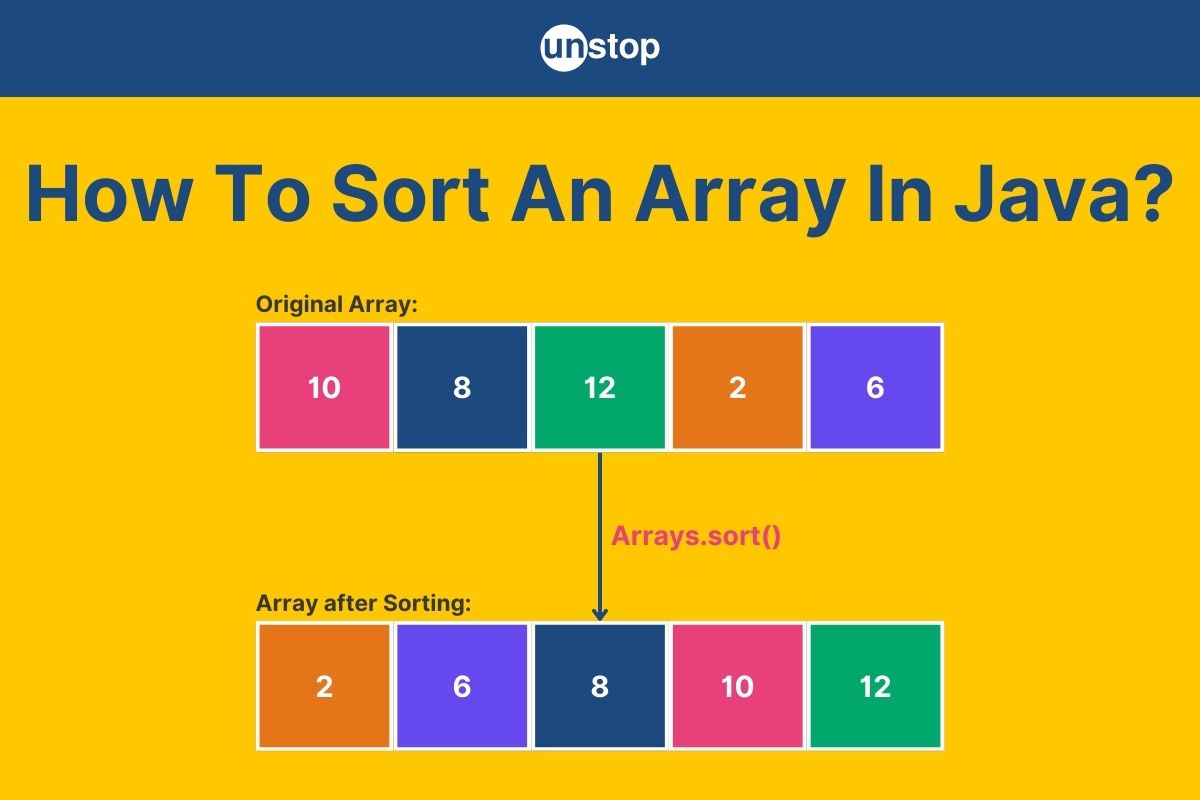
I used to write my own sort implementations for everything. Turns out, that's unnecessary unless you're dealing with something exotic. Java gives you four solid ways to sort an ArrayList, each with their own tradeoffs. Here's what they actually look like in practice. This is the default go-to for most developers and for good reason. It uses TimSort under the hood, which is a hybrid of merge sort and insertion sort. The time complexity sits at O(n log n), and it's stable, meaning equal elements keep their relative order. Here's the basic usage: List<Integer> numbers = new ArrayList<>(Arrays.asList(5, 2, 8, 1, 9, 3));
Collections.sort(numbers);
// numbers is now [1, 2, 3, 5, 8, 9]
You can pass a custom comparator if you need descending order or object field sorting: Collections.sort(numbers, Collections.reverseOrder());
Collections.sort(users, Comparator.comparing(User::getAge)); Here's the catch most people miss: Collections.sort() modifies the list in place. It doesn't return a new sorted list. If you accidentally pass it a read-only list, you get an UnsupportedOperationException. Also, for large lists with many duplicate elements, TimSort actually performs better than a standard quicksort because it detects and exploits existing runs in the data. That said, the overhead of boxing and unboxing primitives before they hit the sort can be significant if you're working with int arrays instead of Integer objects. Use primitive arrays with Arrays.sort() directly if performance is critical.
I once had a production issue where Collections.sort() was running on a list of 50 million records from a database query result. The garbage collector was pegging at nearly 100% because the temporary arrays created during the merge sort phase were enormous. Switching to a parallel sort on a primitive array dropped the GC pressure and cut the sort time from about 45 seconds down to roughly 12.
Get the Full Details
Transform Your Code The Magic Of 4 Methods To Sort Arrays In Seconds With Java Arraylist
2. Java 8 Streams with sorted()
The stream approach is cleaner syntactically and returns a new sorted list rather than mutating the original: List<Integer> sorted = numbers.stream()
.sorted()
.collect(Collectors.toList()); For custom sorting with streams:
List<User> sortedUsers = users.stream()
.sorted(Comparator.comparing(User::getLastName)
.thenComparing(User::getAge))
.collect(Collectors.toList()); Streams give you lazy evaluation, which means the sort doesn't execute until you call a terminal operation. This matters when you're filtering first: stream.filter().sorted() only sorts the filtered results, not the entire original list. That's a meaningful difference if your filter drops the collection size by 90%. The downside is memory. Streams create intermediate objects. For small lists it's negligible, but on a list with hundreds of thousands of elements, the overhead from boxing, lambda allocation, and the stream pipeline itself becomes measurable. In my experience, stream sorting is about 15-20% slower than Collections.sort() on the same dataset, primarily due to the pipeline setup cost.
Also worth noting: stream().sorted() uses the same TimSort implementation as Collections.sort(). There's no performance advantage in the algorithm itself. The only real difference is the API ergonomics and whether you want to chain it with other stream operations.
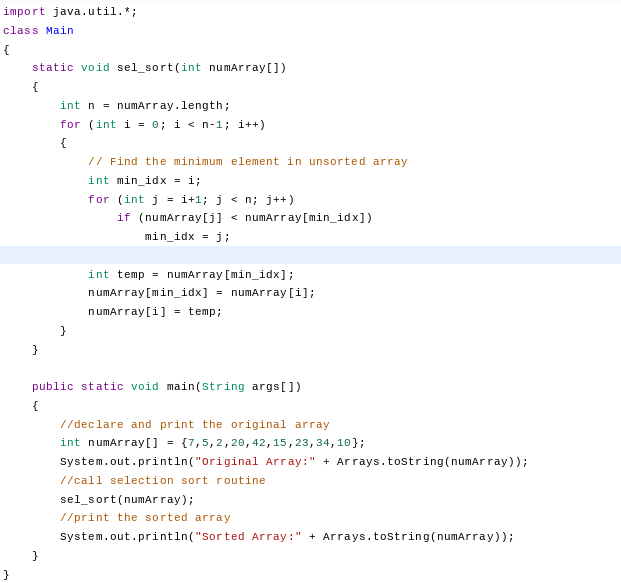
3. Parallel sorting with Collections.sort() on a parallel stream
When your list is large enough, parallel sorting can slice the work across multiple CPU cores: List<Integer> sorted = numbers.parallelStream()
.sorted()
.collect(Collectors.toList()); This spawns a ForkJoinPool task for each chunk of the data, sorts each chunk independently, then merges the results. The sweet spot for parallel sorting is usually around 100,000+ elements, though this depends heavily on your hardware and the cost of comparing elements.
I ran into a problem once where parallel sorting was actually slower than sequential sorting on a list of roughly 200,000 items. The issue was that the comparator was doing a string comparison on long fields, and the overhead of splitting and merging the data across threads outweighed the benefit of parallelism. When I switched to sorting by a comparable primitive field instead, the parallel version became roughly 2.5x faster on a 16-core machine. The rule of thumb: parallel sort is worth it when the per-element comparison is cheap and the list is large. If you're sorting complex objects with expensive comparators, stick with the sequential version. You can also explicitly set the ForkJoinPool size if you're concerned about thread contention in a multi-application environment.
4. Using a custom quicksort or mergesort implementation
Sometimes the built-in sort doesn't fit your needs. Maybe you're sorting in a specific partial order, or you need to sort in-place with minimal memory overhead. Writing your own implementation gives you full control. Here's a basic in-place quicksort: public static void quicksort(List<Integer> list, int low, int high) {
if (low < high) {
int pivotIndex = partition(list, low, high);
quicksort(list, low, pivotIndex - 1);
quicksort(list, pivotIndex + 1, high);
}
}
private static int partition(List<Integer> list, int low, int high) {
int pivot = list.get(high);
int i = low - 1;
for (int j = low; j < high; j++) {
if (list.get(j) <= pivot) {
i++;
Collections.swap(list, i, j);
}
}
Collections.swap(list, i + 1, high);
return i + 1;
}
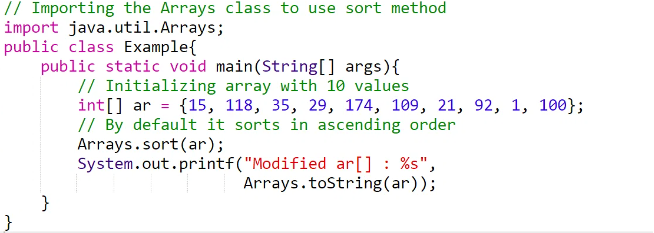
Quicksort has an average time complexity of O(n log n) but can degrade to O(n^2) in the worst case, which happens when your pivot selection is consistently bad. The standard fix is randomizing the pivot or using the "median of three" strategy. Java's Arrays.sort() for primitives actually uses a dual-pivot quicksort variant for this reason. The real advantage of a custom sort is flexibility. I needed to sort a list of transactions by a calculated score that depended on data from an external API, and there was no way to precompute that score and store it in the object. So I computed it on the fly in the comparator and cached it in a Map keyed by transaction ID. The custom sort handled the dependency naturally without requiring a preliminary data-fetch step. One thing to watch out for with custom implementations: recursion depth. A naive quicksort on 100,000 elements in a reversed order can blow the stack. Iterative quicksort or switching to insertion sort for small subarrays (the approach TimSort uses) prevents this.
Common Pitfalls
The most common mistake I see is assuming sort() is stable when it isn't. Arrays.sort() on primitive arrays is not guaranteed to be stable. If you're sorting a list of objects and stability matters—like when you've already sorted by one field and want to preserve that order while sorting by another—use Collections.sort() or stream().sorted() instead, both of which use TimSort and are stable. Another issue is null handling. If your list contains null values and you call Collections.sort() without a custom comparator, you get a NullPointerException. You can work around this by providing a comparator that treats nulls as either greater or less than all other elements: Collections.sort(list, Comparator.nullsFirst(Comparator.naturalOrder()));
Concurrent modification is a subtle one. If you're sorting a list that's being accessed by another thread simultaneously, you can get inconsistent results or exceptions. Synchronize access or use a concurrent data structure like CopyOnWriteArrayList if the list is small and reads far outnumber writes. Finally, don't confuse sorting with ordering. Sorting rearranges elements. Ordering just arranges them according to some criteria. If you're just displaying data in a particular order and the underlying collection doesn't need to change, consider using a sorted view or a TreeMap/TreeSet instead of actually sorting the list.