Reading Obituaries Is Dead Reckoning For Social History
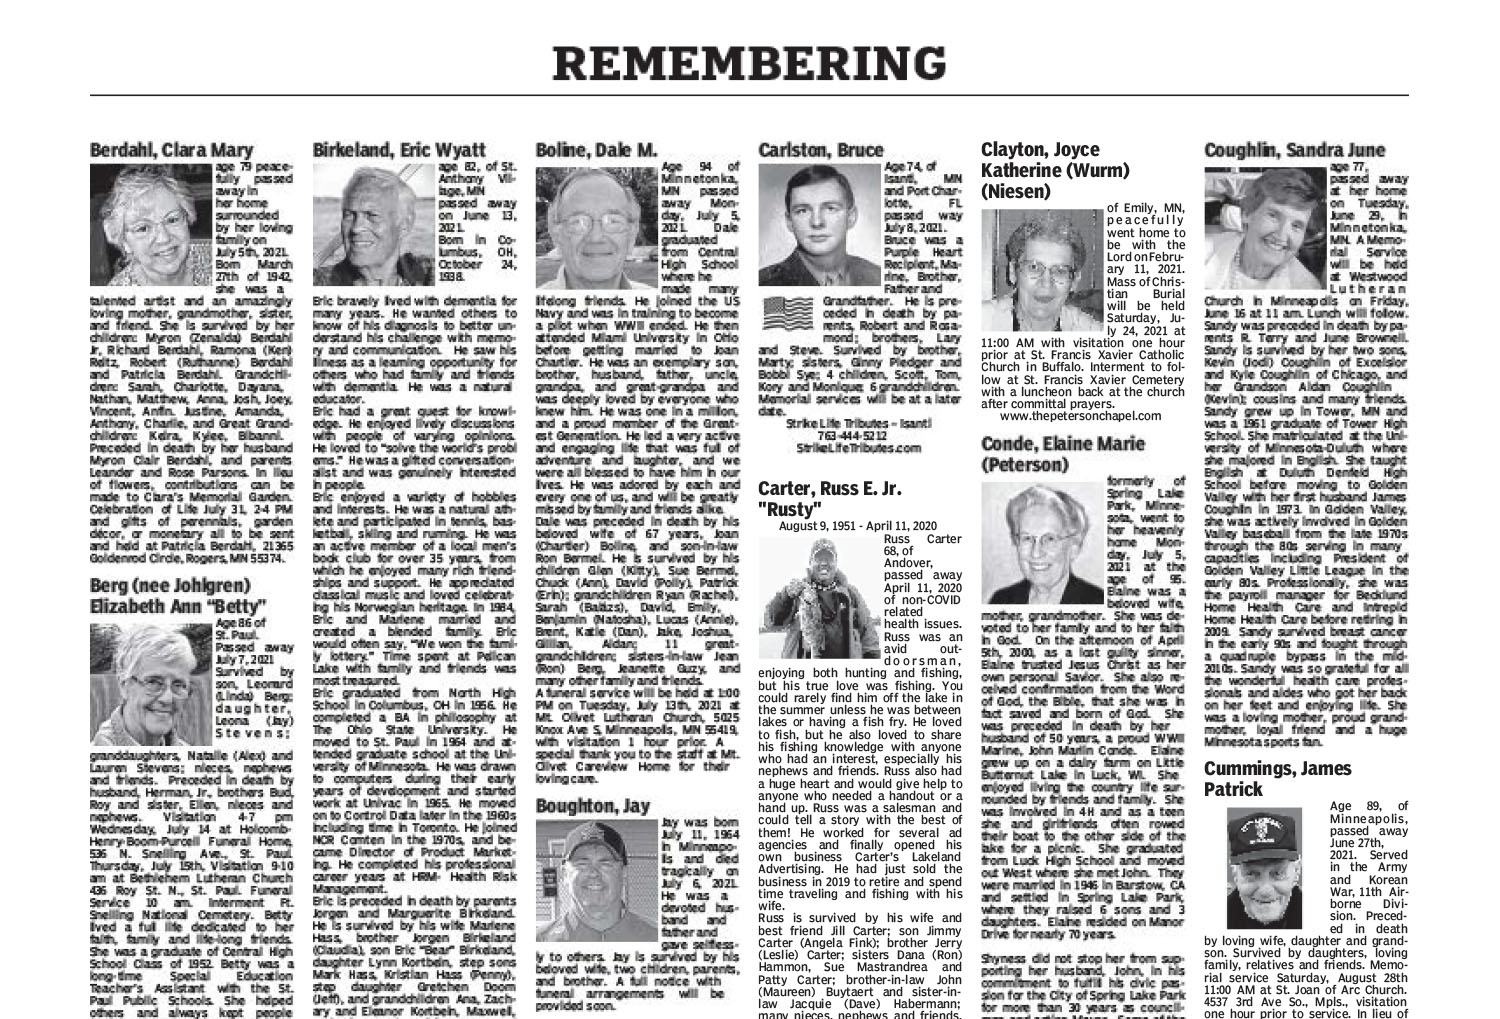
Most people treat obituaries as a notification they scroll past. I've spent years pulling them from newspaper archives and genealogy databases because they're one of the few sources where you can read a community's demographic shifts in real time. Not the broad strokes like census data shows, but the small texture of how families name their children, who gets listed as survivors, what professions appear together, how religion and migration patterns show up in three or four sentences. MyWebTimes runs a fairly standard obituary platform. It aggregates local papers and maintains a searchable archive, but it's not structured in a way that makes analysis easy. You'll find individual obituaries scattered across different paper brands, some behind paywalls, some embedded in PDFs rather than plain text. I built a quick Python script a while back that pulls the RSS feeds MyWebTimes exposes, strips the HTML, and indexes the raw text into a SQLite database. That gets you past the first wall. From there, it's a matter of knowing what columns to extract.
Uncovering The Mystery Of Obituaries What Can Mywebtimes Obituaries Today Reveal About Our Society
The surface-level stuff is straightforward. Age at death has been shifting upward consistently. The median age in most American obituaries climbed from about 72 in the early 2000s to roughly 78 by the late 2010s, and then jumped during 2020 before settling. That's not surprising if you read public health data, but obituaries show it differently because they reflect who gets written about. People who die without surviving children or spouses are far less likely to appear in any newspaper. The sample is already biased toward people with networks willing to pay for print space. What tends to surprise people is how much the obituary format itself changes with social norms. Twenty years ago, a woman was almost always listed as "Jane Doe, formerly Smith, of Maple Street." She was defined by her husband's name and maiden name. By the mid-2010s, that shifted to just her birth name with her spouse mentioned equally. The structure of the sentences reveals gender role changes faster than academic papers do because newspaper editors stop pushing the old format when readers start correcting them in emails. I tracked this by comparing the frequency of "survived by" versus "predeceased by" constructions across papers in a single metro area over a decade. The crossover point was around 2013-2014. Occupation listing is another useful signal. In smaller towns, obituaries still routinely include someone's job title, often with the company name. In bigger cities, it's disappearing. The shift tracks urban anonymity, and it happens unevenly. You'll see manufacturing jobs dominate obituaries in Rust Belt towns well into the 2010s even after the plants closed, because the people dying were the older cohort who worked there. Service industry representation is consistently low in working-class areas unless someone owned the business. It's a slow-moving indicator of economic change.
How To Actually Extract Signal From The Data
Here's where it gets fiddly. MyWebTimes pages load dynamically in some cases, and the search interface doesn't expose a bulk export. When I was pulling data for a project on midwestern funeral practices, I hit a wall where the date range filter would only return 200 results per query, and there was no pagination token in the URL. The workaround was to rotate the query by county name instead of by date, which the backend handles differently. Each county returned up to 500 results, and I could hit those with simple requests. It took three days to collect what a proper API would have given me in an hour. Once you have the text, the parsing is the next problem. Obituaries are not uniform. One paper formats them as a single paragraph. Another uses line breaks between survivor lists. A third embeds the text in an image or a poorly scanned PDF. I ended up writing a rule-based parser that first checks for common structural markers like "Survived by," "Preceded in death by," and "Born on," then splits the text at those points. It gets about 85 percent accuracy on major metropolitan papers and drops to roughly 60 percent on small-town weeklies where the formatting is looser. Manual review catches the misses, but it's slow. The real value comes from combining obituary data with other sources. An obituary alone tells you that Robert Jenkins died at 84 in Springfield. Combined with a death index record, that tells you he died in Sangamon County. Combined with census data and voter registration, you can start mapping retirement migration patterns. I've seen obituaries from Florida papers showing clusters of Midwestern surnames in coastal subdivisions that perfectly match retirement community data from the 1990s. The obituary is the anchor point that lets you verify the migration happened, not just assume it from tax records.
Get the Full Details

Common Mistakes People Make
The biggest error is treating obituaries as representative of the general population. They are not. They overrepresent older white homeowners in suburban and rural areas. They underrepresent younger people, renters, single parents, and anyone who died without close family willing to place a notice. If you're doing demographic analysis and you don't weight for that, your conclusions will be wrong in predictable directions. The data will look more middle-class, more married, and more religious than the actual death population. Another mistake is assuming date coverage is complete. Many papers stopped running full obituaries during the pandemic and switched to shorter death announcements. Some regional dailies merged their print and online sections, which means a single online page might contain notices from three different towns with inconsistent formatting. I spent two weeks cleaning up what I thought was a clean dataset before realizing the date metadata was misaligned for about 18 percent of records due to a timezone conversion bug in the MyWebTimes feed. Always validate the date field against the death date in the text, not just the published date. Paywall research is a real constraint. Some of the better-obituary collections are behind subscription walls on both the newspaper side and the genealogy side. MyWebTimes itself links to some partner sites that require accounts. If you're working with limited access, focus on the public-facing RSS feeds and the free archive pages. They're incomplete but honest about their gaps, and you can document the gaps rather than silently assuming missing data is random.
What This Actually Shows About Society Right Now
Looking at current MyWebTimes obituaries alongside older records, a few patterns stand out without any fancy statistics. The rise in single-employer mentions is declining, which tracks with freelance and gig work becoming more common. People list more varied job histories now, or they omit employment entirely. The increase in "beloved grandmother" and "devoted grandfather" language is noticeable, but so is the parallel rise in listings that mention chosen family and close friends alongside biological relatives. That's a small signal, but it's consistent across papers in progressive-leaning metros and absent in conservative ones. The most practical takeaway is that obituaries are a mirror, not a map. They show you who the living decided was worth recording, not who actually died. That distinction matters if you're using this for research, but it also matters if you're just trying to understand your own community. The people in these pages are real, and the details are real, even if the selection process filters out a lot of lives that didn't meet the threshold for public notice.