Why You Should Stop Ignoring Contiguous US Infrastructure Mapping
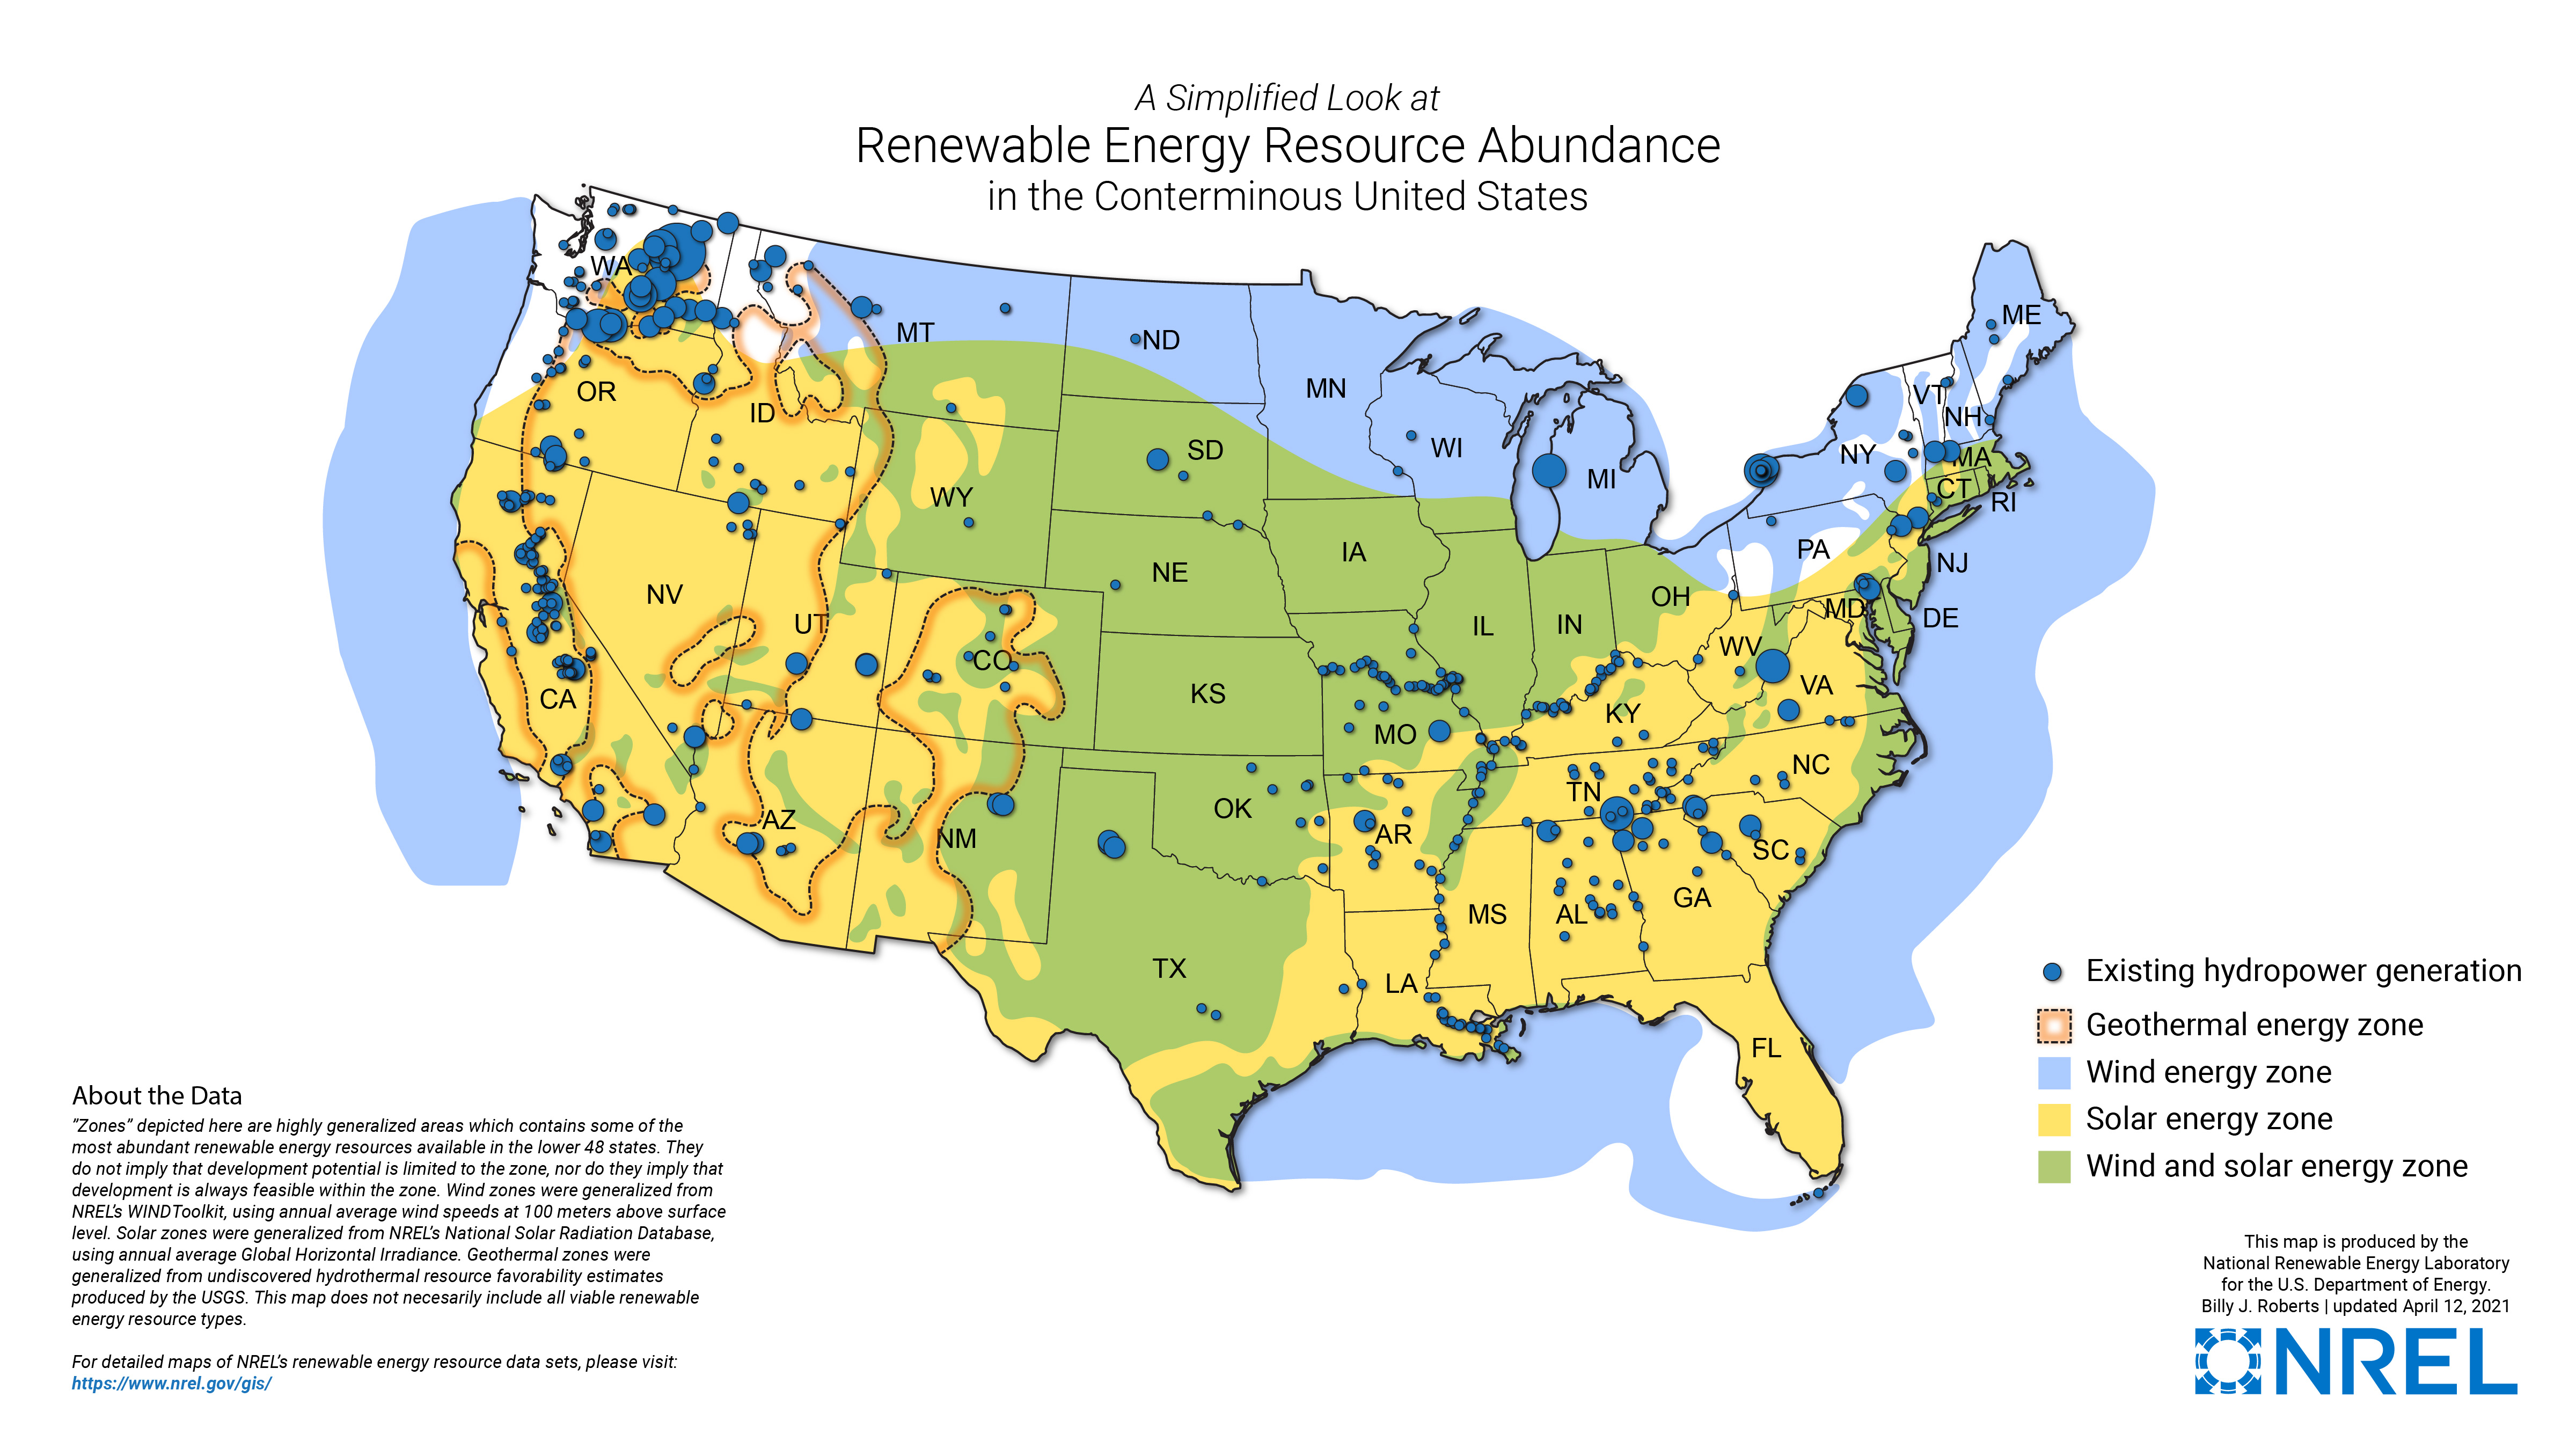
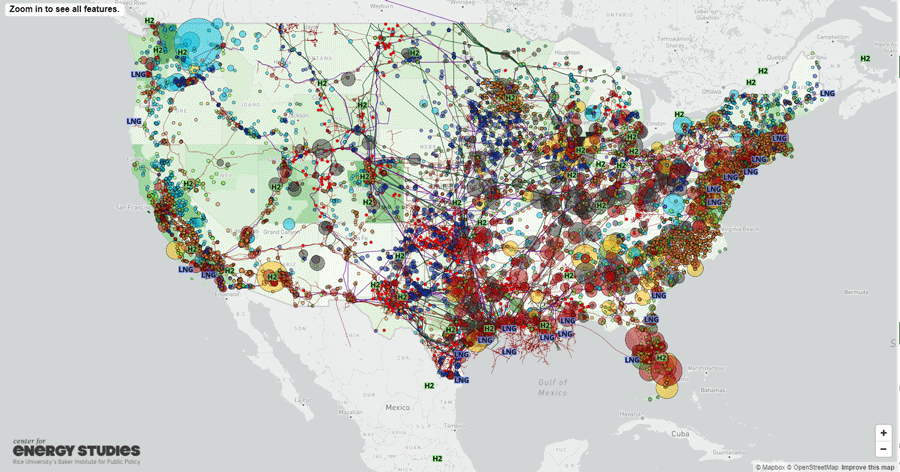
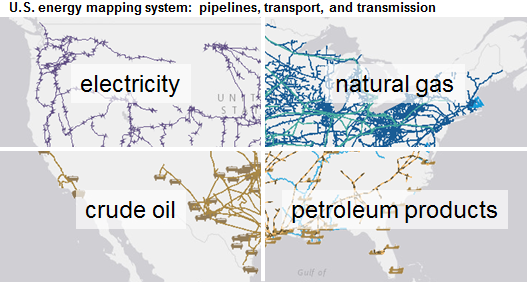
Most people think of the lower 48 as just a bunch of states on a map. The reality is that underneath and above every square mile of that landmass runs a dense, overlapping web of energy and infrastructure that most organizations have never properly catalogued. Pipelines crisscross the Midwest. High-voltage transmission corridors slice through rural counties. Substations cluster in patterns that make sense only when you layer them against population centers and industrial zones. The data exists, but it is scattered across dozens of different agencies, private datasets, and legacy formats that were never designed to work together.I spent several years building geospatial models for energy infrastructure planning, and the hardest part was never the technology. It was reconciling the fact that the Federal Energy Regulatory Commission, the Department of Transportation, individual state public utility commissions, and roughly 150 independent system operators all maintain their own incomplete versions of the same information. When I first tried to produce a unified view of natural gas pipeline infrastructure across Texas, Oklahoma, and Louisiana, I ended up spending three weeks just normalizing coordinate reference systems. Different counties use different datums. Some municipal records are in NAD 27, others in NAD 83, and a few legacy systems still reference the old North American Datum from the 1920s. If you do not reproject everything into a single consistent CRS before doing any analysis, your pipeline routes will drift apart by anywhere from a few meters to over a hundred meters depending on how far you get from the prime meridian. The workaround I settled on was straightforward but tedious. I wrote a Python script using PyProj to reproject all layers into NAD 83 / CRS 4269 for point data and NAD 83 / UTM zone 15N through 17N for linear features, then validated every transformed dataset against known benchmark coordinates from the National Geodetic Survey. I cross-checked pipeline centerlines against the PHMSA pipeline mapping database and transmission lines against EIA facility-level data. Any feature that did not align within a five-meter tolerance flagging for manual review. That process cut down my reconciliation time from weeks to about two days per state combination, and it caught about forty significant misalignments that would have been invisible at a glance.
The Untapped Power Of The Us Lower 48 Mapping Americas Contiguous Energy And Infrastructure Frontier
What makes contiguous US infrastructure mapping genuinely useful is not the act of mapping itself. It is what you can do once the data is clean. Grid reliability analysts use it to model fault propagation across transmission networks. Pipeline companies rely on layered environmental and demographic data to assess corridor risk. Municipal planners use it to anticipate where new renewable generation will stress existing distribution infrastructure. The common thread is that almost nobody has a complete picture because the pieces live in different places and talk to different standards. Here is how I approach a project like this when I need to move from raw data to something usable. First, you define the scope and pick the primary data sources. The EIA maintains facility-level data on power plants, pipelines, and natural gas storage. The USGS has topographic and hydrologic layers that matter when you are siting infrastructure near waterways. FERC has interconnection queue data that tells you which renewable projects are waiting to connect to the grid. The Federal Highway Administration publishes route-level transportation data. These are all publicly accessible, but they are not formatted for joint analysis. You pull them, you standardize them, and you store them in a consistent database structure. For the geospatial work, I use PostGIS as the backend because it handles large polygon and line datasets far better than file-based formats. QGIS is the main interface for visual inspection and manual correction. For batch processing and reprojection, Python with GeoPandas, Shapely, and Rasterio does the heavy lifting. I structure everything so that each infrastructure type gets its own table with standardized fields: facility ID, geometry, owner, operational status, capacity, and last verified date. The last verified date is critical. A lot of pipeline and substation data in public databases has not been updated since 2018. If you build models on stale data without checking timestamps, you are essentially building on sand.
One thing beginners consistently overlook is attribute topology. Just because two line features share the same coordinates does not mean they are connected in the data model. I encountered this when modeling electrical interconnections between three regional transmission organizations. The geometries looked correct on screen, but the topology graph showed zero connections because the endpoints were off by less than a meter. The fix was a snap tolerance of 0.5 meters combined with a networkx-based connectivity check that flagged any endpoints that did not actually touch. Without that step, any simulation you run will show dead ends that do not exist in reality. Data quality varies enormously across sources. The EIA data is generally well-maintained for operational facilities. FERC interconnection queue data is accurate but constantly changing, and it includes many projects that never reach commercial operation. State-level pipeline data is the weakest link. I found gaps in Texas where local mapping practices predate digital records and old paper surveys were never digitized. In those cases, the only reliable workaround is to pull satellite imagery and manually digitize the missing segments, then flag them as inferred rather than verified. Never present inferred data as confirmed. It will come back to haunt you during a regulatory review or a due diligence process. When you start running spatial queries across the lower 48, performance becomes a real issue. A simple buffer analysis around all active natural gas pipelines within fifty miles of a proposed solar farm can take hours if you are not careful about indexing. I learned this the hard way. The solution is to create spatial indexes on every geometry column and to filter by bounding box before running any intersection or buffer operation. With proper indexing, the same query drops from roughly forty minutes to about ninety seconds on a standard workstation with 32 gigabytes of RAM.
Get the Full Details
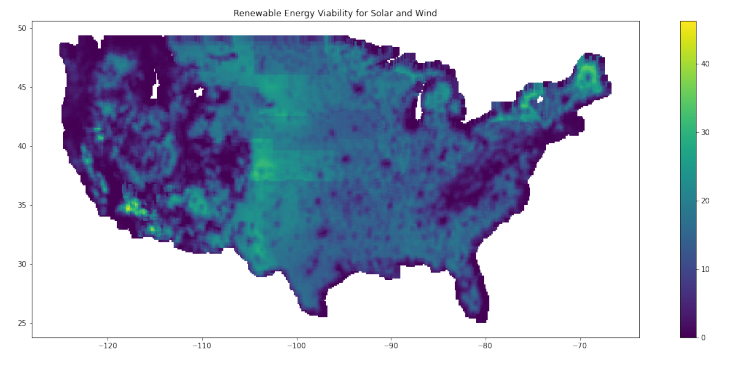
Another layer most people ignore is temporal variability. Infrastructure is not static. New pipelines get commissioned. Old ones get retired. Transmission upgrades happen every year. If you are producing a map for strategic planning, you need versioned snapshots rather than a single point-in-time dataset. I keep quarterly snapshots in a separate schema and track changes between them. This lets you answer questions like how much additional transmission capacity was added in the Southwest between 2022 and 2024, or which pipeline corridors have seen the most retirements in the past five years. Those change detection queries are surprisingly powerful for forecasting and risk assessment. The biggest limitation of this kind of work is that no single dataset covers everything, and there is no central authority that maintains a complete contiguous US infrastructure database. You will always have gaps. The best you can do is be systematic about documenting what you have, what you do not have, and what you inferred. I maintain a data provenance log for every project that records source, acquisition date, transformation steps, and confidence level for each dataset. It takes extra time upfront, but it saves you from having to redo everything when someone asks for a methodology walkthrough six months later. If you are just starting out, do not try to build the perfect comprehensive map. Pick a specific question and work backwards from that. Something like determining which counties in the Rust Belt would be suitable for battery storage deployment based on existing substation proximity, grid capacity, and industrial land availability. That gives you a focused set of layers, a clear success criterion, and a manageable scope. Once you have a working pipeline for one region, scaling it to neighboring states is mostly a matter of repeating the same process with adjusted data sources.
The tools are all available. The data is all there, even if it is fragmented. What is missing is the habit of treating infrastructure mapping as a repeatable discipline rather than a one-off consulting exercise. Build the standardized pipeline, keep your versioning consistent, and validate your results against known ground truth. Everything else is just iteration.