Why Most Decision Support Systems Fail Before They Ship
I spent three years building a DSS for a mid-size logistics company. We had a $400,000 budget, a team of six, and about eight months to deliver something that would replace their Excel-based forecasting workflow. It didn't go well. Not because the technology was bad — the actual model worked fine — but because we completely misunderstood the anatomy of the decisions it was supposed to support.The Anatomy Of Decision Making Understanding The Dynamics Of Dss Conway Sc
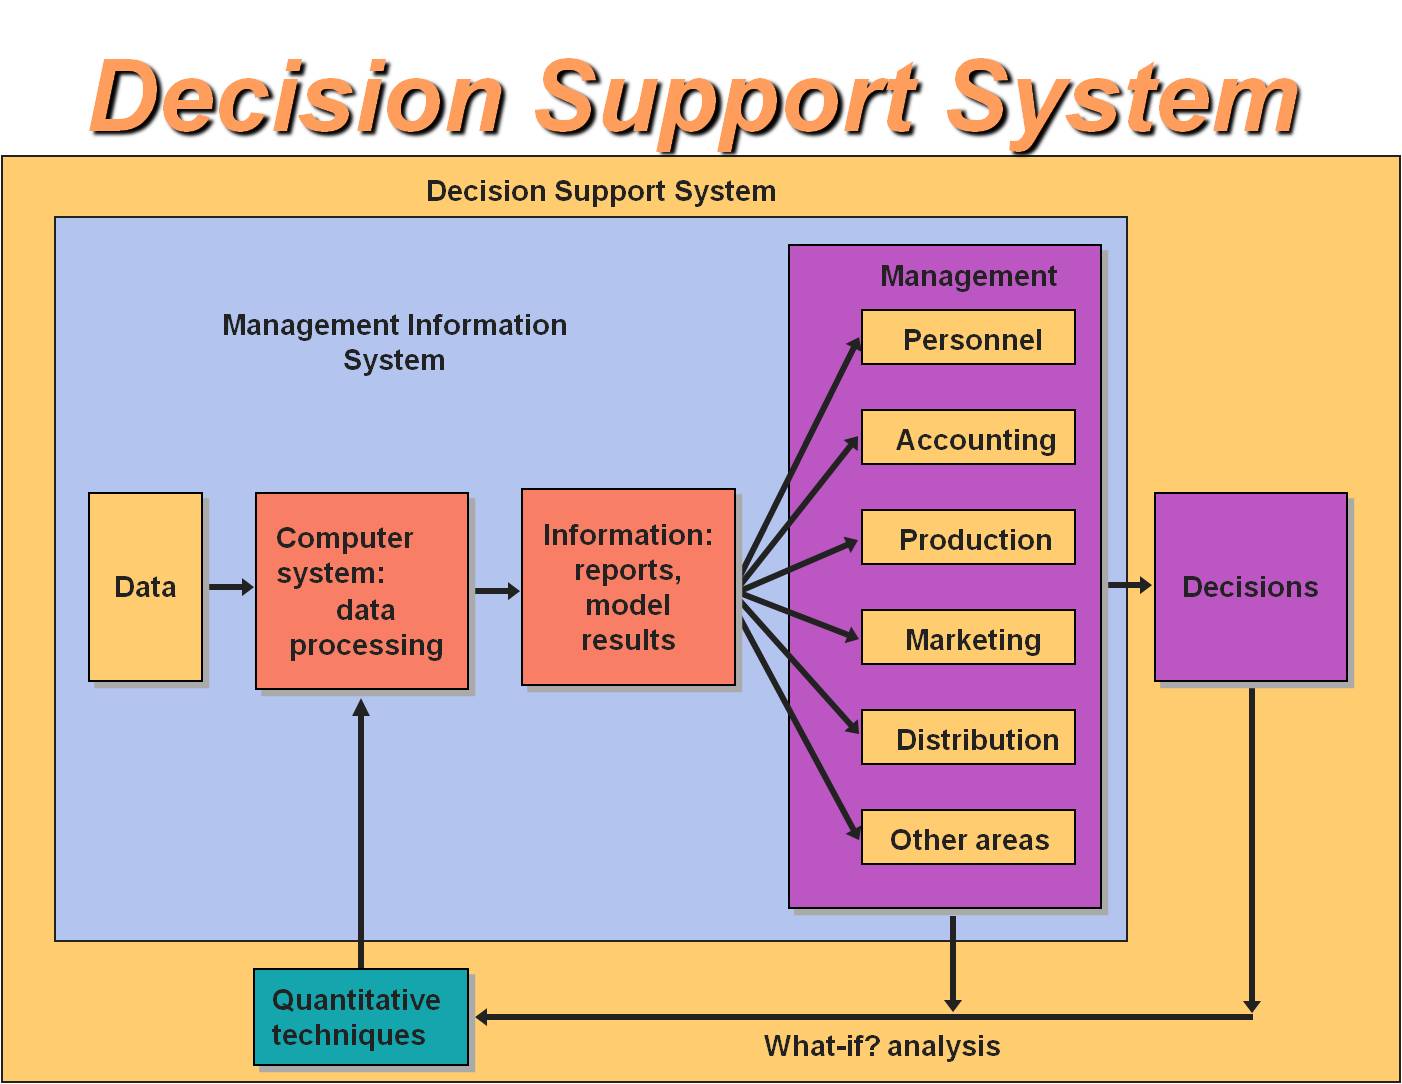
Let me be blunt about Conway's Law first, because most people misapply it. It's not just a buzzword about organizational charts. It says that the structure of your software system will mirror the communication patterns of your organization. When you're building a Decision Support System, this means the system will naturally fragment into sub-modules that match whoever talks to whom in the company. If your sales team doesn't share data with operations, your DSS will reflect that wall. You can fight it, but fighting it usually means redesigning the org structure, not the code. The anatomy of decision making in a DSS context breaks down into three layers:1. The data layer — what information is actually available and how it flows between systems. 2. The process layer — who makes decisions, what criteria they use, and what constraints they work under. 3. The interface layer — how the output of the system reaches the person who needs to act on it.
Most people build the data layer first. That's backwards. The process layer determines what the data needs to support. I learned this the hard way when our logistics DSS was nearly unusable because we hadn't accounted for the fact that warehouse managers were making real-time routing calls without any system input — they trusted their gut and a whiteboard. Our system was designed for planners who sat at desks and had twenty-four hours to optimize. It was solving the wrong problem. Here's what happens when you get the anatomy wrong: you end up with a Decision Support System that generates beautiful reports about decisions nobody makes. I've seen it repeatedly. The system outputs confidence intervals and scenario trees while the actual decision-makers are working off text messages and whatever they remember from the last meeting. Now, a practical point about implementation. When I say "Dynamics of DSS" I'm talking about how the system behaves across time, not just its architecture. A static model of decision making is almost always wrong because decisions compound. A routing choice today affects tomorrow's inventory. A pricing decision this quarter reshapes next quarter's customer expectations. The system needs to represent those feedback loops or it's just a fancy calculator with a dashboard.Conway's Law and DSS Design
The scariest part about Conway's Law in practice is that it works against you whether you acknowledge it or not. When I was working on that logistics platform, I watched the development team organically split into camps: the API team, the reporting team, the optimization team. Each group built interfaces that matched their own communication boundaries. There was no middle layer connecting their outputs until we forced one in. By then, the project was three weeks behind schedule. The workaround I used was deliberate and not popular with management. I mapped every decision point in the organization first — not what people said they did, but what they actually did. I shadowed dispatchers for two days. I sat in on weekly planning meetings. I found that the real decisions happened in fifteen-minute hallway conversations, not in the formal process they'd documented for us. Once I had that map, I rebuilt the system architecture to mirror the actual communication paths, not the org chart. It still had silos, because the org had silos, but now those silos aligned with how decisions actually flowed. The system became usable within a month of that pivot.Common Pitfalls When Building DSS Tools
There are a few traps that show up consistently.Pitfall 1: Treating uncertainty as a bug. Decision makers know their inputs are uncertain. If your system presents a single number without any indication of confidence or range, they will ignore it. That's not resistance to technology. That's the system lying by omission. Show the variance. Show the scenarios. Make the uncertainty visible. Pitfall 2: Optimizing for accuracy over usefulness. A model that's 94% accurate but takes three hours to run is often worse than one that's 87% accurate and runs in forty-five seconds. Decisions have deadlines. The best DSS respects the decision timeline, not just the statistical ideal. Pitfall 3: Assuming the user will adopt the right process. If your system requires users to enter data in a specific format and that format doesn't match how they already work, they'll find a workaround. Or they'll input garbage data. Or they'll stop using the system entirely. Build around existing habits, don't fight them.