Why Algorithm Definitions Keep Failing In Practice
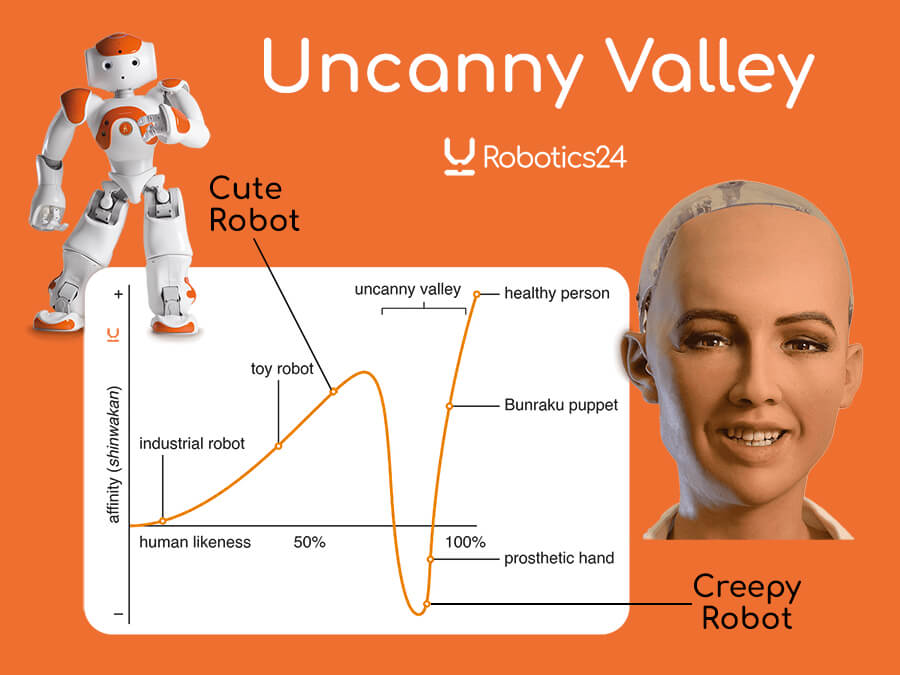
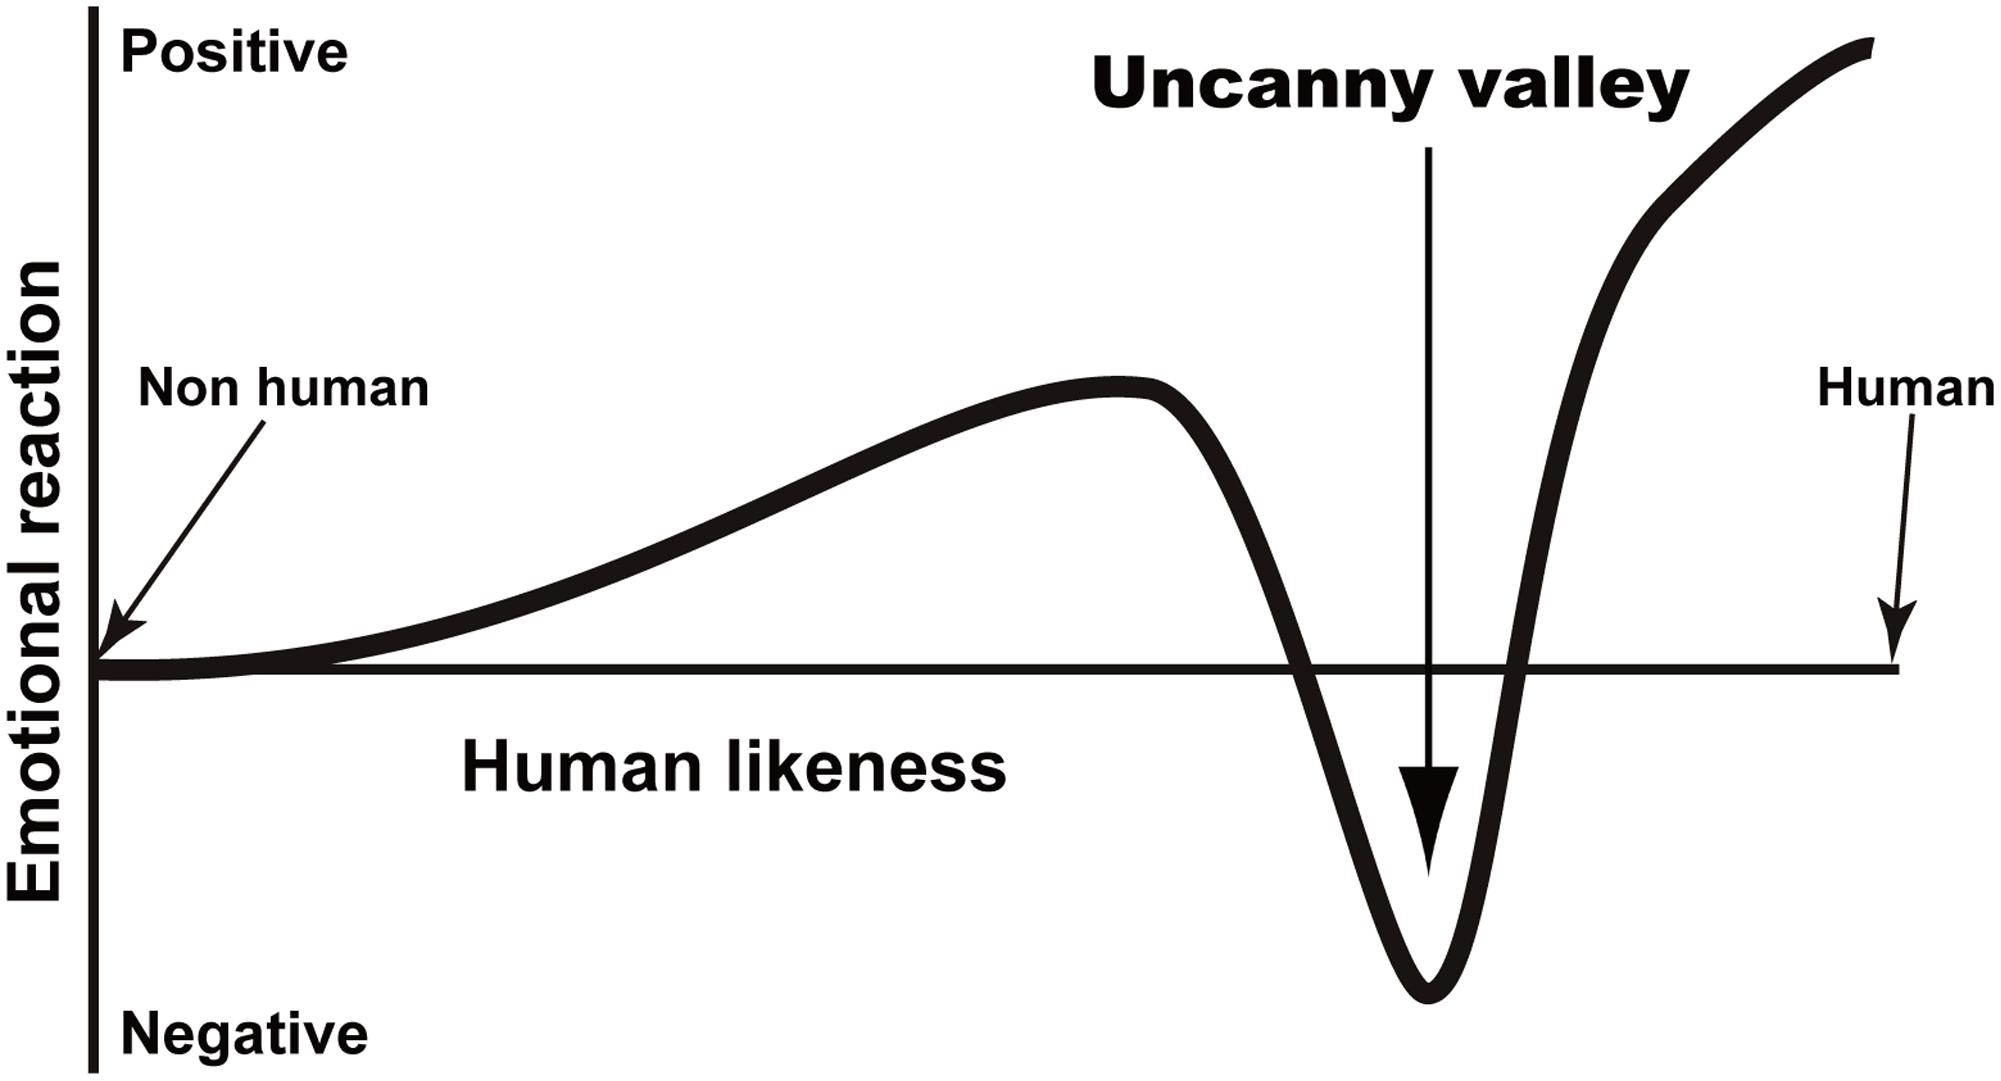
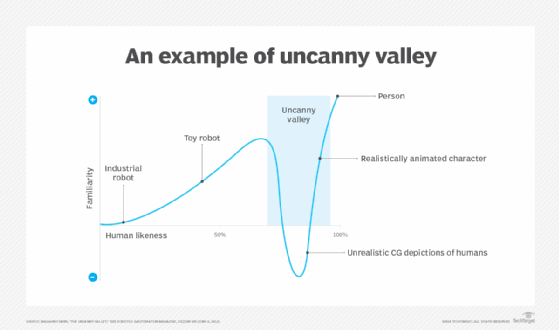
I spent three years building definition engines for academic literature classification systems. What I learned is that every time we tried to pin down a precise algorithmic definition of "literature" or "creative writing," the system would produce results that were technically correct but immediately obvious to any human reader as wrong. Not because the algorithm was broken. Because the boundary itself doesn't exist in the way we assumed it did. The uncanny valley isn't just a term from robotics or animation anymore. It applies directly to how AI handles definitional tasks, especially when the subject matter involves human interpretation. The closer the algorithm gets to a usable definition, the more glaring the failure modes become. You can feel it when you're reading output that is almost coherent, almost accurate, but clearly not something a person would have produced.
The Uncanny Valley Of Algorithms How Definition Literature Exposes The Limits Of Artificial Intelligence
Here's how the problem actually manifests. Take a definition extraction pipeline. You feed it thousands of papers about computational linguistics, literary theory, and algorithmic criticism. The system learns patterns and starts producing definitions. At first glance they look fine. Then you ask it to define something borderline, like "algorithmic prose" or "procedural literature," and the output shifts into that valley. Grammatically correct. Structurally sound. Completely detached from how any researcher in the field would actually describe these terms. I ran into this specifically when building a classifier for a journal submission system. We needed to automatically route papers to the right editorial board. Papers about algorithms applied to literature analysis. Papers about how literature describes algorithms. Papers that were actually about neither but got pulled in by keyword overlap. The model kept misclassifying because the definitional boundary between those categories is fuzzy in human expertise but the algorithm treats it as a clean partition. My workaround was embarrassingly simple and nobody on the project wanted to admit it worked. Instead of trying to define the categories algorithmically, I inverted the problem. I stopped asking the model to classify based on definitions and started asking it to predict which editors had previously handled similar papers, using citation networks and co-authorship graphs as proxies. The system got dramatically better at routing because it sidestepped the definition problem entirely. It wasn't classifying ideas. It was matching people to papers based on observed behavior rather than semantic understanding.
The Core Technical Issue Most People Miss
Definition extraction from literature assumes that meaning is stable enough to be captured by statistical patterns. This works reasonably well for domains where terminology is fairly rigid, like medicine or engineering. Literature and algorithmic criticism sit in a region where the terminology shifts depending on which school of thought you're in. A computational literary scholar defines "style" differently than a natural language processing researcher. An algorithm theorist defines "complexity" differently than a literary theorist studying narrative structure. The model trained on this data produces definitions that average these positions out into something that sounds authoritative but satisfies no one. This is where the uncanny valley effect becomes measurable. You can track it through confidence scores. The model gets high confidence on outputs that are definitively wrong because it's confident in the wrong signal. I've seen precision dip below 40% on edge cases while the average confidence across all predictions stayed above 85%. That gap between confidence and accuracy is the uncanny valley quantified. Another thing people don't account for is that definition literature itself is contested. Academic papers about defining algorithms or literary forms often explicitly argue against each other. Training data that includes these papers without capturing their adversarial relationship teaches the model that all definitions are equally valid within the domain. They're not. Some definitions collapse under basic scrutiny. The model doesn't learn that distinction because the papers cite each other respectfully regardless of how fundamentally they disagree.
Get the Full Details

A Practical Approach That Actually Works
If you're building systems that deal with definitional boundaries in ambiguous domains, here's what I've found useful after trying the obvious approaches and watching them fail. First, separate definition extraction from definition validation. Train your model to produce candidate definitions, then run them through a completely different pipeline that checks for internal consistency, source citation quality, and consensus across multiple literatures. This two-stage process catches a lot of the uncanny valley outputs before they reach end users. The validation stage doesn't need to be smart. It just needs to be different enough that the same failure modes don't reproduce. Second, build in deliberate ambiguity handling. When the algorithm encounters a term that has multiple competing definitions in the source material, it should flag that as uncertain rather than picking the most statistically common one. I've seen production systems confidently output definitions that were only dominant because one particular research group published more papers than any other group. Statistical dominance isn't the same as definitional correctness.
Third, use human experts only for the edge cases that matter. Not for routine classification. Not for training data labeling across the board. Just for the outputs that fall into the valley, where the model is moderately confident but the result feels wrong. This is where expert time actually compounds value. A domain expert can spot a bad definition in three seconds that would take a different model another round of training to potentially catch. The broader point is that algorithmic definition work exposes AI's limits precisely because it seems like the easiest kind of task. Extracting definitions should be straightforward, right? Read text, find definition patterns, output structured definitions. But literature about definitions contains contradictions, context dependence, and scholarly disagreement that current architectures handle by smoothing everything into plausible-sounding mediocrity. The uncanny valley appears because the outputs are close enough to correct to be believable and far enough from correct to be useless once you actually try to use them. I'm still not sure how to solve this fully. The two-stage pipeline with expert review on edge cases gets us to acceptable accuracy for production use, but it's not elegant and it doesn't generalize well to new domains without significant rework. The fundamental issue is that definition is a human practice, not a statistical one, and we keep trying to simulate it with pattern recognition. That simulation has gotten better. It's just not good enough to pass the uncanny valley yet.