Understanding Central Time and the Reality Behind the Phrase
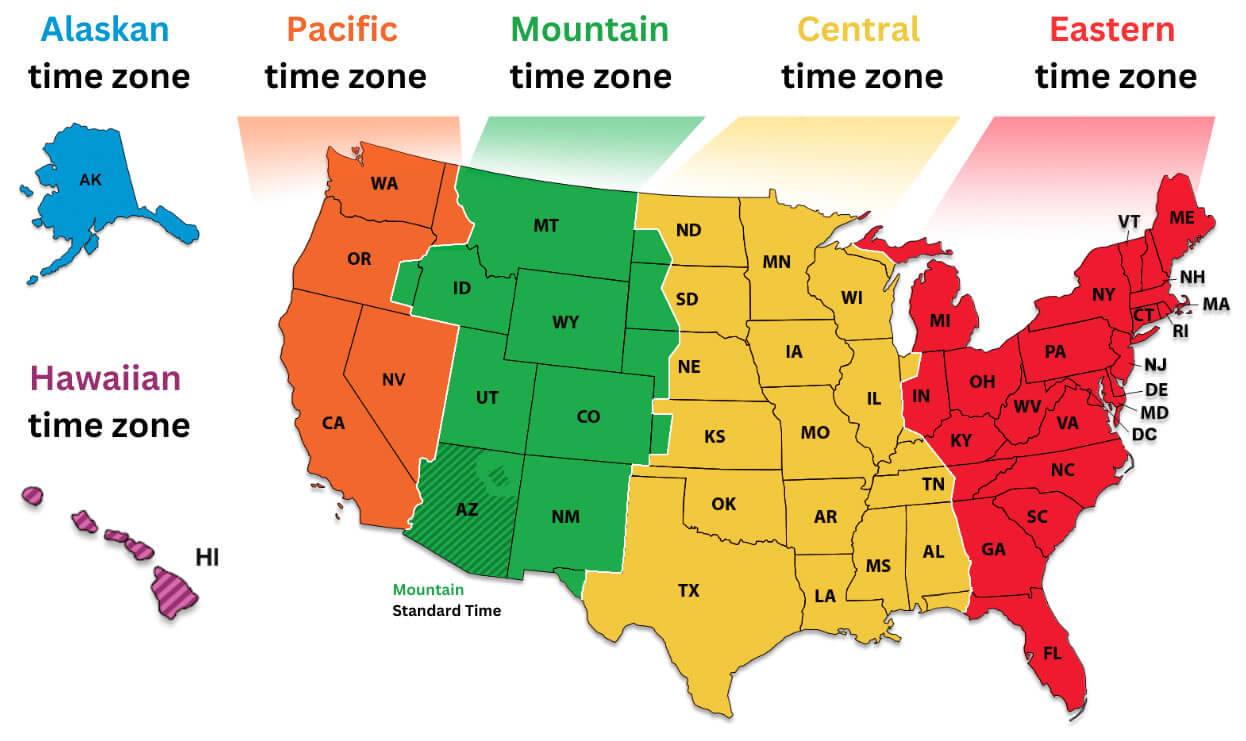
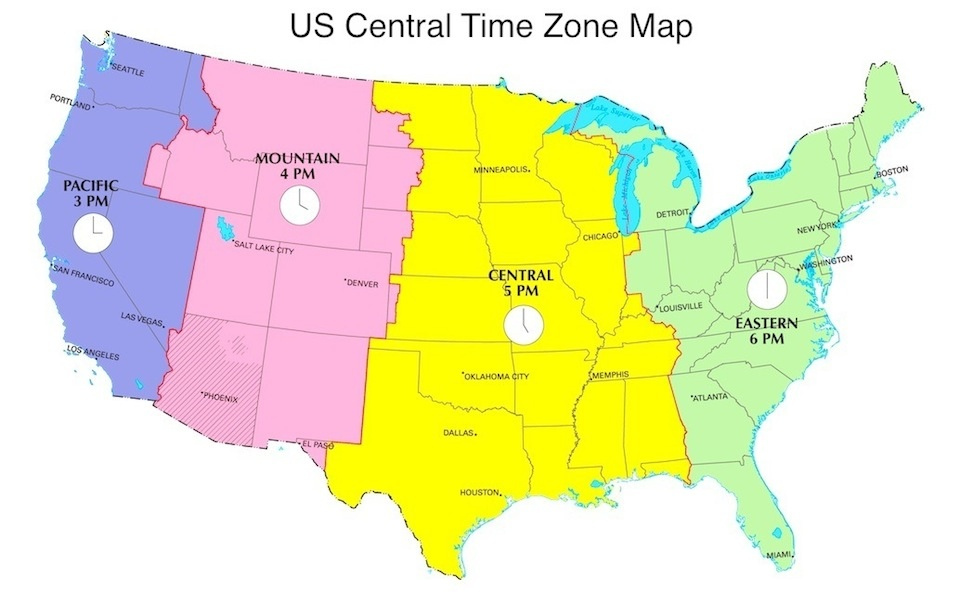
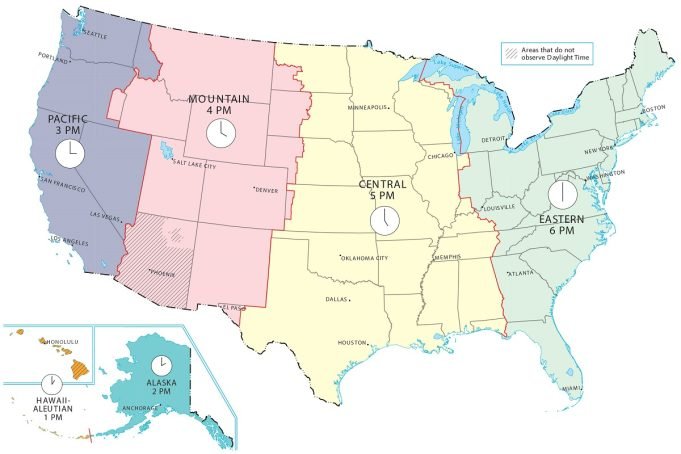
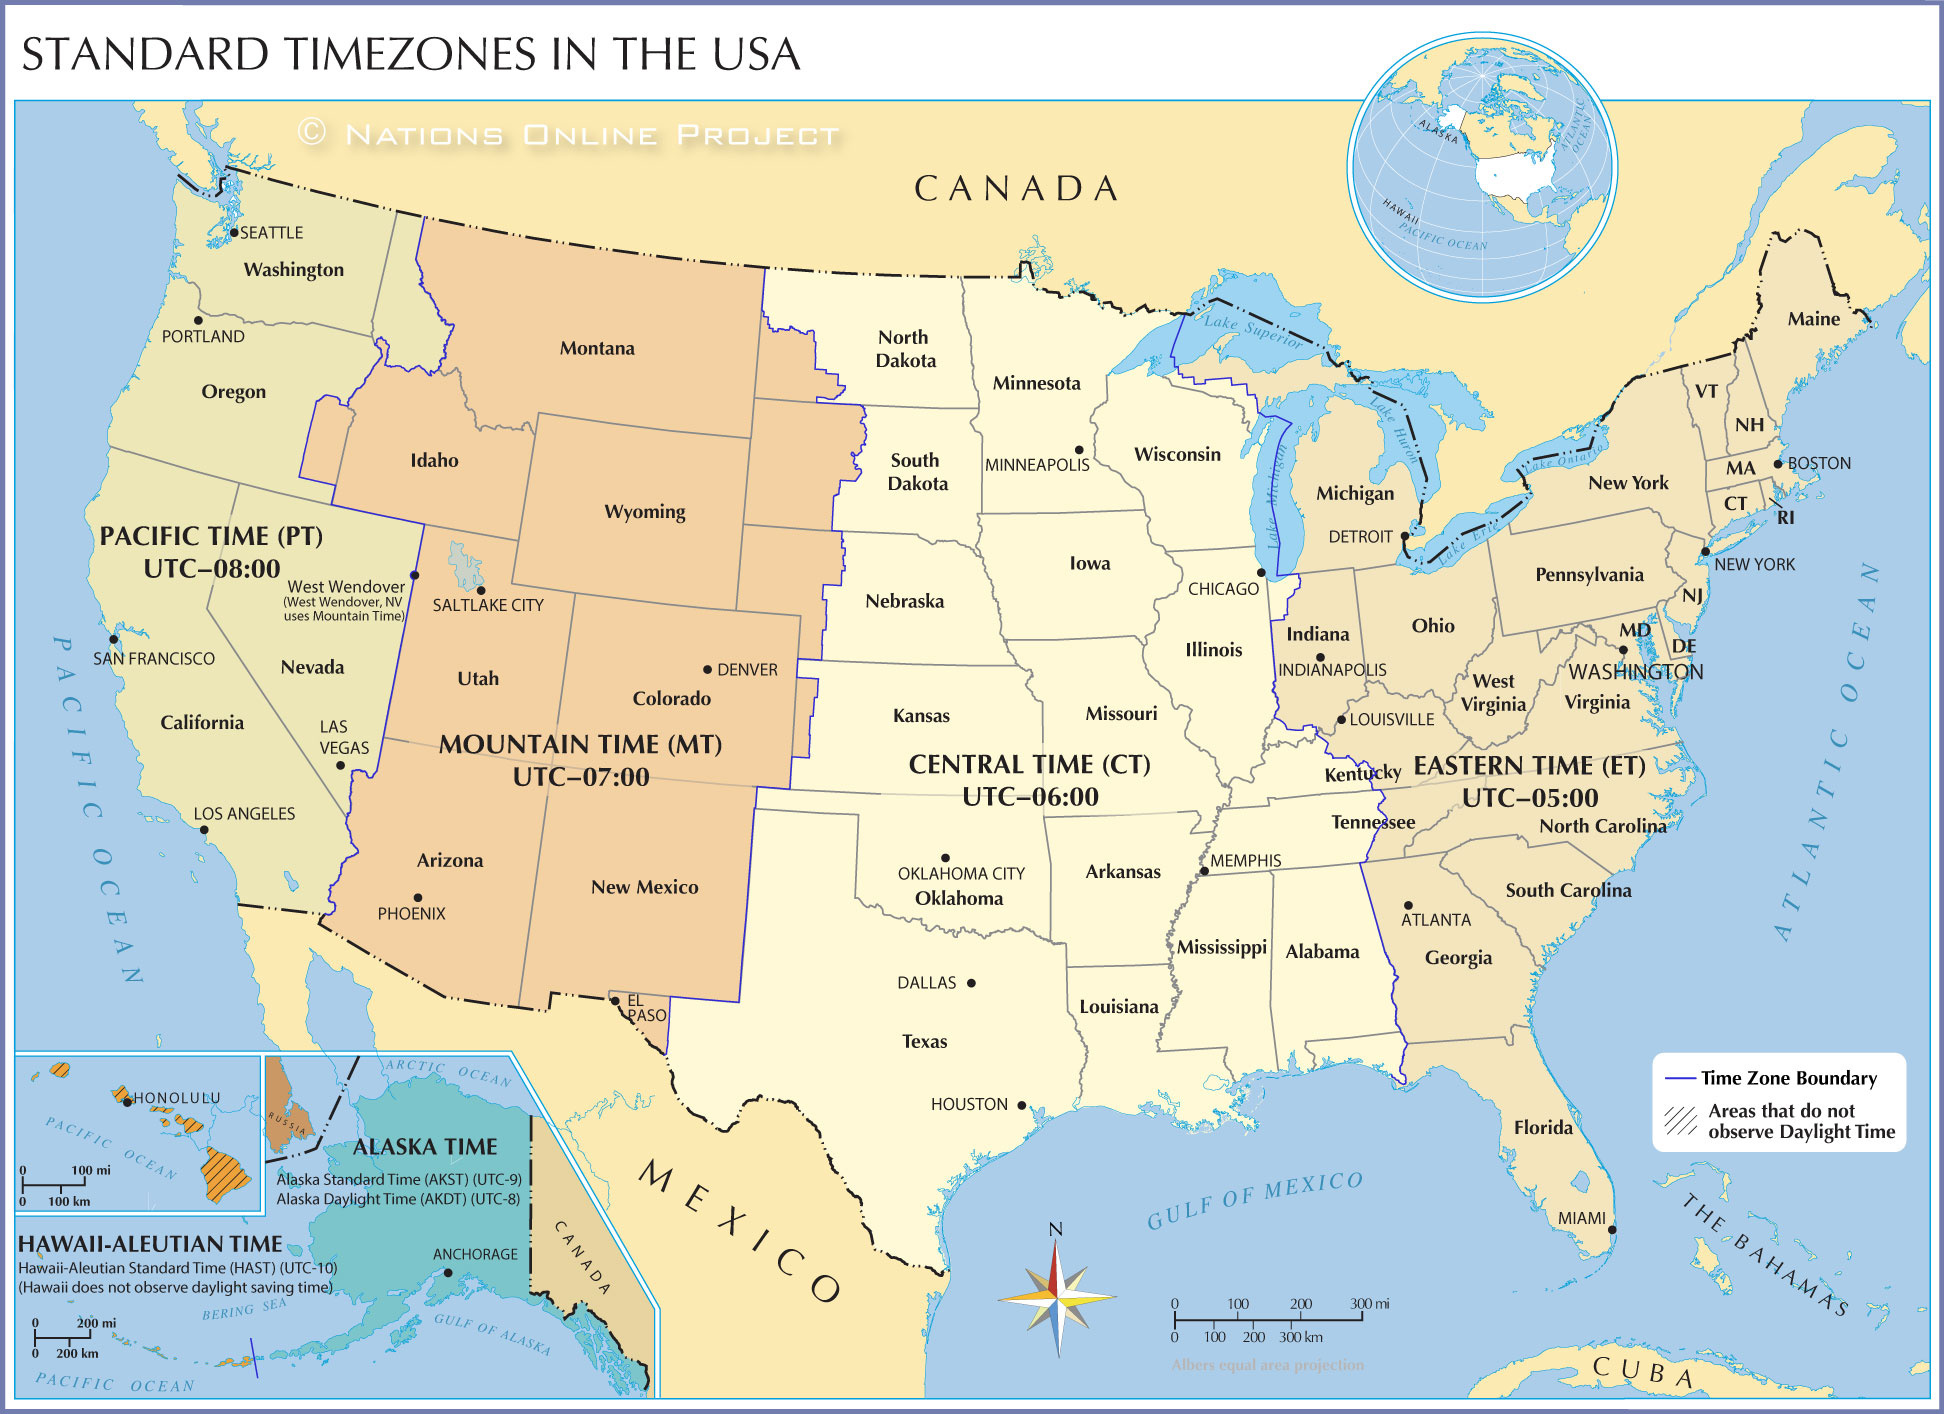
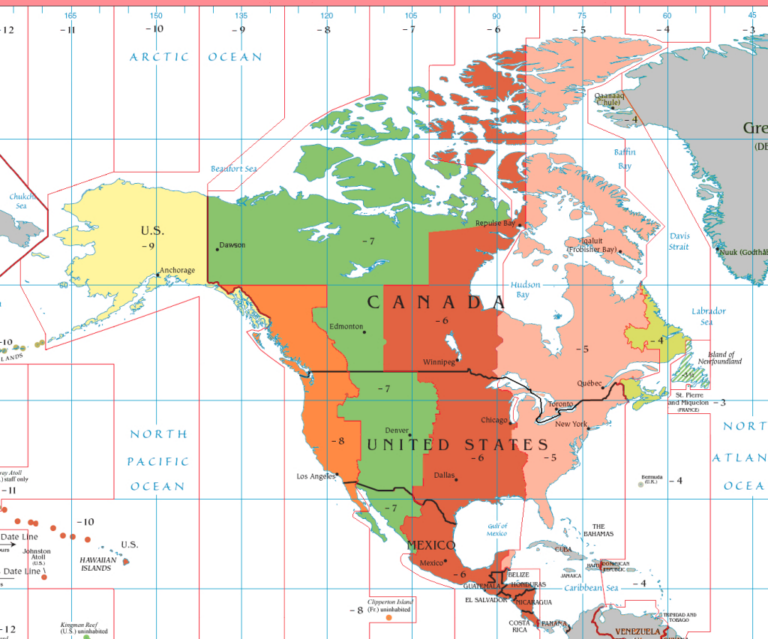
There is no system, protocol, or technical standard known as "The Quiet Heartbeat Of Americas Central Time Zone." That phrase doesn't exist in any industry documentation, RFC, or engineering resource I've come across in years of working with distributed systems and timekeeping infrastructure. What does exist is Central Standard Time (CST), Central Daylight Time (CDT), and the various operational realities of working with that offset in software and networking. If you're encountering this phrase somewhere, it's almost certainly creative writing or an internal nickname that hasn't been documented publicly. I've seen teams name their internal cron jobs, heartbeat monitors, or clock-sync services with poetic names. "The Quiet Heartbeat" sounds exactly like something a small dev team would call their CST-based health-check service and then forget to add to any README. If that's what you're dealing with, your first move should be tracking down whoever named it and asking where the actual docs are. The Central Time Zone runs UTC-6 during standard time and UTC-5 during daylight saving time. The DST transition happens on the second Sunday in March and the first Sunday in November. That's the part that breaks things, not any mystical heartbeat mechanism.
How CST Actually Works in Production Systems
I once spent an afternoon debugging a payment reconciliation job that kept producing off-by-one-hour discrepancies every spring and fall. The system stored timestamps in UTC internally but did its date-range calculations in CST without properly handling the transition days. The fix was straightforward once I found it: switch all boundary calculations to use explicit UTC offsets instead of named timezone strings, and add a regression test that simulates the March and November transition weeks. That test alone caught three similar bugs in other services on the same codebase. Here's what most people miss about working with Central Time in distributed systems. The first issue is that not every service in your stack respects the same DST rules. The US changes DST on a fixed calendar rule, but if your infrastructure touches any systems serving Mexico or Indiana, those jurisdictions have different transition dates or don't observe DST at all. I learned this the hard way when a cross-border reporting pipeline started generating duplicate records because one microservice was in a US Eastern timezone library and the other was using a server configured to Mexico City time. They diverged by an hour for part of 2023 before anyone noticed. The second counter-intuitive thing is that storing everything in UTC and converting to CST only at the presentation layer sounds correct on paper but creates real problems when you're doing aggregations, scheduling, or windowed queries. If you need to answer "how many events happened on a given Central Time day," doing that conversion at query time across billions of rows is expensive and error-prone. The better approach is to store a materialized CST date column alongside your UTC timestamp, updated at insert time. This means you pay the conversion cost once, not on every read.
Practical Approach to Managing CST in Your Stack
Decide early whether your application needs to handle DST transitions or whether you can just treat Central Time as a fixed UTC-6 offset. Many internal tools don't actually need DST awareness because their users are all within the same region and the edge case of the transition week doesn't affect the output. Fixing the offset simplifies everything and eliminates an entire class of bugs. Only add full tz database support when you have a real requirement for it. When you do need proper timezone handling, use the IANA timezone database, not the older three-letter abbreviations. CST is ambiguous — it's used for Central Standard Time in North America, China Standard Time, and Cuba Standard Time, all of which are different offsets. I've seen this cause real data corruption in ETL pipelines where a CSV import job interpreted "CST" as UTC+8 instead of UTC-6. The logs showed perfectly valid timestamps, but the dates were eight hours off, and the downstream aggregation was silently wrong for months. For scheduling recurring jobs in Central Time, avoid cron expressions that assume a fixed offset. Use something like the Python `schedule` library with explicit timezone arguments, or on Linux set the `TZ` environment variable in the crontab itself rather than relying on the system default. A single misconfigured server timezone in a container cluster can cause jobs to run at the wrong Central Time for days before anyone notices, especially if the containers get rescheduled onto nodes in different timezone configurations.
Get the Full Details
Where This Breaks Down
None of this is elegant. There is no clean solution to the DST problem because the problem is fundamentally messy — the rules change, different regions follow different rules, and historical timezone data has been revised retroactively. If your system needs to produce auditable reports spanning multiple decades, you will need to account for timezone changes that happened before your software even existed. The pytz library, which many older codebases rely on, handles this poorly. Use `zoneinfo` in Python 3.9+ or the equivalent in your language of choice. If you found the phrase "The Quiet Heartbeat Of Americas Central Time Zone" in a specific codebase, internal wiki, or product documentation, share the context and I can help you track down what it actually refers to. Otherwise, the practical takeaway is that Central Time is just UTC-6/UTC-5 with DST, and the only thing quiet about it is how easily it goes unnoticed until something breaks at 2:15 AM on the first Sunday in April.