What You Actually Need to Know Before Touching the Console
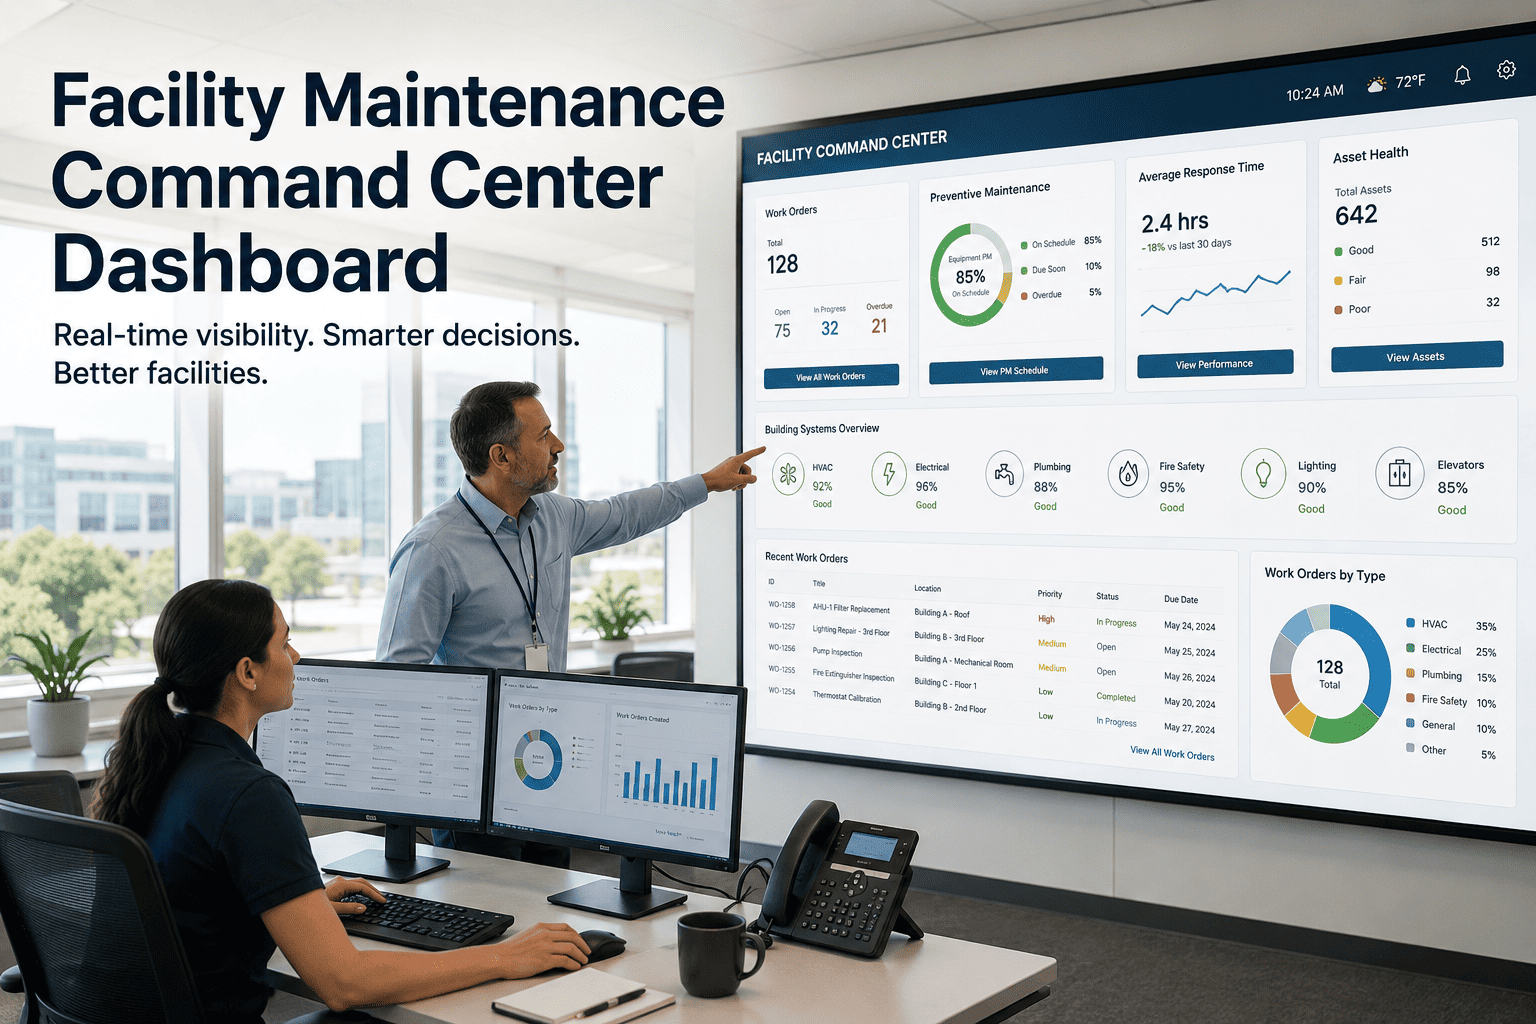
Most people approach a station command center dashboard expecting it to be a polished overview panel that tells you everything at a glance. The reality is more frustrating. The dashboard is a collection of widgets that pull from different data sources, and if those sources aren't aligned, you're looking at a beautiful screen showing half-truths. I spent three weeks untangling a monitoring setup where the temperature readout and the vibration sensor were reporting on completely different time windows. The dashboard looked normal. The data wasn't. It took me comparing raw API timestamps to realize the two streams were shifted by roughly four hours because one was pulling from a cached snapshot and the other was live. Let's get the basics out of the way first. A station command center dashboard is a centralized visualization layer that aggregates telemetry, status indicators, and control inputs from multiple subsystems within an industrial or operational environment. The word "command center" sounds like something from a war movie, but in practice it's usually just a web interface running on a local server with panels that refresh at configurable intervals. That's it. The complexity comes from what's behind the panels. The key components are the data ingestion layer, the visualization engine, and the command routing system. Data ingestion handles the polling or streaming of metrics from PLCs, SCADA systems, sensors, and sometimes external APIs. Visualization is the frontend rendering—charts, gauges, status lights, and alarm lists. Command routing takes any user input, like a toggle or a setpoint adjustment, and sends it to the right endpoint. These three pieces need to talk to each other without blocking, which is where most setups break down.
I'd recommend starting with the data source audit before you install anything. Map out every sensor, controller, and signal that needs to appear on the dashboard. List the protocol each one uses—Modbus TCP, OPC UA, MQTT, REST. Note the refresh rates. A dashboard that tries to poll a high-frequency vibration sensor at the same interval as a ambient temperature gauge will either lag or overwhelm the network. You'll want to separate high-frequency streams into their own polling cycles. I've seen installations stall because someone put a 100ms update rate on a 5-minute average without isolating the queries.
Setting Up the Backend Without Messing It Up
The backend is where patience pays off. You need a time-series database to handle incoming metrics efficiently. InfluxDB and TimescaleDB are the standard choices. I went with TimescaleDB for a site deployment because the PostgreSQL compatibility meant our existing query patterns didn't need rewriting. If you're working with legacy systems that export CSV dumps instead of live streams, you can still connect them using a lightweight ingest agent like Telegraf or a custom Python script that pushes to the database on schedule. One thing that trips people up is retention policy design. By default, most dashboards don't manage data cleanup. If you store every millisecond reading from every sensor forever, your database will grow until it chokes. Set retention policies at the bucket or table level. Keep raw high-resolution data for 72 hours, roll up to one-minute averages for 90 days, and daily aggregates for three years. This alone will determine whether your dashboard stays responsive or slows to a crawl after a few months. The API gateway sits between your frontend and your data layer. Don't skip this step. Without a gateway, your frontend is either exposing the database directly—which is a security risk—or making unstructured queries that vary wildly in load. A gateway like nginx or a lightweight Node.js proxy in front gives you rate limiting, authentication, and consistent endpoint routing. I've had clients skip this to save time and then spend two days debugging why a single dashboard refresh was hammering the database with forty simultaneous queries.
Get the Full Details
Building the Frontend Panels That Actually Work
Frontend frameworks like Grafana, Home Assistant, or custom React-based dashboards are the usual suspects. Grafana is the go-to for most industrial setups because it handles time-series visualization out of the box and connects directly to InfluxDB and TimescaleDB. Custom React dashboards give you more control but require significantly more development time. If you have a team that can commit to building and maintaining it, go custom. If you need something operational this week, Grafana is the practical choice. Panel design follows a simple rule that most people ignore: critical information should be readable in under three seconds. That means alarm states need color coding that's immediately distinguishable. Normal operating ranges should be visually quiet. Don't make every metric scream for attention or nothing gets noticed. I once reviewed a dashboard where twelve different gauges were using red, amber, and green simultaneously, all blinking, and none of them were actually alarming. The operator became desensitized within twenty minutes and started ignoring the whole thing. That's not a dashboard problem. That's a design problem. Use templated variables for things like station ID, zone, or shift. This lets you reuse the same panel layout across different production lines without duplicating work. Set default values and allow selection from a dropdown populated by your database queries. When done correctly, this cuts dashboard creation time for a new station from several hours to maybe twenty minutes.
Real Problems You Will Encounter
Here's a specific issue I ran into that I haven't seen documented well. I was configuring a dashboard for a packaging line where the conveyor motor temperature sensor and the servo drive status were both reporting through Modbus TCP to the same PLC. The dashboard showed normal readings for both until a weekend maintenance cycle. After the reset, the dashboard displayed stale data from before the shutdown. The PLC had rebooted and dropped its Modbus connection state, but the dashboard's last known values persisted because the frontend was caching responses without checking the sample timestamp against the current time window. The fix wasn't a dashboard setting. It was a backend query adjustment. I added a staleness check to the Prometheus-style rule that fed the panels—anything older than two minutes of elapsed time from the server clock got flagged as expired and blanked out instead of displaying a stale number. This is a nuance most dashboard guides skip because it depends on your specific data pipeline, not the visualization layer itself. But it matters. Seeing a temperature reading of 42 degrees from six hours ago because the sensor went offline isn't helpful. It's misleading. Another common failure point is alarm flooding. When a single root cause triggers cascading failures across multiple subsystems, your dashboard can light up with dozens of simultaneous alarms. Operators can't prioritize. I've seen this happen when a power fluctuation caused a compressor trip, which then backed up pressure across three downstream stations, each triggering its own high-pressure alarm. The dashboard showed seven critical alerts. The actual problem was one. I resolved this by implementing alarm suppression rules at the ingestion level—any alarm from a downstream station that falls within three minutes of the upstream trigger gets marked as dependent rather than independent. This doesn't eliminate the data. It just groups it logically.
What This Approach Doesn't Handle Well
A dashboard is only as reliable as its data sources. If a sensor fails, the dashboard won't tell you the sensor failed unless you explicitly build that diagnostic into the feed. I learned this the hard way when a pressure transducer on a hydraulic line stopped responding. The dashboard showed a flatline at zero, which looked identical to a legitimate zero-pressure state. We nearly shipped a product batch based on readings that were all technically "normal" but practically useless. The workaround was adding a delta-check rule that flags any sensor holding an identical value for longer than a configurable threshold as potentially stuck, and that flag gets displayed alongside the reading. Another limitation is real-time versus near-real-time confusion. Most dashboards operate on polling intervals of one to five seconds. That's fine for thermal and pressure monitoring. It's not fine for safety interlocks or emergency stop tracking. If your use case requires sub-second response visibility, a web dashboard is the wrong tool. You'd need a dedicated SCADA HMI or a real-time display system built on something like LabVIEW or a custom low-latency protocol. No amount of widget optimization fixes the fundamental round-trip delay between browser refresh and database query. Security is another area that gets underestimated. A command center dashboard often runs on the same network as your operational equipment. If it's exposed to the internet without proper isolation, it's an entry point. I've seen it happen. Use a VPN or a hardware firewall to restrict access. Authenticate every session. Rotate credentials on a schedule. These aren't optional because the people who skip them are the ones who hear about it through a support call at 3 AM.

Download and Deployment Notes
There isn't a single downloadable package that covers every use case. Most dashboard solutions are either open-source platforms you install yourself or commercial products with license models. Grafana Server is free and available from grafana.com. Home Assistant has a command center add-on ecosystem available through its official store. For custom builds, you'd assemble the stack from InfluxDB, TimescaleDB, Node-RED, or a React frontend depending on your requirements. If you're deploying in an industrial environment, budget time for network configuration. Dashboards don't fail because of software bugs half the time. They fail because someone plugged the monitoring server into the corporate VLAN instead of the OT network segment, or because a firewall rule blocked the database port after a routine security scan. Document your network topology before you start installing anything. It will save you days of troubleshooting later.
Where to Go From Here
Start small. Get one station, one data source, one panel working correctly before you expand. Test the stale-data behavior with a simulated sensor failure. Verify that alarm suppression logic actually groups related events the way you expect. Check the retention policies after a week to make sure they're doing what you thought they would. The dashboard will evolve as your understanding of what matters to the operators evolves. That's normal. The first version is rarely the final version, and that's not a flaw in the approach—it's just how these systems work.