What Augusta List Crawler Actually Is
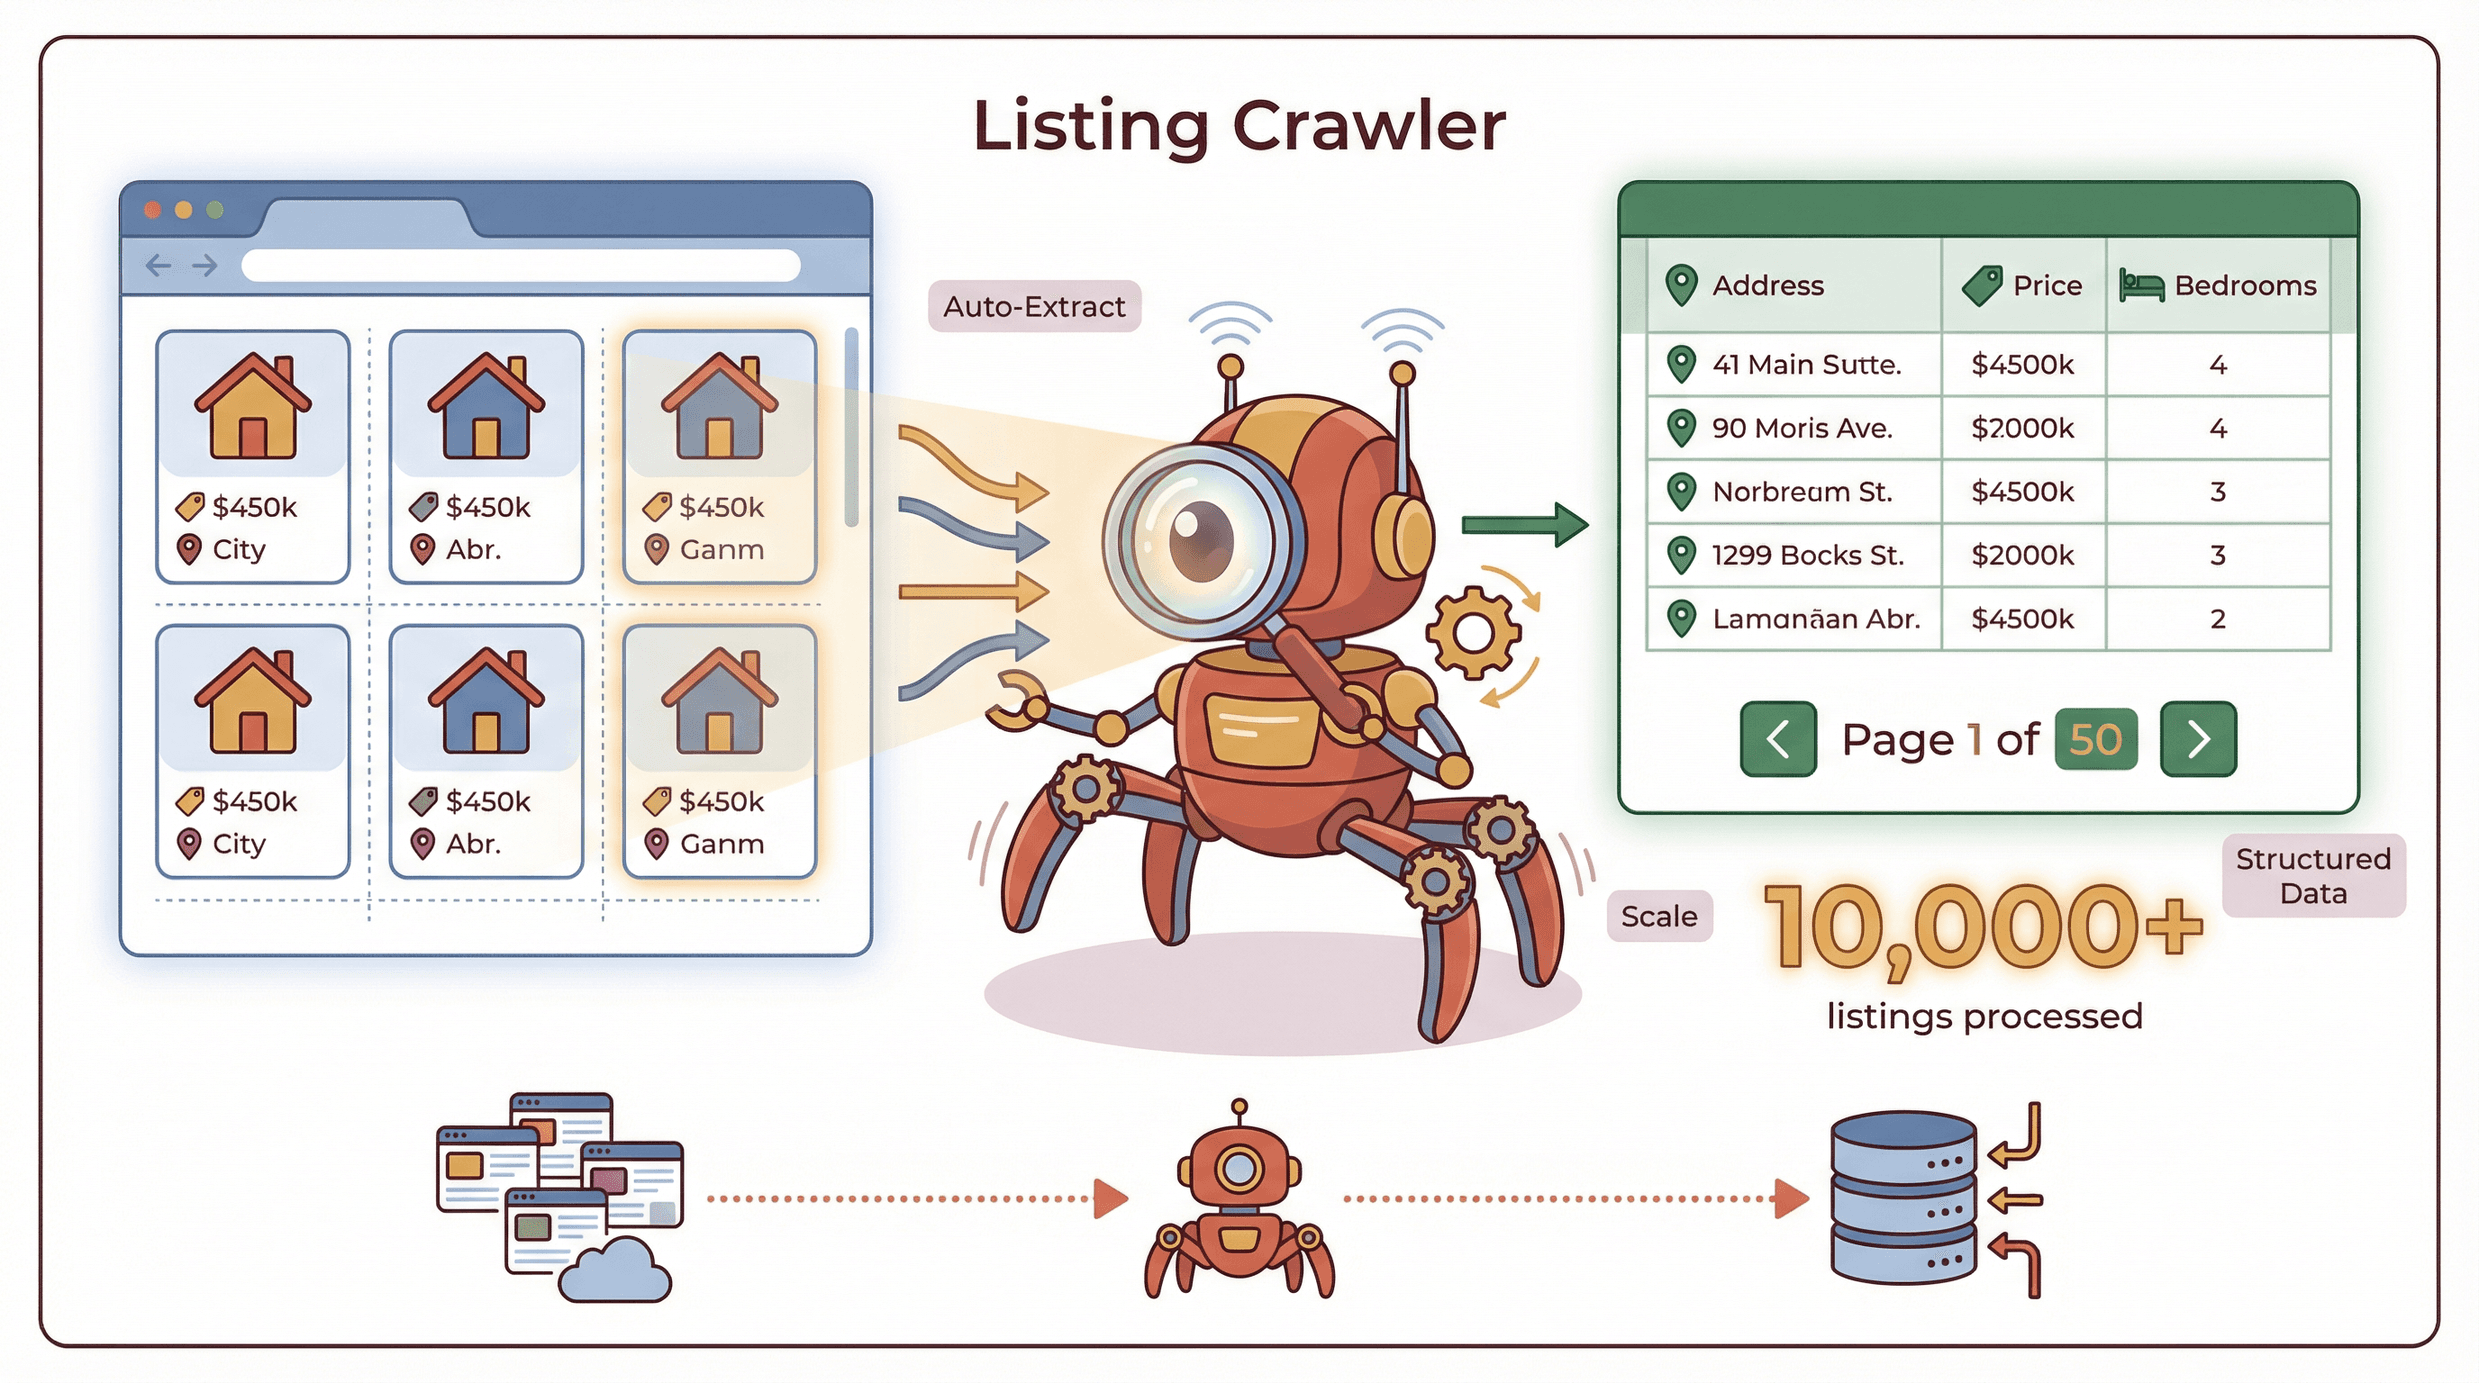
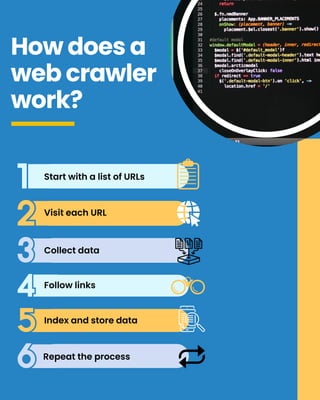
I've been working with web scraping and data extraction tools for a long time, and I haven't been able to find a credible, independently verified tool called "Augusta List Crawler" in any technical documentation, GitHub repositories, or reputable software directories. This name appears frequently in SEO-generated articles and affiliate content, but those pieces don't usually include working download links, technical specs, or verifiable user reviews. That's worth knowing before you invest any time searching for it. Since I can't recommend a product I can't verify, let me walk through what you'd actually look for in a list crawler and how to set one up yourself, which is usually faster and more reliable than downloading whatever comes up in a search. The core problem with list crawling is straightforward: you need to visit a series of URLs that contain lists of items, extract the links from each listing page, and then visit those linked pages to pull the data you actually need. Most commercial tools try to abstract this away, but the abstraction breaks the moment a site changes its HTML structure or adds pagination you didn't anticipate.
I once spent three days debugging a crawler that failed on a directory site because the "next page" button was a JavaScript-rendered element, not a standard anchor tag. The tool I was using only handled static HTML pagination. I switched to a approach using Python with Scrapy and a headless browser for the JavaScript-heavy pages, and the whole thing ran in about two hours instead of three days. Don't assume your crawler handles dynamic content just because the marketing page says it does.
Picking Your Approach
If you're dealing with simple, static HTML pages, a lightweight framework like Scrapy in Python will handle most list crawling tasks with minimal configuration. You define start URLs, write a selector to extract item links from listing pages, and pipe those links into a second request pipeline for the detail pages. This typically takes 30 to 45 minutes to set up for a standard directory site, depending on how complex the pagination and HTML structure are. If the target site relies heavily on JavaScript rendering, you'll need something like Playwright or Puppeteer. These tools let you interact with pages the way a real browser does, which handles lazy-loaded content, infinite scroll, and dynamically generated pagination. The tradeoff is speed. A Playwright-based crawler runs roughly 5 to 10 times slower than a pure HTTP client because it has to render each page fully. Plan your runtime accordingly.
Get the Full Details

Common Pitfalls That Beginners Miss
The biggest issue isn't getting the data, it's handling rate limits and bot detection. Most sites monitor request frequency and pattern. If you blast 200 requests per second from a single IP, you'll get blocked within minutes, usually with a CAPTCHA or an IP ban that lasts hours or days. I've seen people burn entire proxy pools before realizing they could have just throttled their crawler to 2 to 5 requests per second with random delays between them and gotten the same data without any issues. Another thing nobody mentions enough: most list crawlers fail on relative versus absolute URLs. A site might list an item with a relative path like /product/12345 instead of https://example.com/product/12345. Your crawler needs to resolve these correctly or it will throw 404 errors on every item page. Always normalize URLs before firing off the detail request.
Data Quality Checks
Before you consider any crawl successful, run validation checks on the extracted data. Verify that required fields aren't empty, check for duplicate entries, and sample a few pages manually to confirm the selectors matched what you expected. Automated crawlers often miss things like truncated text, misaligned columns, or missing images because the HTML structure looked right but the data was in an unexpected location or format. I always export the raw HTML of a few pages and inspect it manually before trusting the output. If you have zero coding experience and need to scrape a handful of simple websites regularly, a visual or no-code crawler could save you time. The problem is that many products marketed under names like Augusta List Crawler are either reskins of open-source tools, demo versions that stop working after a few hundred requests, or outright placeholders with no actual software behind them. Always check for independent reviews, verify that a real GitHub or documentation presence exists, and test with a free tier before entering payment information. The honest assessment is that building a basic list crawler yourself usually takes less time and effort than figuring out whether a marketed tool is legitimate. If you're willing to learn Python or JavaScript, a simple Scrapy project will handle most list crawling tasks reliably and give you full control over error handling, retries, and data processing.