Working With Evolutionary Data Is Messier Than Textbooks Make It Sound
When you actually sit down to analyze evolutionary relationships using phylogenetic methods, you quickly realize that the process is far from clean. I spent years building phylogenetic trees for marine invertebrates and learning the hard way that model selection, alignment quality, and bootstrapping thresholds can make or break your results. The Root Of All Life Unraveling The Mysteries Of Biological Evolution isn't just about reading papers and understanding natural selection. It's about getting your hands dirty with sequence data, figuring out why your maximum likelihood tree keeps collapsing, and learning which assumptions are actually holding your analysis together. At the center of this work is the idea that all living organisms share common ancestry and that the diversity we see today is the product of modification over deep time. That sounds simple enough until you're staring at a alignment of 400 mitochondrial sequences and trying to decide whether to use GTR+G+I or something simpler. Most people coming into this field learn the core concepts through textbooks first. They read about Darwin's finches and bacterial resistance and feel like they understand it. What nobody tells you is that actual evolutionary inference requires knowing when your data is lying to you. I worked on a project where we were trying to resolve relationships within a genus of deep-sea corals. The morphology was nearly identical across dozens of species. Everyone had assumed these were recent radiations with very little genetic divergence. We pulled COI and 16S sequences, ran the alignments through MAFFT, and checked for saturation. That's when things got interesting. The third codon position was completely saturated. Plugging that raw data into a phylogenetic model without filtering it produced a tree that looked almost random. I learned pretty quickly that checking for substitution saturation using Xia's test in DAMBE is not optional if you care about your topology.
Getting Your Alignment Right Actually Matters
A lot of beginners skip alignment refinement and just run their sequences through a builder program like RAxML or IQ-TREE and call it done. That habit will cost you. Bad alignments produce bad trees, and there is no amount of computational power that fixes a garbage alignment. I usually start with MAFFT for larger datasets because it handles indels reasonably well, then I go through and manually adjust problematic regions in AliView or Geneious. You spend more time on this step than anything else, but it is the step that determines whether your tree reflects biological reality or alignment artifacts. One specific edge case I ran into involved a set of ribosomal RNA genes with long variable regions. The default MAFFT settings produced a mess of gap-heavy columns that no tree program could handle sensibly. I switched to MAFFT with the L-INS-i option, which is slower but far more accurate for sequences with multiple conserved domains and irregular spacing. It took about four times longer to run, but the resulting alignment was dramatically cleaner. That tradeoff between speed and accuracy shows up repeatedly in this field, and you learn to pick your battles.
Model Selection Is Where People Make Mistakes
Model selection tools like ModelFinder in IQ-TREE or jModelTest are necessary, but they are not infallible. The problem is that these programs choose the best model for your data under certain criteria, and sometimes the best model is still wrong for your purposes. I once had a dataset where the selected model was GTR+G, but when I compared it against a simpler HKY+G model using a likelihood ratio test, the difference was negligible. The more complex model added parameters without improving the tree topology at all. I switched to HKY+G and the results were nearly identical but much faster to compute. That experience taught me to question the default model output rather than treating it as gospel. Another thing that trips people up is partitioning. If you are working with multi-gene datasets, running a single model across all partitions is usually a mistake. Partitioning by gene and codon position is standard practice, but overpartitioning can also cause problems. I worked with a transcriptome-derived dataset where I initially split every exon and intron into its own partition. The model became so parameter-heavy that the analysis would not converge. I collapsed the partitions back down to gene-level only and the tree stabilized within a reasonable timeframe. There is a middle ground between too few and too many partitions, and finding it takes trial and error.
Get the Full Details
Bootstrapping And Support Values Are Not What Beginners Think They Are
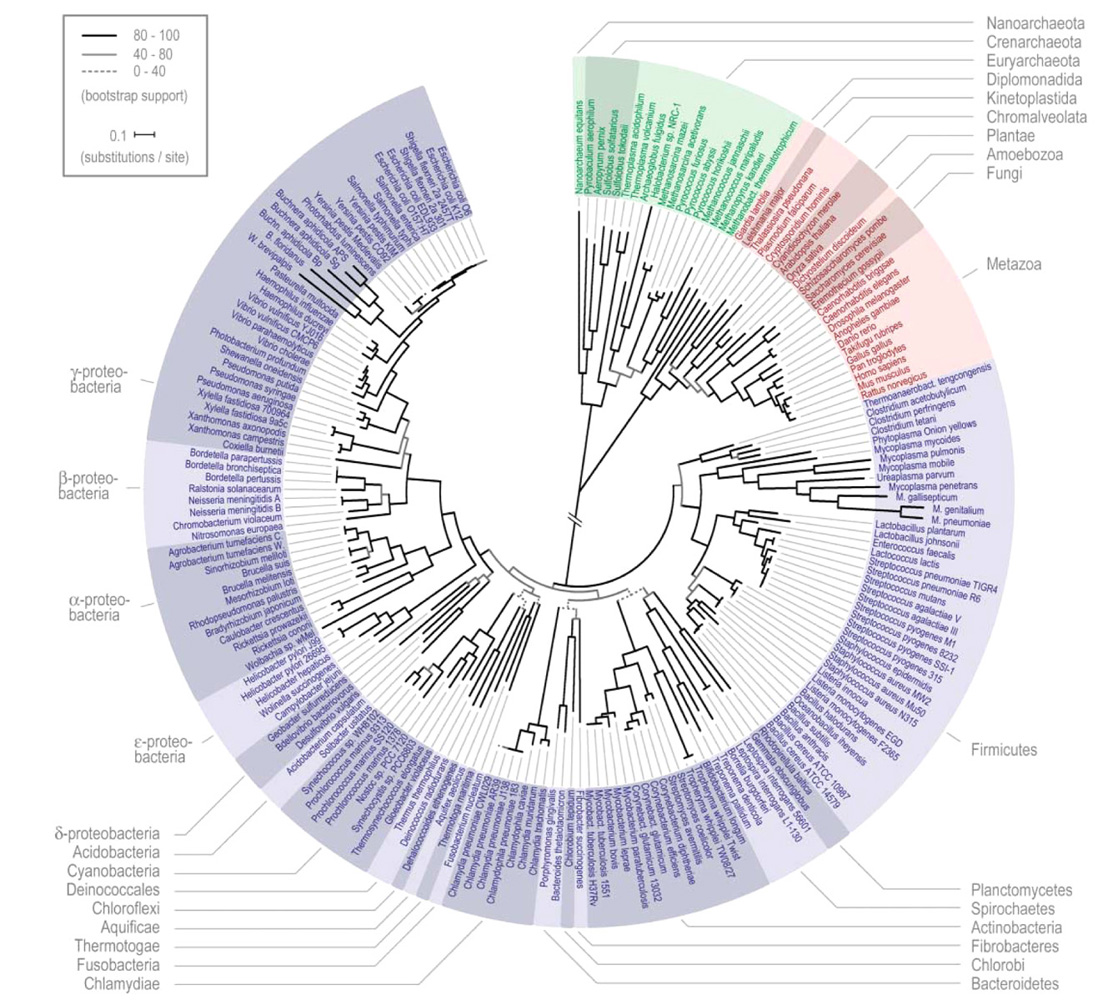
Bootstrap values tell you about repeatability under resampling, not about whether a clade is true. A bootstrap value of 95 does not mean there is a 95 percent chance that the clade is correct. This distinction matters more than most people realize. I have seen students treat low bootstrap support as proof that a relationship is uncertain and then build entire arguments around poorly supported nodes. The right response is usually to acknowledge the uncertainty and move on rather than overinterpreting weak signal. For most of my work I target at least 1000 bootstrap replicates. Some people run 10000 when computing time allows it. The improvement in stability beyond a certain point is marginal for most datasets. I also use SH-aLRT alongside bootstrap when using IQ-TREE because it gives a different kind of support estimate that can be useful for spotting problematic branches. When both methods agree, you can be reasonably confident. When they disagree, you need to look at the data more carefully before drawing conclusions.
Common Pitfalls That Wreck Phylogenetic Analyses
Long-branch attraction is the classic problem. When two unrelated lineages both accumulate many substitutions, they can appear artificially close to each other in a tree. I dealt with this directly when analyzing a dataset that included several fast-evolving parasitic species alongside slowly evolving outgroups. The parasites kept clustering together regardless of their known morphology. Switching to a site-heterogeneous model like CAT in PhyloBayes resolved the artifact. It took much longer to run, but the tree topology made biological sense afterward. If you are working with uneven evolutionary rates across your taxa, standard nucleotide models will mislead you. Contamination and misidentified sequences are another quiet killer of accurate phylogenies. I once found a nuclear mitochondrial pseudogene, commonly called a NUMT, hiding in what I thought was clean mitochondrial DNA. It had a stop codon and an insertion that broke the reading frame. I would have never spotted it without checking the translation. Now I always verify open reading frames for protein-coding genes before including them in an analysis. Even a small amount of contaminating sequence can shift branch lengths and topology in unexpected ways.
What Tools Actually Hold Up In Practice
IQ-TREE remains my go-to for most model-based phylogenetic analyses. It is fast, it includes ModelFinder, and it supports a wide range of substitution models including site-heterogeneous ones. For Bayesian inference I use MrBayes or PhyloBayes depending on the dataset. MrBayes is easier to set up and debug. PhyloBayes is more computationally intensive but handles certain kinds of heterogeneity better. For alignment, MAFFT is the default, though for very large datasets PRANK can be worth considering if indel modeling matters for your question. I also keep Mesquite and FigTree installed for visualization and tree manipulation, even though I mostly do figure preparation in R using ggtree. R is overkill for quick checks but essential when you need to compare multiple trees or annotate clades consistently across figures. Having a reproducible workflow in R scripts saves significant time when you are revising figures for publication or generating supplementary materials.
When Phylogenetics Fails You
Sometimes the data simply does not contain enough signal to resolve the relationships you care about. I have encountered datasets where every model and every method produced the same poorly supported polytomy. No amount of bootstrapping or model switching fixes that. In those cases, adding more loci or switching to genomic-scale data is usually the only real option. Another scenario where standard phylogenetic methods fall apart is when horizontal gene transfer is common, like in bacterial and archaeal datasets. A single gene tree does not represent the organismal history in those cases, and you need methods designed for reticulate evolution instead. If you are just starting out in this area, do not treat any single analysis as definitive. Run multiple methods, compare the results, check your assumptions explicitly, and report uncertainty honestly. The field rewards patience more than it rewards speed.