Getting Started With Neurofeedback Hardware and Software
The Rise Of Neurofeedback Training Unlocking The Secrets Of The Human Brain
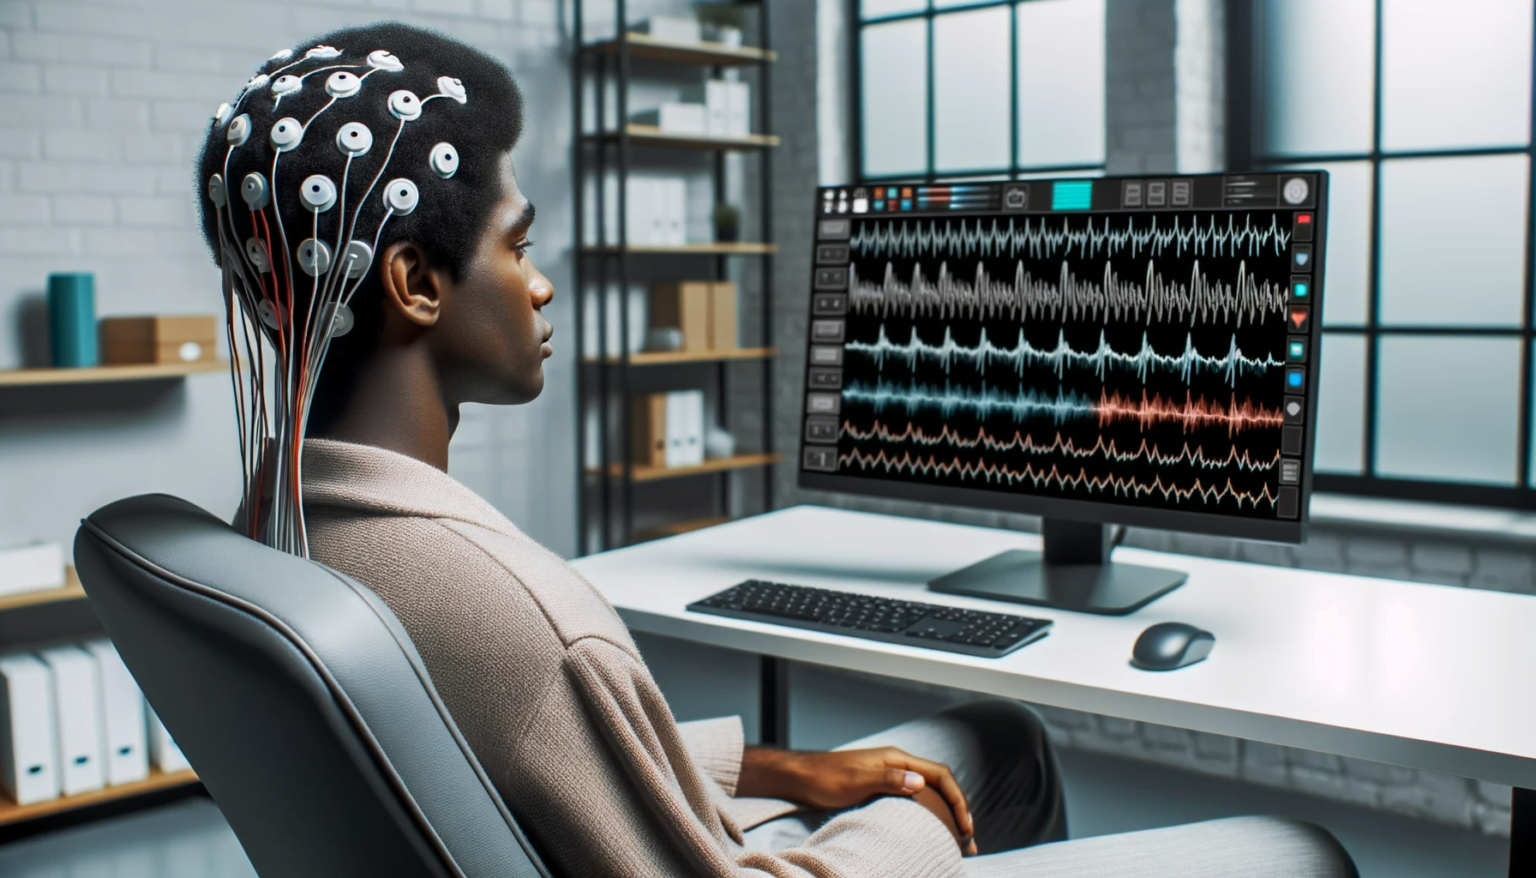
I've been running neurofeedback setups for years now, mostly with OpenBCI boards and some custom EEG caps, and the first thing people get wrong is the hardware assumption. You don't need a $5,000 clinical-grade system to get usable data. A $200 to $400 board like the OpenBCI Cyton or even the newer Daisy setup will give you raw EEG that you can actually work with. The problem isn't the equipment. It's understanding what you're recording and how to process it before you start training anyone. Raw EEG from consumer boards comes in as time-series data at sampling rates typically between 200Hz and 500Hz. That raw signal contains power line noise at 50Hz or 60Hz depending on your region, motion artifacts, eye blinks, and the actual brain waves you care about: delta below 4Hz, theta 4 to 8Hz, alpha 8 to 13Hz, beta 13 to 30Hz, and gamma above 30Hz. Most beginner tutorials skip straight to applying a bandpass filter and calling it done, but artifact removal is where everything falls apart if you don't handle it properly. I've seen people train alpha enhancement on subjects whose "alpha increases" were actually just eye-blink artifacts being misclassified because they skipped the ICA step entirely. Here's the practical workflow I use. Start with Python. Specifically, the MNE library for loading and filtering the data, and PyEEG or custom scripts using scipy for spectral analysis. Set up a basic pipeline that takes raw EEG, applies a 0.5 to 45Hz bandpass filter, notch filters out the power line frequency, then runs Independent Component Analysis to separate out blink and muscle artifacts. You can visually inspect the ICs in MNE and reject the ones that look like eye movement or jaw tension. This usually takes about 10 to 15 minutes per session for a 5-minute recording if you're doing it manually, which is the honest truth that nobody tells you. It's not automated magic.
For the actual training feedback loop, you want to keep the latency under 200 milliseconds or the subject won't connect the visual or auditory reward to their brain state. I use a combination of MNE for preprocessing and a Flask or FastAPI backend to stream the computed features to a simple web-based feedback interface. The feedback can be as simple as a bar that grows when alpha power increases or a sound that changes pitch based on theta suppression. The key is computing the feature fast enough. Power spectral density using Welch's method with a 2-second window and 50 percent overlap gives you updates roughly every second, which is plenty for most training protocols. If you try to update more frequently than that with short windows, your spectral resolution tanks and the feedback becomes jittery and useless. One thing that catches everyone off guard is electrode placement. The standard 10-20 system is what you should start with, specifically positions Pz for alpha measurement and Fz for frontal theta. Pz sits at the back of the head where alpha is most prominent, and Fz is useful for monitoring attention-related theta in the frontal midline. But here's the edge case that almost made me quit a project last year: I was running alpha neurofeedback with a client and the power readings at Pz were completely flat during relaxed eyes-closed periods. Normal alpha should jump to 8 to 13 microvolts in that state. The electrodes were fine. The amplifier was fine. The issue was a hair product buildup on the scalp that I hadn't noticed because the impedance readings were technically acceptable at 50k ohms, which most consumer systems consider fine. They're not. I cleaned the scalp properly with alcohol prep pads and lowered the impedance below 20k ohms, and the alpha signal immediately became robust. Impedance matters more than most guides admit, especially for the high-impedance passive electrodes that come with most DIY kits. When it comes to actually designing a training protocol, most people follow what's called the standard alpha-theta protocol popularized by the Monastery Program, or a simple beta training protocol for attention. The alpha-theta protocol involves lowering the alpha threshold initially to get the subject into a relaxed state, then slowly introducing theta rewards and raising the alpha threshold over multiple sessions. It typically takes 20 to 40 sessions for noticeable changes. Beta training for ADHD-type symptoms usually targets 12 to 15Hz suppression or 15 to 18Hz enhancement depending on whether you're trying to reduce distractibility or improve focus. The research on these protocols is mixed at best, and I want to be straightforward about that. A lot of the published positive results come from small samples with poor controls. The meta-analyses show modest effects at best, and the effect sizes shrink considerably when you account for placebo and expectation bias.
Despite that, the practical application works if you manage expectations correctly. Here's what I've found through hands-on use: neurofeedback can produce measurable shifts in subjective relaxation and focus for many people, but it's not a treatment for clinical conditions. It doesn't cure ADHD, PTSD, or anxiety disorders in the way that pharmaceutical interventions or structured psychotherapy does. What it does is train self-regulation of brain activity, which is a skill that transfers imperfectly to daily life. Most subjects need ongoing booster sessions, and without them the gains tend to fade within weeks or months depending on the protocol and individual differences. For software that handles the heavy lifting, the most reliable open-source option is the OpenViBE platform. It has a visual designer where you can build signal processing blocks, classifiers, and feedback presentation without writing much code. It's not the most elegant tool, and the learning curve is steep, but it's stable and well-documented. If you're comfortable coding, building your own pipeline in Python gives you more control and is easier to customize for specific protocols. The trade-off is development time. Expect to spend several weeks on a working prototype before it's reliable enough for actual training sessions. Another common pitfall is ignoring baseline measurements. You need at least 3 to 5 minutes of eyes-closed resting EEG before you start any training to establish each subject's individual alpha peak frequency. This varies significantly between people. Some subjects peak at 9Hz, others at 12Hz. If you train everyone at the same frequency band regardless of their individual peak, you're essentially guessing and the results will be inconsistent. I calculate the individual alpha frequency by finding the peak in the power spectral density during the resting baseline and then set the training band to center around that frequency with a 1 to 2Hz bandwidth. This simple adjustment alone improved my training consistency noticeably across subjects.
Get the Full Details

Storage and data management also deserve attention. A single 30-minute session at 500Hz with 16 channels generates roughly 1.4GB of raw data in continuous recording mode. You don't need continuous storage. Downsample to 250Hz after initial filtering and store the downsampled data, which cuts it to about 700MB per session. Compress with a lossless format or store as binary float32 to keep the file size reasonable. Use a naming convention that includes the date, subject ID, session number, and protocol type. When you're looking back at six months of data trying to figure out why a certain protocol stopped working, you will be grateful for any system you put in place early on. The hardware side has gotten dramatically cheaper over the last few years. The OpenBCI boards are the most mature option in the DIY space, but there are newer entrants like the Muse 2 and the Emotiv EPOC+ that offer consumer-friendly setups at lower cost, though their signal quality and flexibility are more limited. If you're serious about getting actual training data rather than novelty entertainment value, stick with a proper dry or wet electrode system that gives you access to raw voltage data rather than preprocessed band power values. Preprocessed outputs lock you into the manufacturer's interpretation of what the signals mean, and you lose the ability to do your own artifact handling and spectral analysis. Documentation is sparse for most of these DIY setups. The OpenBCI documentation covers basic setup and example code, but it doesn't go into the details of building a real training protocol. You'll spend a lot of time reading research papers to understand what parameters actually matter, cross-referencing with the API documentation, and debugging why your feedback latency is too high. The community forums and GitHub issues are where most of the practical knowledge lives, and it's fragmented. Nothing consolidates the information well.
If you're considering this for a clinical or therapeutic context, you need to understand the regulatory landscape. In the United States, the FDA classifies neurofeedback devices as medical devices and requires clearance for claims about treating medical conditions. Using neurofeedback for research or personal use is a different matter, but distributing it or making therapeutic claims crosses into regulated territory. The European Medicines Agency has similar requirements. This isn't a side note. It's the boundary between a hobby project and something that can cause real harm if someone delays proper treatment because they believe unverified claims. The honest summary is that neurofeedback is a real technology with genuine mechanisms, but it's not the breakthrough solution that marketing materials suggest. It works for some people, in some contexts, with measurable but modest effects. The barrier to entry has dropped significantly, which means more people are experimenting with it, but also means more poorly designed protocols floating around online. If you're building your own setup, focus on clean data, proper artifact handling, individualized baselines, and realistic expectations. The rest follows from there.