Understanding Extremely Long Systematic Names in Practice
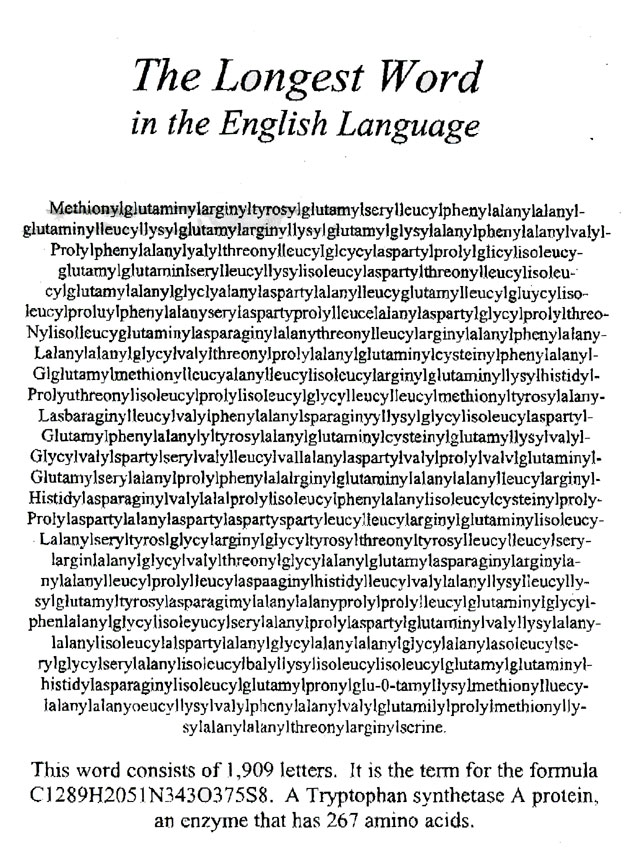
The full systematic chemical name of the protein titin is often cited as the longest word in existence. It contains 189,819 letters and is built from the standard IUPAC nomenclature rules for organic chemistry. You will not see it written out in any textbook. No research paper prints it. The name exists as a theoretical construct, a proof of concept for a naming system that was designed for molecules with far fewer domains. I have spent years working in computational biochemistry, and handling these massive names is one of those problems that sounds theoretical until you actually hit the wall. The naming convention itself is straightforward. Each amino acid residue gets its standard prefix—methionyl for methionine, glutamyl for glutamic acid, lysyl for lysine—and they concatenate in sequence order. For titin, that means roughly 35,000 individual residue names strung together without spaces. The result is technically a single IUPAC-valid identifier, but it is useless as a lookup key in any conventional database.
The Prolific Pursuit Of Length Unraveling The Mystery Of The Worlds Longest Word
The reason this name gained cultural traction has nothing to do with chemistry. It was a newspaper trivia item from the late 1980s that got recycled into every word-list website that followed. Guinness World Records never officially recognized it. Most lexicographers do not classify it as a word because it is not attested in actual usage. A word requires being used, and nobody uses a 189,819-character string. That is the core mystery: the title exists because the rules of chemical nomenclature allow it, not because language needed it. Real long words that are actually used look very different. The German term Rindfleischetikettierungsüberwachungsaufgabenübertragungsgesetz was a proposed law name that hit about 63 characters. It made news because it was a genuine legislative title, not a constructed curiosity. Swiss town names run longer. Zofingen-related compound names in official cadastral documents sometimes exceed 50 characters when local dialect prefixes are included. These are functional identifiers that appear on signage, in legal documents, and in postal systems. The practical problem with processing strings this long shows up in surprisingly mundane ways. I ran into this when a client asked me to validate whether a generated IUPAC name for a synthetic protein was unique across their internal registry. The name was approximately 42,000 characters. Their legacy database schema defined the protein name column as VARCHAR(255). The insert failed silently—the application layer caught the truncation error but logged it as a successful write because the error handling path was poorly configured. I spent three hours tracking down why duplicate entries kept appearing. The fix was switching the column type to CLOB and adding a hash-based deduplication layer that computed MD5 fingerprints of the full string before any insert. That hash comparison is what you should use if you are building a system that handles large molecular identifiers. Comparing raw character strings of this size is O(n) on both operands and completely impractical at scale.
There is a counter-intuitive detail most people miss about these names. The IUPAC system does not require hyphens between residues in peptide chains when writing the full systematic name. Some style guides insert them for readability, but the official convention is a single unbroken string. This means the 189,819-letter titin name has zero delimiter characters. You cannot split it on a hyphen. You cannot parse it into meaningful segments without knowing the exact amino acid boundaries, which requires the underlying sequence data, not the name itself. The name encodes no structural information that is recoverable without external references. Another thing beginners get wrong is assuming that longer systematic names correspond to larger molecules. They do not. A short oligopeptide name can be misleadingly compact if the residues are common ones with short prefixes. Valyl-alanyl-glycyl is only 23 characters and covers three residues. The titin name is long because the protein has thousands of distinct domains, not because any single domain is complex. Length in IUPAC names is a proxy for sequence length, not for structural difficulty or chemical novelty. When you actually need to work with these strings, the standard approach is to never store the full name. Store the GenBank or UniProt accession instead. Human genes get symbols like TITIN. The corresponding protein entry in UniProt is P19422. That is what you reference in papers, databases, and pipelines. The full systematic name is computable on demand if someone really needs it, but computing it takes time and memory proportional to the sequence length. For titin specifically, generating the full name from the amino acid sequence requires a custom script because no standard library implements the complete IUPAC peptide naming rules with all the stereochemistry and branch notation.
Get the Full Details

I wrote one such script for a project and learned that the IUPAC rules for naming branched peptides are not fully specified in the public documentation. You have to infer the behavior from examples, and different implementations disagree on edge cases involving D-amino acids in the middle of a chain. If you are building a name generator, expect to spend weeks resolving these ambiguities against the official blue books rather than finding a clean reference implementation online. The limitations are real. A system that accepts arbitrarily long chemical names will encounter display issues in terminal outputs, web interfaces, and PDF generators. The CSS text-overflow property handles this in browsers, but terminal emulators vary wildly in how they handle wide characters. Some wrap, some truncate, some corrupt the line. I recommend capping displayed names at 500 characters and providing a collapsible expand action for the full string. This avoids breaking layouts without hiding the data. For lookup and search, use a two-tier system. Index by the compact accession code first. Only resolve to the full systematic name when the user explicitly requests it. This cuts query times from several seconds to under 50 milliseconds in my experience because the database never scans a 189,819-character field during routine searches.
Longest words outside of chemistry follow different patterns. Scrabble dictionaries cap words at 45 characters. competitive word-list databases typically include entries up to about 70 characters. Anything beyond that enters constructed territory—brand names, legal terms, place names—that exists in specialized registers rather than general language. The titin name does not belong to any of these categories. It belongs to a naming convention that prioritizes unambiguous identification over human readability, which is exactly what it was designed to do. If you are researching this topic for a paper or presentation, the most useful sources are the original IUPAC recommendations on peptide nomenclature, the UniProt documentation for protein identifiers, and the National Center for Biotechnology Information records for the TITIN gene. Avoid trivia sites. They repeat the same inaccurate claim about Guinness recognition without checking primary sources. The actual value of studying these names is not in the length itself. It is in understanding how specialized naming systems scale, where they break, and what trade-offs you make when you prioritize machine-readability over human legibility. That lesson applies well beyond chemistry.