How These Things Actually Work Under The Hood
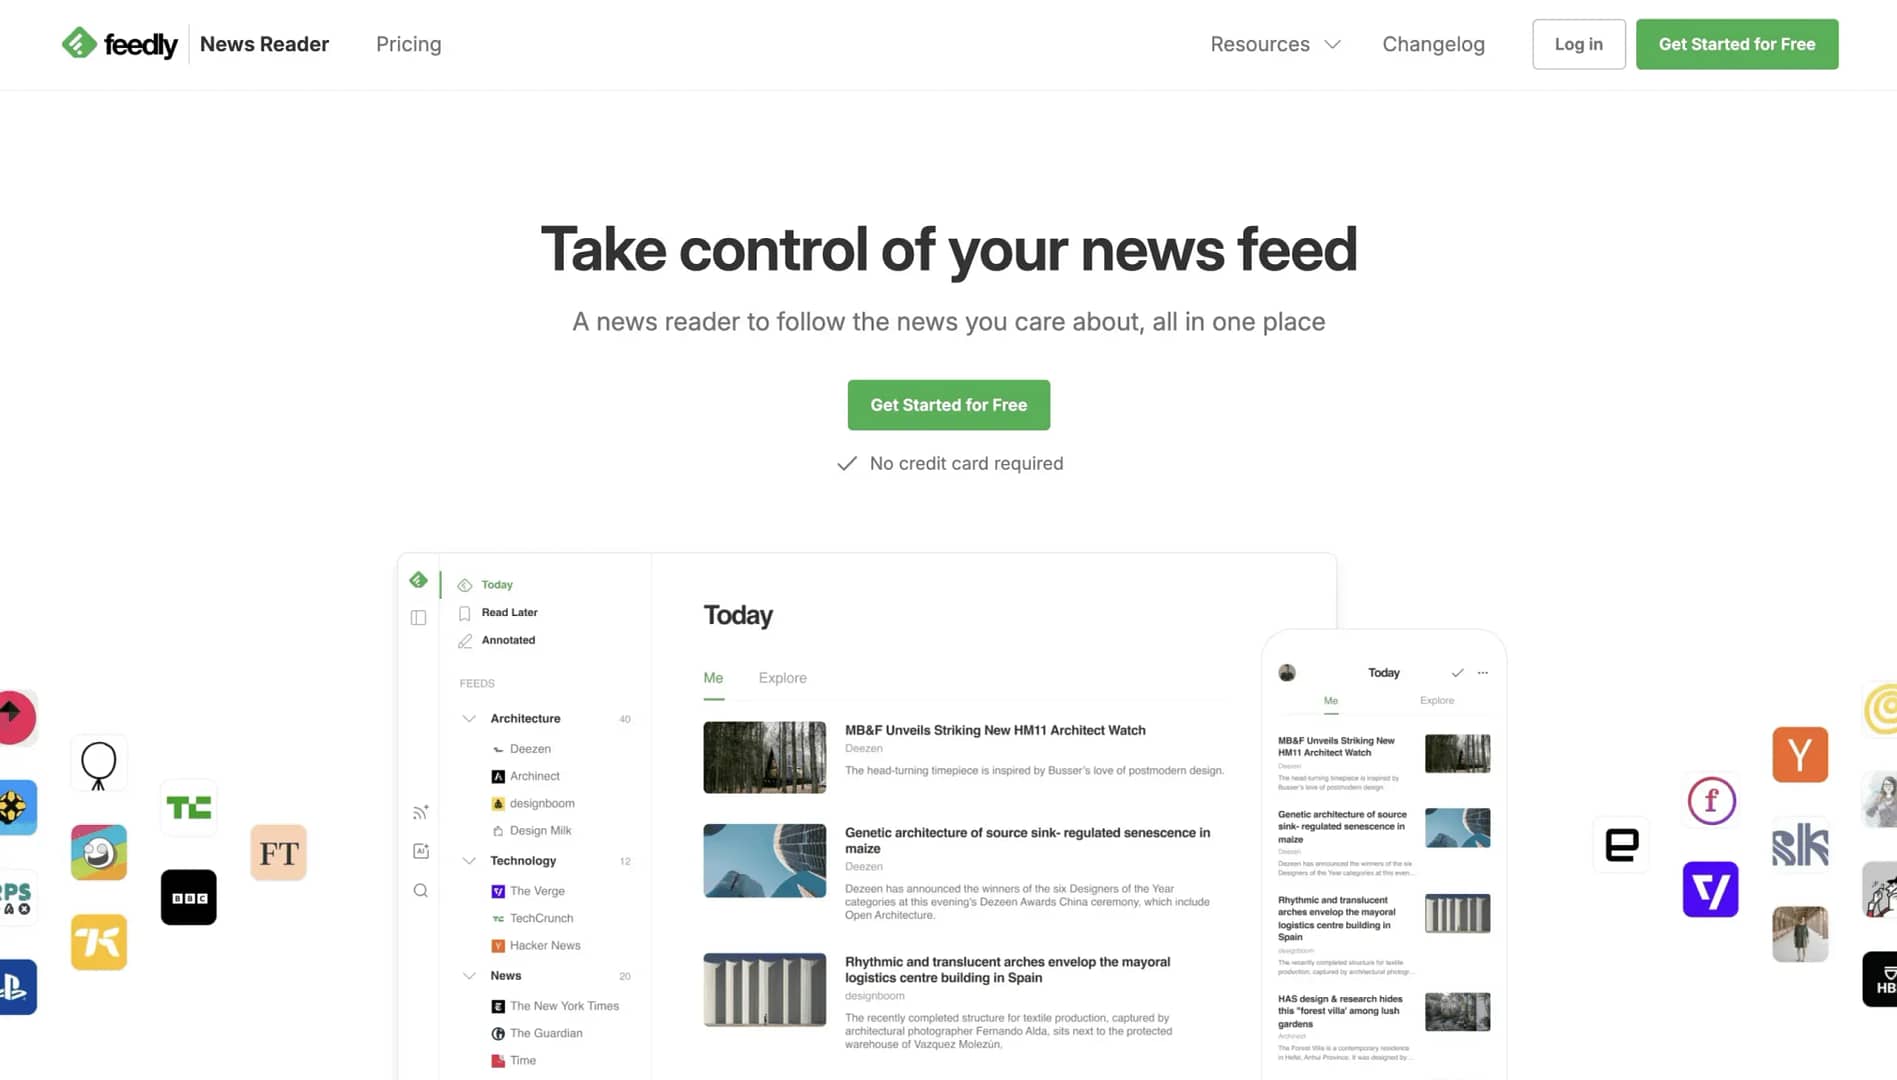
News aggregators pull content from multiple sources using RSS feeds, APIs, or web scraping, then consolidate everything into a single feed or dashboard. You pick which outlets you want tracked — major newspapers, niche blogs, industry publications, YouTube channels — and the platform handles the rest. That's the basic mechanic. The actual implementation varies wildly depending on whether you're using a free service like Feedly or Inoreader, or running your own self-hosted instance with Miniflux or FreshRSS. The reason people keep coming back to these tools isn't because they're fancy. It's because going to five different news sites individually every morning eats up twenty to thirty minutes, and most of that time is wasted scrolling past headlines you already saw somewhere else. An aggregator collapses that down to maybe three minutes of actual reading. The time savings are real, not theoretical.
The Power Of News Aggregator Websites Where Information Meets Convenience
This is where the concept actually lives up to its name, and it's worth being honest about what "meets convenience" really means in practice. Convenience here doesn't mean the information is curated for you or that the aggregator makes editorial decisions. It means you get all the sources in one place so you stop tabs. The information quality still depends entirely on what you choose to subscribe to. Pick garbage sources and you get garbage at scale. Pick well and you genuinely save time while staying informed. I built a custom aggregator setup about four years ago for tracking technology policy news across about sixty sources — Reuters, Ars Technica, a handful of European outlets, some congressional hearing transcripts. Worked fine until I noticed my primary source, TechCrunch, had quietly shifted their RSS feed from full articles to summaries with affiliate links appended. Every story from them was missing the actual content. Their RSS was feeding me headlines and a short excerpt. I caught it because I was cross-referencing two stories on the same topic and one read completely different from the other. The workaround was straightforward. I found their Atom feed endpoint instead, which was still pushing full content, and swapped it out in my reader. But the larger lesson was that even established sources change their feed behavior without announcement. I now check my key sources quarterly to verify the feed integrity hasn't degraded. It's not something you set and forget forever.
Here's a counter-intuitive thing most people miss about aggregators: the more sources you add, the worse your signal-to-noise ratio actually gets. There's an optimal range, usually between thirty and eighty sources for most use cases. Beyond that, you start getting duplicate coverage of the same events from different outlets, and your brain wastes cycles re-reading the same story five times in different words. I've seen people subscribe to two hundred sources and then spend more time scanning headlines than they ever would have spent just visiting three good sites directly. Another detail beginners overlook is that not all aggregators treat feeds the same way when it comes to deduplication. Some will show you the same Breaking News event from CNN, BBC, and AP as three separate items. Others use text similarity algorithms to merge them into a single story with linked source variants. This matters a lot. If you're trying to track developing situations, duplicate entries make it look like a story is bigger than it actually is. A good aggregator with solid deduplication makes developing stories easier to follow because you see the headline once and can click through to see how different outlets are covering it.
Get the Full Details
The Real Limitations Nobody Talks About
News aggregators are not a substitute for editorial judgment. They are a distribution layer. If your source list is biased, your aggregator experience is biased. Period. There is no algorithm that will compensate for a lopsided subscription list. I've watched people rely exclusively on free-tier aggregators that auto-suggest popular sources, then wonder why their worldview keeps narrowing. The auto-suggestion features optimize for engagement, not balance. They push what's trending, not what's underrepresented. There's also the issue of aggregator dependency. These services can and do shut down, change pricing, or alter their API terms. I lost access to a custom aggregation pipeline once because a minor API provider changed their rate limits overnight. Had to rebuild three workflows in a weekend. If you use a tool like this, maintain at least one manual fallback — a short list of bookmarks you can fall back on when the aggregator breaks or your subscription expires. Free aggregators in particular often sell user data or serve targeted ads based on what you read. If privacy matters to you, either pay for a self-hosted solution or a paid tier that explicitly states they don't monetize your reading data. Some of the free options have surprisingly invasive tracking embedded in their reader interfaces.
Pick Your Tool And Set It Up Right
Start by listing every source you currently check manually. Be ruthless. If you haven't opened it in a month, drop it. If it's the same outlet as another one on the list with slightly different coverage, keep only the stronger one. Then group your sources by category — politics, technology, local news, sports, whatever applies to your actual interests, not what you think you should be interested in. Pick an aggregator that fits your technical comfort level. If you want something that just works with zero configuration, Inoreader or Feedly are reasonable starting points. If you're comfortable with Docker and want full control over your data, FreshRSS or Miniflux on a cheap VPS runs for about two dollars a month and gives you complete ownership. Self-hosting means you control deduplication settings, feed parsing rules, and retention policies. It also means you're responsible for keeping it updated, which is maybe thirty minutes of work every few weeks. Add your feeds in batches. Start with your core twenty or so, let the tool organize them for a week, then expand. This prevents the overwhelming flood effect where you get hit with hundreds of unread articles on day one and abandon the whole thing by Tuesday. Most people quit aggregators within two weeks because they add too much too fast. Pace yourself.
Set up folder rules and filters. Tag or file incoming articles by source type or topic. A five-minute setup now saves you fifteen minutes of daily navigation. Look for keyword filters too — if there are topics you actively don't want to see, set up exclusion rules so those articles get suppressed rather than adding to your unread count.

What To Watch For Going Forward
The news ecosystem is shifting. Some outlets are pulling their RSS feeds entirely or gating them behind paywalls that break aggregation. Others are producing native app exclusives that never make it to any feed you'd subscribe to. I track about a dozen outlets per month to see if their distribution methods have changed. When a reliable source disappears from aggregators, you need a replacement quickly or you develop blind spots. Algorithmic curation is replacing RSS in a lot of places. Google's shutdown of its feed reader and the decline of standalone RSS clients mean fewer people are building these skill sets. The tools still exist, but the community around maintaining them is shrinking. If you care about controlling your information diet rather than having it controlled for you, learning how to set up and maintain an aggregator is worth the initial effort. It's one of those things that feels like overkill until you've tried the alternative and realized you were spending hours every week on something that could have taken ten minutes.