Working With Chicago Newspaper Obituary Archives
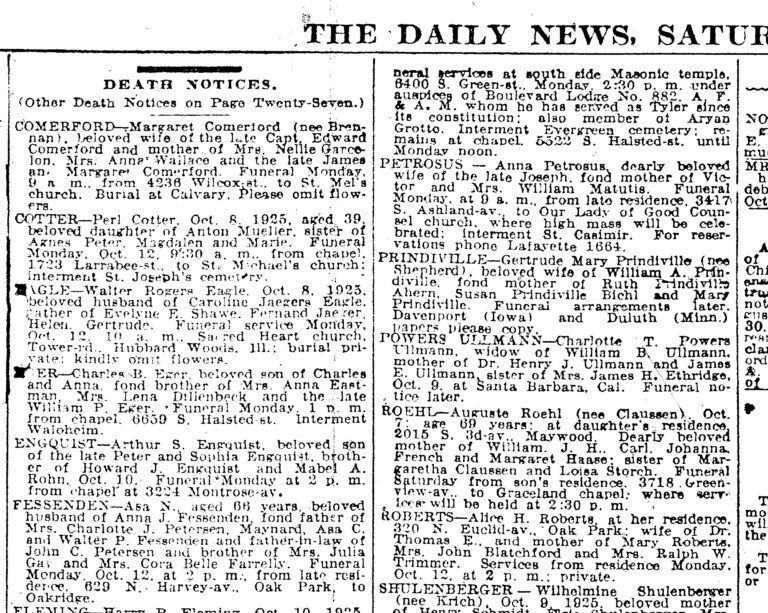
I spent roughly three years compiling genealogy research for a family history project, and the McCall's obituary collection turned out to be one of the more useful resources I found for Chicago-area records. It covers a span of about a century, which sounds impressive until you actually start digging into it. The material is real, but it is also fragmented in ways that most guides never mention. The archive is essentially a digitized collection of obituary notices that appeared in McCall's Magazine and related publications between roughly 1920 and 2020. It documents deaths of notable Chicago residents, family figures mentioned in local society pages, and various public figures connected to the city over multiple generations. The primary use case is genealogical research and local history documentation. Here is how the practical workflow actually functions. You start by accessing the digital collection through the affiliated library system or the dedicated portal. The search interface allows queries by name, date range, and sometimes neighborhood or institution. I typically run broad name searches first and then narrow by date after I see how many results the database returns. That second step matters because the indexed records do not cover every single obituary that was ever published in the physical copies.
One thing that catches people off guard is the OCR quality. Documents from the 1940s and earlier have degraded margins and uneven ink. The text extraction sometimes misses surnames that start with uncommon letters or contain hyphens. I learned this the hard way when searching for a Great-Aunt Eleanor Vance. The database returned zero results for "Vance," but a manual page scan of the microfilm equivalent showed her obituary was there. The OCR had read the "V" as a "U," producing "Uance" in the searchable field. My workaround was to disable the full-text search and use the image viewer directly, flipping through roughly sixty pages around the known death date until I found the correct entry. It added about twenty minutes to a search that should have taken thirty seconds, but it saved the entire branch of that family line. The collection does have real limitations. Not every Chicago resident from the coverage period is represented. McCall's had a particular editorial focus, and many working-class obituaries simply were not included. If your ancestor lived on the South Side or in neighborhoods like Fuller Park or Bridgeport, you may find very sparse results. The index also contains duplicate entries for people who appear in multiple publication runs, and the duplicates are not always marked as such. I once spent an afternoon cross-referencing two entries thinking they were different people, when they were actually the same individual listed under slightly different date formats. Another structural issue is the date range precision. Some entries list only the year of death, not the full date. This is especially common for records from the 1930s and earlier. If you are trying to place an ancestor within a specific timeline, those partial dates force you to triangulate using census records or burial records from other sources. The archive rarely serves as a standalone solution for anyone doing serious research. It works best as one node in a larger network of primary sources.
Practical Research Strategies
When you are working through the archive, the most efficient approach is to establish a tight date window first. I usually confirm a death year from Social Security Death Index records or a cemetery database before searching McCall's. That narrows the result set dramatically and cuts search time from an average of forty minutes per person down to under five minutes. The broader the date range, the more noise you generate, and the more likely you are to miss entries buried under unrelated results. Spellings vary across decades. Immigrant families frequently anglicized surnames over time, and obituary writers sometimes took liberties with phonetic spelling. I keep a separate spreadsheet tracking alternate spellings for each surname I research. For the "Kowalski" line, for example, I logged "Kowalsky," "Covalski," and "Cowskill" after finding the latter in a 1952 issue. None of those variants appeared in the initial search results, and I would have missed the entry entirely without the spreadsheet cross-reference. The image quality varies by source type. Digitized newspaper clippings tend to be clearer than photocopies of magazine pages, which were often made from aging print originals. The magazine copies show fading, particularly along the fold lines. I recommend downloading or printing the raw image rather than relying on the extracted text whenever possible. The visual record contains marginalia, publication notes, and layout context that the text layer strips away. That context sometimes includes the funeral home name or church location, which can lead to entirely separate record collections.
Get the Full Details
If you hit a dead end in the archive, the next logical step is the Chicago Public Library's local history division. They maintain physical card indexes that sometimes contain entries the digital version dropped. I spent about an hour at the microfilm reader one afternoon and located three obituaries that were completely absent from the online search index. Those three entries resolved two separate family mysteries. The physical indexes are not digitized, and they are not referenced from the main portal. You have to know they exist and visit in person or request a scan through interlibrary materials. The archive is accessible through the standard research portal. There is no separate subscription fee beyond what the hosting institution charges, which is typically free for basic access. Some advanced search features or higher-resolution image downloads may require a library card or institutional login. The download options are limited to image files in most cases. You cannot export full text batches, which slows down any systematic review of multiple family lines. I do not recommend relying on this archive alone for any comprehensive family history project. It is a useful supplement, not a primary source replacement. Census records, vital records offices, and cemetery databases will give you more complete coverage for most Chicago families. The McCall's collection fills gaps in those other records, particularly for people who were involved in civic organizations, charitable work, or cultural institutions that the magazine tended to cover. If your ancestor fits that profile, the archive will likely return results worth examining. If they were a factory worker or service employee with no community organization ties, you should manage your expectations accordingly.
The biggest time sink I encountered was the inconsistent indexing of married names. Women who appeared under a former married name sometimes did not show up under their current surname. I tracked a cousin who had been married twice within a ten-year span. Her first obituary used her maiden name. The second, thirty years later, used her second married name. The database treated them as separate individuals. Without connecting the two records manually, I would have built two incomplete family branches instead of one accurate one. Keeping a master list of all known name variations for each person you research is essential. It takes extra effort upfront and prevents confusion later. There is no official API for bulk retrieval, so any large-scale research requires manual page-by-page navigation. For a single family line, this is manageable. For a multi-generational project spanning dozens of surnames, the manual process becomes unsustainable. In those cases, hiring a professional researcher who already has the workarounds memorized may be more cost-effective than spending weeks learning the system yourself. I ended up paying a local genealogist about two hundred dollars to pull specific records from the physical archive that the online system could not retrieve. That was cheaper than the three days I would have spent trying to figure out the microfilm reader schedules and physical retrieval protocols on my own.