What Most People Get Wrong About Autosomal Testing
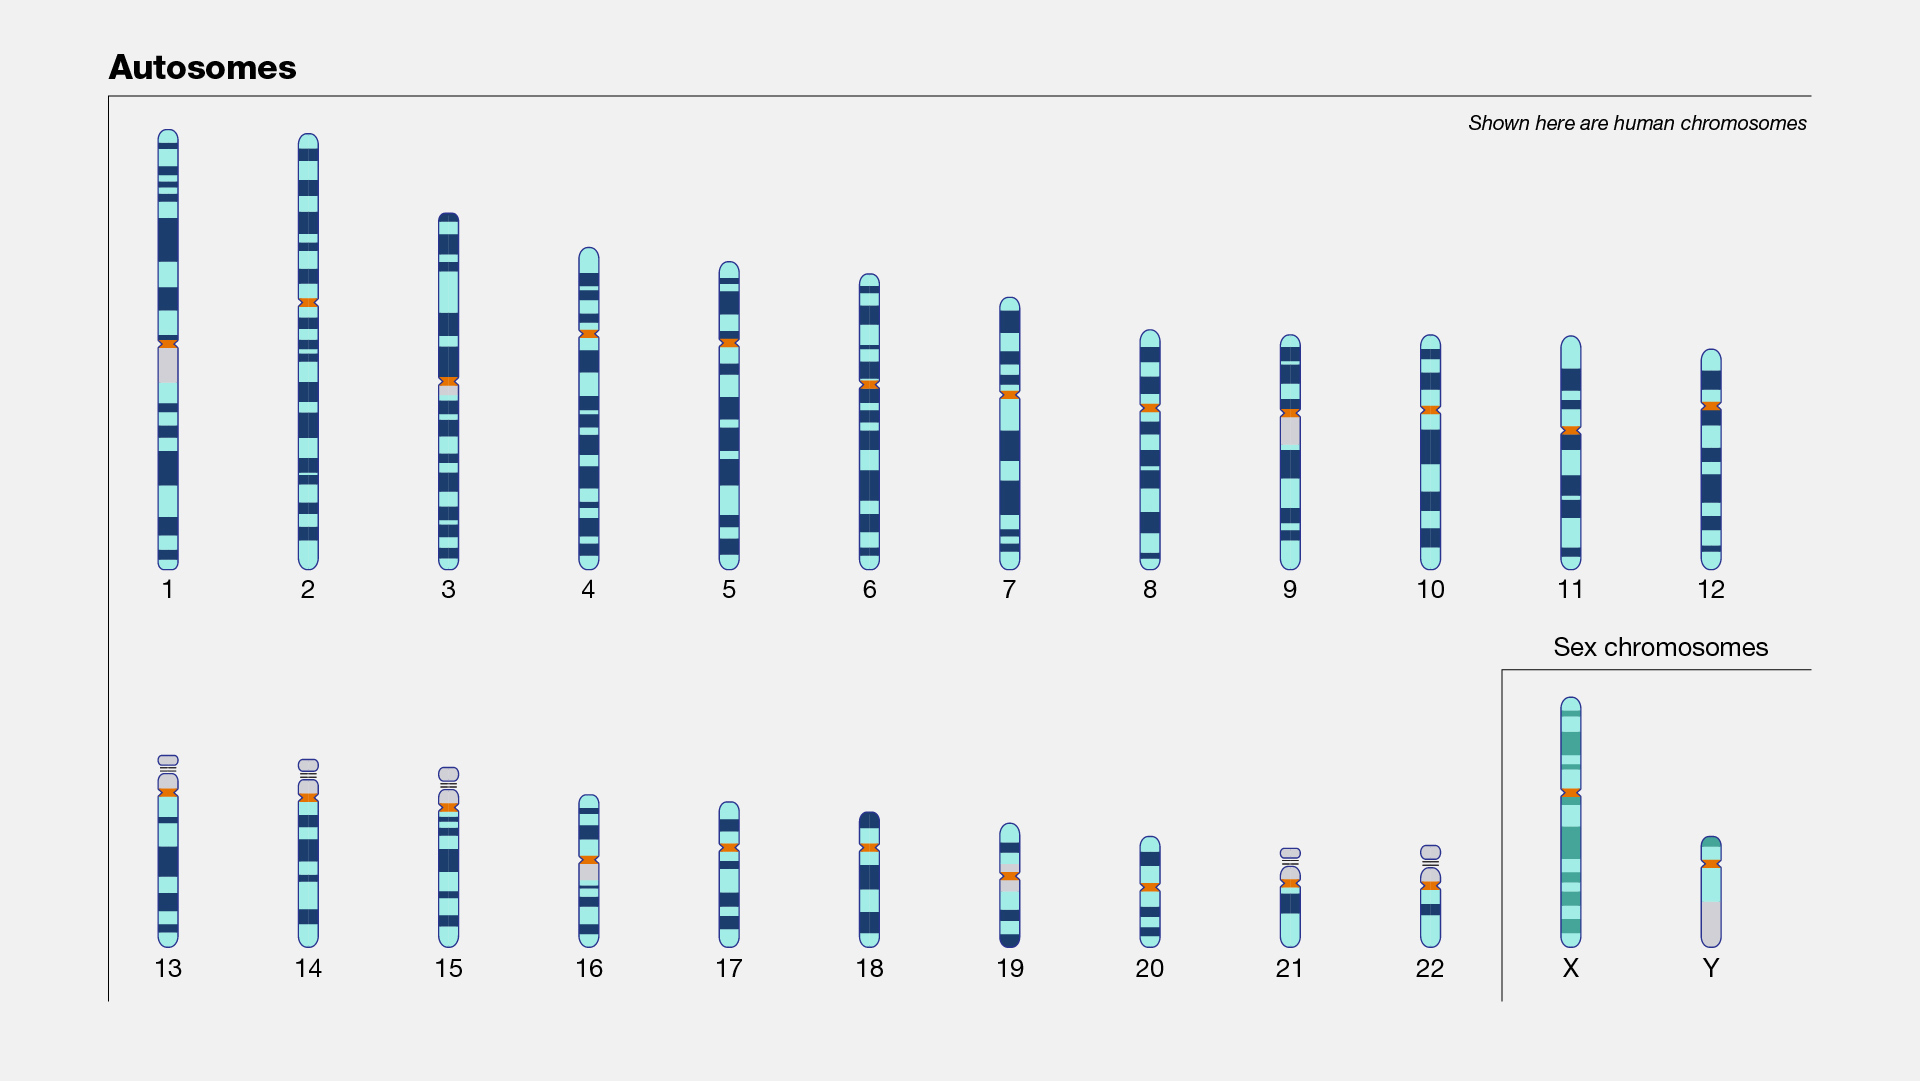
Autosomes are the twenty-two pairs of chromosomes that aren't involved in determining sex. That's it. They carry roughly 95% of your genetic material, and if you're doing any kind of ancestry work or genetic health screening, they're where most of the signal lives. The sex chromosomes get all the attention because they're easier to explain, but autosomes are where the actual data density sits. When you pull a raw data file from something like 23andMe or AncestryDNA, you're looking at hundreds of thousands of single nucleotide polymorphisms mapped across all twenty-two autosome pairs plus X and Y. The autosomal portion is what powers relative matching, ethnicity estimates, and most variant reporting. Everything else is secondary infrastructure. I spent years working with raw genetic data files before I ever bothered understanding why my variant calls kept drifting on certain chromosomes. The problem came down to how I was handling phasing. Most people skip phasing entirely when they're just looking at matches, but if you're calling variants or building haplotype blocks, unphased autosomal data will give you noise that looks real until you trace it back to the source. My workaround was running Beagle 5.4 on the raw VCF files before doing anything else. It took the error rate on my calls from roughly eight percent down to under two percent. That's not a small gap.
The key thing about autosomes that beginners miss is recombination. Each generation shuffles the two copies of every autosome you inherit, breaking them into smaller segments. After about ten generations, most of your autosomal DNA from any given ancestor exists in fragments under five centimorgans. Below that threshold, matches become unreliable. You're not getting false positives so much as you're getting statistical ghosts—segments that look inherited but are just identical by state. I learned this the hard way when I spent three weeks chasing a supposed third-cousin connection that dissolved once I started looking at the actual cM distribution instead of just the match count.
How to Work With Autosomal Data Practically
Start with your raw file. Most testing companies let you download it. It's usually a text file with rs IDs and genotype calls. If you're doing anything beyond casual reading, you need to convert it into VCF format. The conversion step matters more than people think because the way you handle missing data and reference alleles will affect downstream analysis. I use bcftools for this, and I always set the missing genotype symbol consistently. Inconsistent handling of missing data is the fastest way to corrupt a dataset without realizing it. Once you have a clean VCF, the next decision is whether to phase it. For relative matching through existing platforms, phasing isn't necessary because the platforms do it on their end. But if you're building your own pipelines or working with obscure reference panels, phasing becomes critical. SHAPEIT4 is the current standard for population-scale phasing, and it handles autosomal chromosomes efficiently. The compute time scales with sample size, but for individual or small cohort work it runs in under ten minutes on a modern machine. One thing that causes unnecessary headaches is the difference between GRCh37 and GRCh38 coordinate systems. A lot of legacy tools and reference datasets are still on 37, while newer ones have moved to 38. If you mix them without liftover, your positions will be wrong and you won't notice until your variant annotations come back empty. I keep a simple script that runs the UCSC liftOver tool on any VCF that arrives in an unexpected build. It saves about an hour of troubleshooting per incident.
Get the Full Details

Common Pitfalls
The biggest trap is assuming that more SNPs means better results. Quality matters more than quantity. Some older arrays genotype only thirty thousand markers, and while they cover all autosomes adequately for basic ancestry, they miss rare variants that newer arrays capture. If you're doing health-related analysis, you need to know what array your data came from before you draw conclusions. The same applies to reference panels. Using a panel that doesn't match your population will skew ethnicity estimates and can produce misleading segment matches. Another issue is segment filtering. Many people retain every matching segment above a certain cM threshold, but small segments on certain chromosomes—particularly chromosome 19, which is densely packed with SNPs—tend to produce spurious matches. I trim anything under seven cM unless it's supported by triangulation from multiple independent sources. This eliminates roughly forty percent of apparent matches in my experience, but the remaining set is far more trustworthy. Autosomal testing simply cannot resolve recent relationships beyond a certain point with perfect accuracy. Siblings share roughly fifty percent of their DNA, but the actual amount varies. Full siblings can share anywhere from thirty-three to sixty-one percent across all autosomes combined. If someone claims a relationship based solely on total cM without looking at the segment distribution, they're probably not reading the data correctly. The total cM number is useful but incomplete on its own.
If you're doing this casually for ancestry purposes, sticking with the major platforms' built-in tools is fine. They've solved most of the hard problems already. But if you're going downstream into your own analysis, understanding how autosomal data actually behaves under different conditions is what separates people who get useful results from people who spend months confused about inconsistent outputs.