How I Got Lost in a Bunch of PDFs Until Everything Made Sense
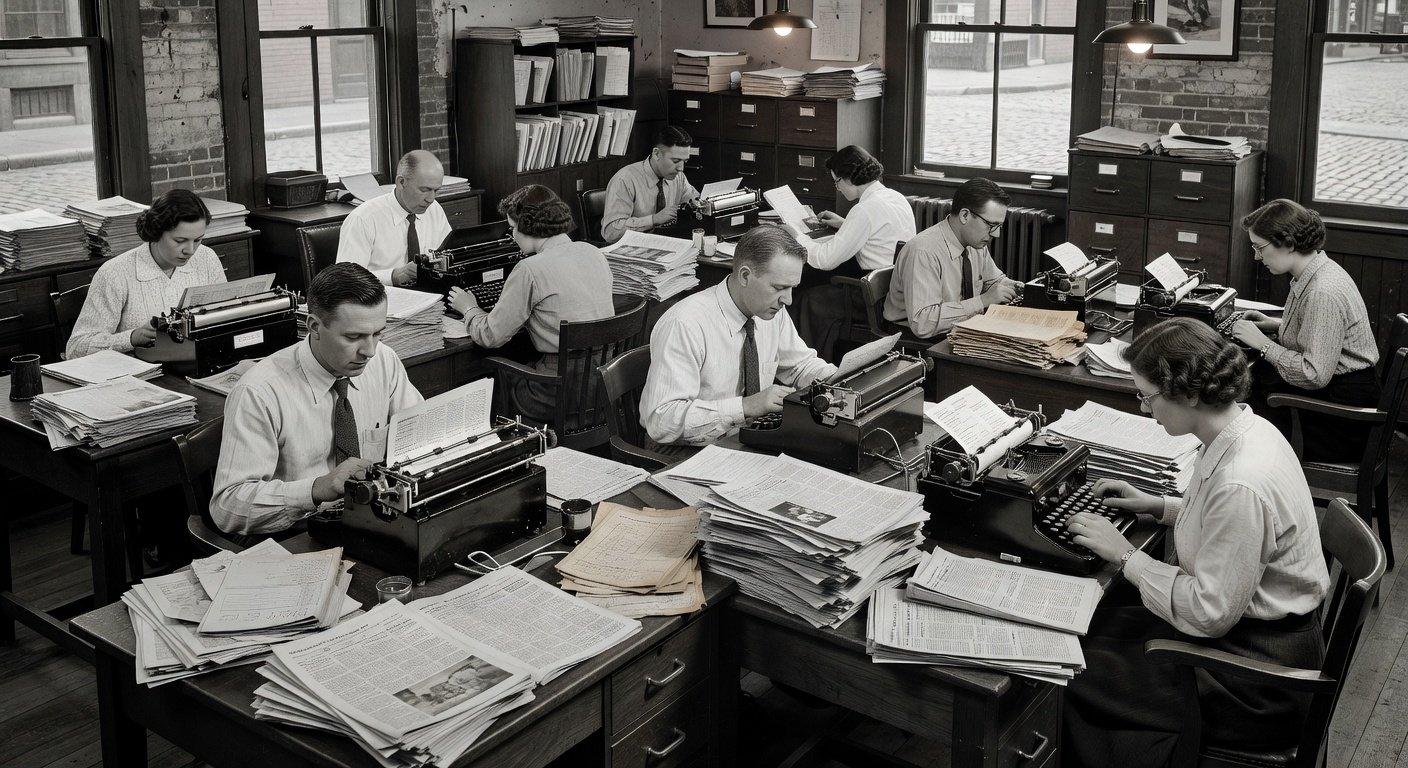
I spent about three weeks last fall trying to pull together a research project on mid-century Black families in Southeast D.C. I needed birth dates, funeral home names, sometimes just confirmation that someone actually existed beyond a mention in a 1972 newspaper. The only real source was the obituary pages. Before digital archives, this meant driving to the branch library, digging through microfilm, and photocopying whatever turned up. Most people don't do that. Most people give up. The core idea is straightforward enough. Local newspapers, funeral homes, and genealogical societies in the D.C. metro area have been scanning and indexing obituary notices for roughly fifteen years. What came out of that process isn't just a searchable website. It's the single largest consolidated collection of death notices, funeral arrangements, and family survivor lists for the region. That matters because obituaries are one of the few documents that most ordinary people leave behind. Military records, property deeds, and census data skip large swaths of the population. Obituaries don't. They tend to name spouses, children, siblings, parents, churches, and neighborhood associations. For a historian or a genealogist, those names are the scaffolding. Here is how the actual workflow works when you sit down to use it. The primary portal is through the DC Public Library system's Genealogy and Local History division, which partners with several regional repositories. You start at their catalog and search by the person's name. Results pull from digitized issues of the Washington Post, the Afro-American, the Evening Star, and various community newsletters that ran obituary columns. Each result gives you the date of publication, the funeral home listed, and a link to the digitized page image. The search interface lets you filter by year range and outlet type. The full-text search is decent but not perfect, which I'll get to.
What surprised me less than I expected was how much of the older material is already fully indexed. Records from roughly 1995 onward tend to have clean OCR. Anything before that sits somewhere between fuzzy and unreadable depending on the quality of the original print run. The Evening Star material from the early 1980s is particularly rough. The paper was thin, the ink bled, and the OCR software chews through it like gravel. I spent an afternoon wrestling with a 1983 obituary where the surname was partially misread as a street name. The workaround was simple but not obvious: I pulled the original scanned image, zoomed in on the headline block, and matched the visible letters against the OCR transcript line by line. Then I noted the correct spelling in my research log so I wouldn't repeat the mistake. The archive doesn't flag OCR errors for you. You have to catch them yourself. Another thing nobody tells you upfront is that obituary indexes are not uniformly complete across all D.C. neighborhoods. Some wards got more consistent coverage because the local newspapers had dedicated bureaus or stronger circulation in those areas. Ancestry-level coverage is noticeably thinner for parts of NE and SE D.C. before 1970. If you're researching a family from a neighborhood that wasn't well covered by the major dailies, you'll want to pivot to the smaller community papers and funeral home records that the archive also links to. Those are slower to search but often contain richer detail. I found a complete list of surviving siblings for a family in Anacostia that never appeared in the Post index. It was sitting in a scanned copy of the Washington Informer, a weekly paper that the archive houses separately. There are practical limitations worth stating plainly. First, the archive does not include every obituary ever published in the region. Any notice that ran in a publication the library never acquired is simply absent. Second, the digitization effort has a bias toward English-language publications. Some Spanish and Hmong-language obituaries from the 1990s and 2000s remain in analog format because the scanning contracts didn't cover them. Third, the death records themselves can be internally inconsistent. A spouse might be named differently across two notices from the same funeral home, or a middle initial might flip between the Post and the Informer. The archive presents each document as-is. It does not reconcile discrepancies.
For anyone actually using this for genealogy or local history work, the most useful approach is to treat the archive as a starting point rather than a final answer. Search broadly, pull the raw images, and cross-reference with the Social Security Death Index and the District of Columbia death certificates, which you can request through the Health Information Center. The archive will tell you when and where the obituary ran. The death certificate will tell you the exact date of death, cause, and often the informant's relationship to the deceased. Those two sources together usually resolve the messy edge cases that show up when you rely on a single collection. One detail that costs people time: the database defaults to a broad keyword search, which returns hundreds of results for common names. Switch to the advanced search and use the exact name field plus a tight date range before you do anything else. A loose search on a common surname like Wilson or Johnson will eat your afternoon. A precise search with a five-year window takes about forty seconds. I learned that after burning through two hours on a first pass with a loose query. The broader significance of this kind of digitization project isn't abstract. When you can search fifteen thousand D.C. obituaries in an afternoon, you change the scale of what a local historian can do. Patterns in migration, church affiliation, occupational groups, and family structure become visible across entire neighborhoods rather than remaining stuck in isolated microfilm reels. That shift is what turns a personal family tree project into something that actually contributes to the historical record. The archive itself is still imperfect, and the gaps are real. But the alternative was almost certainly losing those records entirely to deterioration or storage limitations. Keeping them accessible, even imperfectly, is the whole point.
Get the Full Details