The actual problem most Baylor offices face with payroll
Baylor isn't one system. It is a set of departments, campuses, and units, each with its own scheduling quirks, FLSA classifications, and labor agreements. When you try to pull time and attendance data into payroll across that environment, the first thing you notice is that nobody maps their time the same way. One department clocks in at 7:00 AM and expects a half-hour lunch deduction. Another has analysts on annualized leave who are never meant to see a lunch deduction at all. The third runs shift workers on a union contract that requires overtime after 40 hours in a work week, not a pay period. Get those rules wrong in your setup and the payroll run either breaks or produces results that look right until someone notices. The short version of how this works is that you build a single source of truth for hours, apply the right calculation logic before anything reaches the payroll engine, and then let the system handle the distribution. That means integrating your timekeeping platform with the payroll system so that approved hours flow in automatically, with exceptions flagged rather than buried. Manual imports, spreadsheets waiting in email chains, and midnight data entry before a cutoff date are the things that cause the errors. They are also the things you eliminate when the integration is done correctly. I spent a few years dealing with this exact setup across a multi-campus institution. The worst case I ran into involved a department that used a third party to manage scheduling. That third party exported time in a format that dropped the first and last day of each pay period whenever a holiday fell on a Monday. The payroll team caught it once, but not every time. The fix was not to yell at the scheduler. It was to build a validation rule in the integration layer that compared submitted hours against a baseline schedule and flagged any gap wider than one day for review before approval. That cut our error rate down to near zero and removed about two hours of manual checking per pay cycle.
How the integration actually works in practice
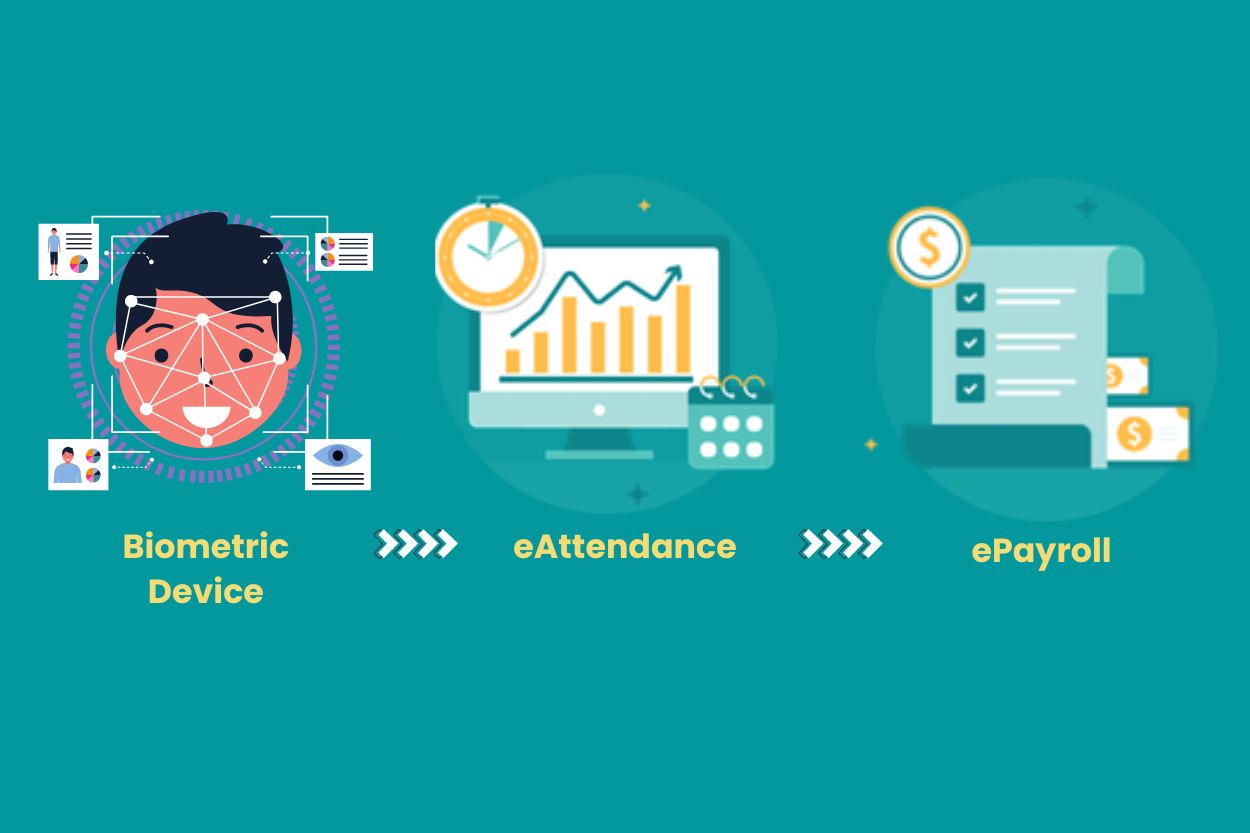
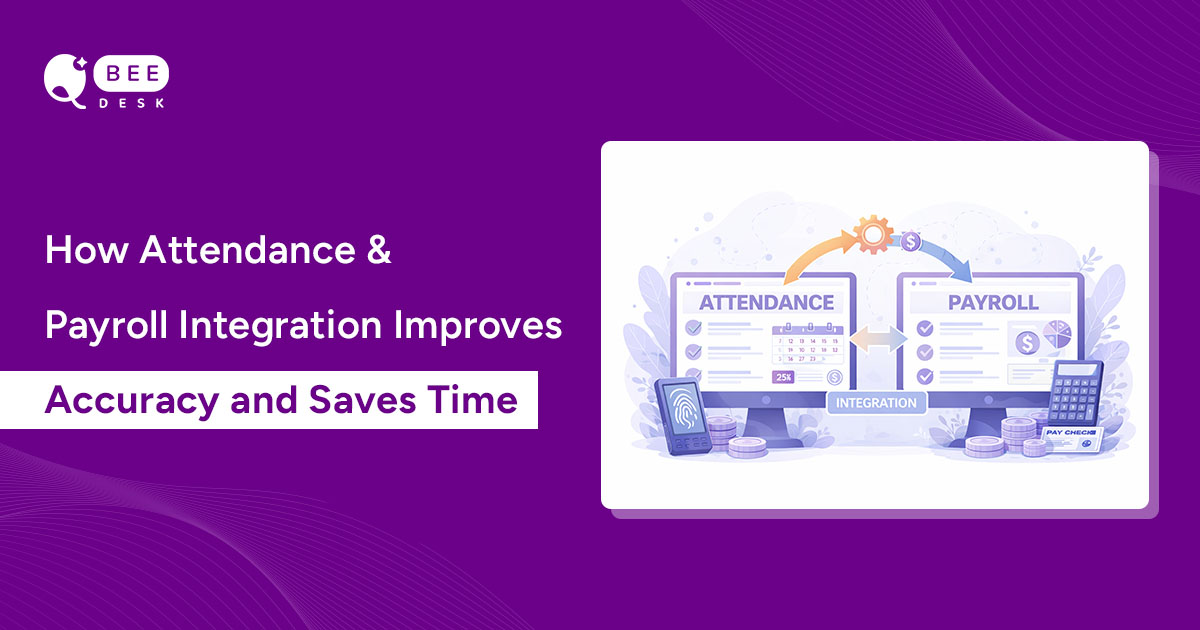
Most modern time and attendance platforms talk to payroll systems through defined interfaces. The exact protocol depends on what Baylor is using at any given moment. In some cases it is a direct API push. In others it is a secure file transfer with a mapped schema. The goal is the same: move approved hours, not raw clock-ins, and keep the audit trail intact. That distinction matters more than people usually realize. Raw clock data is not payroll data. Raw data includes missed punches, system errors, and time entered outside policy. Payroll data is the cleaned, approved version that reflects actual earned wages. If your integration sends raw data to payroll, you will spend every cycle fixing missing punches by hand. If you route it through an approval workflow first, the exceptions get handled before they become payroll problems. That is the difference between a clean run and a three-day headache. The approval workflow itself should be simple. Supervisors approve hours for their teams within a set window. Timekeepers reconcile exceptions. Someone with payroll authority finalizes the batch. Each step leaves a timestamp and an identity. When an audit comes later, you can trace every hour back to the person who approved it and when. That is not optional in a university environment. It is the difference between a clean report and a memo required for compliance.
What most people get wrong about FLSA and overtime in this context
FLSA compliance in a Baylor-like structure is not hard if you know where it breaks. It breaks when you assume one rule applies everywhere. Non-exempt staff get hourly pay and overtime. Exempt staff do not. Annualized employees are paid on a salary basis with flexible time off. Then you have bonuses, shift differentials, and on-call pay that may or may not count toward overtime depending on how they are structured. If your time system does not separate these categories at the source, the payroll calculations will be wrong, and fixing them after the fact is expensive. I learned this the hard way with a department that had a mix of hourly and exempt workers sharing the same schedule template. The system applied the same deduction rules to both groups. The exempt staff ended up with unauthorized deductions on their paychecks, which is a serious FLSA issue. The workaround was to split the employee population into clearly defined classification groups early in the setup, assign each group its own calculation rules, and lock the template so supervisors could not accidentally mix them. It took a little more initial configuration, but it prevented a compliance problem that would have cost far more to fix.
Get the Full Details
Common pitfalls that slow everything down
One major pitfall is treating the payroll cutoff as a deadline rather than a buffer. If you push everything to the last possible moment, any error in time submission forces a rush to fix it. A better approach is to set an internal cutoff two days before the official payroll deadline. That gives timekeepers room to reconcile exceptions and gives payroll room to review the batch without panic. I have seen teams lose hours because they waited until the cutoff to notice a missing shift. Those hours had to be added manually, which broke the automation and introduced risk. Another pitfall is assuming that integration equals accuracy. Integration only moves data correctly. It does not validate the data before it moves. If the time system allows a supervisor to approve negative hours or duplicate entries, the payroll system will process them just fine. You need validation rules in the timekeeping side, not just in payroll. Rules like "no more than 24 hours in a single day," "no negative adjustments without a reason code," and "overtime over 40 hours requires secondary approval" are cheap to implement and expensive to ignore. A third pitfall is poor mapping between employee types and pay codes. Baylor uses a wide range of funding sources, appointment types, and pay codes. If your time system does not map each employee to the correct pay code at the point of clock-in, the hours will land in the wrong account. That creates accounting problems that ripple through budget reporting for months. I have seen entire departments spend a pay cycle reclassifying hours after realizing the default mapping was wrong. The fix was to require a pay code selection at clock-in for any employee with a non-standard appointment type, and to test the mapping during onboarding rather than after the first payroll run.
What the setup actually looks like if you do it right
Start with a clear list of employee classifications and their corresponding rules. Non-exempt hourly, exempt salary, annualized, student workers, contingent faculty, union staff. Each one gets its own calculation path. Map pay codes to funding sources. Set approval hierarchies so the right people sign off on the right hours. Build validation rules that catch obvious errors before they reach payroll. Test the integration with a small group before rolling it out campus-wide. Run a parallel cycle where both the old manual process and the new automated process produce results, then compare them line by line. The parallel cycle is the most important step. It is easy to skip because it takes time, but it is the only way to catch mapping errors, rounding differences, and edge cases before they affect everyone. I have seen teams skip it and discover a rounding rule mismatch on payroll day. The fix required retroactive adjustments for an entire department, which took three days of work and caused a lot of complaints. Running the parallel cycle would have caught that in a test environment where it only cost an afternoon.
Where this approach does not work
It does not work well if your time and attendance system is too old to support APIs or secure file transfers. Some institutions still rely on legacy platforms that require manual export and import. In those cases, automation is limited, and you are better off upgrading the timekeeping side before chasing integration gains on the payroll side. Trying to build a complex workaround for a system that cannot communicate is usually more work than it is worth. It also does not work if leadership expects a quick fix with no investment in cleanup. If employee records are incomplete, classification rules are undefined, and historical data is messy, the integration will reflect that mess. You need to clean the master data first. That means auditing current employee classifications, fixing duplicate records, and standardizing how time is recorded across departments. Skipping this step because it feels slow will cost you later. The system will run, but the results will be unreliable.
A realistic view of the effort versus the payoff
Setting this up properly usually takes several weeks of configuration, testing, and training. The first two weeks are spent defining rules and mapping data. The next week is testing with a pilot group. The final week is full deployment and close monitoring. After that, the daily workload drops significantly. Payroll teams that used to spend hours reconciling time entries often find themselves spending maybe an hour or two per cycle on exceptions instead. That is not a small saving. It is the difference between finishing payroll before the weekend and pulling an all-nighter every cycle. The ongoing maintenance is lighter than the old manual process but not zero. You still need to review exception reports, update rules when policies change, and retest after any system update. If Baylor adds a new campus or changes labor agreements, those changes need to be reflected in the calculation rules promptly. Ignoring that maintenance for a few cycles will cause problems to accumulate quickly.
The parts that actually move the needle
The biggest gains come from three things: eliminating manual data entry, enforcing approval workflows before payroll receives hours, and validating employee classifications at the source. Anything else is optimization. Adding dashboards, generating extra reports, or tweaking notification settings is useful but secondary. If you skip the foundational steps and jump straight to dashboard customization, you will have a pretty interface displaying inaccurate data. That is worse than no interface at all. I also found that training supervisors made a bigger difference than most teams expected. Supervisors are the people who approve time, and they are often the ones who introduce errors by approving without checking. A short training session on why the rules exist, what the common mistakes are, and how to read the exception report can reduce errors by half. I have seen this repeatedly. The tools only help if the people using them understand what they are looking at.
How to decide if this is ready for your situation
You are ready when your current process relies heavily on manual entry, when payroll errors are common enough that someone spends significant time each cycle fixing them, and when there is a clear separation between timekeeping and payroll responsibility. You are not ready if the data behind your time and attendance system is untrusted, if employee classifications are unclear, or if the timekeeping platform itself cannot support automation. Fix the foundation first. Then add the integration. Then enjoy the time savings. The end result is not magic. It is a system where approved hours flow into payroll without manual intervention, where exceptions are visible early, and where payroll can run on schedule without last-minute scrambles. That is what most Baylor offices that get this right end up with. It takes effort to build. It pays off quickly once it is running. The harder part is starting while the data is still messy, not after it has been clean for a year.