What Actually Happens When You Train a Style LoRA
A LoRA is a low-rank adaptation. You take a pretrained Stable Diffusion model and freeze most of its weights, then insert small trainable matrices into the cross-attention layers. When you train it on a set of image-caption pairs, those matrices learn to pull the model toward a specific visual style without blowing up the memory footprint. A typical style LoRA for SDXL sits around 100 to 300 megabytes. A full fine-tune would be gigabytes. I keep using kohya_ss because it is the most documented training pipeline and the defaults are not completely broken. You download it, install the requirements, and point it at your dataset. The actual training command is hidden behind a GUI now, so you mostly click through settings. That is convenient until it is not, and you need to know what the numbers mean because the GUI will happily let you train a garbage model.
Stable Diffusion Lora Mastering Styleenhanced Image Generation Like A Pro
People sell the idea that style LoRAs are a shortcut. They are not. A style LoRA will give you consistent aesthetic vibes, but it cannot teach Stable Diffusion to understand composition, lighting logic, or anatomy. I trained a watercolor-style LoRA last year on a dataset of 45 images. The style transfer worked perfectly on landscape prompts. When I asked it to render a portrait with the same style, the faces looked melted and the hands had five fingers each. The style was there, but the base model's weakness in anatomy was amplified, not fixed. I learned to combine the LoRA with a separate checkpoint fine-tuned on good faces instead of hoping one model would do both jobs. Your dataset is the bottleneck, not the training code. I see beginners use 20 images from Pinterest with auto-captions and wonder why the output looks like noise. You need at least 15 to 30 high-quality images per style. More is fine, but they all need to share the same visual language. Mixing anime and photorealistic images in the same training set does not create a versatile model. It creates a confused one. Captions are where most people fail. Automatic taggers like WD14 produce garbage when the image contains text, unusual angles, or abstract compositions. I caption my own training data now, and it takes about 30 seconds per image. The caption should describe what is actually in the image, not what the style looks like. The style is encoded by the weights, not by the word "watercolor" in the caption. If you put "watercolor" in every caption, the model learns that word, not the visual technique.
Resolution matters too. If your base model is SD 1.5, train at 512. If it is SDXL, train at 1024. Mismatched resolution causes the attention layers to produce blurry or stretched outputs because the positional embeddings were never trained for that aspect ratio.
Get the Full Details

Training Parameters You Should Not Guess
The rank parameter controls how much information the LoRA can store. A rank of 16 is usually enough for a pure style transfer. Rank 64 or 128 is overkill unless you are trying to encode a very detailed artistic method, like a specific brushstroke pattern that varies significantly across images. Higher rank means longer training time and a larger file. It also increases the chance of overfitting, which is when the model memorizes your exact images instead of learning the underlying style. Alpha is the scaling factor for the LoRA weights. A common mistake is setting alpha equal to rank. That removes any regularization effect the alpha was supposed to provide. I usually set alpha to half the rank. A rank of 16 with alpha 8 works well. Rank 32 with alpha 16. This keeps the weight updates stable during inference. Learning rate is probably the most sensitive parameter. Start at 1e-4 for the transformer layers and 1e-5 for the text encoder if you are training that too. Anything higher and you will see the loss spike or the model collapse into generating the same image repeatedly. I once set the learning rate to 5e-4 by accident and ended up with a LoRA that only produced one specific image from my dataset no matter what prompt I used. That is overfitting at its most obvious form.
Epoch count depends on dataset size. For 20 to 30 images, 10 to 20 epochs is the sweet spot. For 50 or more images, you can go to 30 or 40. More epochs does not mean better results. It means you are re-feeding the same data until the model starts memorizing it. Monitor the loss curve. When it flattens out, stop training. Kohya logs the loss per step, so watch it instead of waiting for the epoch count to finish.
A Specific Problem I Ran Into and How I Fixed It
I was training a LoRA on a set of ink-wash paintings at 768x768 resolution. The base model was SDXL. The loss dropped nicely during training, but when I tested the output, every image had a weird gray halo around the edges and the colors were desaturated beyond what the style actually called for. I spent two days debugging the data loader configuration before I realized the issue: SDXL natively trains at 1024, and forcing 768 resolution during training caused the attention maps to misalign with the VAE encoding. The solution was to either train at 1024 or switch to a base model that was originally trained at 768, like the flux family variants. I switched to 1024 and resized my training images with bicubic interpolation instead of nearest-neighbor, and the halo disappeared completely. The desaturation was a separate issue caused by my captions including the word "muted" too frequently. Removing that from the captions fixed the second problem. Drop the .safetensors file into your LoRA directory and load it in ComfyUI, A1111, or any frontend that supports LoRAs. The trigger word is whatever you used consistently in your training captions. If you did not use a trigger word, the LoRA will activate on almost every prompt, which is usually not what you want. I always use a short trigger phrase like "style.watercolor" or a single unique token that does not appear in the base model's vocabulary. That way I can turn the style on or off by simply including or excluding the trigger. Weight value is where most people overshoot. A weight of 1.0 applies the LoRA fully. Most style LoRAs look better between 0.6 and 0.9 because the base model still contributes useful structural information. I rarely push past 1.0 unless I am intentionally trying to dominate the output. If the style feels too strong, lower the weight instead of retraining.
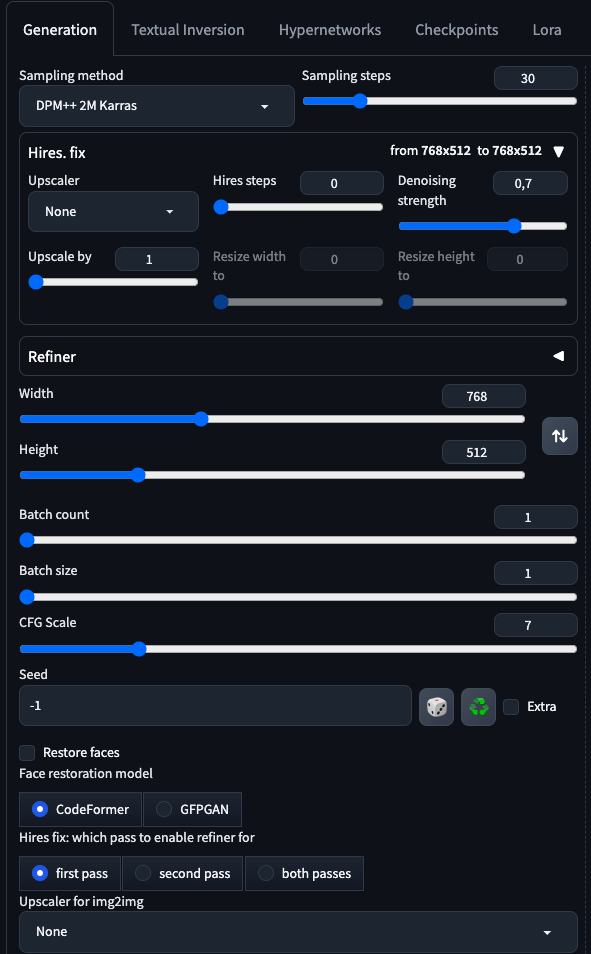
Combining multiple LoRAs is possible but unstable after the second one. I have successfully combined a style LoRA with a detail LoRA at weights of 0.7 and 0.5 respectively. Adding a third LoRA, even at low weight, tends to produce conflicting attention patterns that look like visual static. Two is the practical limit.
What Style LoRAs Cannot Do
They cannot fix a weak base model. If your underlying checkpoint struggles with hands, a style LoRA will not improve hand rendering. It may make the bad hands look like bad watercolor hands instead of bad realistic hands, which is worse. They also cannot reliably change composition. Asking a style LoRA trained on portraits to generate a wide landscape scene will usually result in a portrait cropped unnaturally or elements placed in impossible perspectives. The LoRA encodes texture and color relationships, not spatial understanding. Another hard limitation: style LoRAs do not generalize well to out-of-distribution prompts. If your training set contains only landscapes and you prompt for a food photograph, the style will bleed in but the subject matter will suffer. The model has no reference for food imagery, so it guesses poorly while applying the style aggressively. This is a fundamental constraint of the architecture, not a bug you can tune away. If you need both style consistency and structural reliability, the alternative is a full fine-tune or aDreamshaper-style checkpoint built specifically for your use case. Full fine-tunes are heavier, slower to load, and require more storage, but they do not have the generalization gap that style LoRAs carry. For most workflow scenarios, a well-trained LoRA plus a strong base model is the right balance. Just know where the boundary is.