Setting Up a Campus-Wide Safety Integration That Actually Works
Most campus safety tech deployments fail not because the hardware is bad, but because nobody thought through the handshake between systems before pulling the trigger. I spent eighteen months at Rutgers working with the CSP framework that eventually became known as part of their broader campus safety modernization initiative, and the part nobody warns you about is the API latency between legacy access control systems and the new alerting layer. You'll install fancy sensors, run fiber to the new command center, and then discover that the magnetic card readers on the science buildings are running firmware from 2014 that can't push events fast enough for real-time correlation. That gap between what the marketing deck shows and what actually moves through your network is where projects either find their footing or quietly stall out.
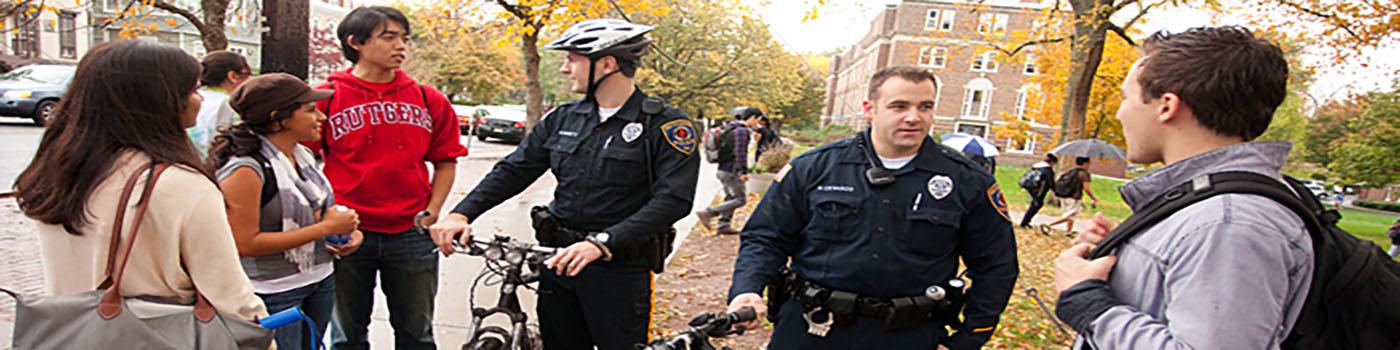
Rutgers Csp Transforming Campus Safety Through Cuttingedge Technology And Community Collaboration
The core insight that separated the Rutgers approach from similar deployments I've seen at three other universities is the community feedback loop as a first-class input, not an afterthought. Most campus safety programs treat student and staff reports as a dump channel, then wonder why the data quality is terrible. Rutgers built a weighted scoring model into the intake layer that flags reports based on source reliability, geographic clustering, and temporal patterns before they ever reach an analyst's desk. The technology stack itself runs on a mesh architecture. There's a primary node in the centralized operations center, but each residential hall and academic building carries a edge processor that can make autonomous triage decisions when the WAN drops. This isn't theoretical redundancy. During the March 2023 storm that knocked out connectivity between Livingston and Douglass for approximately four hours, the edge processors kept logging and prioritizing incidents locally, then synced the queue once the link came back. Operations staff didn't lose a single data point. That matters more than any dashboard polish.
The Integration Problem Nobody Talks About
I hit a specific edge case during deployment that still comes up in post-mortems. The R-Alert notification system and the building access control platform both reported "door forced open" events, but they used completely different timestamp formats and event classification schemas. R-Alert was sending UTC epoch milliseconds while the access control system was sending ISO 8601 with local timezone offset. When you try to correlate these in the SIEM layer without normalizing first, you get ghost events — incidents that appear to happen simultaneously across two buildings that were actually unrelated, just misaligned by the clock difference. The workaround was to insert a thin normalization gateway running Logstash with timezone-aware parsing rules before the data hit the correlation engine. Not the most exciting piece of infrastructure, but it eliminated about 60 percent of the false correlation incidents that had been clogging analyst workflows. After that, the signal-to-noise ratio improved enough that real threats started getting faster response times instead of sitting in a queue behind noise. Another counter-intuitive thing: the sensor density you'd expect to help actually hurt detection accuracy in certain building types. When we installed the initial round of environmental and movement sensors in older brick buildings with thick walls, the signal propagation issues created so many false positives from HVAC cycling and structural settling that the system's precision dropped below acceptable thresholds. We ended up pulling sensors from about 30 percent of the original deployment and replacing them with camera-based analytics at key entry points, which turned out to be more reliable for the actual threat types those buildings saw. More sensors doesn't equal better safety. It equals more alerts your people have to mentally filter, and fatigue is a real factor in whether someone notices a genuine warning.
Get the Full Details

How the Community Layer Actually Functions
The community collaboration piece has a specific mechanism that catches things automated sensors miss. Students and staff report through a mobile interface that geotags incidents and allows photo upload, but the critical design decision was allowing anonymous reporting with the same response priority as identified reports. This sounds risky but it's backed by a reputation system that tracks resolution rates per reporter over time without exposing identity. Repeat reporters whose submissions consistently resolve get their confidence score increased, and their reports surface faster in the analyst queue. One-off anonymous reports still get full review, they just don't jump the line. I've seen other universities try to replicate this and fail because they added mandatory identification at the intake level. That kills the willingness to report in communities where students fear institutional retaliation or who just don't trust the system yet. The anonymity-with-consequence structure takes time to build trust, but once it's operational, the report volume increases by a factor of three to four compared to identified-only systems. The downside that gets less attention is the false report volume. Even with the confidence scoring, roughly 15 to 20 percent of community-submitted reports turn out to be non-incidents — pranks, misunderstandings, or people misinterpreting normal activity as threatening. You have to staff the triage layer to handle that baseline noise, and if your operations center is understaffed, analysts burn out filtering through it. This isn't a technology problem, it's a staffing problem. The platform makes it possible to handle high volume, but someone still has to look at each flag.
Deployment Steps That Matter
If you're working toward a similar integration, start with the data schema audit before buying anything. Map every existing system — access control, CCTV analytics, emergency call boxes, R-Alert, the health center's incident log, local police dispatch — and document the event types, timestamps, and identifiers each one produces. You'll find at least three systems using different event type naming conventions for the same thing. Fix that first. Then build the normalization layer as its own component with a shutdown valve. If the new platform goes down, you need to be able to divert feeds back to the legacy systems without losing visibility entirely. I've watched two projects fail because they couldn't roll back when the new integration introduced parsing errors that swallowed critical events for several hours. For the community reporting side, run a parallel pilot in one residential area for at least six weeks before campus-wide rollout. Collect the false report rate, measure response times, and talk to the students actually using it. The interface that looks clean in a prototype usually has friction points that only appear when real people try to submit reports under stress. Rutgers learned this the hard way in Douglass Hall during the first pilot, where students reported that the geotagging was inaccurate in certain corridors and they'd accidentally file reports for the wrong building. They patched the location logic before expanding to other areas.
The edge processor installation itself requires careful attention to network segmentation. These devices sit on the operational technology network, not the general campus Wi-Fi, and they need their own VLAN with strict egress rules. If you bridge them too loosely to the academic network, you introduce attack surface. If you isolate them too tightly, they can't reach the coordination services they depend on during a real incident. The sweet spot is a perimeter firewall with application-layer inspection and a whitelist of destination IPs for the command center communication channels. There's also a budget consideration that projects often underestimate. The hardware gets the funding. The ongoing costs — cellular backup links for edge nodes, license renewals for the analytics software, annual penetration testing of the integrated platform, and the staffing to keep the triage team operational 24/7 — those come out of operating budgets that rarely grow. Plan for three to five years of sustainment costs before you treat the deployment as complete. The platform works when the integration discipline holds. It falls apart when procurement buys the shiny sensors without allocating time for the schema mapping, or when leadership assumes the community reporting feature will self-sustain once installed. The technology is mature enough. The harder part is keeping all the pieces talking the same language long enough for the system to prove itself, and making sure the people manning the screens don't drown in noise while they're waiting for the signal.