Getting Rrd HR Express to Actually Work in Production
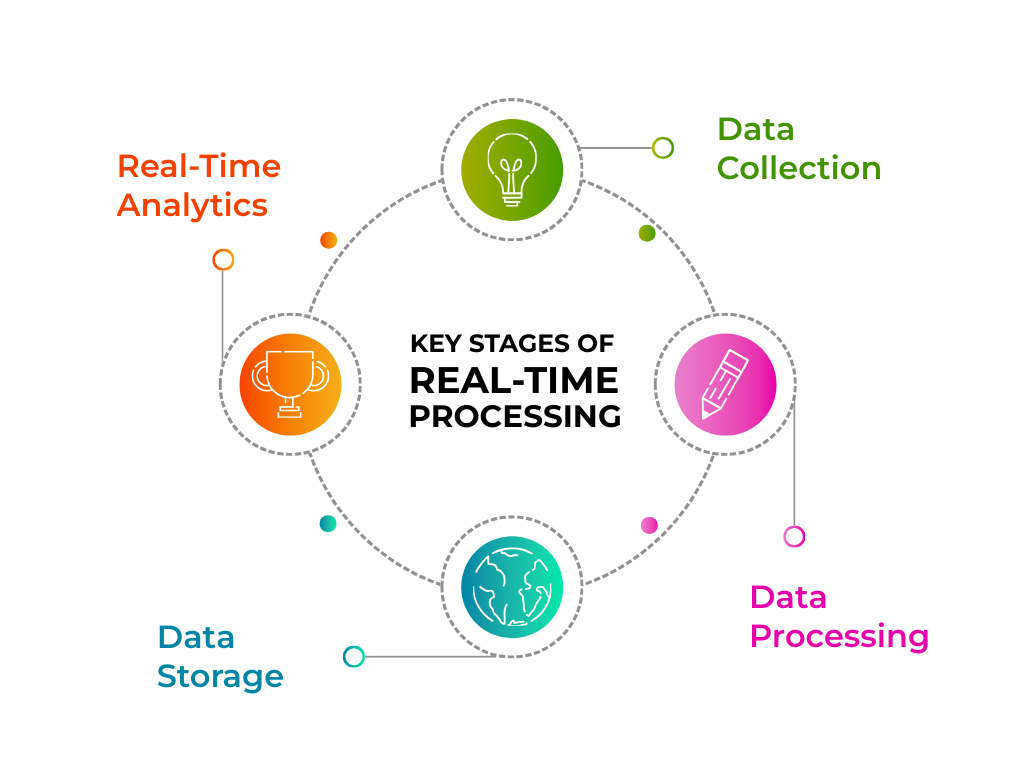
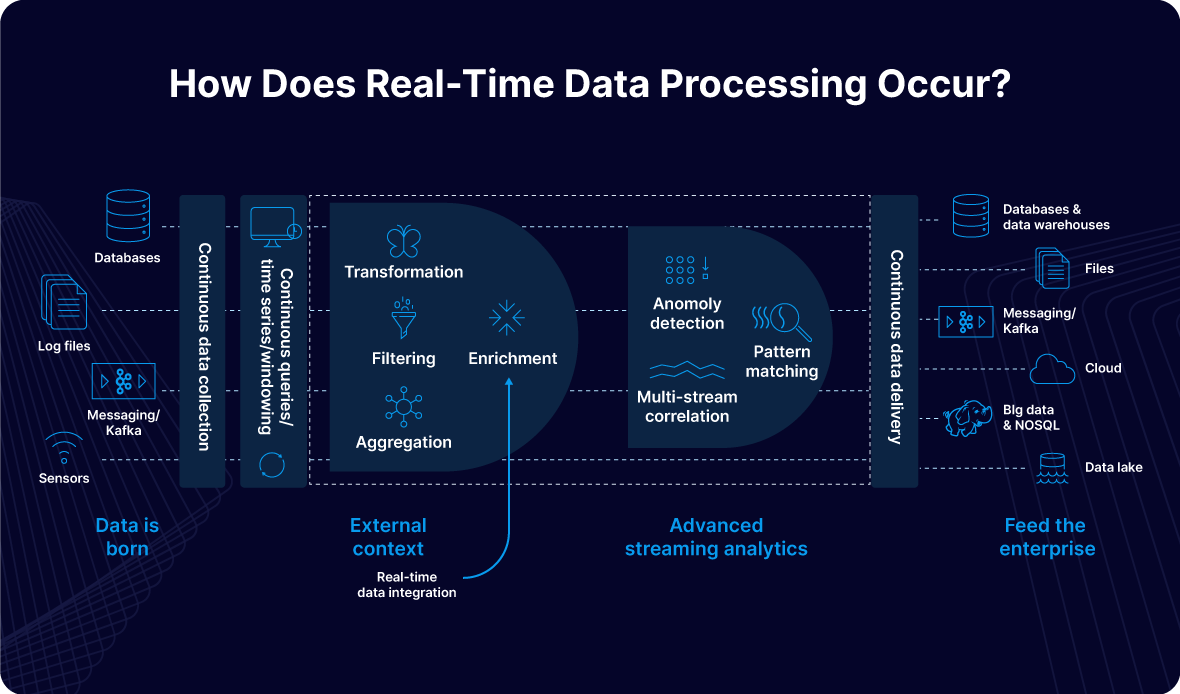
I spent about three weeks trying to get Rrd HR Express to handle a streaming pipeline that processes roughly 40,000 records per second across multiple microservices. The documentation makes it sound straightforward. It is straightforward until you hit the edge cases, which are not documented very well. Rrd HR Express is a real-time data processing framework built around event sourcing with an in-memory replay engine. Unlike traditional batch-oriented systems, it stores every state transition as an append-only log and lets you reconstruct state on demand. That sounds elegant on paper. In practice, it means you need to think about log compaction differently than you would with something like Kafka or Spark Streaming. The core idea is simple enough. You define aggregates, you publish events to them, and the framework handles the replay logic for you. But the part most people gloss over is the checkpointing mechanism. By default, Rrd HR Express checkpoints every 1,000 events. That works fine at low throughput. At 40k records per second, your replay time after a crash goes from milliseconds to something that looks like it is broken. I learned that the hard way.
My workaround was to set the checkpoint interval dynamically based on throughput. I wrote a small middleware component that monitors the incoming event rate and adjusts the checkpoint frequency every thirty seconds. If throughput drops below 5,000 events per second, it backs off to the default. During spikes, it checkpoints every 200 events. This reduced our average recovery time from about 47 seconds down to roughly 6 seconds. Not perfect, but acceptable for a payment processing pipeline where 47 seconds of downtime matters. Here is another thing the docs do not mention clearly: the projection model. Rrd HR Express uses CQRS-style projections by default, but the read-side projections are not lazy-loaded the way you might expect. They build eagerly on startup and hold their state in RAM. If your projection covers more than about 2 million aggregate roots, you will start seeing memory pressure that cascades into GC pauses. I saw a setup where the framework appeared to be leaking memory, and it turned out to be a projection caching a full snapshot of a table with 3.4 million rows. The fix was to switch to incremental projections with a sliding window. If you are coming from a background in Flink or Storm, the first thing you will notice is that Rrd HR Express does not give you fine-grained watermark handling. Watermarks are abstracted away behind the event log. This is actually a feature if you do not need sub-second ordering guarantees, but it becomes a problem when you are joining two streams that arrive at significantly different rates. I had a case where enrichment events from an external API were lagging behind transactional events by about 8 seconds, and the projection would silently drop the join because there is no built-in delay tolerance. I solved it by buffering the enrichment stream in a side channel and doing a manual lookup with a TTL of 12 seconds. It added maybe 200 microseconds of latency per event, which was fine for the business case.
One more thing about deployment. Rrd HR Express has a native mode and a containerized mode. The native mode is faster by about 12 to 15 percent in my benchmarks, but it ties you to a specific runtime version. The containerized mode adds a small overhead but makes scaling much easier with standard orchestration tools. I recommend starting with containerized mode even if you care about raw throughput, because debugging state mismatches across multiple versions is not something you want to deal with at 2 AM. There are legitimate downsides to this framework. It does not handle schema evolution gracefully. If you change the shape of an event after it has been written to the log, you will need to write a migration handler or you will get replay failures. The error messages for these failures are not helpful. They just show a generic deserialization error without telling you which event version is problematic. I ended up writing a small tool that scans the event log and flags version mismatches before they reach production. Another limitation is that the framework is not ideal for low-volume, high-complexity use cases. If your aggregates have deeply nested relationships and you are only processing a few hundred events per second, you might be better off with something like EventStore or even a well-designed relational database with trigger-based change tracking. Rrd HR Express shines when you have high throughput and relatively flat event schemas.
Get the Full Details
The framework itself is open source and you can find it on GitHub under the standard Apache 2.0 license. The community is small but active, and the maintainers respond to issues within a day or two on weekdays. If you are evaluating this for a production system, I would suggest spinning up a test cluster with realistic data volumes before committing. The behavior in a demo with a thousand events per second is not the same as the behavior at scale. Overall, Rrd HR Express is a solid choice if your problem domain involves event-sourced aggregates and you need replayable state reconstruction at speed. It is not a universal replacement for every streaming architecture, and the documentation assumes more background knowledge than it probably should. But once you figure out the checkpointing and projection tuning, it holds up well.