Understanding R2 Without the Textbook Fluff
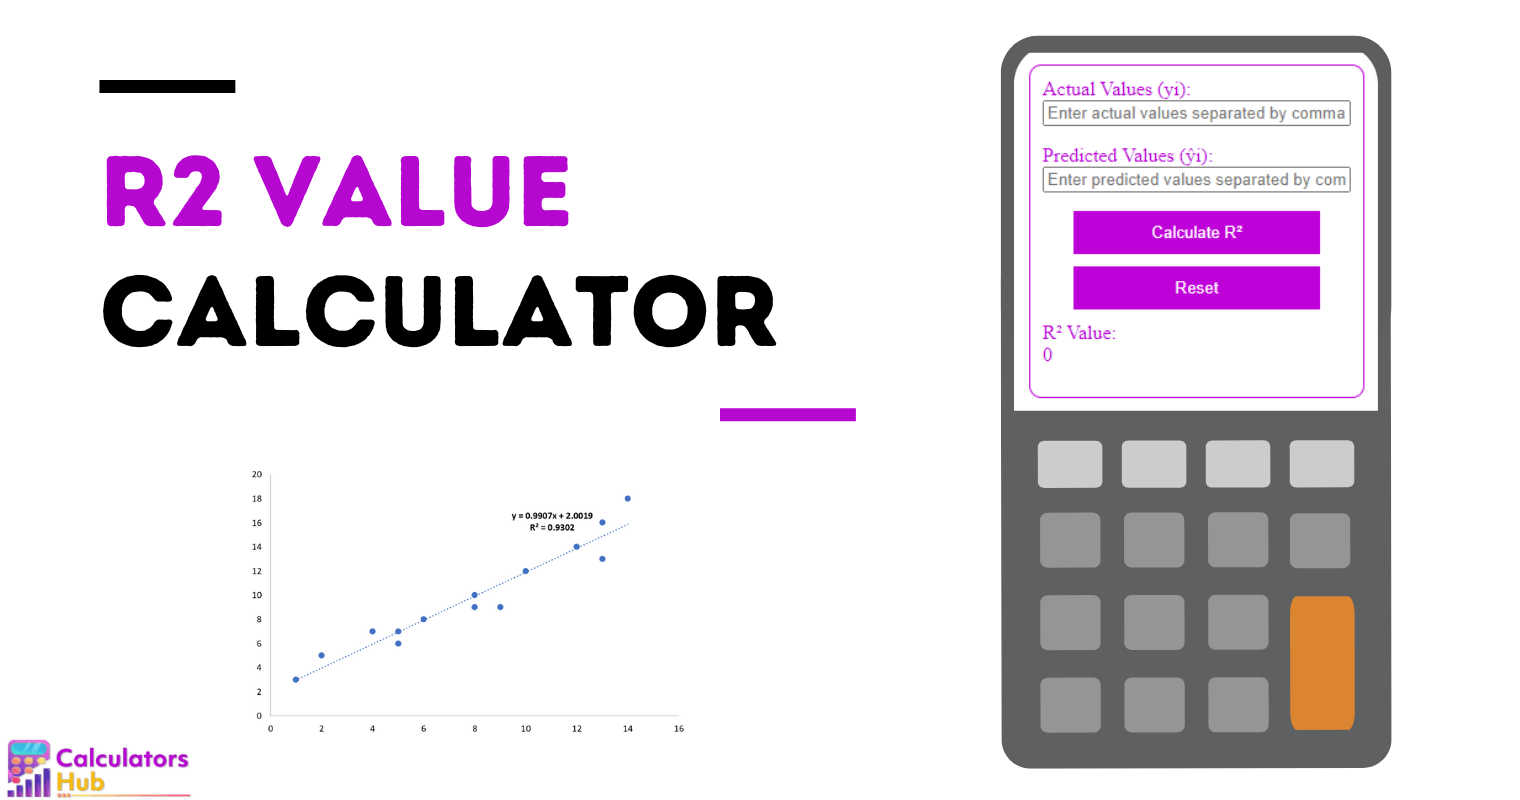
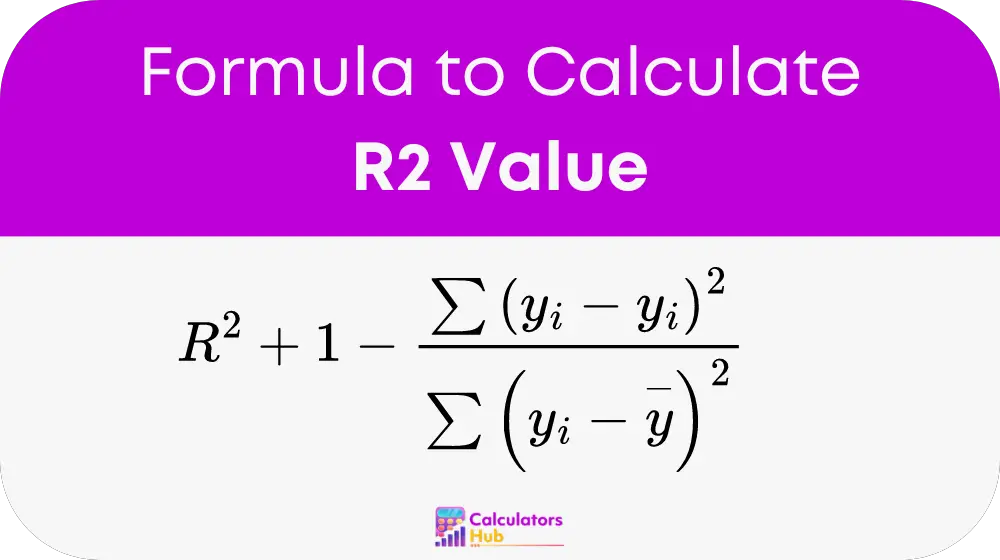
R2, or the coefficient of determination, measures how much of the variance in your dependent variable is explained by your model. That's it. Most people treat it as some sort of truth meter. It isn't. It's just a ratio. When you're building regression models, R2 will sit there looking trustworthy while quietly misleading you. I've seen plenty of cases where the number looked great and the model was useless. The math behind it is straightforward. You take the sum of squared residuals from your model and divide it by the total sum of squares in the data. The result tells you what fraction of variability your predictors captured.R2 Value Explained What It Really Means For Your Data
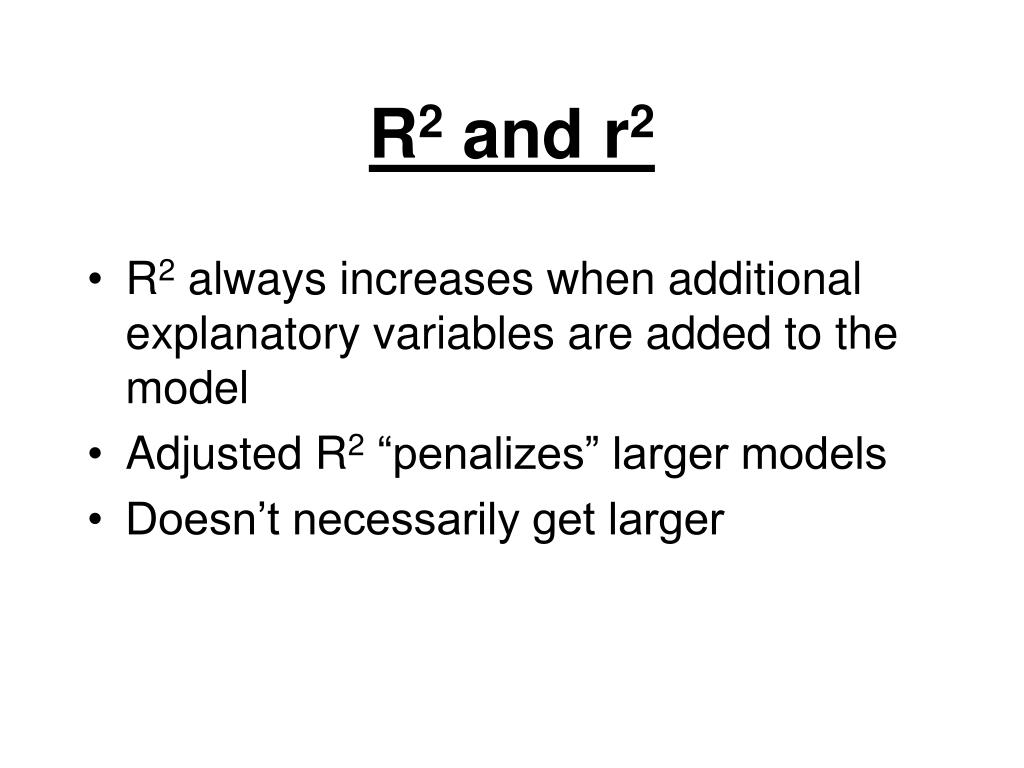
A perfect R2 of 1.0 means your model explains every single point exactly. Zero R2 means your model does no better than predicting the mean every time. Most real models land somewhere between those extremes, usually in the 0.3 to 0.8 range depending on the field. Social sciences tend to have lower values because human behavior is messy. Physics experiments often score higher because the systems are tighter. The trap most people fall into is treating R2 as a standalone quality check. Here's what actually happens on a project I ran last year. I was building a demand forecasting model for retail inventory. The training R2 came back at 0.91. Looked solid. But when I split the data chronologically and tested on the holdout period, the R2 dropped to 0.43. The model had memorized seasonal patterns from the training window but couldn't generalize to the test period. The fix was adding lagged features and a time-based cross-validation strategy instead of random splits. Validation R2 after that came in at 0.78, which was honestly the first honest number I'd seen all week. Adjusted R2 exists for a reason. Every extra predictor inflates your regular R2, even if that predictor is pure noise. Adjusted R2 penalizes unnecessary complexity. If you're running a model with twenty features and your adjusted R2 is significantly lower than your raw R2, you probably have dead weight in there. Drop the weak predictors and watch the adjusted value climb back toward the raw one.
Common Pitfalls That Wreck Your Interpretation
One thing nobody warns you about is the relationship between R2 and prediction intervals. A model with R2 of 0.6 might sound decent until you calculate the actual confidence bounds around your forecasts. With that level of unexplained variance, your prediction intervals can easily span 30 to 50 percent of the mean value. That width often makes the model unusable for anything requiring precision, like pricing decisions or staffing schedules. I learned this the hard way on a healthcare utilization model where the leadership kept pushing for individual patient forecasts. The aggregate R2 was 0.72, which looked fine on a slide deck. The patient-level error rates were brutal because the unexplained variance wasn't random. It clustered around certain conditions and demographics that the model simply couldn't capture without deeper feature engineering. Another issue is non-linear relationships. R2 assumes your model captures the structure in the data. If you're fitting a linear model to something inherently curved, the R2 will be artificially low. Not because the relationship is weak, but because your model form is wrong. Quadratic terms, logarithmic transforms, or switching to tree-based methods often resolve this. I once spent three weeks debugging a supposedly broken model before realizing the underlying relationship was exponential. A simple log transform on the target variable pushed R2 from 0.31 to 0.84. The data never changed. Only the model shape did.
What R2 Can't Tell You
R2 has blind spots. It won't tell you if your model is overfitting. It won't catch biased residuals. It won't warn you about omitted variable bias. It also doesn't distinguish between correlation and causation, which is perhaps its most dangerous limitation. A high R2 combined with statistically significant p-values still doesn't mean your predictors actually cause the outcome. They might just be correlated with something else in the system. If you need to validate beyond R2, look at residual plots, cross-validated error metrics like MAE or RMSE, and information criteria like AIC or BIC for model comparison. R2 should be one data point in your evaluation toolkit, not the whole toolkit.
Get the Full Details