The Four Rs That Actually Matter in Research
Reproducibility, replicability, rigor, and robustness. Those are the R words everyone in science talks about now. They used to be footnotes in methodology sections. Now they're the entire point. Most people conflate them anyway. Reproducibility is getting the same computational result from the same data and code. Replicability is getting the same conclusion from new data collected under similar conditions. Rigor is how carefully you designed and executed the whole thing. Robustness is whether your finding holds when you tweak assumptions, models, or parameters. I spent three years trying to replicate a 2018 psychology paper that had become a textbook example of a "robust" social priming effect. The original authors published their data and code. I ran their analysis pipeline on my machine. Got a p-value of 0.14 where they had 0.003. Not even close. Turned out there was one line of R code that excluded three outlier participants whose behavior didn't fit the expected pattern, and the original authors had documented this exclusion in a supplementary file that wasn't linked from the main paper. I caught it by reading every single line of their github repository instead of just running their analysis script. This is why rigor matters more than any of the other R's. Without it, everything else is guesswork.
R Words In Science Radar Replication And Rigor Reshaping Research Reality
The "radar" framing isn't a formal academic term. It's shorthand researchers use to describe the systematic scanning of a field for these four qualities at once. Think of it as a quality control lens you apply before you trust any finding. Here's how to actually do it instead of just nodding along when reviewers mention it. Start by asking four specific questions about any paper you read, in this order. First, can the results be reproduced? Check if the data and code are available. If they aren't, that's a yellow flag. Not a death sentence, but you need to know you're taking the author's word for it. Second, can it be replicated? Look at the methods section for enough detail that you could theoretically run the same study. If the sample size is 23 people recruited from one university psychology department and the procedure involves a handshake protocol that's described in two paragraphs, replication is going to be nearly impossible. Third, is the rigor sound? Check for preregistration, power analysis, correction for multiple comparisons, and whether the effect sizes are reported alongside p-values. Fourth, is it robust? Run sensitivity analyses yourself if possible, or at least check whether the authors did. Did they test alternative model specifications? Did they control for reasonable confounds? Did they report what happens when you drop outliers? I use a simple checklist I built around this framework. It takes about ten minutes per paper. I track whether each of the four R's is clearly addressed, partially addressed, or not addressed. I rate papers on a three-point scale and sort them that way. Papers that score high on all four tend to hold up. Papers that score low on rigor but high on statistical significance are the ones that fall apart six months later. I've seen this pattern dozens of times across my work in cognitive science and behavioral economics.
Common Methods for Enforcing These Standards
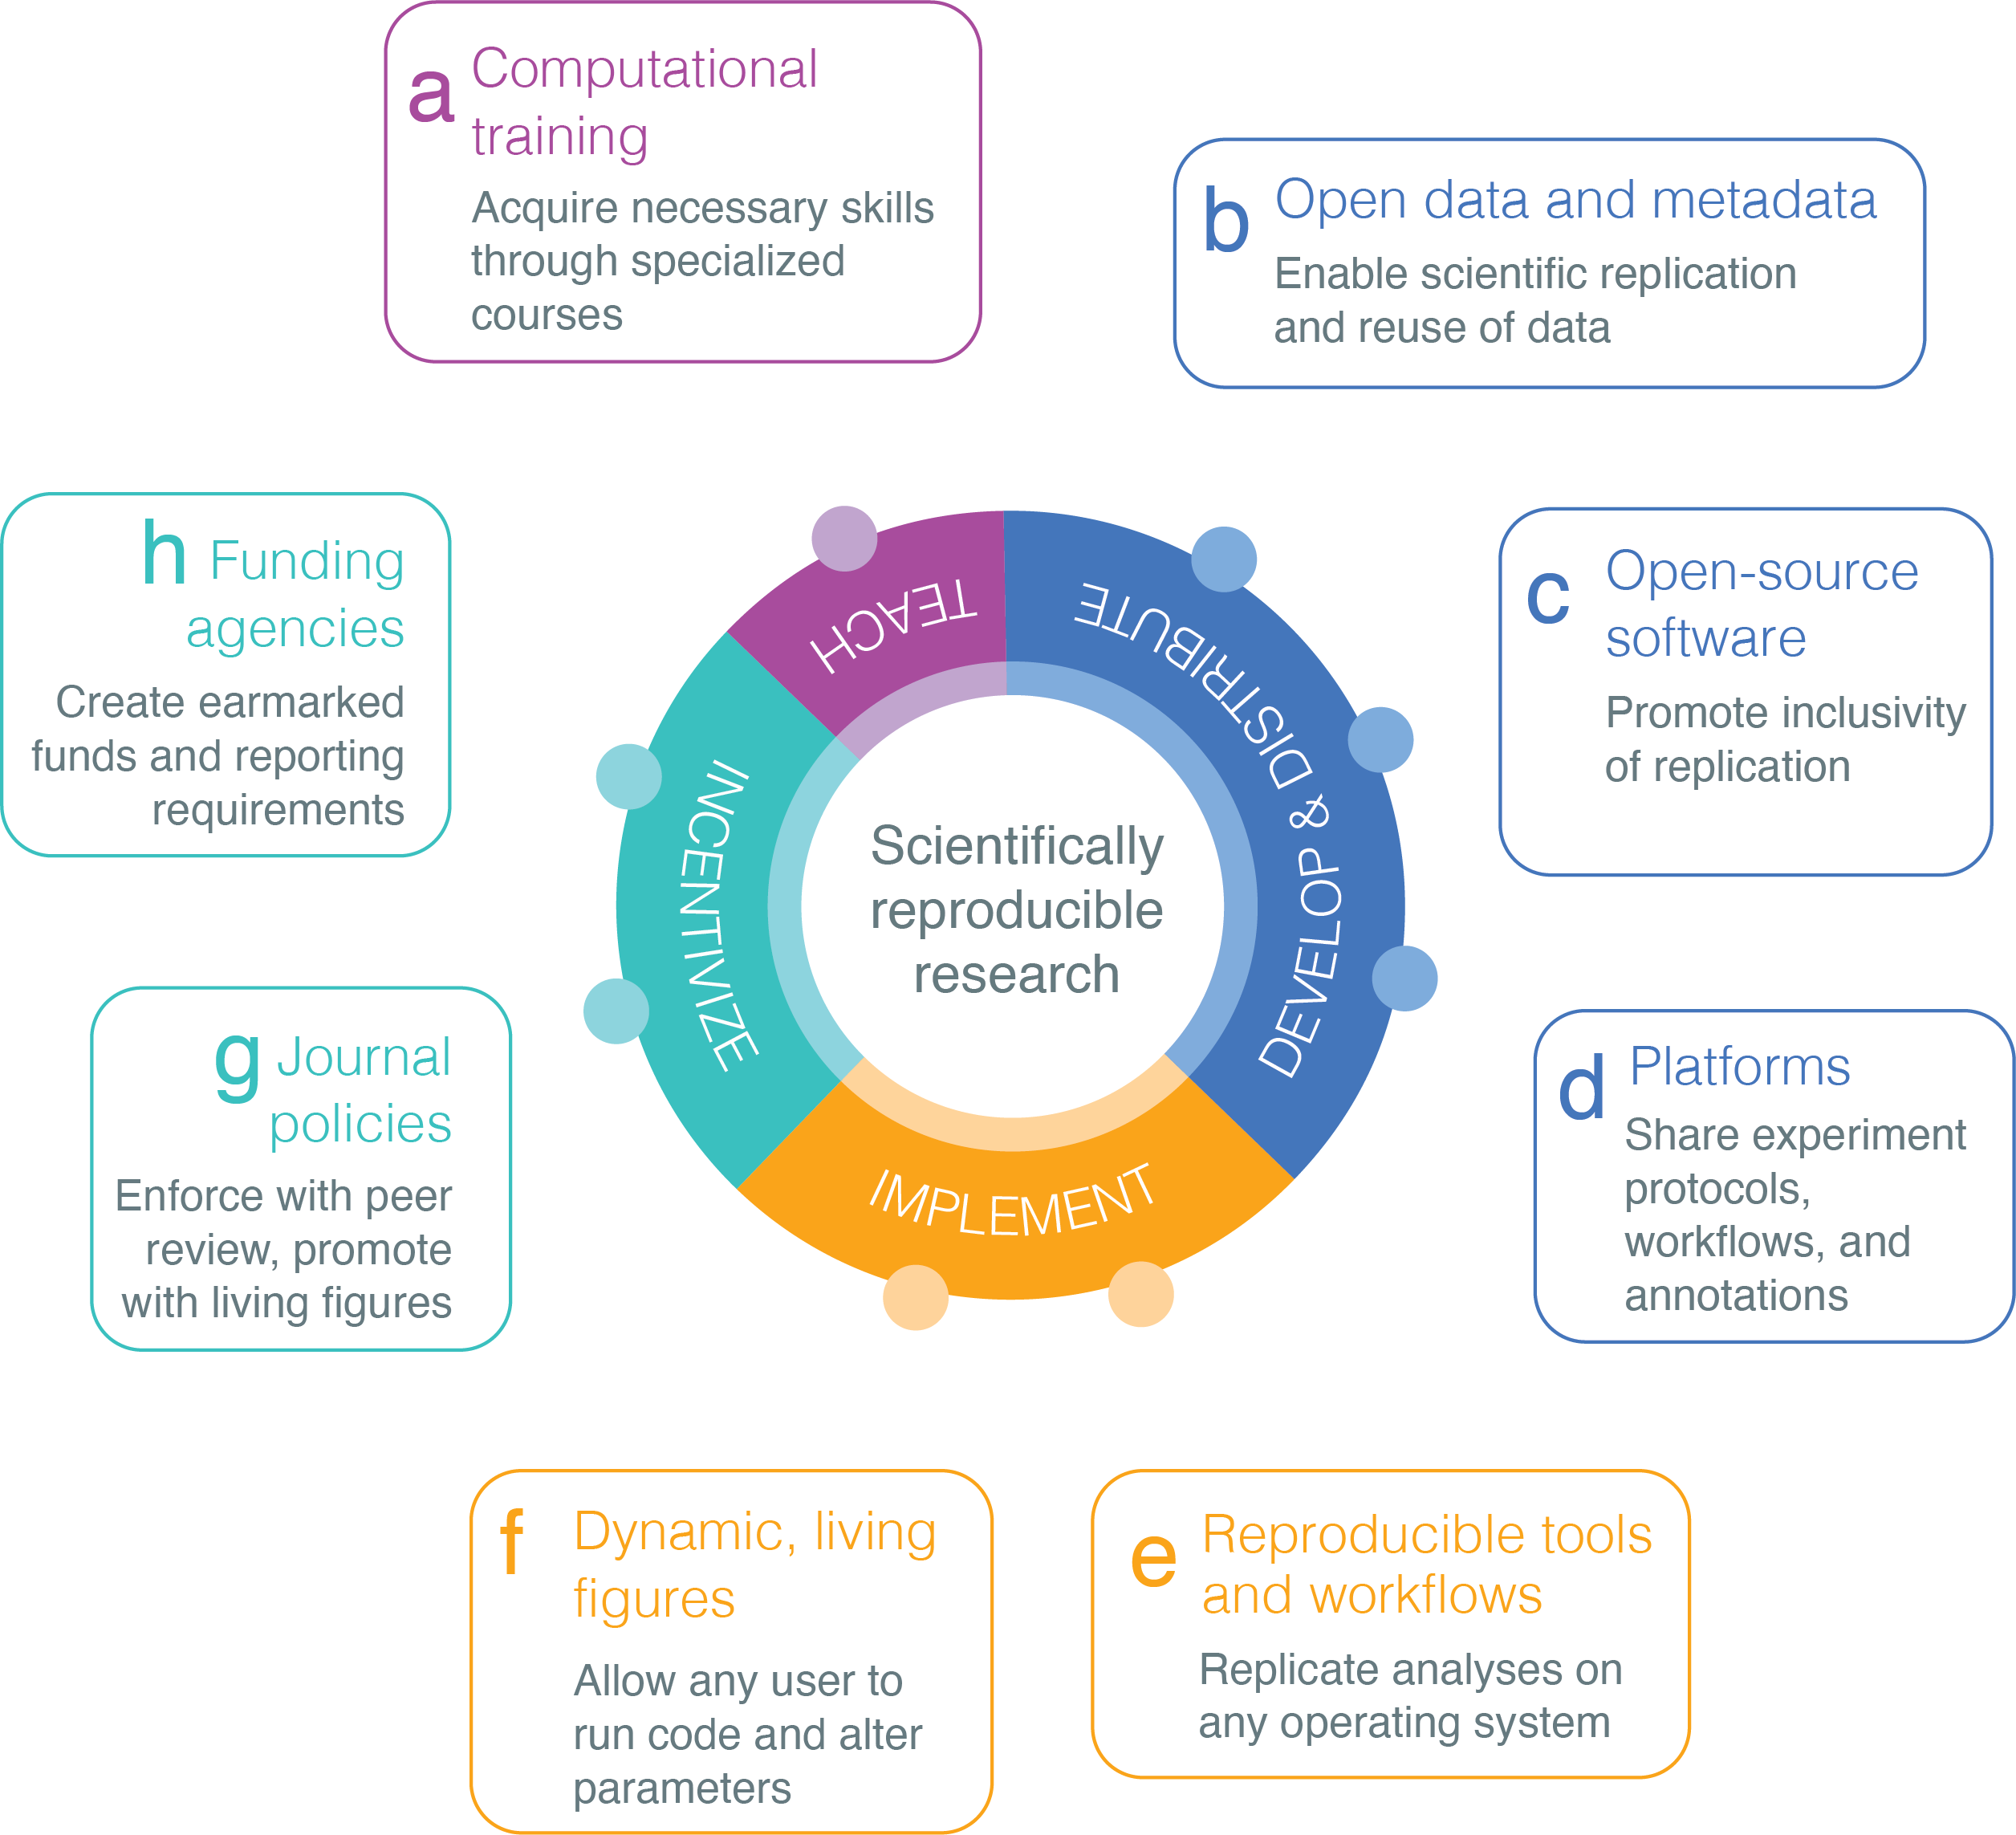
Preregistration is the biggest structural change in the last decade. You file your hypotheses, methods, and analysis plan with a timestamped record before you collect data. This prevents p-hacking and HARKing, which are the two practices that destroyed confidence in so many fields. Registered Reports are an even stronger version where journals commit to publishing your results regardless of whether they're statistically significant, as long as you followed your preregistered plan. The acceptance happens at the proposal stage, not the results stage. Open data and open code are table stakes now. Repositories like OSF, Zenodo, and GitHub have made this easier. The friction isn't technical anymore. It's cultural. Some fields still treat data as intellectual property or a competitive advantage. That mindset is fading but it hasn't disappeared. Power analysis deserves more attention than it gets. Most underpowered studies publish false positives because the statistical test lacks sensitivity. A rule of thumb that works reasonably well: if your study has fewer than 50 participants per group and you're measuring a small effect (Cohen's d below 0.3), you're probably wasting your time. The result will either be nonsignificant or significant by chance. There's no middle ground that means anything.
Get the Full Details

Where This Framework Breaks Down
Not every field can or should apply these standards the same way. Qualitative research operates differently. Case studies, ethnographies, and interpretive methodologies don't lend themselves to preregistration or direct replication in the quantitative sense. That doesn't make them less rigorous. It means rigor looks different. Trustworthiness, credibility, and transferability replace reproducibility and replicability as the relevant concepts. I've watched reviewers reject perfectly sound qualitative work because they applied quantitative R-standards to it. That's a category error, not a quality issue. There's also the problem of registered reports creating their own kind of bias. When journals accept studies at the proposal stage, there's a selection effect. Novel, high-risk hypotheses get rejected in favor of safe, incremental projects that look solid on paper. You end up with a literature that's methodologically rigorous but intellectually uninteresting. I've seen grant panels and hiring committees reward Registered Report publications over bold exploratory work, which slowly changes what kind of research gets done. That's a real cost. And robustness checks can become their own form of fishing. If you run enough variations of an analysis, something will look significant by chance. The solution isn't to avoid sensitivity analyses. It's to distinguish between preregistered robustness tests and exploratory ones, and to report all of them transparently. I usually annotate my sensitivity analyses with color coding in tables: green for preregistered, yellow for pre-analysis plan but not formally preregistered, and red for purely exploratory. It makes the distinction visible to anyone reading the paper.
A Working Example From My Own Research
Last year I was auditing a dataset for a collaborator who wanted to submit a replication study to a major journal. The original study had n=142, reported a medium effect size, and passed every methodological check I'd expect. When we reanalyzed the data using their published code, our results matched. Reproducibility check passed. Then we collected new data with a similar design but different recruitment. The effect dropped to half the original size and lost statistical significance. The replication failed, but the rigor was sound. Every step was documented, every decision was transparent, and the null result was worth publishing. That's the whole point of this framework. It's not about confirming what you already believe. It's about finding out whether what you believe is actually supported by evidence that survives scrutiny. The four R's aren't a grading system you apply to other people's work and move on. They're a discipline you apply to your own. The papers I'm most proud of are the ones where I caught my own errors before reviewers did. That usually happens when I run through this checklist myself before I even submit anything. It's slower upfront. It saves months of revision cycles later. And it produces work that actually lasts instead of disappearing into the replication graveyard that half of psychology and economics seems to have become.