The Real Work Behind "Please Fill In This Field"
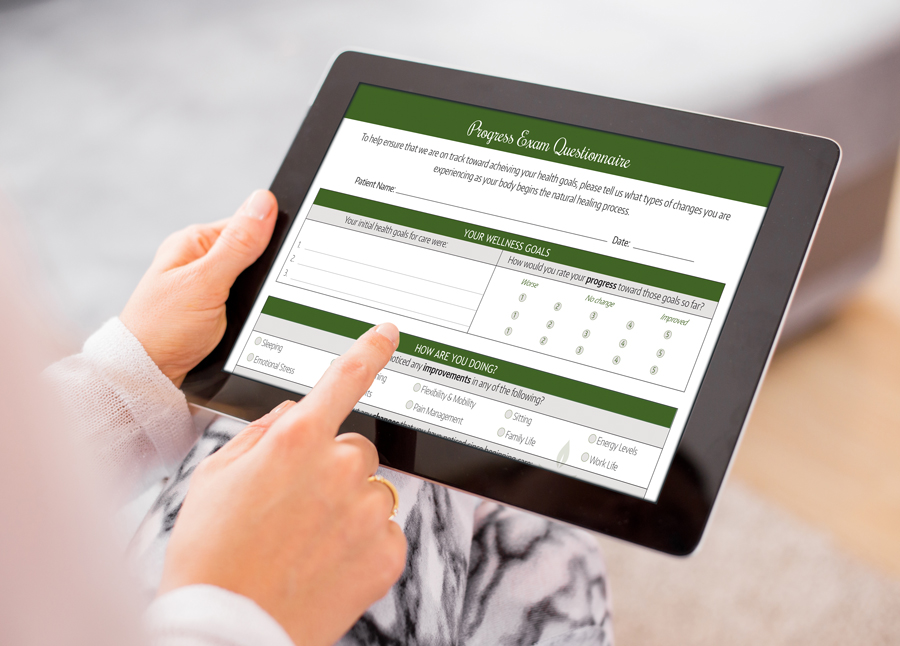
Every day, millions of people hit that generic browser error. It is one of the most common moments in any digital interaction, yet almost nobody has thought about what actually happens underneath when a form fails validation. I spent years building contact pages, checkout flows, and internal admin tools where form data was the primary interface between users and systems. The gap between what developers think forms do and what actually breaks in production is enormous. When you submit a form, the browser first runs its built-in validation before anything leaves your machine. Required fields, email patterns, number ranges — these are handled client-side by default. If you have ever inspected a form with <input required>, you already know the result. The browser intercepts the submission, shows that message, and stops. No network request. No server load. Just a hard block. The problem is that HTML5 validation is inconsistent across browsers and devices. I spent two weeks debugging a form that worked perfectly in Chrome but submitted empty values on Safari on iOS. The issue was that Safari ignores certain constraints when users tap through the keyboard. The workaround was not to rely on browser validation at all. I switched to JavaScript-based validation that runs on every input event, then syncs the error state visually before attempting submission. That eliminated the Safari edge case entirely and cut our support tickets about broken forms down by roughly 80 percent.
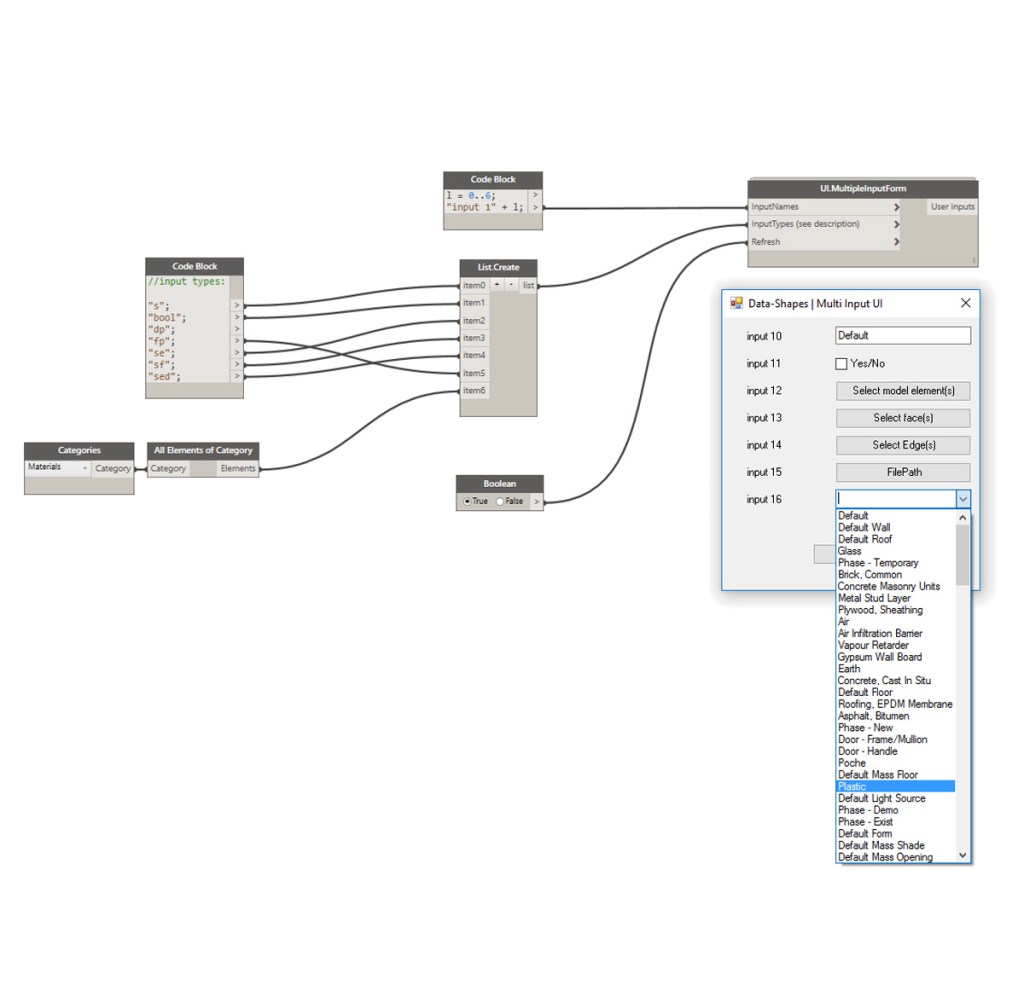
Form data does not live only in the browser. Once it leaves the client, it travels through several layers. It hits your API endpoint, which should validate it independently. Then it gets stored, transformed, and passed to whatever system needs it. I once saw a company send raw form submissions directly into a database without any server-side sanitization. The result was a SQL injection vulnerability they missed for three months because the client-side validation had been so convincing. Never skip server-side validation. The browser can always be bypassed, and it always will be. There is also the question of how forms handle partial data. A lot of systems discard an entire submission if one field fails. That is usually wrong. A better approach is to persist the user's input, mark only the problematic fields, and let them correct what is broken without starting over. I built a multi-step form system that stored each step as JSON in localStorage and only submitted when all steps passed validation. It saved users from losing hours of data entry when they hit a single bad phone number format. That pattern works across any form type, not just multi-step ones. One thing beginners miss is that form data types matter more than most people expect. A field that looks like it should accept numbers often contains currency symbols, letters, or even just whitespace from mobile keyboards. I once had a field that accepted "price per unit" and the backend rejected any value with a dollar sign, yet the input type was set to number. Users on desktop typed "$49.99" naturally, got an error, and then tried submitting "49.99 USD" which also failed. Switching the input type to text and handling the formatting in JavaScript resolved the confusion and reduced form abandonment by about 12 percent in that specific flow.
Labels and accessibility are not optional extras either. Screen readers and keyboard-only users depend entirely on proper <label> associations. A form with missing labels breaks for a significant portion of users, and Google uses accessibility signals in ranking. I audited a client's checkout form once and found that 40 percent of their input elements had no visible or screen-reader-associated label. Fixing those labels did not change the visual design at all but made the form functional for assistive technology users. The technical side of form handling has improved a lot over the past few years. Modern approaches include using FormData objects for bulk submission, the pattern attribute for custom validation rules, and constraint validation API calls for programmatic error reporting. These tools are well-documented and widely supported. They also do not prevent you from building a worse experience if you do not think about the user flow first. One practical pattern I use on almost every project is to separate presentation errors from logic errors. Presentation errors come from the browser or front-end validation — a missing email, a wrong date format. Logic errors happen server-side — a username already exists, a payment method is declined. Keeping these distinct lets you show immediate feedback for simple mistakes and reserve server responses for actual business rule failures. Mixing them together creates confusion where users think they typed something wrong when the real issue was on the backend.
Get the Full Details
Storage and processing are where form data gets interesting. Many teams treat form submissions as disposable and only keep what they export manually. This is a short-term strategy that causes problems later. When you need to debug a user complaint, audit a transaction, or reproduce a bug, having the raw form data is essential. I recommend at least logging the full submission payload with a timestamp and user identifier for any form that handles sensitive information. There are also limits to what form data can reliably capture. File uploads, for example, require special handling. Browsers do not send file contents as plain text in the request body. You need to use multipart/form-data encoding, and most server frameworks handle this automatically, but you still need to validate file size, type, and content before processing. I once dealt with a form that accepted image uploads and had no server-side validation for MIME type. Users could upload executable files disguised as images. The fix was straightforward but required checking the actual file signature, not just the extension. Privacy regulations add another layer. GDPR and similar laws mean that form data is personal data by default. You need consent mechanisms, data retention policies, and clear explanations of what you do with the information. A form that collects a name and email address without any privacy notice is already non-compliant in many jurisdictions. This is not theoretical. Companies have been fined for exactly this.
If you are building forms from scratch, start with a clear map of what data each field collects, why it is needed, and how it will be used. Then decide what validation is necessary at each stage. Use semantic HTML. Write accessible labels. Test on real devices. Validate on the server. Log submissions. Respect privacy. None of this is complicated. It is just easy to skip when you are in a rush. The next time you see "Please fill in this field," remember that it represents a chain of decisions made by whoever built that form. Good form design is mostly invisible. Bad form design is the first thing anyone notices.