Getting Your Database Work Done Without Losing Your Mind
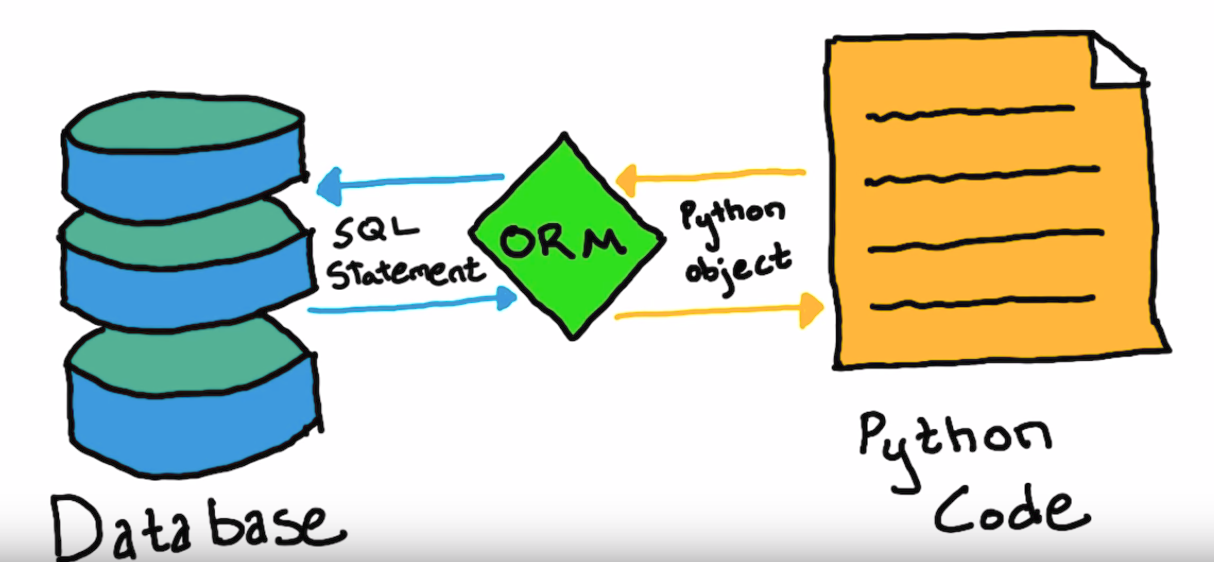
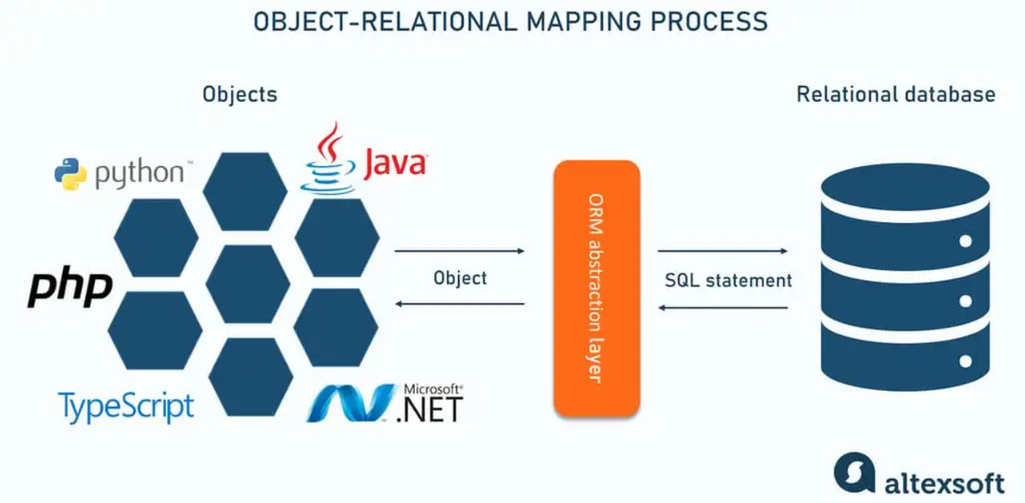
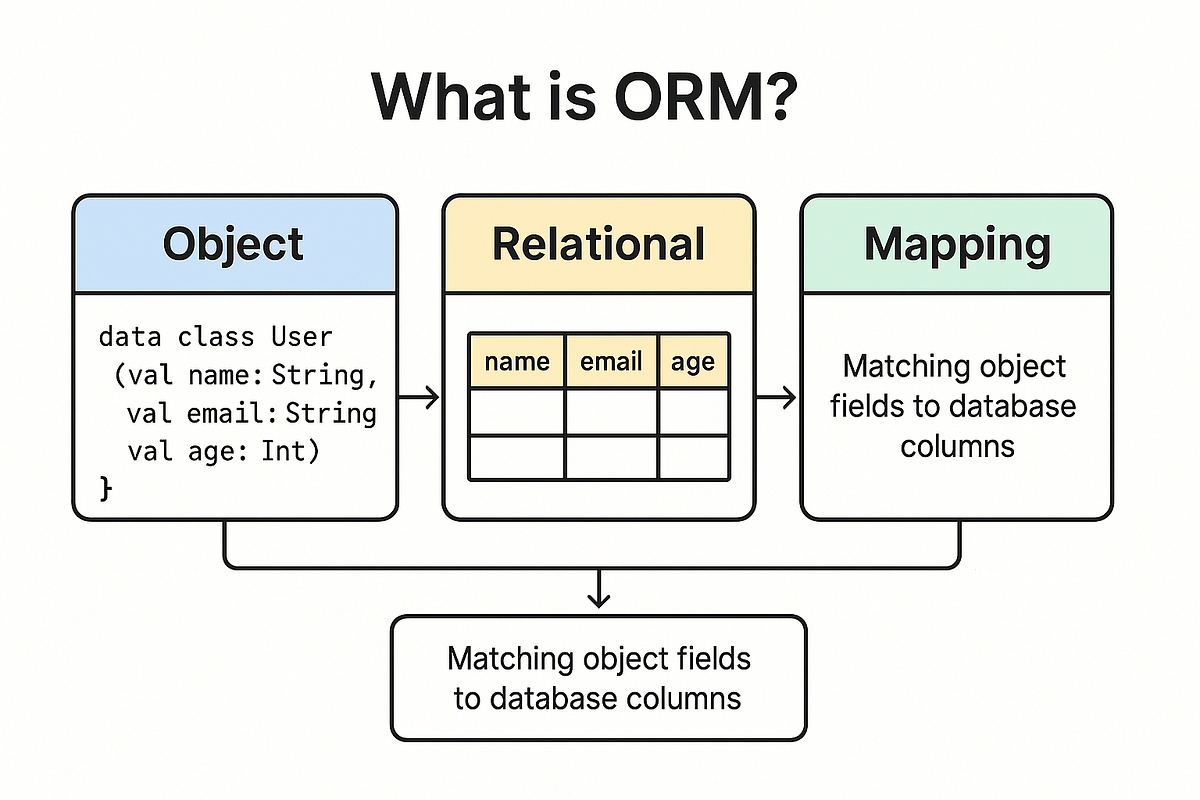
I spent three years building a custom data access layer for a logistics platform before I finally accepted that rewriting SQL by hand was making me slower, not faster. An Orm is just a tool that sits between your application code and your database. You write methods in your preferred language instead of strings of SQL. You trade direct control for development speed. The framework takes your object model and translates it into queries behind the scenes. Most people use this daily without thinking about it. A typical setup involves defining models as classes, mapping fields to table columns, and letting the library handle INSERT, UPDATE, and DELETE statements. The initial investment usually pays off after about a week of actual project work because you stop writing the same CRUD boilerplate over and over. Start by picking one library that matches your stack. If you are doing Python, look at SQLAlchemy or Django ORM. For Node.js, Prisma and TypeORM are the most common choices. The first step is always configuring your database connection string and creating a migration to set up your initial schema. Don't skip migrations. I have seen too many production incidents where someone pushed a model change without a migration and the app crashed on the first write operation.
Once your connection is working, define your first model. Keep it simple with just a few fields. Test that you can save a record and retrieve it. Then gradually add relationships. Many ORMs handle one-to-many and many-to-many through relationship declarations. You will usually write something like defining a foreign key and telling the ORM which table it references.
Where people get stuck and what actually works
The most common problem is N+1 queries. This happens when you load a list of records and then access a related object for each one individually. The ORM fires a separate query for every item in the loop instead of joining them. I ran into this with a reporting feature that was pulling inventory movements for a warehouse. The original code made over four thousand individual queries to load related supplier data. I added an eager loading call and it dropped to six queries total. The page went from fourteen seconds to under three hundred milliseconds. Another issue is overusing the ORM for complex analytics. Some operations are still faster in raw SQL. Aggregations across multiple large tables with conditional logic often run better as a prepared statement you execute directly. The ORM can generate incorrect or extremely slow queries if you ask it to do something that requires window functions or recursive CTEs without careful configuration.
Get the Full Details
Download and resources
Most ORM libraries are available through your language package manager. The official documentation sites have installation instructions and quickstart guides. I recommend installing the latest stable release and following the getting started tutorial before diving into advanced features. The community examples online are generally useful for common patterns, though they sometimes show older approaches that have been superseded. An ORM will not fix bad database design. If your schema has circular dependencies, missing indexes, or wrong data types, the ORM just makes it easier to write slow code faster. Performance profiling tools are still necessary. You should regularly check the actual SQL being generated, especially in production environments where query patterns differ from local testing. There are also edge cases with certain database features. Triggers, stored procedures, and specific transaction isolation levels may require dropping down to raw queries anyway. I had a situation where a PostgreSQL trigger was updating audit timestamps on every row modification, and the ORM's bulk update method completely bypassed it. The audit log ended up empty for any batch operation. I had to switch those operations to process records individually or write a custom query.
Choosing the right abstraction level matters. Use the ORM for standard CRUD operations where you want consistency and maintainability. Fall back to direct queries for anything involving heavy aggregation, complex joins, or database-specific features that the ORM does not support cleanly. This hybrid approach kept my team productive without leaving us dependent on the library for every database interaction.