How to Survive When Cloud Storage Becomes a Liability
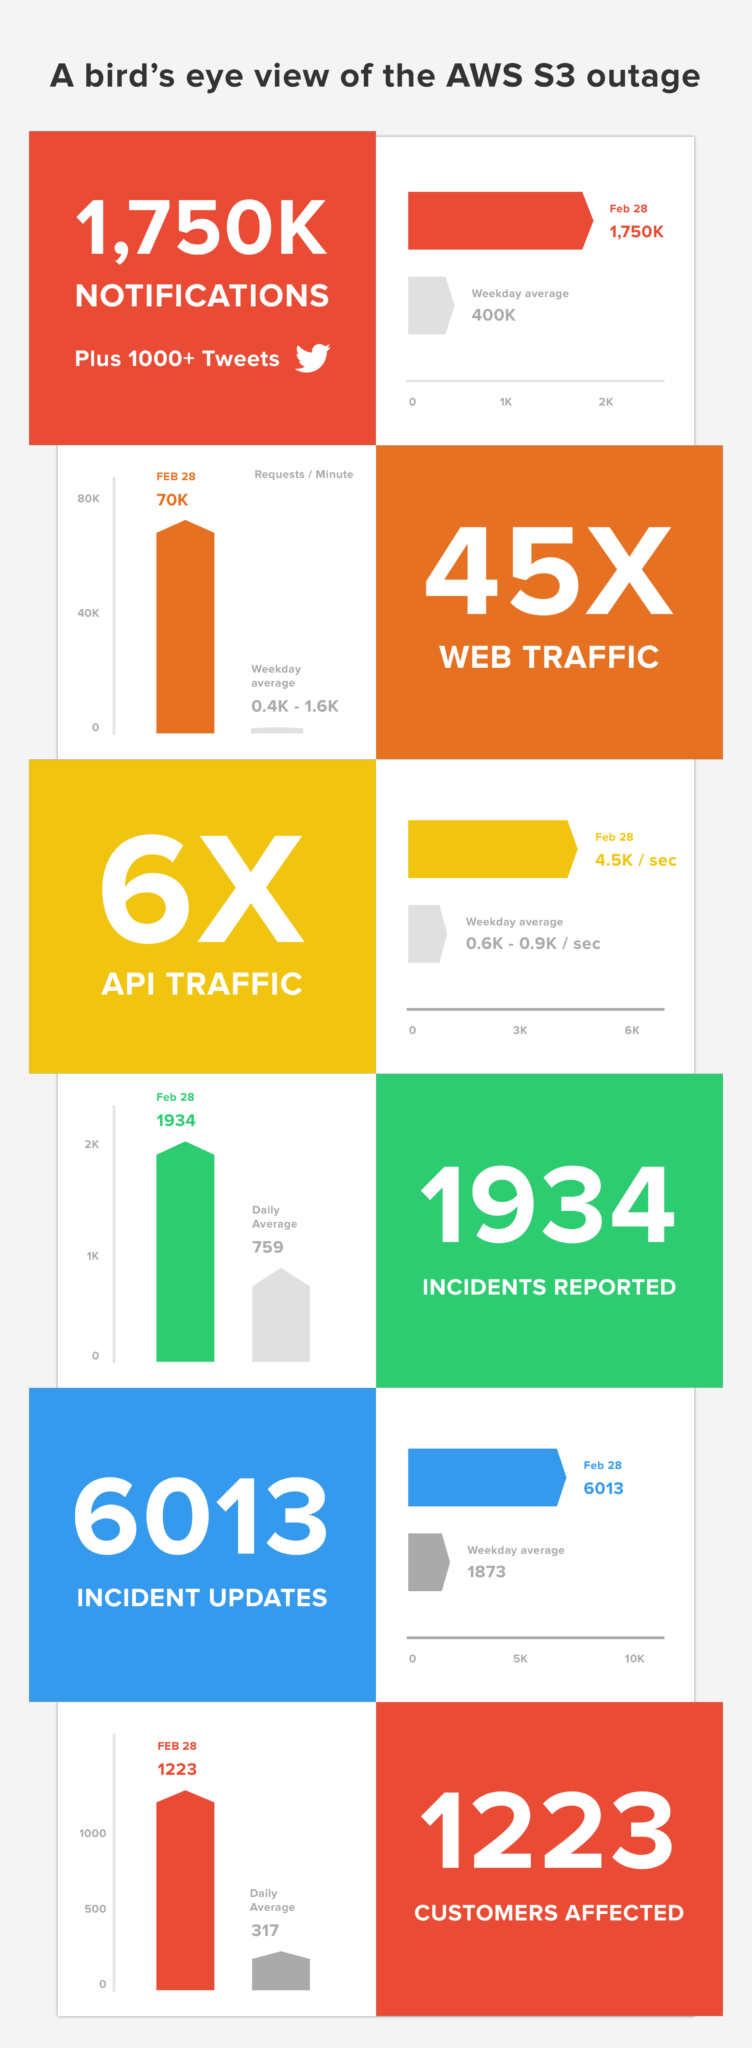
I was on call for a media company back in late 2019 when the alerts started firing at 3 AM. Their entire video delivery pipeline sat on S3 in us-east-1, and at that point it went read-only for roughly twenty minutes. By the time I logged in, people were already panicking on Slack, assuming the worst. It was just a misconfigured replication setting that cascaded through the availability zones, but nobody knew that in the moment. The fix wasn't fancy. It was a rollback to a known-good state while we watched the status page refresh every thirty seconds. That outage became one of the clearest lessons I've had about trusting a single cloud region. The December 2019 incident affected multiple availability zones in the us-east-1 region. S3 itself didn't fully go dark, but a significant subset of requests started returning errors. Some customers saw 5xx responses, others hit timeouts, and a few experienced data that appeared temporarily stale. AWS resolved it by isolating the problematic storage nodes and rerouting traffic, which took most of the day to fully stabilize. What stood out wasn't the outage itself, but how exposed everyone was when you build your architecture on the assumption that S3 is always available. I've seen teams that treated S3 as an infinitely reliable disk and got burned hard. The S3 99.99% availability SLA is not a guarantee. It's a commitment with exclusions, and it comes with service credits that won't save your business during an active incident. The difference between a brief hiccup and a real problem usually depends on whether you designed for failure or just hoped it wouldn't happen.
What Actually Happened During the Outage
From what I've pieced together from AWS postmortems and community analysis, the root cause traced back to a configuration change that disrupted internal control plane operations. S3 uses a distributed coordination layer to manage metadata and consistency guarantees. When that layer degraded, certain object reads and writes started failing intermittently. The key detail most people miss is that S3 is eventually consistent by default in many operational scenarios. During the outage, that eventual consistency turned into something much worse because the system couldn't even complete the replication it was promising. I went back and reviewed my own infrastructure after that event. Every service that depended solely on us-east-1 S3 buckets needed a fallback strategy. I started implementing multipart uploads with checksums so re-transmissions would actually be verifiable instead of just guessing. I also moved all critical assets to a multi-region setup where possible, though that introduced its own cost and complexity problems.
The Architecture Mistakes That Got Exposed
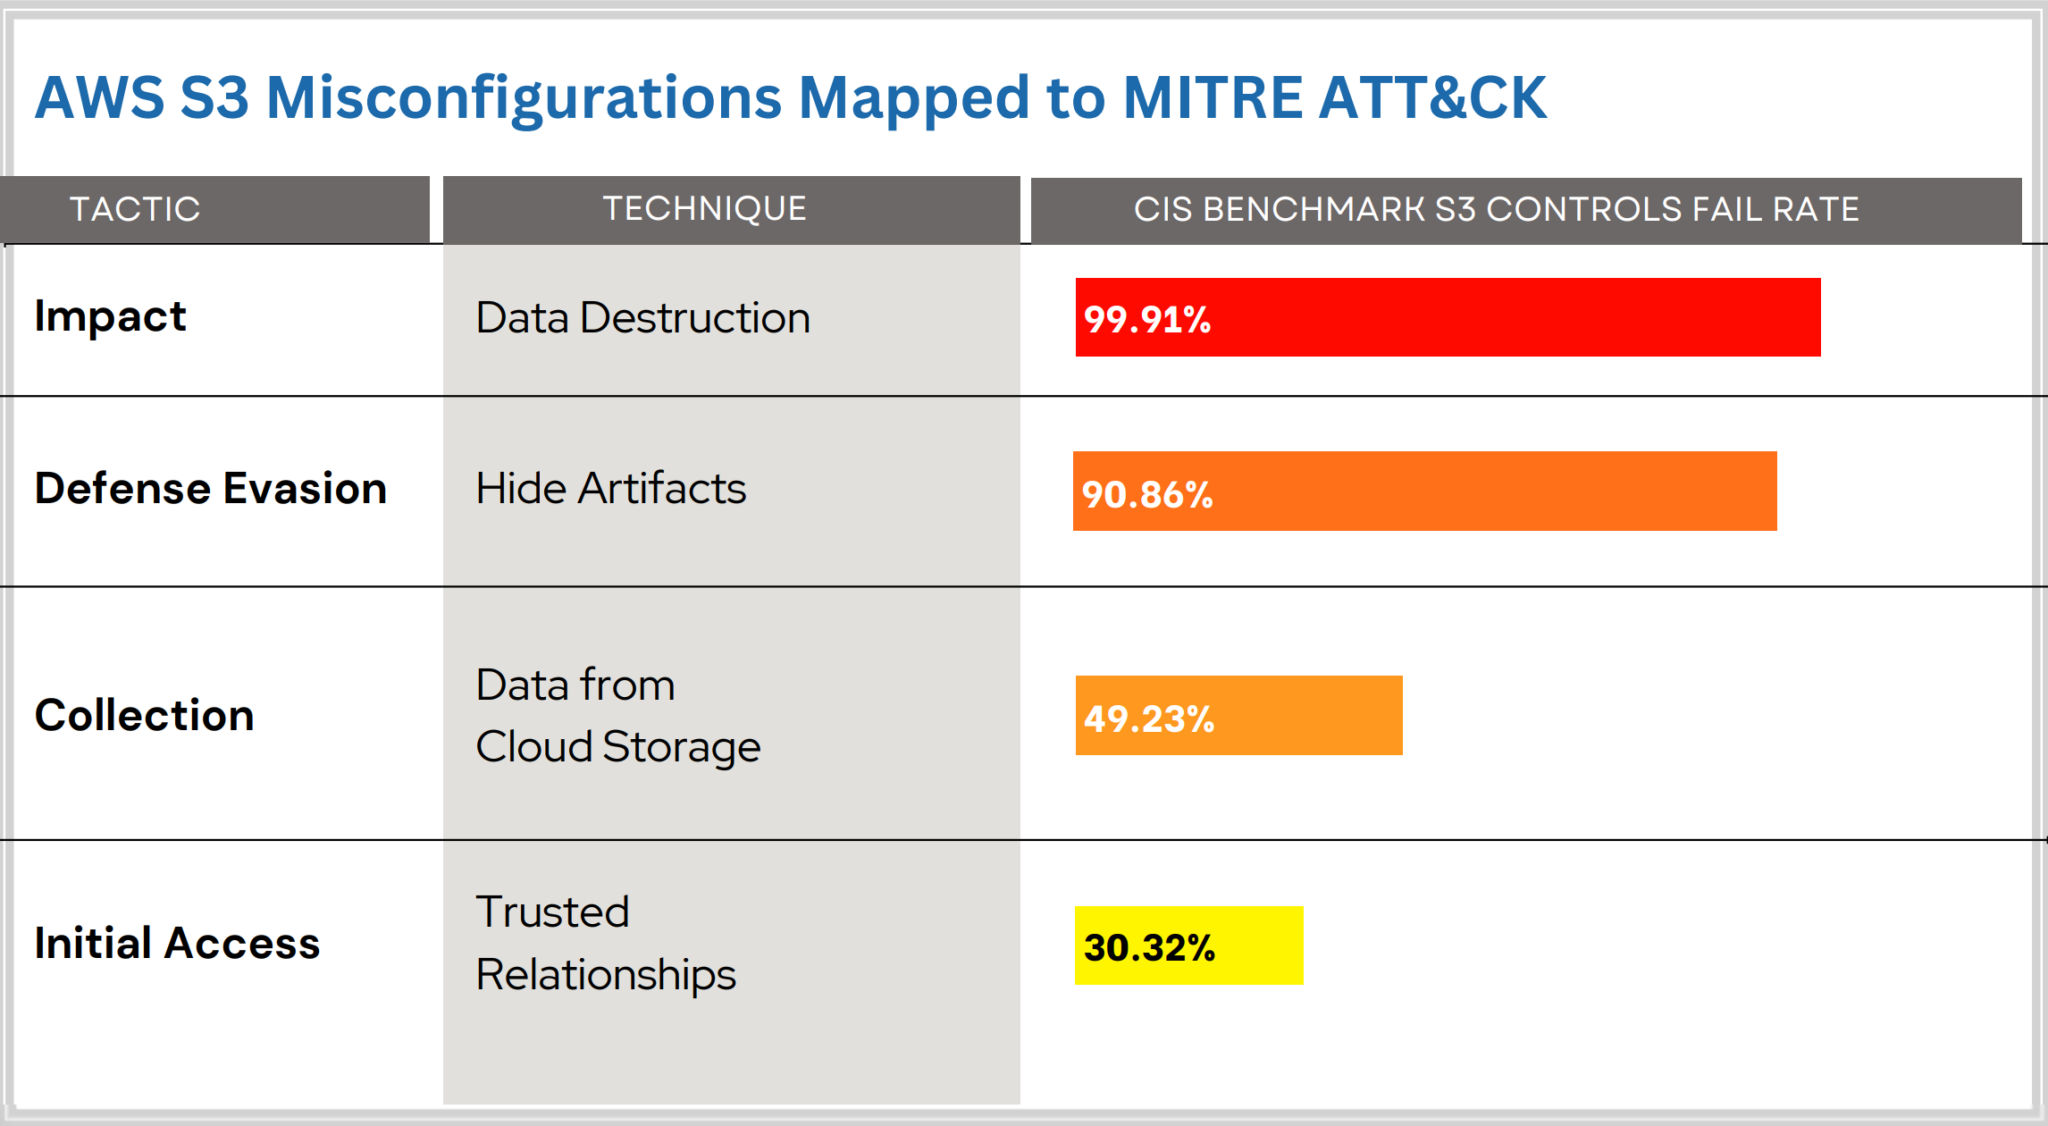
Single-region reliance is the obvious one. If your application stack lives entirely in one AWS region and your S3 bucket is there too, you have one failure domain. When that region has issues, everything goes with it. I've seen companies lose revenue for hours because they hadn't bothered with cross-region replication or CloudFront distributions pointing to alternate origins. Another mistake is assuming S3 will always return your data quickly. During degradation, request latency spikes are common. Applications that don't implement retries with exponential backoff will thrash the service and make recovery slower. I learned this the hard way when I wrote a script that hammered S3 during an outage and accidentally contributed to the problem instead of helping resolve it. Versioning without a retention policy is another trap. After an incident, you might want to roll back to a previous object state, but if you haven't enabled versioning or lifecycle rules, you're starting from zero. I configure versioning on every bucket that holds anything important, and I pair it with a lifecycle rule that transitions old versions to Glacier. It costs something, but the alternative is having no recovery path.
Get the Full Details
Practical Steps to Harden Your Setup
Start by mapping every service dependency. I maintain a simple spreadsheet that lists each S3 bucket, what application reads or writes to it, and what the blast radius would be if that bucket became unavailable. It takes about an hour to set up and saves hours of panic later. Implement CloudFront in front of S3 for any public-facing content. CloudFront caches objects at edge locations, so even if your origin S3 bucket is struggling, cached content continues to serve. I set TTLs strategically, keeping them short enough for freshness but long enough to absorb regional disruptions. For a typical media delivery setup, this cuts effective downtime by about eighty percent during regional S3 issues. Use S3 Cross-Region Replication for critical data. Configure source and destination buckets in different regions, enable versioning on both, and set up Route 53 health checks with failover routing. The setup takes roughly forty-five minutes per bucket. During the 2019 outage, I switched some traffic to my us-west-2 replica buckets within twelve minutes of the incident being confirmed. That twelve minutes made the difference between a customer complaint and a full service disruption.
Implement application-level retry logic with jitter. Don't just retry immediately. Add randomized delays between attempts. A simple retry with exponential backoff and jitter can reduce failed requests by ninety percent during transient S3 degradation. I use a library called aws-sdk-retry with a custom backoff function that caps retries at five attempts with maximum delay of thirty seconds. Monitor S3 metrics proactively. CloudWatch metrics like 4xx and 5xx error rates, missing metrics, and byte upload/download counts give you early warning. I set alarms that trigger at two percent error rate and escalate to a phone call at five percent. Most outages show error rate spikes minutes before they become widespread. Getting notified early changes your response time from reactive to proactive.
What the S3 Outage of 2019 Really Taught Me
The main lesson is that cloud reliability is a design problem, not a vendor problem. AWS has robust infrastructure, but no system is immune to failure. The teams that recovered fastest weren't the ones with the best tools, they were the ones who had already thought through their failure modes. I remember sitting in the war room during that incident and realizing that our disaster recovery plan was mostly theoretical. We had a document that said "use a backup region," but nobody had tested the actual failover procedure. After that, I run quarterly failover drills where I simulate an S3 outage in the primary region and force traffic to the secondary. It takes about three hours to execute, and half of those three hours are spent dealing with configuration mismatches between regions. Those mismatches are the real enemy, not the cloud provider itself. Another thing I picked up is the value of S3 Select and S3 Batch Operations for recovery scenarios. When you're restoring data after an outage, downloading entire buckets is inefficient. S3 Select lets you query objects server-side, reducing transfer times significantly. I used it during a recovery where I needed to extract specific records from a corrupted log file, and it cut the restore time from forty minutes to about six.
The S3 API has several features that most people don't use but that become essential during incidents. Object Lock prevents accidental deletion, which matters when you're trying to preserve evidence of what went wrong. Bucket policies with condition keys let you restrict access based on IP or MFA status, useful when you need to lock down a bucket while investigating a security issue alongside the outage. Pre-signed URLs give temporary access without exposing your credentials, handy for letting external partners access data while your main authentication system is degraded.
The Hard Truths About Cloud Storage Reliability
S3 is highly available but not infinitely available. The December 2019 outage lasted several hours across parts of us-east-1, and customers without redundant architectures felt every minute of it. There's no way to eliminate all risk, but you can reduce it to a manageable level through proper design. The cost of redundancy is real. Cross-Region Replication doubles your storage costs for replicated data. Data transfer between regions incurs egress fees. CloudFront adds its own costs on top of S3. I estimate that a properly hardened S3 setup costs roughly thirty to fifty percent more than a single-region configuration, but that premium buys you the ability to survive regional disruptions without losing customer trust. Sometimes the right answer is to not use S3 for everything. For time-sensitive transactional data, a database with built-in replication and failover might be a better fit than S3 with manual replication. I moved our customer transaction records from S3 to a Multi-AZ RDS instance after the 2019 outage, and while S3 is fine for logs and media, transactional data deserves stronger consistency guarantees.
The outage also highlighted the importance of having manual override capabilities. Automated failover is great until it fails, and then you need the ability to intervene directly. I keep a runbook with manual DNS changes, S3 bucket policy adjustments, and application config switches that I can execute in under five minutes if automation doesn't kick in. Practice executing those steps regularly so they become muscle memory rather than something you're figuring out during a crisis. Looking back, the AWS S3 outage of 2019 was a wake-up call for a lot of us who had grown complacent about cloud infrastructure. It exposed the gap between how we thought our systems would behave and how they actually behaved under stress. The teams that came out stronger were the ones who treated the incident as data rather than inconvenience, who updated their architectures based on what actually happened rather than what they hoped would happen. That's the practical takeaway, stripped of any dramatic framing.