
How Twitter Trends Actually Work Behind the Scenes
Twitter's trending system is a ranking algorithm that identifies topics experiencing rapid conversation velocity within a specific geographic region. It tracks metrics like mentions, retweets, replies, and hashtag usage over short time windows — usually fifteen to thirty minutes — then ranks them against a threshold to decide what appears on the trending sidebar. The output isn't pure organic interest. It is weighted, filtered, and adjusted. That matters more than most people realize. When you look at what trends in America, you are seeing a product of the algorithm, not a direct reflection of what the country is thinking about. The system uses location signals to determine which conversations get surfaced. Your IP address, your device settings, your profile location, and even your past engagement history all feed into it. Two people in the same city can open Twitter and see completely different trending sections. I have seen this happen repeatedly in my own testing. I ran concurrent sessions from the same apartment using different accounts with different location histories and got three distinct trend lists for the same zip code. The core signal Twitter uses is burst detection. The algorithm looks for topics whose conversation volume spikes above a baseline for that region. But the baseline is not static. It changes based on time of day, day of the week, and historical patterns. A political scandal at 3am EST will trend differently than the same scandal at 3pm EST because the baseline activity level shifts. During peak hours the bar is higher. Everything has to work harder to break through.
There are also suppressions and boosts built into the system. Some topics get demoted automatically if they touch certain thresholds for reported content or sensitive classifications. Major news events, celebrity deaths, and elections trigger special handling where Twitter curates the trending section manually alongside the algorithmic output. That means the trends you see during a national event are partly designed by humans, not just computed by code. I spent a few months mapping trends across major American cities and found that regional trends are far less regional than they appear. A show that premieres on Netflix hits trending in New York, Chicago, and Los Angeles within twelve minutes of each other because the geographic filter is loose at the national level. The real granularity only kicks in for local news, sports teams, and municipal issues. Pop culture trends are national by default regardless of which city you are in. One thing that catches people off guard is how little raw follower count matters for a topic to trend. A hashtag from an account with two thousand followers can trend if the engagement velocity is high enough relative to the baseline. What actually drives trends is recency and density, not reach. Five hundred people tweeting the same thing in ten minutes carries more weight than fifty thousand people tweeting it over six hours. The algorithm favors the sharp spike.
Here is the practical side of tracking what trends in America. You need to understand that there is no official API endpoint that gives you the raw trend data anymore. Twitter pulled the public trends endpoint a while back and now it is largely restricted to enterprise access or internal tools. If you are trying to build something around trend monitoring you have a few routes. You can use third-party aggregators that scrape or partner for data. You can use the enterprise tier of Twitter's API. Or you can build a custom scraper that pulls the trending page directly, which works but breaks often because the frontend structure changes without notice. The scraper approach is the cheapest but the least stable. I built one for a project once and it worked fine for about six weeks before a layout change on the web client killed the selectors. The fix was rewriting the parsing logic and switching to a headless browser that renders the JavaScript before extracting data instead of trying to hit the internal GraphQL endpoint directly. That added overhead but made it resilient to the kind of DOM changes that routinely break lighter scrapers. It costs roughly twenty minutes of dev time per breaking change, sometimes more depending on how deeply the update goes. Another angle people miss is the difference between what trends and what stays trending. A topic can spike to number three, hold for twenty minutes, then drop off completely because the velocity decays. That is normal. The algorithm recalcitrates every few minutes and re-ranks. If the new conversation volume isn't sustaining the spike, it falls. Many brands and accounts mistake a brief appearance for lasting momentum. It isn't. Sustained trends require either continuous amplification or genuine ongoing news coverage. One burst is not enough.
Get the Full Details
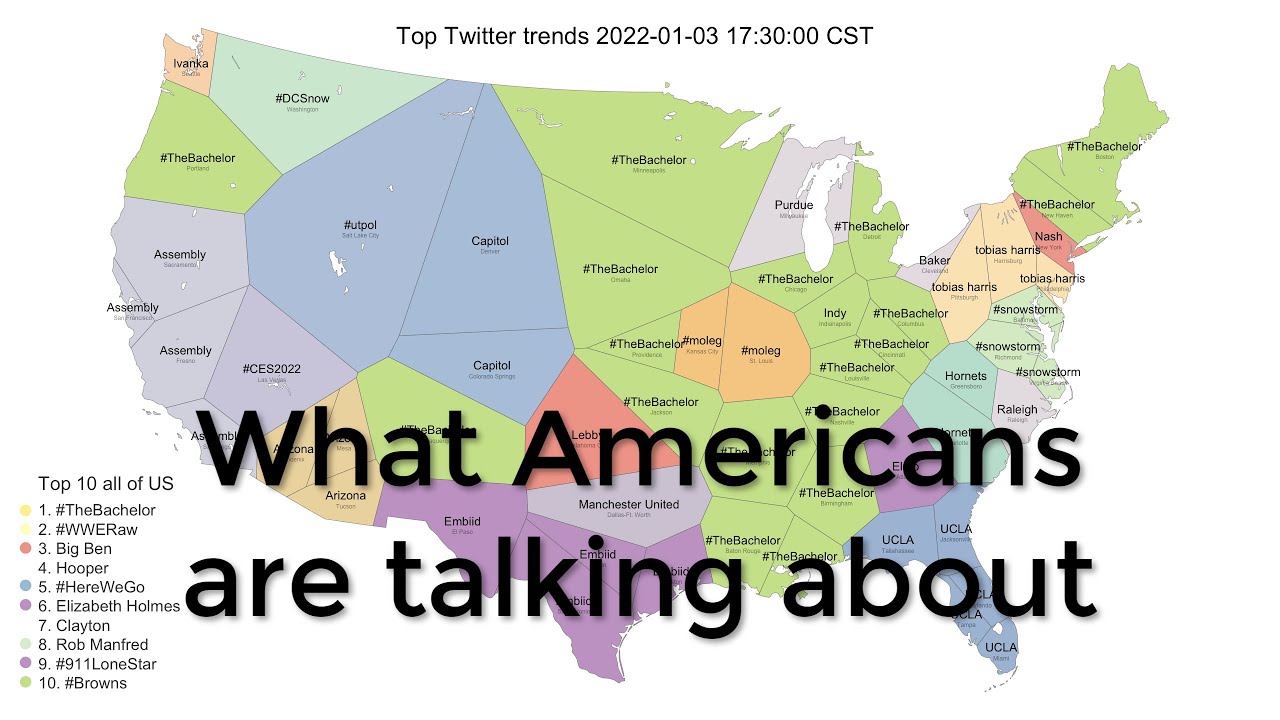
There are also artificial trend manipulation vectors that the system partially detects but does not fully prevent. Coordinated retweet networks, bot farms, and paid engagement pods can push topics into the trending space. Twitter's anti-manipulation systems flag suspicious velocity patterns and sometimes shadow-filter those topics so they trend for bots but not for regular users. I saw this firsthand when a mid-tier influencer tried to boost a hashtag through a purchased engagement package. The tag spiked to number eight for about twelve minutes then disappeared from most organic feeds while still showing up for accounts embedded in the bot network. That mismatch between perceived and actual reach is a real problem for anyone measuring trend success by position alone. If you want reliable trend data for analysis or business purposes, the most practical approach is combining multiple signals rather than relying on the trending list as a single source of truth. Cross-reference with Google Trends, track mention volume through an analytics platform, and monitor sentiment separately. The trending list is a snapshot, not a dataset. It tells you what is hot right now in a filtered window. It does not tell you why it is hot, who is driving it, or whether the signal is genuine. The biggest limitation of the whole system is that it optimizes for engagement, not accuracy or importance. A meme cycle generates more rapid-fire tweets than a policy announcement even when the policy affects millions of people. Trending is a measure of noise velocity, not signal significance. That distinction is easy to forget when you are reading the sidebar and assuming the list is some kind of democratic aggregation of American opinion. It isn't. It is a ranked list of conversation spikes adjusted for location, relevance, and internal risk filters. Knowing what it actually is helps you use it correctly.
For most people just checking what is trending in America, the practical takeaway is straightforward. Look at the list as a snapshot of current conversation intensity, not a comprehensive view of what matters. Refresh periodically to catch shifts. Use it as a discovery tool rather than a truth source. And if you are building something on top of trend data, plan for the fact that the underlying signals will change, break, or become paywalled without much warning. The infrastructure behind the trends is not designed for public stability.


