Starting From Space and Ending in Mud
The workflow begins with satellite imagery, usually from Landsat 8/9 or Sentinel-2 for most practical purposes. Both offer 10-30 meter resolution and free access through USGS EarthExplorer or Copernicus Open Access Hub. I grab the data, check cloud cover percentages, and download the Level-2 Surface Reflectance products if I'm doing vegetation or land cover work. Anything less than that and you're working with top-of-atmosphere values that will waste your time later. After the satellite data lands on your drive, the next step is processing it in something like QGIS. Free, open source, and it handles GeoTIFFs without complaint. You'll do band math here—NDVI calculations, classification routines, change detection across time series. The tricky part is geometry and projection. If you're working across multiple UTM zones or mixing datasets from different sources, your analysis will drift unless you reproject everything to a consistent CRS early. I learned that the hard way on a project spanning three counties with overlapping Sentinel tiles. Two weeks of cleanup. GIS software isn't the only tool at this stage. Python with rasterio, geopandas, and xarray handles batch processing better than any GUI application when you need to automate workflows across dozens of scenes. A single script can pull, mosaic, clip, and classify a year's worth of imagery in the time it takes to brew coffee, assuming your machine has enough RAM to hold the rasters.
Ground Truthing
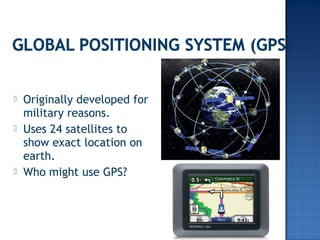
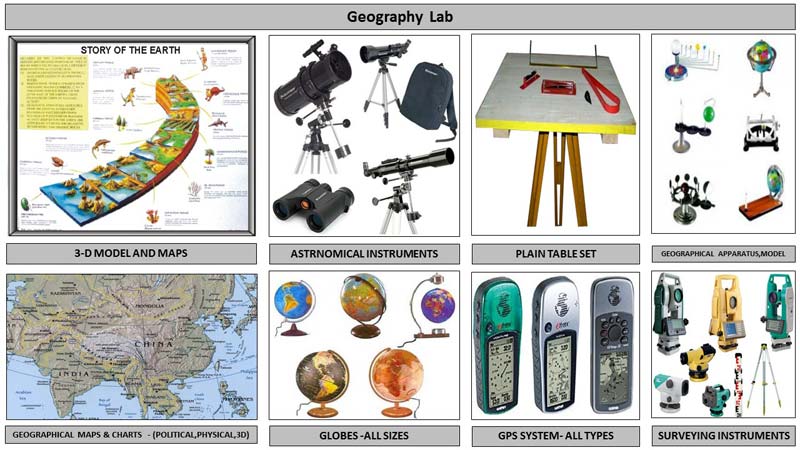
Satellite data alone is insufficient. You need ground truth, and that means heading outside with a GPS unit and a notebook. I use a Garmin GPSMAP 66i for field work—it holds a charge for days, maps well on solar, and logs waypoints reliably. The cheaper units are fine for basic work, but multipath error in valleys and dense canopy will cost you positional accuracy measured in meters, which matters when you're trying to match ground points to satellite pixels. My notebook setup is deliberately analog. A Rite in the Rain book and a mechanical pencil. Electronics fail in rain, cold, and humidity, and I've lost more field data to dying tablets than I care to admit. I sketch transect routes, mark sample locations, record observations by hand, then digitize them back at camp using a scanner or phone camera with a reference scale. It adds a step, but it's a step I won't skip. For more precise work, I carry a Trimble XRS+ RTK GPS. It costs roughly $12,000 and takes ten minutes to set up relative to the Garmin, but it gives centimeter-level accuracy. When you're verifying feature boundaries or validating classification results against sub-meter ground control, the investment pays off fast. When you're just collecting point samples for general land cover validation, the Garmin does the job.
Bridging the Scale Gap
One of the hardest parts of this workflow is reconciling the scale difference between satellite pixels and what you actually observe on the ground. A 30-meter Landsat pixel might contain a forest edge, a road, and a clearing all at once. Your ground observation is a single point. This mismatch causes classification errors that inflate confusion matrices and make validation metrics look worse than they should be. I account for it by collecting at least five ground points per pixel rather than one, and I note the dominant land cover type within a buffer zone around each point instead of treating it as a purely local measurement. Another practical problem: atmospheric conditions on ground-truthing days rarely match satellite overpass conditions. I had a situation where my field observations suggested heavy leaf-off conditions in a deciduous stand, but the Landsat image was captured two weeks earlier during full canopy. The spectral signatures didn't align, and my initial validation flagged the satellite classification as wrong when the problem was purely temporal mismatch. The fix was checking the satellite acquisition date against my field date and adjusting my validation window accordingly, or finding a closer imagery pass if the timing gap was too large to correct.
Get the Full Details
Structuring the Full Workflow
The full pipeline runs from data acquisition through final maps, and it's modular enough that you can swap tools at any stage depending on your budget and computing resources. Start with scene selection. Filter by cloud cover—anything over 15 percent is usually problematic for visual interpretation and can introduce artifacts in classification. Download both the red and near-infrared bands at minimum; they're the foundation for most vegetation indices. Preprocessing involves atmospheric correction if you're using Level-1 data, orthorectification to handle terrain displacement, and mosaicking if your study area spans multiple tiles. For a typical 100 by 100 kilometer area, you're looking at roughly 40 Sentinel-2 tiles that need to be stacked and blended at the edges to avoid visible seams.
Field collection happens next. Establish your transects or grid before heading out. I prefer a stratified random approach—divide the study area into land cover classes from a preliminary satellite classification, then randomly place points within each class. This prevents oversampling the easy-to-identify areas and undersampling the ambiguous ones. Total time in the field varies wildly. A small watershed study might take two days. A regional land cover validation project could stretch into weeks. Data integration brings the satellite and ground data together. Georeference your field notes, merge point layers with your processed imagery, run accuracy assessments using your ground control points. Confusion matrices, overall accuracy, kappa coefficients—these are the standard metrics. Be honest about the results. If your validation shows 68 percent accuracy, don't present it as 85 percent because you cherry-picked the easier land cover classes.
Common Mistakes That Wreck Projects
Beginners consistently underweight preprocessing. Skipping atmospheric correction because it's optional for Level-2 data is fine, but skipping geometric correction because "the satellite already corrected it" is not. Terrain-correlated shadow effects remain in many products, and they'll bias your classification in mountainous regions. Always check thehillshade version of your DEM alongside the imagery before classifying. Another issue is insufficient ground samples. A classification with 95 percent confidence intervals wider than 15 percent is essentially useless for most mapping purposes. If your validation points number fewer than thirty per class, your accuracy estimates are unreliable. This is especially true for rare classes—roads, water bodies, developed land often get enough points, but transitional zones like shrubland or disturbed forest are where projects typically fall apart. Remote sensing also fails in persistent cloud environments. The Amazon basin, the Pacific Northwest during certain seasons, coastal fog zones—optical satellites simply cannot penetrate thick cloud cover. In those cases, SAR (Synthetic Aperture Radar) from Sentinel-1 becomes necessary. It costs the same as optical data and goes through clouds, but interpreting radar backscatter requires different training and a different skill set. The learning curve is steeper, and the output is less intuitive. I've spent more time troubleshooting SAR phase unwrapping artifacts than I'd like to acknowledge.
What Stays in the Field
Not every geographic question requires satellite data. Sometimes the best tool is a hand lens, a soil auger, and a topo map. I've worked with colleagues who built entire models on satellite-derived vegetation indices only to discover their key variable—soil moisture—was invisible to the sensors they were using. The satellite told them what was green. It didn't tell them why. The field notebook captures context that no sensor records. Microtopography, species composition, disturbance history, human modifications. These details matter when you're trying to explain patterns that satellite imagery can show but not cause. A dead tree crown looks the same spectrally whether it died from drought, beetle infestation, or construction damage. Your ground observation determines which explanation fits. Combining the two scales—satellite for extent and pattern, field work for mechanism and detail—is where the method actually works. Neither alone is sufficient, and treating one as a replacement for the other is a common shortcut that produces publishable but fragile results. The tools are straightforward. The discipline of using both correctly is what separates adequate mapping from work that holds up under scrutiny.