Getting Your New Jersey Infrastructure Time-Synced Properly
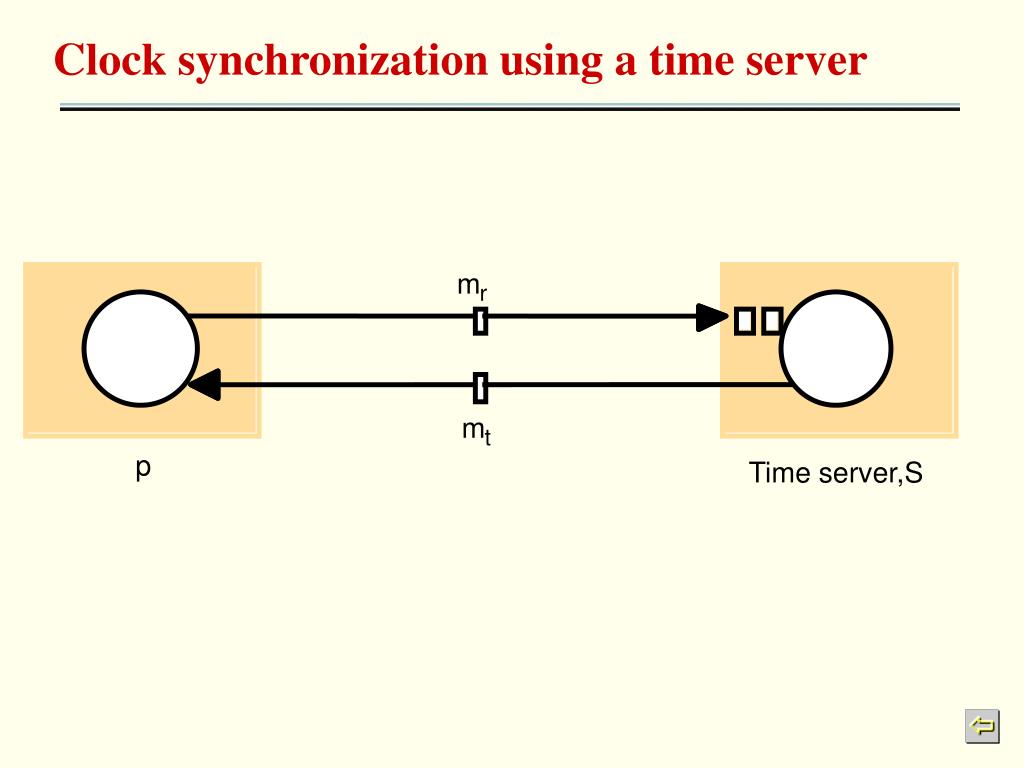
New Jersey runs on Eastern Time, same as everything from Delaware to Florida. The actual question here is how do you make sure every server, router, and endpoint across the Garden State agrees on the exact same moment down to the millisecond. I've spent years dealing with this because when you're running distributed systems out of data centers in Newark and Jersey City, even a few hundred milliseconds of drift causes real problems. Logs don't line up. Payment timestamps get disputed. Replication chains break for no obvious reason and then you spend three hours wondering what happened. The phrase itself is a mouthful, but the core idea is straightforward. It's about taking a local New Jersey network and forcing every device on it to reference the same authoritative time source with enough accuracy that nobody can claim their clock was right and yours was wrong. That usually means getting below 10 milliseconds of variance across the board, which is tight but very achievable if you know what you're doing. The most common starting point is NTP, or the Network Time Protocol. Every modern operating system has an NTP client built in, and it will normally grab time from whatever pool you've got configured. The problem is that default pool servers are often hundreds of miles away and sitting behind multiple layers of caching infrastructure. That introduces latency jitter that makes your timestamps look fine but isn't actually precise. I've seen production servers in Secaucus drifting by 50 milliseconds over a week because they were talking to an NTP server in Virginia through a congested peering link.
What Actually Works in Practice
Set up a local NTP stratum 2 server in your own infrastructure and point everything else at it. That local server should be pulling from a stratum 1 source like the USNO atomic clock feeds or the NIST time service. For New Jersey specifically, the closest reliable stratum 1 sources are usually servers in the 129.6.1.x range, which is the University of Colorado system, or the 132.163.x range from NIST. You can also use the GPS-disciplined oscillator approach if you want to get serious about it, but that's probably overkill unless you're running a financial trading desk. The config on your local NTP server matters more than people realize. By default, most NTP implementations will happily accept time from any server that responds, even if that server is wildly off. You need to lock down your config with the restrict directive, specify which servers are authoritative, and set the maxoffset and panic threshold values. Without those settings, a compromised or misconfigured upstream server can silently shift your entire network's clock backwards by several seconds. I learned that one the hard way back in 2019 when a DDoS on a common public NTP pool caused a cascading time shift across three of our servers and took down our session validation for about forty minutes. Here's a sample configuration that actually holds up under production conditions:
server 129.6.15.28 prefer
server 132.163.97.3
server time.nist.gov
restrict default nomodify notrap nopeer noquery
restrict 127.0.0.1
restrict ::1
maxdistance 0.1000
panic threshold 1000 The prefer flag on the first line tells your server to use that source as the primary even if others seem slightly more responsive. The maxdistance setting prevents your server from accepting time from a source that's more than 100 milliseconds away from the current time, which catches pathological cases. The panic threshold is your safety net. If NTP ever detects a time shift larger than 1000 seconds, it'll just halt instead of making a sudden jump that breaks everything connected to it.
Get the Full Details
Chrony vs NTPD
Old-school admins will tell you to use ntpd, the reference implementation. It works fine and has been the standard for decades. But chrony is what I actually use now, and for a few specific reasons that matter in a New Jersey deployment. Chrony handles intermittent connectivity better, which is relevant if any of your servers are on a VPN or backup circuit that drops occasionally. It also converges faster after a system restart, which matters when you're dealing with virtual machines that get migrated across hosts in different rack locations. And chrony can use multiple sources simultaneously rather than picking one and ignoring the rest until it fails. The chrony equivalent of that setup looks like this: pool time.nist.gov iburst maxsources 4
pool 129.6.15.0/24 iburst maxsources 4
server 132.163.97.3 iburst
makestep 1.0 3
rtcsync
logdir /var/log/chrony
The iburst flag is important. When your server first connects to an upstream, it sends a burst of eight packets instead of waiting for the normal poll interval. That gets you a time sync much faster after a reboot. The makestep directive tells chrony to instantly correct any offset larger than one second during the first three adjustments, after which it starts slewing gradually like ntpd does.
The Edge Case Nobody Warns You About
Virtual machines are where precise time synchronization breaks down in ways that are extremely difficult to diagnose. Hypervisors like VMware and Hyper-V have their own time sync mechanisms that fight with the guest OS's NTP client. What ends up happening is your VM clock gets nudged forward and backward by the hypervisor's clock synchronization every few seconds while your NTP client is simultaneously trying to correct drift in the other direction. The result is a jittery timestamp that looks completely normal in your monitoring dashboard but causes replication lag and log ordering issues that make no sense at all. The workaround is to disable the hypervisor's time sync and let the guest NTP client handle everything. In VMware that means setting vmware.tools.timesync.enable to false in the VMX file. In Hyper-V it's disabling the time synchronization integration service in the VM's settings. Once you do that and configure chrony with the localirq and cpu scale directives, the timestamps smooth out immediately. I spent an entire afternoon chasing a 200-millisecond log ordering issue across a cluster of twenty VMs before I realized the hypervisor was the culprit. Another thing that catches people out is leap seconds. They happen roughly once a year when the Earth's rotation doesn't quite match atomic time, and NTP handles them by inserting a second that lasts from 23:58:60 to 23:59:60 instead of the normal progression. Most systems handle this fine, but some older software and certain database engines don't. If you're running anything that does sub-second timestamp comparisons in a loop, a leap second can cause it to hang or produce duplicate keys. I had a PostgreSQL instance in Hoboken lock up for six minutes during the 2016 leap second insertion because an application was doing tight timestamp polling without any timeout handling. You can preemptively disable leap second smoothing by setting clock_step=0 in your chrony config or by applying the NTP kernel patch that handles leap seconds more gracefully.
Verifying Everything Is Actually Synced
Just because your NTP service is running doesn't mean it's accurate. Run ntpq -p or chronyc sources -v to see what your server thinks it's doing. You want to see a star next to the active source and a tilde for the fallback. The offset column should be well under a millisecond for a properly synced local server, and the delay should be under 20 milliseconds if you're hitting East Coast stratum 1 sources. If your offset is sitting at 5 or 10 milliseconds, something is wrong. Most often it's a firewall blocking the NTP UDP port, a misconfigured restrict directive, or the server simply can't reach the upstream because of a routing issue. chronyc tracking gives you a detailed breakdown of your clock discipline state. Look at the system time field, the last offset command, and the frequency offset. If your frequency is drifting more than a few parts per million, your hardware clock is bad and you need to either replace the machine or accept that it won't hold time well during network outages.
What This Can't Fix
Time synchronization only gets you so far. If your application logic depends on precise ordering and you're running across multiple data centers, NTP alone won't solve your problem. You'd need something like a Lamport timestamp or a hybrid logical clock built into your application layer. Similarly, if you need cryptographic-grade time assurance for compliance purposes, NTP isn't sufficient. The time could be spoofed, and there's no built-in authentication strong enough for legal proceedings. In those cases you'd want to look at PTPTM or TAI time scales with authenticated NTP extensions, though that adds significant complexity. Also worth noting that Wi-Fi and cellular interfaces are terrible for time synchronization. The round-trip times are too variable and the protocols introduce unpredictable delays. If any of your devices are accessing NTP over a mobile uplink, they're going to look inaccurate even if everything else is fine. Hardwire the sync traffic or use a cellular router with a GNSS Disciplined Oscillator built in. Get your local NTP server configured properly, lock down the restrict rules, switch to chrony if you're still running ntpd, and disable hypervisor time sync on any VMs. Do that and most New Jersey networks will hold time to well within a millisecond of each other without any further intervention.