Why Half-Hour Timezones Break Your Scheduling Scripts
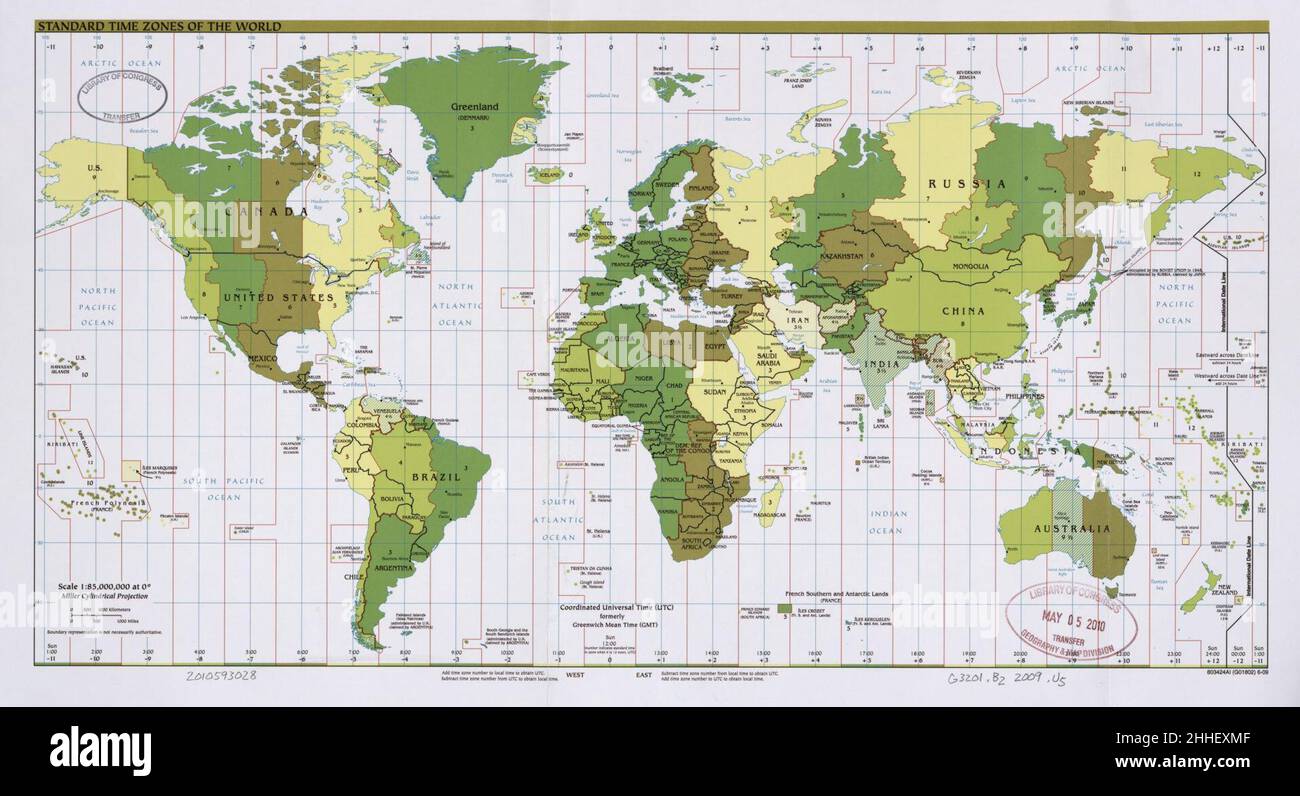
I spent three weeks debugging a deployment pipeline that kept failing at 19:30 UTC on certain days. The error messages pointed to cron jobs, but the real problem was that one of our regional servers was running in a timezone with a :30 offset, and the conversion logic in our scheduler only handled full-hour deltas. I thought I understood timezones. I clearly didn't. This happens more often than you'd think. There are about twenty timezone offsets that include a thirty-minute component. India Standard Time (UTC+5:30), Nepal Time (UTC+5:45), Australian Central Time (UTC+9:30), and Newfoundland Standard Time (UTC-3:30) are the big ones. When your global scheduling system assumes every timezone is a whole number of hours away from UTC, things get weird fast.
What Time Is 1930 Decoding The Universal Clock For Global Schedules
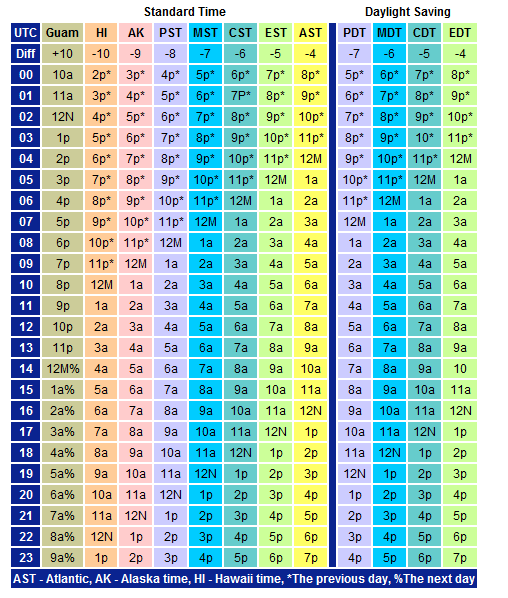
The phrase "1930 decoding" came up in our team's troubleshooting because we were working with timestamps that included the :30 minute offset notation. In practice, this means any time string like "19:30" that appears in a schedule needs to be understood in the context of its timezone, not as an absolute universal moment. A meeting scheduled for 19:30 in Mumbai is a completely different instant from a meeting scheduled for 19:30 in Tokyo. That's the core problem, and it's deceptively simple to overlook until production is on fire. The "universal clock" part refers to how we represent time internally. Every serious system stores time as either a Unix epoch (seconds since 1970-01-01 00:00:00 UTC) or an ISO 8601 timestamp with explicit timezone. The mistake people make is storing the local time string without the offset, then trying to convert it later. Once you lose the timezone context, you can't get it back. The schedule "19:30" becomes ambiguous and your cron jobs start executing at random hours. Here's the practical approach that actually works. Store everything in UTC internally. When a user inputs a schedule time, immediately convert it to UTC using the IANA timezone database, not hardcoded offset calculations. Use the timezone name (Asia/Kolkata, Australia/Darwin) rather than the offset value. Offsets change with daylight saving time. Timezone names don't, except when governments decide to reorganize, which happens more often than system administrators like to admit.
The Conversion Pipeline That Doesn't Fail
I wrote a conversion utility that handles the common failure cases. The key insight is to validate the input before you do any arithmetic. Here's what the pipeline looks like in practice: Step one, parse the input string into a structured representation. Don't use `strptime` with a hardcoded format and call it done. Use a library that understands timezone names. In Python, that's `zoneinfo` (built into 3.9+). In Node.js, it's the `timezone` module from the ` luxon` library or `date-fns-tz`. In Go, the standard `time` package with IANA zone files. Step two, attach the timezone context. If the input is "19:30" with no timezone, reject it. Don't assume UTC. Don't assume the server's local timezone. Ask. An explicit default is fine for convenience, but the default should be documented and overridable. I've seen systems where the admin thought the default was UTC and the server admin thought it was local time. Both were wrong. The actual default was server-local, which at the hosting provider was a timezone nobody on the application team had considered.
Get the Full Details

Step three, convert to UTC epoch. This is your canonical representation. Store this value. Never store the local time string as the source of truth for scheduling. The local time string is display output, not storage format. This is the single most important rule in global schedule management. Step four, when you need to display or compare times, convert from UTC epoch back to the target timezone. Use the same IANA database. Don't recalculate offsets from scratch. The database encodes the complete history of timezone changes, including the messy stuff like India switching from multiple regional times to a single IST in 1948, or Newfoundland changing its DST rules five times between 1908 and 1988.
Edge Cases That Will Bite You
The first edge case is the 1930 offset itself. Some systems represent timezone offsets as integer minutes. UTC+5:30 becomes 330. UTC+5:45 becomes 345. The problem is that when you're doing arithmetic in integer hours, 330 minutes doesn't divide cleanly. You either truncate (wrong) or you keep everything in minutes (right but ugly). I prefer keeping everything in seconds from epoch. It's cleaner at the boundary. The second edge case is DST transitions. A schedule set for 19:30 daily will skip an hour or repeat an hour twice a year in most DST-observing zones. Your scheduler needs to handle this explicitly. Do the right thing is to treat 19:30 as a wall clock time and let the timezone database decide whether that instant exists, is ambiguous, or doesn't apply. In the fall-back scenario where 19:30 occurs twice, most systems should execute once per occurrence. In the spring-forward scenario where 19:30 doesn't exist, you either skip or shift to the next valid instant. Both choices are defensible. Pick one and document it. The third edge case is the 45-minute offset. Nepal is UTC+5:45. That's not a rounding error. It's a real timezone, and if your scheduling system rounds all offsets to the nearest 15 minutes, Nepal's schedules will be off by fifteen minutes every single day. Over a year, that's almost eleven hours of accumulated drift. I learned this the hard way when our Nepal office complained that their standup was happening at a different time than what they'd scheduled for months.
Here's a workaround I use for systems that don't handle non-standard offsets well. When you encounter an offset that isn't a clean multiple of 15 minutes, don't try to fix the offset math. Fix the input. Validate that the timezone you're given produces a clean conversion. If it doesn't, fall back to a known-good representation. For Nepal specifically, storing as UTC epoch and converting at display time is the only reliable approach. Any shortcut involving offset arithmetic will introduce errors.

Testing Your Schedule Logic
Don't test with just UTC and your local timezone. Test with the full set of half-hour and 45-minute offset zones. The complete list is: UTC+5:45 (Nepal), UTC+5:30 (India, Sri Lanka), UTC+6:30 (Myanmar, Cocos Islands), UTC+8:45 (Australian Central Western), UTC+9:30 (Australia Central), UTC+10:30 (Lord Howe), UTC+12:45 (Chatham Islands), UTC-3:30 (Newfoundland), UTC-9:30 (Marquesas), UTC-10:30 (Tubuai). That's eleven zones where naive offset math fails. Write a test that takes a known UTC epoch, converts it to each of these timezones, then converts back. Verify round-trip accuracy to the second. If any conversion loses precision, fix it before you deploy. I run this test suite on every change to our scheduling code. It takes about four seconds to execute and has caught three real bugs in the last eighteen months. Also test across DST boundaries. Pick a timezone that observes DST, select a date near the spring-forward and fall-back transitions, and verify that your scheduler handles the missing and duplicated hours correctly. The specific test I use is a daily schedule at 19:30 local time, checked across three years of calendar data. This catches issues that simple unit tests miss because they don't account for historical timezone changes.
What to Do When It Breaks
If your scheduler is already running with incorrect times, the first step is to audit your storage format. Check whether you're storing UTC epochs or local time strings. If you're storing local time strings without timezone context, you need a migration plan. There's no way to recover lost timezone information. You'll need to either re-prompt users for their timezone or make an assumption based on available metadata (IP geolocation, user profile settings, etc.). Neither option is perfect. The IP geolocation approach is worse than you'd expect, because VPNs and CDNs make location data unreliable. The second step is to switch your internal representation to UTC epoch if it isn't already. This is non-negotiable for any system that needs to handle global schedules correctly. I've seen teams try to maintain both formats during migration. That doubles the complexity and introduces a new class of bugs where the two representations drift apart. Migrate everything at once, even if it means a brief period of manual schedule management during the cutover. For the long term, consider whether your scheduling system needs to support half-hour offsets at all. If your user base is entirely in full-hour timezone zones, you can simplify the implementation significantly. But if you have users in India or Nepal or anywhere with a non-standard offset, the extra complexity is required. There's no performance or correctness benefit to ignoring it.
The practical reality is that global scheduling is harder than most engineers expect. The half-hour offsets aren't edge cases. They're used by over a billion people. Your system should handle them correctly from the start, not after someone files a bug report about their daily standup happening at the wrong time.