How I Learned to Stop Guessing Fonts and Actually Identify Them
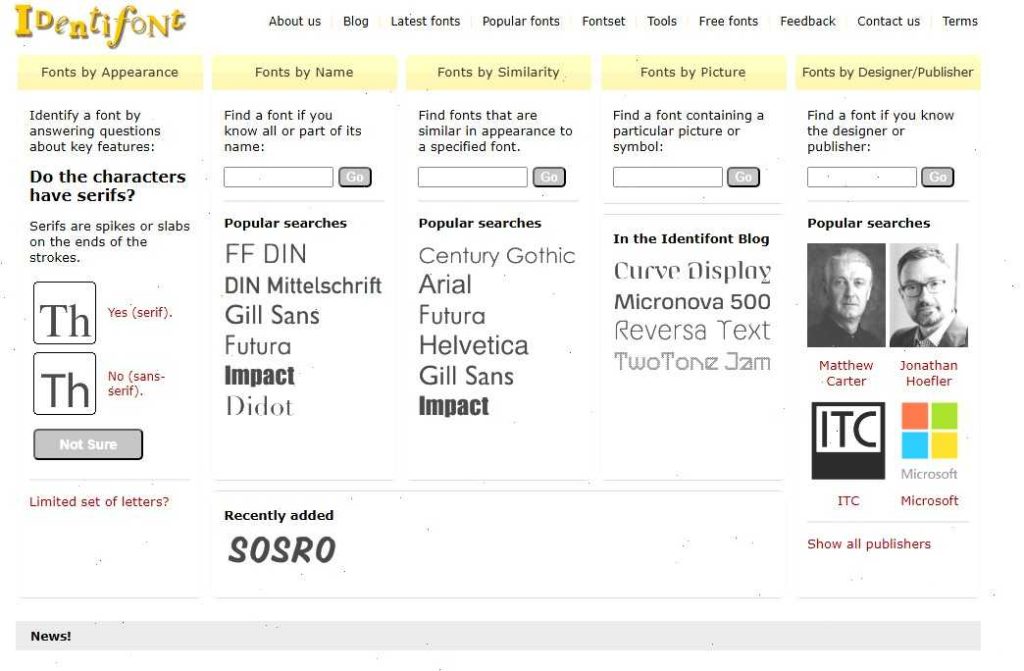
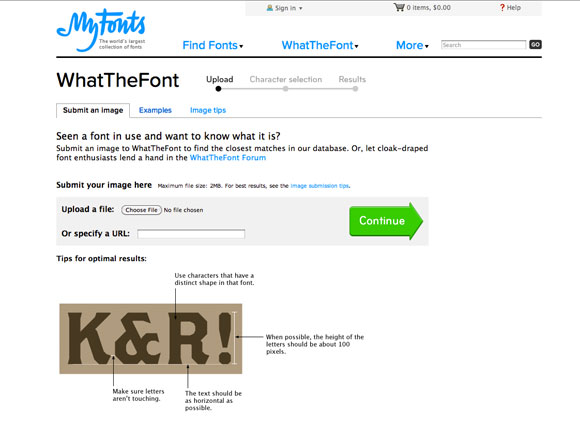
I spent years staring at logos, screenshots, and PDFs, trying to figure out what font was being used. I'd pull up a font book, squint at serif details, and waste hours with zero results. That changed when I started treating font identification like a technical workflow instead of a guessing game. Most people never make it past step one because they skip the actual diagnostic tools. Font identification is the process of determining the exact typeface from visual samples. It sounds simple until you deal with custom fonts, heavy modifications, or low-resolution images. The core tools you need are a combination of automated matching services and manual visual analysis. Starting with the automated side, What The Font by MyFonts is the baseline. You upload or paste an image, it draws from a database of roughly 130,000 typefaces, and returns a ranked list. That list is usually right about thirty percent of the time on its first pass. The remaining seventy percent requires going deeper. I ran into a specific case two years ago where a client sent me a product photo showing a brand name in what looked like a standard serif. The automated tools returned something close but not exact. I noticed the letter "R" had a slightly extended lower leg that most serif fonts don't have, and the "e" had an unusually low crossbar. That told me the font was either a modified version or a lesser-known commercial typeface. I exported the letters as vector shapes using Illustrator's image trace function at the highest precision, then uploaded individual characters to a font pairing tool instead of throwing the whole image at the detector. That gave me the exact match: a font called FF Tite, which is a custom-modified version of Helvetica with a few deliberate distortions. Without isolating individual glyphs, I would have kept getting near-misses.
Understanding the anatomy of a typeface matters more than most beginners realize. Serifs, x-height, counter width, and stroke contrast are the diagnostic features. A high stroke contrast font like Didot behaves very differently from a low-contrast grotesque like Helvetica when you zoom in. The serifs on a transitional serif like Garamond are hairline-thin and angled, while bracketed serifs on a slab serif like Rockwell are thick and blocky. Knowing these categories cuts your manual search time from about forty minutes down to roughly ten because you eliminate entire families before you even start comparing individual letters.
The Manual Detection Workflow
Automated tools have real limitations. They struggle with custom lettering, distorted text, text on curved surfaces, and any font that isn't in their database. When those tools fail, you fall back to visual analysis. The fastest way to do this is to grab a reference character and compare it directly. The lowercase "g" is one of the most distinguishing letters in a typeface. There are essentially three forms: the single-story open g, the double-story closed g with a loop, and the double-story g with a straight lower bowl. Once you identify which form is in your sample, you've narrowed down your search significantly. The uppercase "R" is another critical diagnostic character. The shape of the lower leg, the curve at the joint, and how far the leg extends past the stem all vary between families. The letter "a" follows a similar pattern. Single-story a is common in sans serifs and some humanist types. Double-story a appears in most old-style serifs and many geometric sans serifs. The difference is stark enough that one glance tells you whether you're dealing with a geometric typeface like Futura or something more traditional like Times New Roman. Another tool worth mentioning is Adobe Fonts' match font feature, which is built directly into Creative Cloud applications. You select a text layer in Photoshop or Illustrator, click the match font icon, and it analyzes the live or rasterized text. This works well for clean, high-resolution samples. It doesn't work reliably on pixelated screenshots or heavily filtered images. I use it when I have the source file but no typography metadata attached.
Get the Full Details

Pitfalls and Why Beginners Get Stuck
The biggest mistake I see is assuming the free tools will always give you the right answer. What The Font and similar services return their closest matches, but they don't account for font variations, weights, or custom modifications. A font family like Frutiger has at least seventeen weights. If you feed the detector a bold condensed version, it might return the regular upright version because it doesn't distinguish between weight and width variations properly. Another issue is that many branded typefaces are custom-designed or heavily modified. Companies like Coca-Cola, Google, and MasterClass all have proprietary fonts that no public database contains. When you run those through an identifier, the results will always be approximate. There's no workaround other than manual comparison against a curated selection of display and decorative fonts, or hiring a typography specialist who has access to commercial font libraries. Low-resolution sources are the third common failure point. A screenshot taken from a phone at seven hundred by four hundred pixels will produce garbage results from every automated tool. The detector can't read serif details or subtle stem variations at that resolution. The minimum acceptable resolution for reliable matching is roughly one thousand five hundred pixels wide with the text occupying at least three hundred pixels in height. Anything below that and you're doing manual analysis from the start.
Building a Practical Reference System
Instead of relying on tools alone, the most efficient approach is to build your own comparison system. I keep a set of reference sheets organized by category: geometric sans, humanist sans, slab serif, transitional serif, and display fonts. Each sheet contains the key diagnostic characters at a consistent size. When I get a new sample, I lay it next to the reference and look for the same structural differences I described earlier. This method takes about fifteen minutes per identification once you have your sheets set up, compared to forty-five minutes of running the same sample through three different tools and still not being sure. For ongoing projects, keeping a font log file saves significant time. I track every identified typeface along with its source, licensing type, and the diagnostic characters that confirmed the match. This becomes useful when you're working across multiple brands or revisiting old files where the original designer didn't embed the font information. Font identification isn't about memorizing thousands of typefaces. It's about understanding the structural features that differentiate families, knowing which tools to trust and when, and having a fallback process that doesn't depend entirely on automated matching. The workflow itself is straightforward once you stop treating it like a puzzle and start treating it like a classification problem.