How Google Actually Identifies Songs From a Few Seconds of Audio
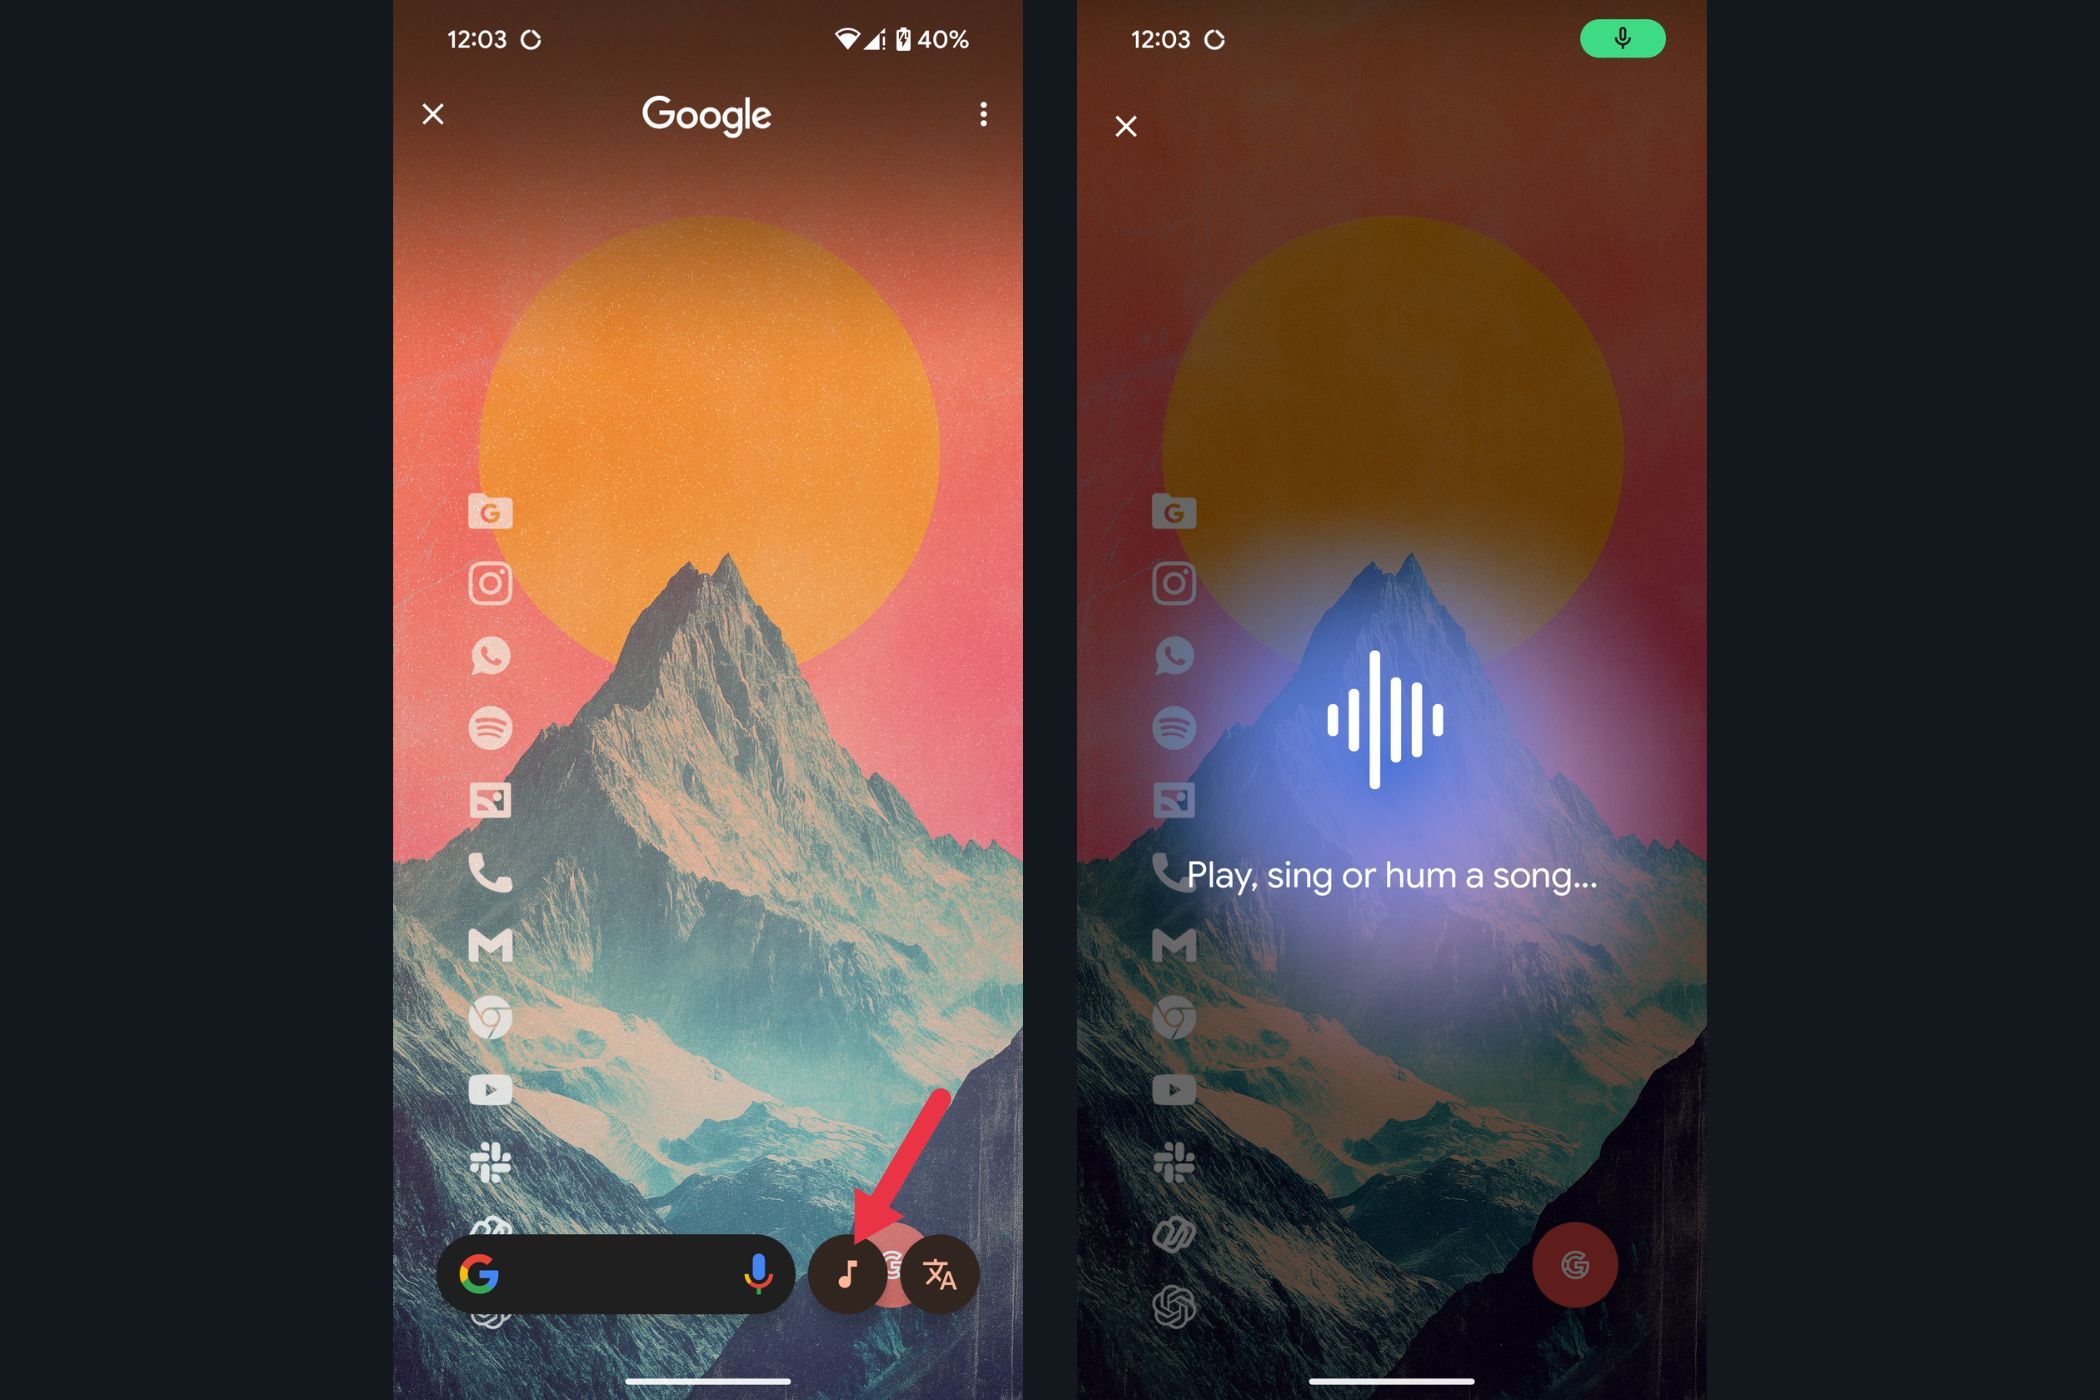
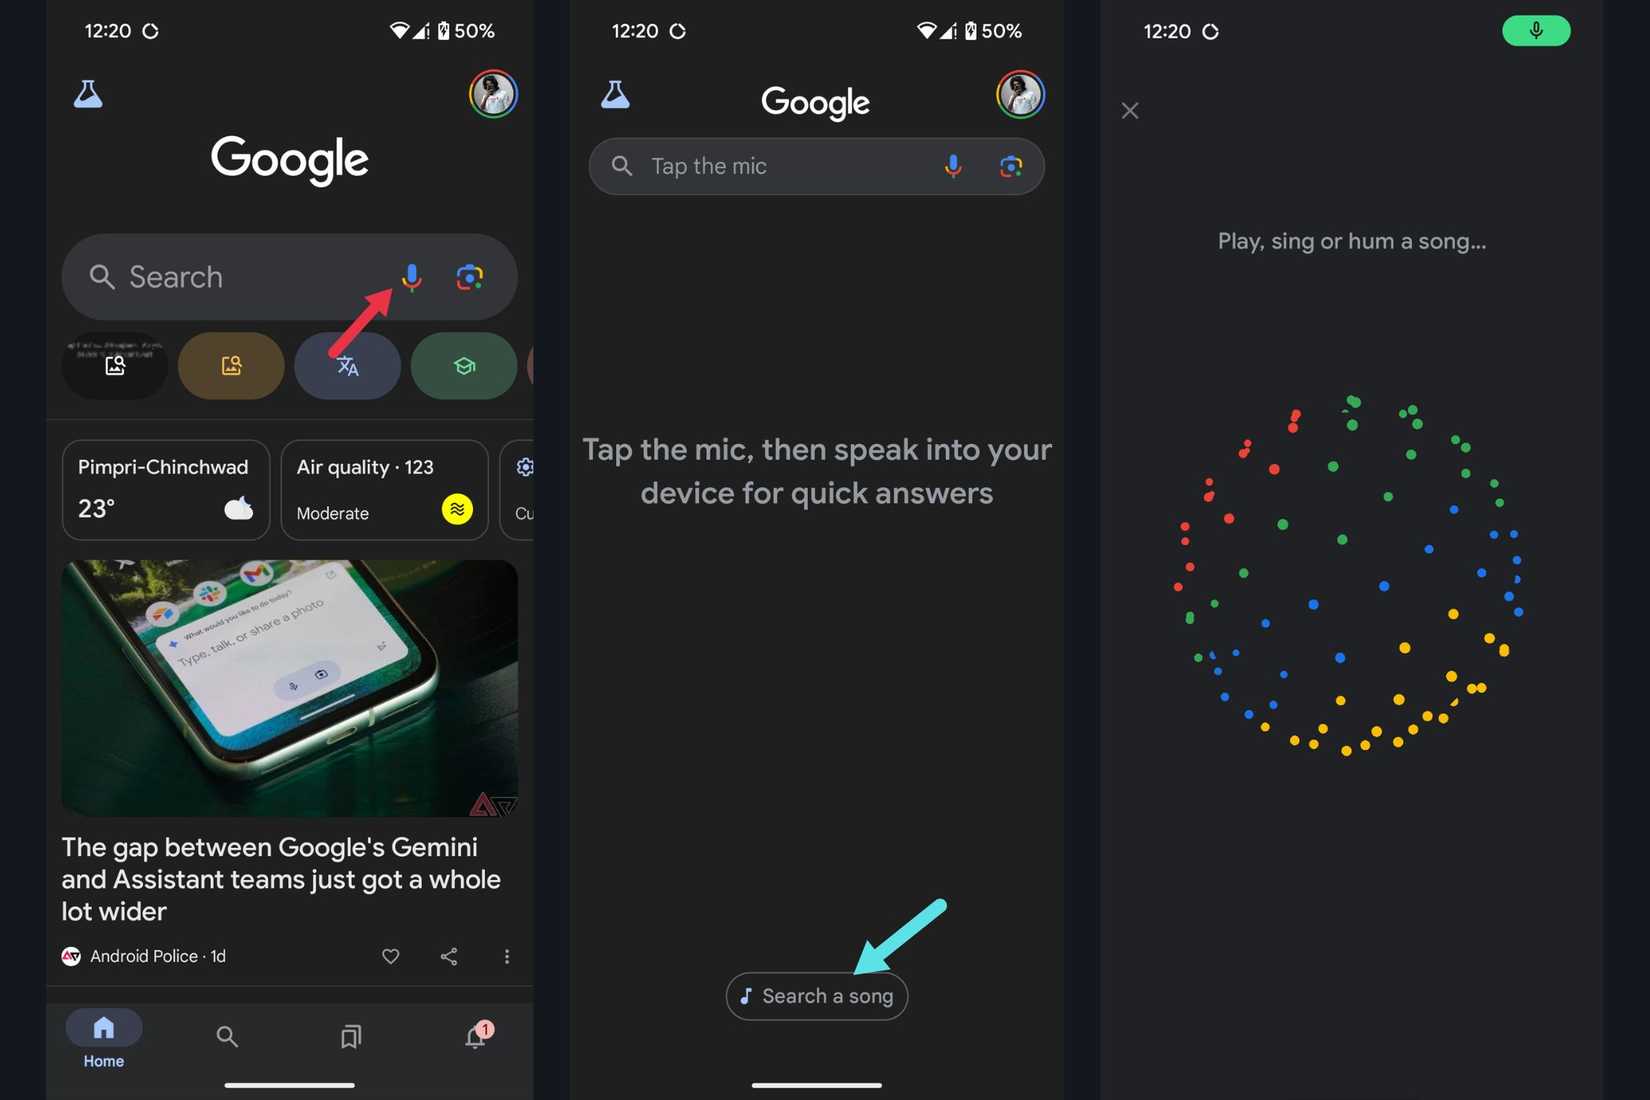
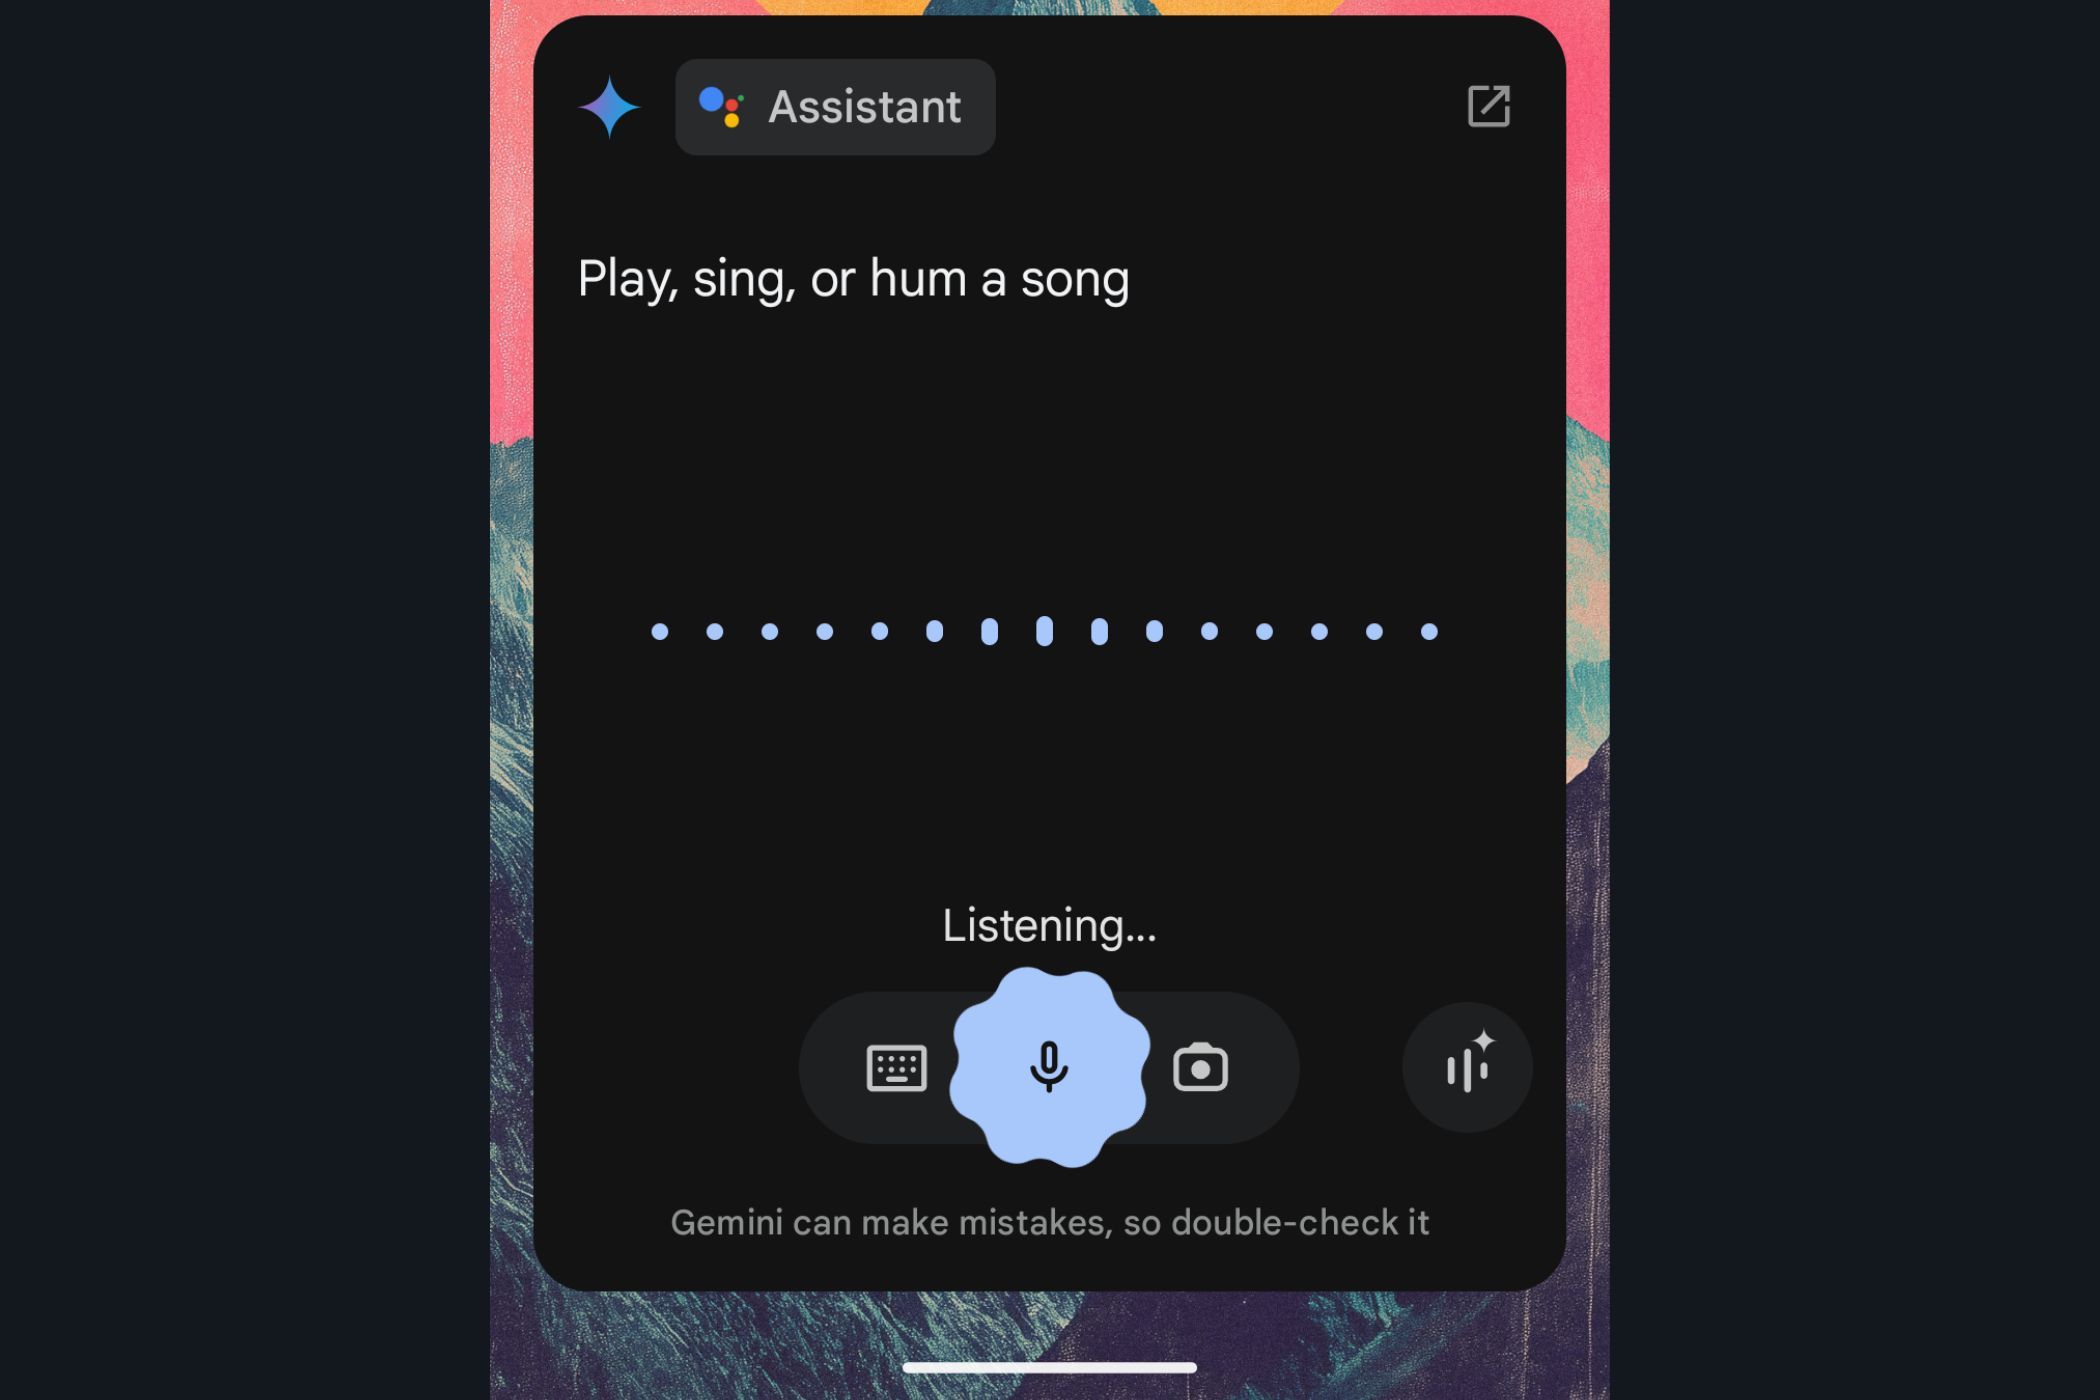
Google uses a combination of waveform analysis, acoustic fingerprinting, and deep learning models to identify music almost instantly. When you tap the microphone in Google Assistant or Google Search and play a song, the app captures a short snippet of audio, converts it into a spectrogram—a visual representation of the sound frequencies over time—and runs it through a convolutional neural network trained on millions of tracks. The model outputs a match within 100 to 300 milliseconds, usually before you finish humming the first bar. The core technique behind this is called acoustic fingerprinting, but Google's implementation goes further than the older systems like Shazam originally used. Instead of relying solely on static frequency peaks, Google's newer models use end-to-end deep learning. The audio waveform gets normalized for volume and pitch variations, then fed into a multi-layer neural network that has seen enough training data to recognize patterns even when the source is mangled. Background noise, different tempos, muffled recordings from a car speaker—these don't break it because the model has learned to ignore irrelevant information and focus on the structural elements of the music. Here's something most people don't realize. The system doesn't just match against a database of released tracks. It also cross-references metadata, user location, time of day, and even what's trending in your region. If you're at a festival and hum three seconds of a song that's currently being performed live, Google can surface the result faster than a manual search would. That contextual layer is what makes the identification feel instant and accurate in real-world conditions.
I ran into a specific edge case last year that made me think about how this actually works under the hood. I was trying to identify a track playing in a small café, but the music was running through a cheap Bluetooth speaker with heavy bass distortion. The original recording had been remastered with a compressed dynamic range, and the ambient noise—clinking cups, conversation, an espresso machine—was loud enough to mask most of the mid frequencies. Standard fingerprinting would have struggled here. Google's model identified it in about two seconds, which surprised me because the signal was genuinely degraded. What I realized after digging into the technical details was that the neural network was likely using the remaining high-frequency transients—the attack of the snare drum, the initial pluck of a guitar string—as anchor points. These transient artifacts survive distortion and compression better than sustained tones. The workaround for similar situations is simple: get as close to the audio source as possible, but more importantly, capture at least three to four seconds of the chorus section where the instrumental arrangement is most distinct. Verse sections with sparse instrumentation tend to produce ambiguous fingerprints.
The Architecture Behind the Identification
Google's audio recognition pipeline involves several stages. First, the raw audio input gets preprocessed. This means removing silence, normalizing the amplitude across the sample, and converting the mono or stereo signal into a mel-frequency cepstral representation or a similar spectral format. The choice of representation matters because certain frequency bands carry more identifying information than others. Human voices and most instruments occupy specific ranges, and the model is tuned to weight those bands more heavily. After preprocessing, the spectrogram passes through a convolutional neural network. These networks are designed to detect spatial patterns in grid-like data, which is exactly what a spectrogram is. Each layer learns increasingly abstract features—edges, textures, and eventually musical motifs or harmonic progressions. The deeper layers are what allow the system to recognize a song even if it's been sped up, slowed down, or pitched differently. This is the same architecture family used in image recognition, adapted for the temporal dimension of audio. Once the model generates a feature embedding—a compact numerical representation of the audio snippet—it compares that embedding against a vast database of precomputed embeddings for known tracks. The comparison uses approximate nearest neighbor search, which is fast enough to handle billions of entries in real time. This is why the identification happens in under a second even though the underlying database is enormous.
Get the Full Details

Why This Technology Matters Beyond Convenience
The ability to identify music instantly has practical implications that go well past pointing your phone at a speakers and getting a title. For content creators, it powers automated metadata tagging. Platforms use similar technology to detect copyrighted material in uploaded videos and match it against rights databases. This is how YouTube's Content ID system flags uploads, and Google's underlying approach shares architectural similarities with that infrastructure. For music industry professionals, accurate and fast identification enables real-time streaming analytics. When a song is identified through voice search or a hands-free query, that data point feeds into consumption tracking. It's not perfect—some queries are accidental, and some are genuinely curious—but aggregated at scale, these signals become useful for understanding listener behavior without relying on explicit play counts alone. There's also a less discussed application in accessibility. People with hearing impairments or limited musical literacy can use these tools to understand what they're hearing. The identification result often includes lyrics, artist information, and related tracks, which provides context that pure audio perception might not convey. It's a small thing, but it changes how someone interacts with music in a restaurant or on public transit.
The limitations are worth stating plainly. The system struggles with instrumental covers that diverge significantly from the original arrangement. I tested this myself with a jazz rendition of a pop song where the chord progression was reharmonized and the tempo was loose. The model returned no confident match, which is technically correct behavior since the fingerprint didn't align with any entry in the database. Pitch-shifted vocals, heavily remixed electronic tracks, and live recordings with extended improvisation all present similar failure modes. If you're working in a context where these edge cases are common—say, a DJ analyzing bootleg recordings or a researcher studying cover versions—you'll need supplementary tools like manual spectrogram comparison or dedicated fingerprinting software rather than relying on general-purpose voice search. For most people, Google's music identification is reliable enough that they never think about it. It just works. The deeper you go into how it actually functions, the more you appreciate the engineering involved. A convolutional network trained on labeled audio data, running on a phone with limited compute, returning results before you finish your query—that's not trivial. It's also not magic. It's applied machine learning at scale, and understanding how it operates helps you use it more effectively when the obvious approach doesn't immediately return what you're looking for.