Developer Responsibility With Generative AI: The Practical Reality
Using a code completion model doesn't transfer liability to the tool vendor. The developer who reviews, approves, and ships code is still the accountable party. When your team starts letting Copilot or similar tools generate entire functions, you're not reducing your legal exposure—you're just changing how quickly mistakes reach production. That's the uncomfortable part most teams gloss over. I was on a call with a mid-size fintech team last fall where they'd been running a generative AI pair programmer for three months. They'd cut their average feature delivery time from about two days to roughly six hours, but their incident rate had also climbed. One bug involved an AI-generated authentication handler that silently accepted expired tokens because the model had patterned its response after an outdated library example it trained on. Nobody on the review board caught it. The fix took a week because we had to audit every function the tool had touched in the preceding sixty days.
What Is Responsibility Of Developers Using Generative AI Coding Ethics And Liability In The Al Era
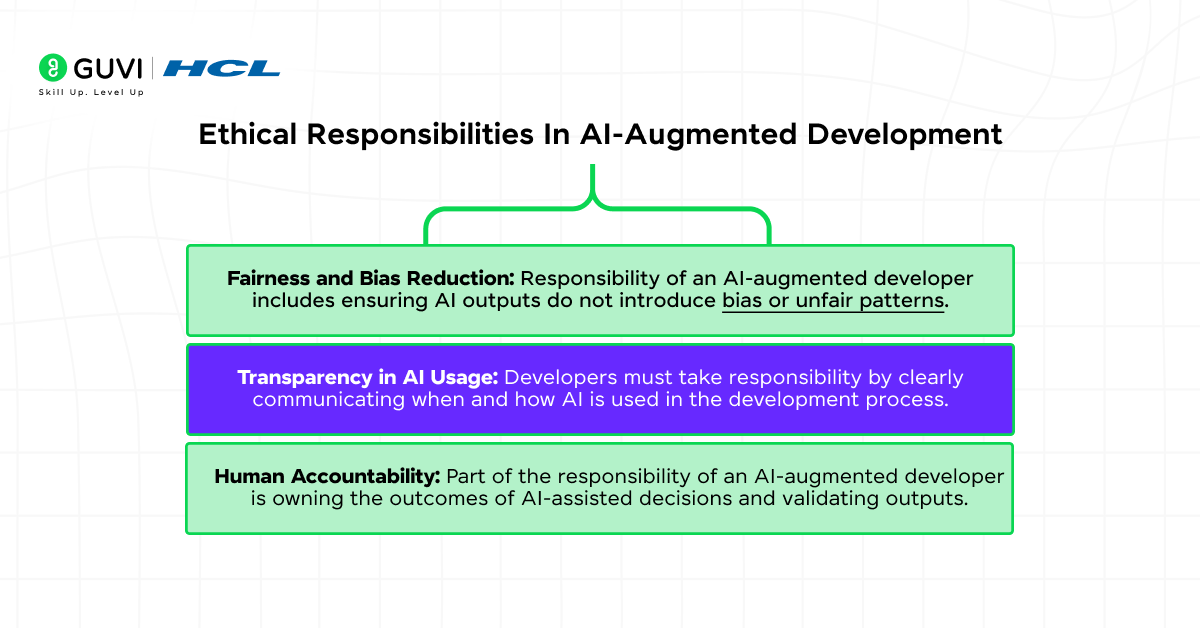
The core question isn't philosophical. It's about where the buck stops when something breaks. Here's how it actually works: you own the output whether you wrote it yourself or generated it. Courts have been pretty consistent about this. If your code causes data leakage, copyright infringement, or a security vulnerability, the employer or the individual sign-off engineer is what gets named—not the AI company. There's no legal firewall between a generated line and a shipped product. Ethics in this space mostly comes down to three things: sourcing, transparency, and bias awareness. You need to know what license the training data carries if it matters for your product. A lot of generative models were trained on publicly available repositories, which means code they generate could potentially mirror copyrighted material. That's not hypothetical. There are already class action lawsuits from open-source authors against OpenAI and Microsoft over exactly this. The ethics piece is simpler than people make it: if you use generated code, verify it, understand where it came from, and document your review process. Liability is where it gets expensive. I've seen teams treat AI output like a first draft they don't need to read carefully. That mindset costs real money. A few years ago I worked with a health tech startup that let their tool generate database migration scripts. The model included a column type mismatch that didn't throw an error during testing but corrupted a small percentage of records in production. The legal team ended up having to disclose a potential data integrity incident. The remediation cost was roughly forty thousand dollars in developer hours alone, not counting the regulatory filing work. All of it traced back to a single unchecked function the AI produced.
How to Actually Handle This Without Losing Your Mind
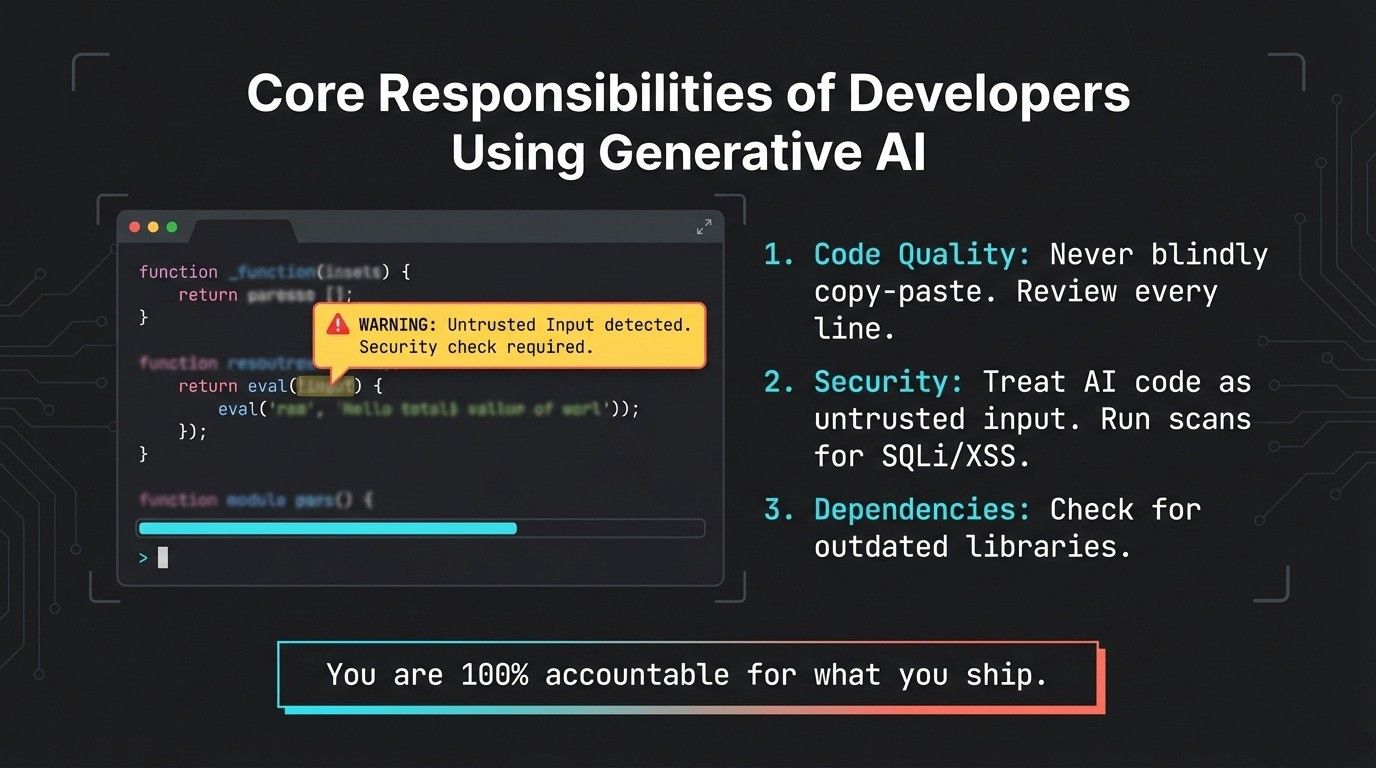
Start with a code review policy that treats generated code the same as human-written code. There's no shortcut here. Every function a model spits out needs a line-by-line review by a person who understands the surrounding system. This usually adds about twenty to thirty percent to your initial development time, which sounds bad until you factor in that you're catching hallucinated API calls, deprecated library references, and logic errors before they hit staging. Implement a traceability system. Keep a log of which code segments were AI-assisted, which model produced them, and when they were reviewed. This sounds bureaucratic but it's the single most useful thing you'll do if anything goes wrong legally. You want to show that your team exercised due diligence, not that you clicked a button and pushed to production. Be honest about model limitations. These tools are good at patterns, not reasoning. They will confidently write code that looks correct but contains subtle logical flaws. A common example is off-by-one errors in loops, or functions that handle edge cases incorrectly because the training data had the same edge case handled wrong in most places. Another thing nobody tells you: these models don't actually understand security. They can generate code with SQL injection vulnerabilities or hardcoded credentials because they've seen that pattern in their training data and associate it with "normal" code. You have to check for this yourself.
Get the Full Details
Training your team on what the tools can and cannot do is critical. I spent two weeks running a workshop for a development team that was completely blind to what their AI assistant was actually doing. They thought it was generating original code from scratch. It wasn't. It was predicting likely next tokens based on similar code patterns. Understanding this distinction changed how they reviewed output almost immediately. People who think the tool is creating something new tend to trust it too much. People who understand it's doing pattern matching tend to scrutinize it appropriately.
The Hard Parts Nobody Talks About
There's a real problem with IP contamination. When you use generated code in a proprietary product, you need to be aware that the model might have regurgitated something that belongs to someone else. The chance is low for individual functions but it compounds across a large codebase. I'd recommend running any AI-generated code through an open-source license scanner before it touches production. Tools like FOSSA or Snyk can catch most of these issues. This adds about ten minutes per deployment cycle and has saved me from potential legal headaches at least twice. Bias in generated code is another quiet risk. Models trained predominantly on English-language GitHub repositories tend to produce code that reflects the conventions and assumptions of that community. This can mean everything from incorrect locale handling to assumptions about user demographics that don't apply to your actual users. If you're building software for a global audience, don't assume the AI output is culturally neutral. It isn't. There's also the question of accountability when multiple developers use AI simultaneously. If five people on your team are all using different prompts to generate similar authentication code, you'll end up with five slightly different implementations that all share the same undetected flaw. This happened to a payment processing team I consulted for. The AI had generated a rounding function that introduced a one-cent discrepancy in one out of every several thousand transactions. Since every developer had made their own version, the bug was spread across the codebase and nearly impossible to trace back to a single source. We ended up writing a custom linter rule to catch the specific pattern across all variants. Took two days to implement. Would have taken months to debug without it.
What Most Teams Get Wrong
The biggest mistake I see is treating AI-generated code as faster code instead of code that needs the same level of scrutiny as anything else. Speed is real, but it's conditional on your review process being sharp. Another mistake is not having clear internal policies about what types of code the AI can and cannot touch. Generating boilerplate? Fine. Generating security-sensitive logic? That should require explicit sign-off from a senior engineer. Generating code that handles personally identifiable information? Double sign-off, plus a manual security review. Some teams try to automate the review of AI output with automated testing. That helps but it's not a complete solution. Unit tests can miss logical errors that only show up in integration scenarios. I'd recommend combining automated checks with mandatory peer review for any AI-assisted code that touches sensitive areas of your system. The legal landscape is still shifting. The EU AI Act and similar frameworks are starting to impose specific requirements on organizations that use generative AI in professional contexts. Even if you're not in the EU, if you serve EU customers, these rules may apply to you. The basics are: you need to be able to demonstrate transparency about AI use, maintain human oversight of high-risk outputs, and keep records that show your due diligence. Start building those habits now rather than scrambling when regulation catches up.

One practical tip that has helped my teams: set up a internal documentation page where developers log interesting or problematic AI-generated code patterns they encounter. Over time this becomes a living knowledge base that makes your whole team better at catching issues. It's low effort and high reward. We've had this running for about a year and the number of AI-related bugs reaching production has dropped significantly because people recognize the patterns before they ship them.