Understanding P Values In Practice
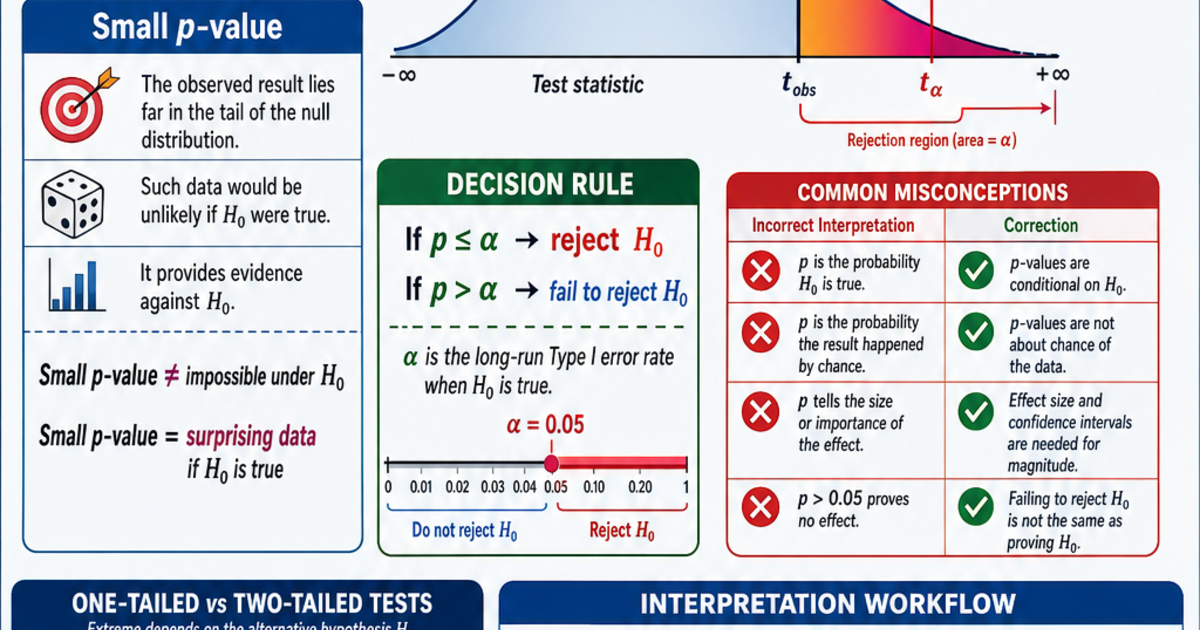
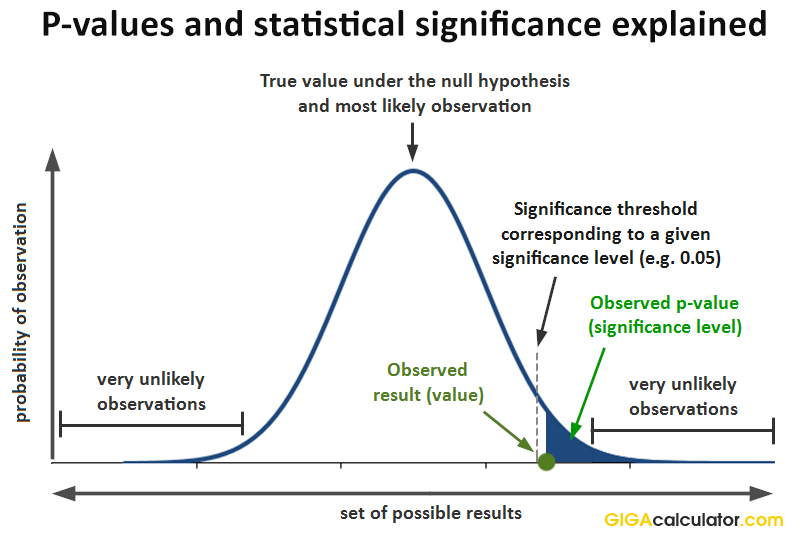
The p-value is one of those concepts everyone uses but almost nobody actually understands correctly. I've spent years watching people make expensive decisions based on misinterpreted statistics, and most of it comes down to the same fundamental misunderstanding. Let me just explain how it actually works and where people mess up. A p-value measures the probability of observing your data, or something more extreme, if the null hypothesis is true. That's the textbook definition. The null hypothesis is usually the default assumption that nothing interesting is happening - no real effect, no real difference between groups. The p-value tells you how incompatible your data is with that default assumption.
What Is P Value The Secret Number Deciding Science Business Your Decisions
Here's what happens in the real world. You run an A/B test on a landing page. Version A gets a 3.2% conversion rate. Version B gets 3.8%. Your instinct says B is better. The p-value tells you whether this difference could plausibly be random noise or whether it's statistically meaningful. A p-value below 0.05 is the conventional threshold for calling something "statistically significant," which is code for "this is unlikely to be pure chance." But that threshold is arbitrary and people treat it like it's carved in stone. I worked on a project last year where we were testing a new onboarding flow for a SaaS product. We had about 12,000 users split between control and treatment. The p-value came out to 0.047. Just barely under the threshold. Everyone on the team wanted to celebrate and roll it out immediately. I pushed back because I'd seen this pattern before. When a p-value is hovering right at 0.05, the result is essentially unreliable. It could flip to 0.06 with a few more signups or a couple of outliers shifting the distribution. The practical implication of the number was marginal at best. We ran the test for another two weeks with a larger sample size, and the p-value moved to 0.11. The effect was real in direction but not robust enough to act on confidently. Rolling it out based on that first result would have been a costly mistake. This is the part nobody tells you in introductory stats courses. A p-value of 0.04 isn't meaningfully different from a p-value of 0.06. The difference between those two numbers is noise. People act like 0.04 is some magic proof and 0.06 means nothing, but that's not how probability works. Both numbers are saying roughly the same thing: the data is somewhat unusual under the null hypothesis. The arbitrary line at 0.05 creates a false sense of certainty where none actually exists.
Another thing that drives me crazy is how people confuse statistical significance with practical significance. I was consulting for a pharmaceutical company a while back. They had a drug trial with 50,000 participants. The experimental drug showed a statistically significant improvement of 0.3 percentage points in recovery rate compared to placebo. The p-value was 0.001. Extremely significant by any standard definition. But 0.3 percentage points is clinically meaningless. A recovery rate going from 94.1% to 94.4% doesn't justify the side effects, the manufacturing cost, or the regulatory burden. The p-value screamed importance but the actual effect size whispered irrelevance. This happens constantly in business too. A website change that increases conversion from 2.00% to 2.05% might be statistically significant with enough traffic, but the revenue impact is negligible compared to the engineering effort required to implement it. The calculation itself is straightforward if you know what you're doing. For a simple two-group comparison, you're typically using a t-test. You calculate the difference between group means, divide by the standard error of that difference, and get a test statistic. Then you convert that statistic to a p-value using the appropriate distribution. Most people never do this manually anymore. They use Python's scipy.stats module, R, or an online calculator. The formula in Python looks something like this: from scipy import stats and then stats.ttest_ind(group_a, group_b). The output gives you the t-statistic and the p-value in one call. It takes about 10 seconds to set up. But here's where the edge cases bite you. Small sample sizes are the most common problem. When you have fewer than 30 observations per group, the t-distribution has heavy tails, which means your p-values are less reliable. You also need to check assumptions like normality and equal variance. If your data is heavily skewed, which happens all the time with business metrics like revenue or order counts, the standard t-test can give you misleading p-values. I learned this the hard way on a project measuring customer lifetime value. The distribution was extremely right-skewed with most customers spending $50 and a few spending $5,000. A standard t-test gave us a p-value of 0.03, suggesting a significant difference between segments. But when I ran a non-parametric Mann-Whitney U test instead, which doesn't assume normal distribution, the p-value jumped to 0.18. The apparent effect disappeared once you accounted for the skewed distribution properly. Switching to the non-parametric test added about five minutes to the analysis and prevented us from making a decision based on a statistical artifact.
Get the Full Details

Multiple testing is another trap that destroys a lot of published research and business decisions. If you run 20 independent tests, each with a 5% false positive rate, you should expect about one false positive purely by chance. This is called the multiple comparisons problem. I've seen marketing teams test five different headline variations against a control and then pick whichever had the lowest p-value without adjusting for the fact that they ran five tests. Their "significant" result was almost certainly a fluke. The fix is the Bonferroni correction, which divides your significance threshold by the number of tests. Five tests means you need a p-value below 0.01 to call something significant. It's conservative but it prevents a lot of bad decisions. There's also the issue of p-hacking, which is the deliberate or semi-deliberate manipulation of data collection and analysis to find a significant result. This isn't always intentional fraud. Often it's just someone trying so hard to find a signal that they keep peeking at the data and running different analyses until something crosses the threshold. I've watched data analysts do this without realizing they were doing it. They'd collect data, see a p-value of 0.08, decide to collect more data, and then check again. Each time they looked, the p-value shifted slightly. After three or four interim checks, it dropped below 0.05. The problem is that each peek at the data inflates your false positive rate. The proper approach is to pre-register your sample size and analysis plan, or at minimum use sequential testing methods that account for interim looks. In practice, most businesses don't do this. They just collect data until they get a promising result, which is a recipe for overconfident wrong answers. For the actual calculation in code, here's a minimal working example. You have two arrays of conversion data. You run a t-test. You interpret the p-value against your significance threshold, keeping in mind everything I just said about not treating that threshold as absolute truth. You also report the effect size alongside the p-value because the p-value alone tells you almost nothing useful about whether a result matters in the real world. A p-value of 0.001 with a Cohen's d of 0.02 is practically worthless. A p-value of 0.04 with a Cohen's d of 0.8 is potentially very interesting. Always report both numbers.
There are software tools and packages that handle all of this automatically now. Packages like statsmodels in Python give you confidence intervals, effect sizes, and power calculations alongside p-values. They also handle multiple comparison corrections with a single function call. Using these tools instead of raw scipy cuts down the analysis time significantly and reduces the chance of making a basic error. I'd recommend getting comfortable with statsmodels if you're doing this work regularly. The bottom line is that a p-value is a tool, not an answer. It quantifies how surprising your data is under a specific assumption. It does not tell you the probability that your hypothesis is true. It does not tell you the size or importance of an effect. It does not prove anything on its own. Use it alongside effect sizes, confidence intervals, domain knowledge, and common sense. And when someone tells you their result is "significant" based only on a p-value below 0.05, ask them what the actual effect size was. Most of the time they won't have that number ready, and that's a red flag worth noting.