What NMM Actually Is, From Someone Who Has Spent Years Wrestling With It
NMM stands for Network Management Monitoring, and most people treat it like a single tool when it is really a layering of protocols, polling loops, and alerting logic that sits between your infrastructure and your sleep schedule. If you are new to this, you will see a lot of vendors claim their product does "everything." They do not. What they do is poll devices at intervals, parse SNMP or agent data, and throw up dashboards that look impressive until a real outage hits. I ended up reading far too many of these so-called complete guides before I stopped trying to absorb them all at once. The honest version is shorter. You pick a stack, you configure your devices, and then you spend the next six months tuning alert thresholds so you stop waking up at 2 AM for false positives. That part nobody puts in the marketing copy. There are three main branches people use in production: Nagios-style event-based systems, Zabbix-style hybrid polling and trapper approaches, and the Prometheus model where everything is scraped on a fixed cadence and time-series data does the heavy lifting. Each has a place. The Nagios approach works fine for small fleets where you care about status changes rather than historical trends. Zabbix handles mixed environments well, but its discovery engine can eat CPU if you let it run wild across a sprawling subnet. Prometheus is elegant on paper and painful when your scrape targets become dynamic without a service discovery layer.
I ran a Prometheus stack for about two years at a mid-size data center. It worked until we had to migrate a legacy Cisco cluster that only spoke SNMPv2c and refused to expose certain MIBs without a proxy. We ended up running snmpexporter in front of those devices and still lost visibility into hardware sensor telemetry because the OIDs were proprietary. That is when I learned you should audit the exact MIBs each vendor exposes before you commit to any monitoring solution.
Setting Up The Basics Without Breaking Everything
Start by defining what you actually need to monitor. I see teams install a full NMM platform and then spend weeks trying to monitor things that do not matter. A router interface going down matters. A DHCP lease renewal taking 300 milliseconds instead of 280 does not. The first configuration step is usually establishing your poll or scrape interval. For SNMP-based checks, 60 seconds is a common default. Going shorter sounds like a good idea until you realize your management station is doing four thousand HTTP GET requests per second and burning through CPU before it gets to the alerting logic. For metrics endpoints, scraping every 15 to 30 seconds is usually the sweet spot unless you are collecting something like per-packet latency, and even then you might not need that granularity in the dashboard. Next comes device templates. Most platforms let you import standard templates for common equipment. Cisco, Juniper, HPE, Arista, Dell, generic Linux servers, Windows hosts. Import them. Then strip out the checks you do not need. A template might give you forty metric pulls per device. Your actual use case probably needs eight. Keeping the rest just adds noise to your alert routing and eats resources you could use elsewhere.
Get the Full Details
The SNMP Gotchas Nobody Warns You About
SNMP is still the dominant protocol for network device monitoring, and it is still a minefield. Here are the things that trip people up repeatedly. Versions matter more than the documentation says. SNMPv3 is the only safe choice for anything on a shared network. v2c sends community strings in cleartext. If you are using v2c on a production LAN, you are already being monitored by anyone who ran Wireshark once. v3 adds authentication and encryption, but the configuration is verbose and every vendor implements it slightly differently. I spent an entire afternoon getting v3 working on a MikroTik switch only to find the platform I was using did not support the authProtocol I had configured on the device. The workaround was exporting the MIBs again and switching to SHA instead of MD5 for authentication. OID timeouts are a silent killer. A device that drops packets under load will also drop SNMP responses. Your monitoring system sees a timeout and marks the device as unreachable. In reality the device is fine, but it is too busy to answer the poll. This is why you need to set appropriate timeouts and retries. A 3-second timeout with two retries is a reasonable starting point. Going shorter just makes your outage reports wrong more often.
Custom MIBs and proprietary extensions. Many vendors include extra OIDs that their standard MIBs do not cover. Power supply status, fan speeds, temperature zones, ASIC errors. If you skip importing the vendor-specific MIB files, you will miss half the data your platform could be showing you. I have seen teams blame a monitoring tool for missing hardware failures that would have been obvious if someone had taken thirty minutes to import the proper MIB bundle from the manufacturer.
Polling Architecture And Why It Matters
A well-designed NMM setup distributes the work. One server doing all the polling for five hundred devices will become a bottleneck. The standard approach is to use poller nodes or remote collectors that query devices locally and forward results to a central server. Zabbix has proxy nodes. Prometheus has pushgateway and remote write for edge cases. Nagios uses NRDP or NSCA to delegate checks. The reason this matters is network topology. Polling a device in another city from a single management station introduces latency. If your poll timeout is set to five seconds and the round-trip time is three seconds, you have two seconds of margin before a timeout occurs. Under normal conditions this might work. Under load or during a storm when your link is congested, you start getting false failure reports. Decentralized polling pushes the queries closer to the source and reduces that risk significantly. I redesigned a monitoring architecture once where all polling went through a single US-based hub for devices scattered across three continents. The latency alone was causing more false alerts than any misconfiguration. Moving to regional pollers cut the false positive rate from roughly twelve percent down to under one percent. The upgrade took about four hours and saved us probably ten hours of investigation work per week.
Alerting Logic And Threshold Tuning
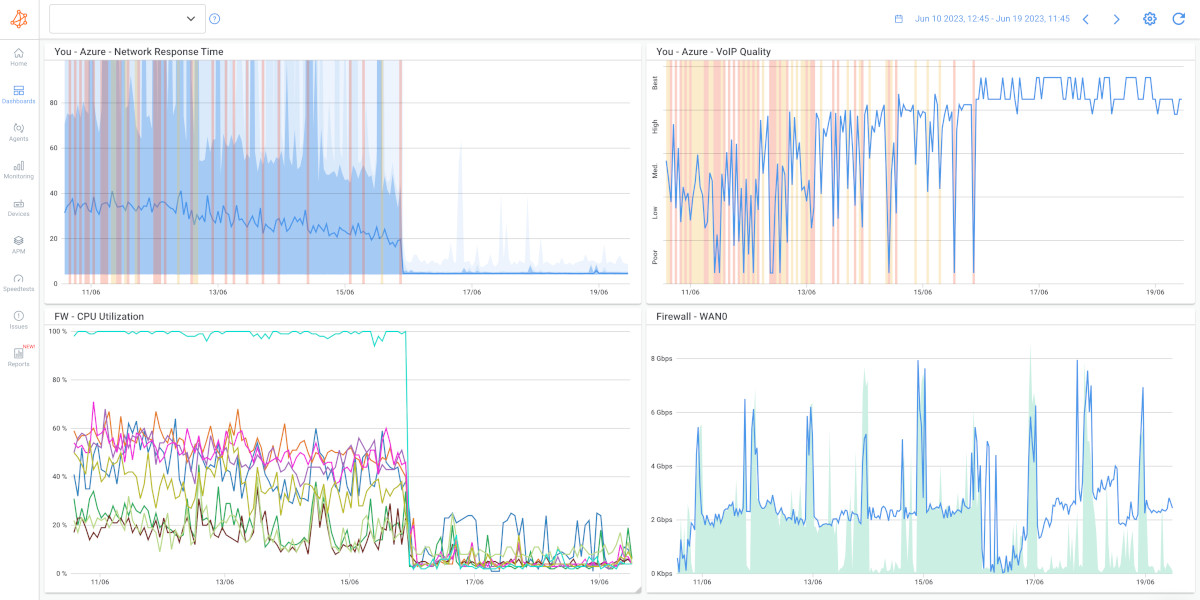
This is where most NMM implementations fail. Setting thresholds is not a one-time task. Network behavior changes. Traffic grows. New applications introduce different packet patterns. A threshold that made sense in January might be garbage by June. Start with absolute thresholds for things that are binary. Interface down, SNMP unreachable, BGP session down. These do not need fancy math. Then move to percentage-based thresholds for utilization metrics. CPU usage over 90 percent for five minutes is a reasonable trigger. But remember that a server consistently at 85 percent CPU might be doing exactly what it is supposed to be doing, and an alert there would just create noise. The counter-intuitive part is that you usually want more alerts on derived metrics rather than raw values. Packet retransmission rate, error rate per interface, ARP table size change over time, DNS query response time distribution. These often surface problems before the raw utilization numbers do. I caught a degrading fiber link once because the CRC error counter on one interface started climbing slowly over three days. The throughput metric looked fine. The latency was within acceptable range. Only the error counter told the real story.
Log Management And Correlation
Monitoring data and log data are different, but they need to talk to each other. An alert about high CPU on a router is more useful when you can see the syslog entries that preceded it. Did an interface flap? Was there a routing update? Was someone running a diagnostic command that spiked the CPU? Syslog forwarding is usually straightforward. Configure your devices to send logs to your NMM platform or a dedicated log collector. Use a standard format. Structured syslog or JSON if your platform supports it. I have seen too many teams accepting raw syslog and then spending hours trying to parse it later because they did not think about the format upfront. Correlation rules take a bit more work. Most platforms let you define conditions where multiple alerts together trigger a higher-priority notification. A switch losing power and its uplink going down at the same time is likely a single root cause, not two independent events. Linking these reduces the alert volume you have to deal with and speeds up diagnosis.
What NMM Does Not Do Well
It is worth being honest about the limitations. Most monitoring platforms are terrible at giving you the exact root cause of a problem. They tell you that something is wrong. Sometimes they tell you what is wrong. Almost never do they tell you why it went wrong without human investigation. A dashboard showing twenty red indicators during an outage does not replace a competent engineer. It replaces the engineer knowing which twenty indicators to look at first. Another limitation is the data retention trade-off. Storing every metric at sub-minute intervals for years requires real storage. Most teams either compress heavily and lose granularity or pay for cloud storage they did not budget for. The practical compromise is keeping high-resolution data for seven to thirty days and rolling up to hourly or daily averages after that. This preserves recent detail while keeping long-term costs manageable. Finally, there is the configuration drift problem. Devices get reconfigured without updating the monitoring templates. New OIDs are added. Old ones are deprecated. The monitoring system keeps asking for data that no longer exists, and you get missing metric errors that look like problems but are just stale configurations. A quarterly review of your monitoring coverage against the actual device inventory catches most of this.
A Practical Walkthrough For Getting Started
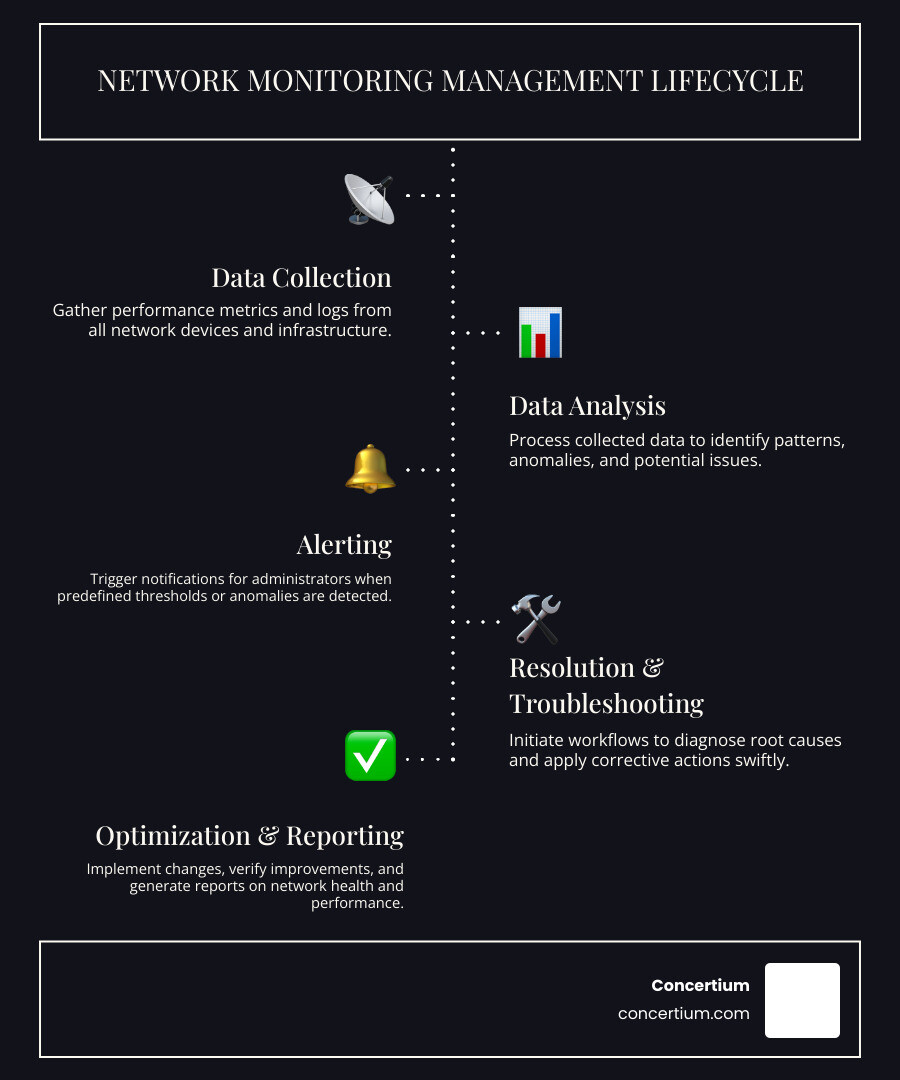
If you are setting this up from scratch, here is the order I would recommend. Install the platform on a dedicated machine. Do not put it on a server that runs anything else critical. Resource contention will show up in your monitoring data, which makes diagnosing real issues harder. Import the base device templates. Add your first ten devices manually. Verify that the data is flowing correctly. Check the raw metric values against what you see in the device CLI. If the monitoring system reports 45 percent CPU and the device says 72 percent, something is wrong with your OIDs, your polling method, or your understanding of what that metric means. Investigate before adding more devices. Configure syslog forwarding next. Then set up alerting rules starting with the obvious ones. Interface down, SNMP unreachable, disk usage above 90 percent, memory below a safe threshold. Do not add complex alerting logic until you have at least two weeks of baseline data. Raw thresholds are enough for the first month.
After the baseline period, review your alert history. Which alerts fired? Were they useful? Which ones were noise? Adjust thresholds based on what you learned, not based on what the documentation recommends. Documentation thresholds are written for generic environments. Your environment is not generic. The whole setup process for a small to medium network usually takes one to two weeks if you are doing it carefully. Rushing it cuts that down to a day and leaves you with a system that generates more noise than insight. Both outcomes are avoidable if you take the time to validate the data before you rely on it.