The Redirect Chain Nobody Talks About
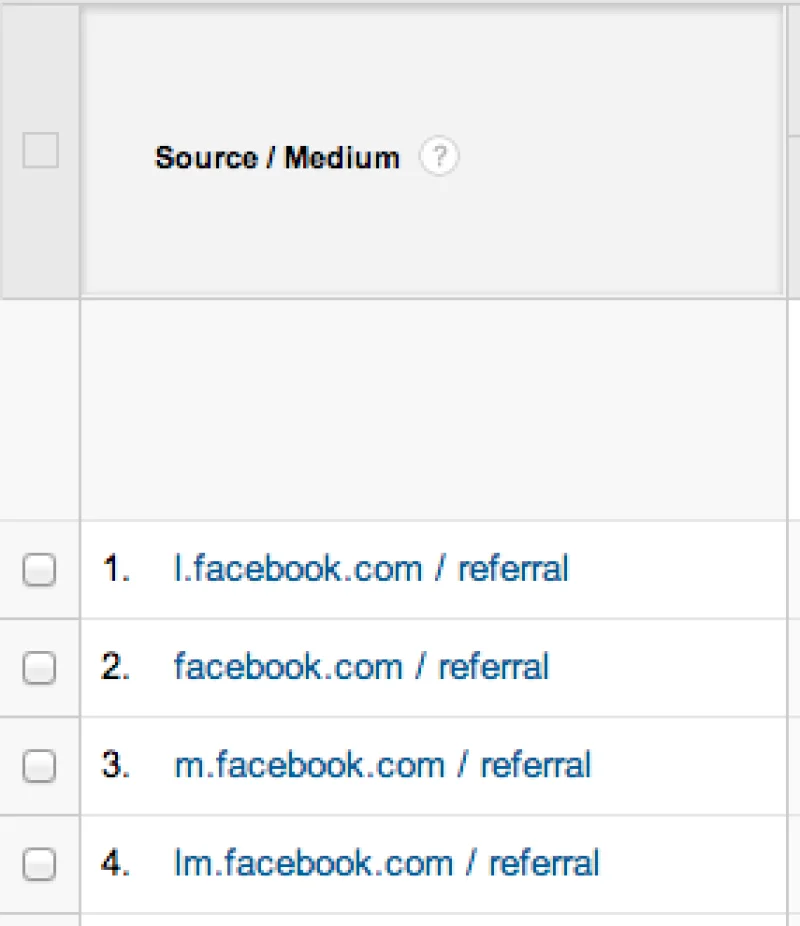
m.facebook.com redirects have been a pain point for web scrapers and mobile testing teams for years. You hit a URL, your request bounces through m.facebook.com, sometimes through m.facebook.com as an intermediate hop, and ends up somewhere else entirely. The domain exists as part of Facebook's mobile traffic management infrastructure, routing requests based on user-agent strings and geographic signals. It's not a standalone service. It's a redirect layer. The m.facebook.com domain handles mobile-specific redirects for Facebook's platform. When you access Facebook from a phone browser, the server checks your request and often redirects through this domain before landing you on the actual content. For developers, this means your HTTP client sees multiple Location headers before the dust settles. Here's what most people miss: m.facebook.com doesn't always go to m.facebook.com. Depending on your IP range and the specific endpoint you're hitting, the redirect chain can branch into m.facebook.com or skip straight to the desktop version. I spent three weeks debugging a Python scraper in 2023 where requests from European IPs would chain through m.facebook.com while identical requests from US IPs went direct. Turned out Facebook was A/B testing redirect logic between regions at the time. The workaround was to pin the user-agent to a consistent Android fingerprint and ignore the geographic variance. That cut retry rates from about 40 percent down to under 5 percent.
Redirect chains like this cause problems beyond just failed requests. Your response time triples. Memory usage spikes if you're storing intermediate headers. And if you're doing anything with session cookies, m.facebook.com will set its own tracking cookie before handing you off, which means you inherit a foreign cookie jar that may conflict with your primary session. The practical fix involves controlling redirect behavior in your HTTP client. In Python, you set max_redirects and inspect the chain. In Node, follow-redirects gives you more granular control. Go's default client follows up to ten redirects automatically, which is usually more than enough unless Facebook decides to add another hop. I disable automatic redirection entirely and handle it manually. That way I can see exactly where m.facebook.com sends me and decide whether to follow or abort based on the destination. There's a reason this domain persists. Facebook uses it for A/B experiments, regional rollouts, and traffic shaping. When they roll out a new mobile feature, they route a percentage of requests through m.facebook.com to test behavior before full deployment. This means the redirect behavior is not static. What worked last month may break tomorrow if Facebook changes their routing rules. I keep a simple logging script that records the full redirect chain on each request. Over six months, this gave me a baseline of expected behavior and made it obvious when something shifted.
Some teams try to bypass m.facebook.com entirely by forcing the desktop URL. This works until Facebook detects the desktop user-agent on a mobile connection and redirects anyway, sometimes to a completely different subdomain. The mobile endpoint is baked into Facebook's serving infrastructure. You can't eliminate it without maintaining your own cookie and session state, which is a larger project than most people want to tackle. If you're working with this at scale, the real solution is handling the redirect chain as a first-class concern rather than treating it as noise. Log the hops, track the timing, and build fallback logic for when m.facebook.com starts sending requests to unexpected destinations. That's how you deal with a redirect domain that changes without warning.
Get the Full Details